# Cyoda Documentation — full content
Source: https://docs.cyoda.net
Generated: 2026-09-26T23:11:34.742Z
---
## build.md
# Build
Develop Cyoda applications — tier-agnostic patterns that work on any runtime.
Cyoda applications are **digital twins**: the same code runs on every
storage tier, from in-memory dev through Cassandra at enterprise
scale. Pages in this section cover the patterns — entity modeling,
workflows, external processors, testing — independent of where your
app runs.
## Build with a coding agent
Building with Cyoda is easiest with an AI coding assistant. The Cyoda Skills plugin drops in
to Claude Code, Cursor, Codex, and other compatible tools, giving them
the skills to set up a local instance, model entities, design
workflows, and run tests against your Cyoda app. Install it from
github.com/Cyoda/cyoda-skills
and let your assistant lead — the rest of this section is the manual
reference behind what the skills do.
Where to next:
- [Modeling entities](./modeling-entities/)
- [Working with entities](./working-with-entities/)
- [Workflows and processors](./workflows-and-processors/)
- [Client compute nodes](./client-compute-nodes/)
- [Testing with digital twins](./testing-with-digital-twins/)
---
## build/analytics-with-sql.md
# Analytics with SQL
Query entities with Trino SQL — when its the right surface, how to connect, and where to find the full grammar.
:::caution[Upcoming]
Trino SQL is on the roadmap and not yet implemented in cyoda-go. The surface below is proven in the enterprise Java/Kotlin Cyoda platform, of which cyoda-go is an adaptation; names and shapes may change before it lands in cyoda-go and [Cyoda Cloud](/cyoda-cloud/).
:::
Cyoda projects every entity model into a set of virtual SQL tables and
exposes them through a Trino connector. Use this surface for cross-entity
analytics: joins across entity types, aggregates, reporting, time-series,
BI dashboards. For operational read/write, stay on [REST](/build/working-with-entities/);
for compute that runs against transitions, use [gRPC compute
nodes](/build/client-compute-nodes/).
## When to use SQL
- Ad-hoc analysis against live data in a notebook or BI tool.
- Scheduled reports aggregating entities across a tenant.
- Historical queries using the `point_time` column for as-of reads.
- Cross-entity joins — e.g. orders joined to customers joined to
payments.
If the question is *transactional* ("read this one entity", "fire this
transition"), it does not belong here. REST is faster, cheaper, and
correctly scoped for that.
## Connect
The JDBC connection string pattern:
```
jdbc:trino://:443/cyoda/
```
- `` — the host serving the Trino connector. On
[Cyoda Cloud](/cyoda-cloud/), each environment will get a managed
endpoint.
- `` — the SQL schema name you configured (via
`PUT /sql/schema/putDefault/{schemaName}`).
Authenticate with a bearer token issued by the platform. For
technical-user setup and the OAuth 2.0 client-credentials flow, see
[Authentication and identity](/concepts/authentication-and-identity/).
## A first query
Given an entity model `orders` with nested `lines`, Cyoda produces one
table per nested level plus a JSON reconstruction table:
- `orders` — root columns + top-level fields
- `orders_lines` — one row per line item, with `index_0` marking
position
- `orders_json` — the complete JSON document per entity
Read a single order and its lines:
```sql
SELECT
o.entity_id,
o.state,
o.customer_id,
l.index_0 AS line_no,
l.sku,
l.quantity,
l.price
FROM orders o
JOIN orders_lines l
ON l.entity_id = o.entity_id
WHERE o.entity_id = '00000000-0000-0000-0000-000000000001';
```
Query as of last Tuesday:
```sql
SELECT * FROM orders
WHERE point_time = TIMESTAMP '2026-04-14 00:00:00'
AND state = 'submitted';
```
## Table-naming rules, at a glance
- Root node of an entity → table named after the model
(e.g. `orders`).
- Array-of-objects node → `_` (e.g. `orders_lines`).
- Multi-dimensional arrays → `__d_array` (detached
array naming).
- JSON reconstruction → `_json`.
The full projection rules — node decomposition, detached arrays, type
mapping, polymorphic fields — live in the
[Trino SQL reference](/reference/trino/).
## Performance notes
- When querying a `_json` table, **always include `entity_id` in
the WHERE clause**. Without that predicate the query scans the
reconstruction table for every entity and gets very slow.
- For joins across nested-array tables, use `entity_id` plus matching
`index_*` columns as join keys.
- Omit `point_time` unless you actually need historical data.
## Where to go next
- [Trino SQL reference](/reference/trino/) — full projection rules,
type mapping, polymorphic fields, complete worked example.
- [APIs and surfaces](/concepts/apis-and-surfaces/) — when to pick
REST vs gRPC vs SQL.
- [Entities and lifecycle](/concepts/entities-and-lifecycle/) — the
entity model whose shape becomes your SQL tables.
---
## build/client-compute-nodes.md
# Client compute nodes
Patterns for processor and criteria services — implementation, registration, and lifecycle.
# 1. Architecture Overview
A **calculation member** is an external gRPC client that participates in entity workflow processing on the Cyoda platform. The platform delegates work to your client over a persistent bidirectional gRPC stream, and your client returns results on the same stream. For the rationale behind preferring gRPC over HTTP for compute nodes, see [APIs and surfaces](/concepts/apis-and-surfaces/).
```
┌──────────────────────┐ gRPC (bidirectional stream) ┌─────────────────────────┐
│ Cyoda Platform │ ◄──────────────────────────────────────────►│ Your Calculation │
│ │ CloudEvent (Protobuf, JSON payload) │ Member (Client) │
│ ┌────────────────┐ │ │ │
│ │ Workflow Engine│ │ 1. Client opens stream, sends Join │ ┌───────────────────┐ │
│ │ │ │ 2. Server responds with Greet │ │ Business Logic │ │
│ │ - Processors │──┼──3. Server pushes Processing/Criteria reqs──┼──│ │ │
│ │ - Criteria │ │ 4. Client returns responses │ │ - Data transforms │ │
│ │ │ │ 5. Keep-alive heartbeats (bidirectional) │ │ - Criteria checks │ │
│ └────────────────┘ │ │ └───────────────────┘ │
└──────────────────────┘ └─────────────────────────┘
```
Three types of work can be delegated:
| Use Case | Description | Request Type | Response Type |
|---|---|---|---|
| **Processing** | Perform actions, such as transforming entity data during a workflow transition, performing CRUD ops on other entities, running reports, interacting with other systems, etc. | `EntityProcessorCalculationRequest` | `EntityProcessorCalculationResponse` |
| **Criteria Evaluation** | Evaluate a boolean condition (e.g., "should this transition fire?") | `EntityCriteriaCalculationRequest` | `EntityCriteriaCalculationResponse` |
| **Function** | Compute and return a declared typed value without mutating anything — currently the firing time of a [scheduled transition](/build/workflows-and-processors/#scheduled-transitions). | `EntityFunctionCalculationRequest` | `EntityFunctionCalculationResponse` |
## 1.1 Protocol Summary
- **Transport**: gRPC bidirectional streaming via `CloudEventsService.startStreaming`
- **Message format**: [CNCF CloudEvents](https://cloudevents.io/) Protobuf envelope with JSON `text_data` payload
- **Authentication**: Bearer JWT token in gRPC `Authorization` metadata header
- **Auth context propagation**: The platform attaches [CloudEvents Auth Context extension](https://github.com/cloudevents/spec/blob/main/cloudevents/extensions/authcontext.md) attributes to processor and criteria requests, identifying the principal whose action triggered the workflow (see [Section 9](#9-auth-context-on-incoming-requests))
- **Serialization**: All payloads are JSON-serialized inside CloudEvent `text_data` (not binary protobuf)
---
# 2. Prerequisites
## 2.1 Proto Definitions
Your client needs the following proto files to generate gRPC stubs:
- **`cloudevents.proto`** — The standard CloudEvents Protobuf message definition (package `io.cloudevents.v1`)
- **`cyoda-cloud-api.proto`** — The Cyoda service definition (package `org.cyoda.cloud.api.grpc`)
The service definition:
```protobuf
service CloudEventsService {
rpc startStreaming(stream io.cloudevents.v1.CloudEvent) returns (stream io.cloudevents.v1.CloudEvent);
}
```
The CloudEvent message:
```protobuf
message CloudEvent {
string id = 1; // Unique event ID (UUID recommended)
string source = 2; // URI-reference identifying the event source
string spec_version = 3; // Must be "1.0"
string type = 4; // Event type string (see Section 4)
map attributes = 5;
oneof data {
bytes binary_data = 6;
string text_data = 7; // ← Used by Cyoda (JSON payload)
google.protobuf.Any proto_data = 8;
}
}
```
## 2.2 JWT Authentication Token
Obtain a valid JWT Bearer token from the Cyoda IAM system (OAuth 2.0 client credentials flow). The token must contain:
- A valid `caas_org_id` claim (your legal entity ID)
- Valid user roles
The token is validated on every stream establishment. If the token expires during an active stream, the stream remains valid — re-authentication occurs only when a new stream is opened.
## 2.3 Dependencies (Java/Kotlin Example)
For JVM-based clients, the recommended dependencies are:
- `io.grpc:grpc-stub`, `io.grpc:grpc-protobuf`, `io.grpc:grpc-netty-shaded` — gRPC runtime
- `io.cloudevents:cloudevents-protobuf` — CloudEvents SDK Protobuf format support
- `io.cloudevents:cloudevents-core` — CloudEvents SDK core
- `com.fasterxml.jackson.core:jackson-databind` — JSON serialization
---
# 3. Connection Setup
## 3.1 Create the gRPC Channel
```java
ManagedChannel channel = ManagedChannelBuilder
.forAddress("cyoda-host.example.com", 50051)
.usePlaintext() // Use .useTransportSecurity() for TLS in production
.keepAliveTime(30, TimeUnit.SECONDS)
.keepAliveTimeout(10, TimeUnit.SECONDS)
.build();
```
**Production TLS**: In production, always use TLS. Replace `.usePlaintext()` with:
```java
.useTransportSecurity()
.sslContext(/* your SSL context */)
```
## 3.2 Attach JWT Credentials
Create a `CallCredentials` implementation that injects the `Authorization` header:
```java
CallCredentials callCredentials = new CallCredentials() {
@Override
public void applyRequestMetadata(RequestInfo requestInfo, Executor executor, MetadataApplier applier) {
executor.execute(() -> {
Metadata headers = new Metadata();
headers.put(
Metadata.Key.of("Authorization", Metadata.ASCII_STRING_MARSHALLER),
"Bearer " + jwtTokenSupplier.get() // Always fetch a fresh token
);
applier.apply(headers);
});
}
};
```
## 3.3 Create the Stub
```java
CloudEventsServiceGrpc.CloudEventsServiceStub asyncStub = CloudEventsServiceGrpc
.newStub(channel)
.withCallCredentials(callCredentials)
.withWaitForReady(); // Wait for the channel to become ready before sending
```
---
# 4. CloudEvent Type System
Every message on the stream is a CloudEvent with a `type` field that determines how to deserialize the JSON `text_data`. Your client must handle the following types:
| CloudEvent `type` | Direction | Description |
|---|---|---|
| `CalculationMemberJoinEvent` | Client → Server | Register as a calculation member |
| `CalculationMemberGreetEvent` | Server → Client | Server confirms registration |
| `CalculationMemberKeepAliveEvent` | Bidirectional | Heartbeat probe and response |
| `EventAckResponse` | Server → Client | Acknowledgment of keep-alive |
| `EntityProcessorCalculationRequest` | Server → Client | Process entity data |
| `EntityProcessorCalculationResponse` | Client → Server | Return processed entity data |
| `EntityCriteriaCalculationRequest` | Server → Client | Evaluate a boolean criterion |
| `EntityCriteriaCalculationResponse` | Client → Server | Return criterion result |
| `EntityFunctionCalculationRequest` | Server → Client | Compute a typed value (no mutation) |
| `EntityFunctionCalculationResponse` | Client → Server | Return the typed result |
## 4.1 Building a CloudEvent
To send a CloudEvent on the stream (Java/Kotlin with CloudEvents SDK):
```java
// 1. Build the CloudEvents SDK event
io.cloudevents.CloudEvent sdkEvent = CloudEventBuilder.v1()
.withType("CalculationMemberJoinEvent") // Must match the type table above
.withSource(URI.create("my-calculation-member"))
.withId(UUID.randomUUID().toString())
.withData(PojoCloudEventData.wrap(event, e -> objectMapper.writeValueAsBytes(e)))
.build();
// 2. Serialize to Protobuf
EventFormat protobufFormat = EventFormatProvider.getInstance()
.resolveFormat("application/cloudevents+protobuf");
byte[] protoBytes = protobufFormat.serialize(sdkEvent);
// 3. Parse to the gRPC CloudEvent message
io.cloudevents.v1.proto.CloudEvent grpcEvent =
io.cloudevents.v1.proto.CloudEvent.parseFrom(protoBytes);
```
## 4.2 Parsing a Received CloudEvent
```java
// From the gRPC StreamObserver.onNext(value):
String eventType = value.getType();
String jsonPayload = value.getTextData();
// Deserialize based on type
switch (eventType) {
case "CalculationMemberGreetEvent":
GreetEvent greet = objectMapper.readValue(jsonPayload, GreetEvent.class);
break;
case "EntityProcessorCalculationRequest":
ProcessorRequest req = objectMapper.readValue(jsonPayload, ProcessorRequest.class);
break;
// ... etc
}
```
---
# 5. Connection Lifecycle
## 5.1 Open the Stream
```java
StreamObserver requestObserver = asyncStub.startStreaming(
new StreamObserver() {
@Override
public void onNext(CloudEvent value) {
// Dispatch based on value.getType() — see Sections 6–8
}
@Override
public void onError(Throwable t) {
// Connection lost — trigger reconnect (see Section 12)
}
@Override
public void onCompleted() {
// Server closed the stream — trigger reconnect
}
}
);
```
## 5.2 Join Handshake
Immediately after opening the stream, send a `CalculationMemberJoinEvent`:
```json
{
"id": "",
"tags": ["my-processor-tag", "production"]
}
```
**Tags** are critical for routing. The platform routes processing/criteria requests to members whose tags are a **superset** of the tags configured on the workflow processor/criterion. Tags are case-insensitive (lowercased server-side).
The server responds with a `CalculationMemberGreetEvent`:
```json
{
"id": "",
"success": true,
"memberId": "",
"joinedLegalEntityId": ""
}
```
**Store the `memberId`** — you will need it for keep-alive messages.
If `success` is `false`, inspect the `error` object for the failure reason (e.g., subscription limit exceeded, invalid token).
### 5.3 Keep-Alive
The platform periodically probes your member with `CalculationMemberKeepAliveEvent` messages to verify liveness. You **must** respond to each probe with an `EventAckResponse`.
**Server-initiated keep-alive probe** (Server → Client):
```json
{
"id": "",
"memberId": ""
}
```
**Required response** (Client → Server):
```json
{
"id": "",
"sourceEventId": "",
"success": true
}
```
You may also send **client-initiated keep-alive** messages to confirm your own
liveness.
> ⚠️ **The server does not reply to an inbound member keep-alive.** It is
> liveness-only: it refreshes your member's last-seen timestamp and produces no
> response event. Each side pings on its own ticker.
>
> **Do not write a handler that echoes an inbound keep-alive.** Two peers that
> each echo what they receive form a zero-delay feedback loop, which pins both
> processes at ~100% CPU with nothing above `Debug` in the logs. If your
> handler waits for an ack after it sends a keep-alive, remove that wait. No
> ack arrives.
Anything you send counts as activity: a keep-alive, a processor response, a
criteria response, or an `EventAckResponse` all refresh liveness. The server
closes the stream if it sees nothing from you within
`CYODA_KEEPALIVE_TIMEOUT` seconds (default `30`), and sends its own probes
every `CYODA_KEEPALIVE_INTERVAL` seconds (default `10`).
**Timing parameters** (server-side defaults):
| Variable | Default | Description |
|---|---|---|
| `CYODA_KEEPALIVE_INTERVAL` | `10` s | Interval between server-sent keep-alive probes. |
| `CYODA_KEEPALIVE_TIMEOUT` | `30` s | Inactivity after which the server **terminates the stream**. |
> ⚠️ **Going idle costs you the stream, not just routing.** There is no
> intermediate "marked not alive but still registered" state that a later probe
> recovers from — exceeding `CYODA_KEEPALIVE_TIMEOUT` closes the stream with
> `DeadlineExceeded`. Keep your keep-alive handler fast and non-blocking, and
> implement the reconnection logic in [Section 12.1](#121-reconnection-strategy);
> it is the only way back.
The server evicts a member for two conditions. The first is inbound silence for
`CYODA_KEEPALIVE_TIMEOUT`. The second is a **stalled write**: one
server-to-client write blocked for `CYODA_KEEPALIVE_TIMEOUT`. The second
condition evicts a node that continues to send keep-alives while its
application is blocked.
A slow consumer applies back pressure to its own stream only, not to the
streams of other members.
---
# 6. Handling Processor Requests
When an entity reaches a workflow transition with an externalized processor configured to match your member's tags, the platform sends an `EntityProcessorCalculationRequest`.
## 6.1 Request Schema
```json
{
"id": "",
"requestId": "",
"entityId": "",
"processorId": "",
"processorName": "",
"transactionId": "",
"workflow": {
"id": "",
"name": ""
},
"transition": {
"id": "",
"name": "",
"stateFrom": "",
"stateTo": ""
},
"parameters": { /* arbitrary JSON configured on the processor */ },
"payload": {
"type": "TREE",
"data": { /* entity data as JSON — present only if attachEntity=true */ },
"meta": { /* entity metadata */ }
}
}
```
**Key fields**:
- `requestId` — You **must** echo this back in the response for correlation.
- `entityId` — The entity being processed. Echo this back.
- `processorName` — Use this to dispatch to different business logic handlers.
- `parameters` — Arbitrary JSON configured on the processor in the workflow definition (the `context` field). Use for passing configuration to your handler.
- `payload.data` — The entity data. Only present when `attachEntity` is `true` in the workflow configuration.
> 💡 **Auth context**: The CloudEvent envelope for this request also carries auth context extension attributes (`authtype`, `authid`, `authclaims`) identifying the principal whose action triggered the workflow. See [Section 9](#9-auth-context-on-incoming-requests) for details on how to extract them.
## 6.2 Response Schema
```json
{
"id": "",
"requestId": "",
"entityId": "",
"success": true,
"payload": {
"type": "TREE",
"data": { /* modified entity data to write back */ }
}
}
```
**Rules**:
1. **`requestId`** must exactly match the value from the request.
2. **`entityId`** must exactly match the value from the request.
3. If you set `success: true`, the platform applies your `payload.data` to the entity.
4. If you set `success: false`, the platform treats this as a processing failure. Include an `error` object.
5. The `payload` field is optional. If omitted (or `payload.data` is null), no data modification occurs.
## 6.3 Error Response
```json
{
"id": "",
"requestId": "",
"entityId": "",
"success": false,
"error": {
"code": "BUSINESS_ERROR",
"message": "Detailed error description",
"retryable": true
}
}
```
The `error.retryable` flag tells the platform whether it should retry the request on a different member (if a retry policy is configured). Set to `true` for transient failures and `false` for permanent failures.
### 6.3.1 Infrastructure failures the platform raises
Separately from errors *you* return, the platform raises its own codes when a
callout cannot be delivered at all. These surface uniformly as a **retryable
`503`** across all three callout kinds — processor, criteria, and function:
| Code | Meaning |
|---|---|
| `NO_COMPUTE_MEMBER_FOR_TAG` | No connected member carries the required `calculationNodesTags`. |
| `COMPUTE_MEMBER_DISCONNECTED` | The selected member dropped mid-dispatch. |
| `DISPATCH_TIMEOUT` | No response within the configured response timeout. |
| `DISPATCH_FORWARD_FAILED` | Cross-node forwarding to the member's owner failed. |
Previously some of these — a missing compute member most visibly — fell through
to a misleading `400 WORKFLOW_FAILED`, which looks like a caller mistake rather
than a deployment problem. If you have error handling that treats
`WORKFLOW_FAILED` as non-retryable, re-check it: these now arrive as `503` and
are worth retrying.
---
# 7. Handling Criteria Requests
When a workflow transition has an externalized criterion configured as a `function`, the platform sends an `EntityCriteriaCalculationRequest`.
## 7.1 Request Schema
```json
{
"id": "",
"requestId": "",
"entityId": "",
"criteriaId": "",
"criteriaName": "",
"target": "TRANSITION",
"transactionId": "",
"workflow": {
"id": "",
"name": ""
},
"transition": {
"id": "",
"name": "",
"stateFrom": "",
"stateTo": ""
},
"processor": {
"id": "",
"name": ""
},
"parameters": { /* arbitrary JSON */ },
"payload": {
"type": "TREE",
"data": { /* entity data */ }
}
}
```
**The `target` field** indicates what the criterion is attached to:
| Target | Meaning | Available Context |
|---|---|---|
| `WORKFLOW` | Workflow-level criterion (selects which workflow applies) | `workflow` |
| `TRANSITION` | Transition-level criterion (should this transition fire?) | `workflow`, `transition` |
| `PROCESSOR` | Processor-level criterion (should this processor run?) | `workflow`, `transition`, `processor` |
| `NA` | Reserved for future use | — |
> 💡 **Auth context**: Like processor requests, criteria requests also carry auth context extension attributes on the CloudEvent envelope. See [Section 9](#9-auth-context-on-incoming-requests).
## 7.2 Response Schema
```json
{
"id": "",
"requestId": "",
"entityId": "",
"success": true,
"matches": true,
"reason": "Entity meets all validation criteria"
}
```
**Key fields**:
- `requestId` — Must exactly match the request.
- `entityId` — Must exactly match the request.
- `matches` — The boolean result: `true` means the criterion is satisfied (transition fires / processor runs), `false` means it is not.
- `reason` — Optional explanation for a `false` result; see below.
If `success: false`, the platform treats it as a criteria evaluation failure (the criterion evaluates to `false` by default).
### 7.2.1 Explaining a `false` result
`reason` reaches the caller and the audit trail, so populate it on every
`false`.
Where it surfaces depends on how the criterion was reached:
- **A manual, explicitly-requested transition** rejected by its criterion
appends the reason to the `400 WORKFLOW_FAILED` detail:
`transition "" criterion not matched: `. This is the
guaranteed, backend-independent surface.
- **Automated cascade and workflow-selection paths** additionally record it
durably on the state-machine audit trail —
`TRANSITION_NOT_MATCH_CRITERION` carries
`{workflowName, transition, criterion, reason}` in its `data`, and
`WORKFLOW_SKIP` carries `{workflowName, reason}`.
Reasons are capped at **2 KiB**. If you omit one, the *audit trail* falls back
to `"criterion did not match"` while the `400` detail is left bare — so an
omitted reason really does leave the caller with nothing. Write the specific
cause: `"order total 4200 exceeds the 1000 auto-approval limit"` beats
`"validation failed"`.
---
# 8. Handling Function Requests
A **Function** callout is the third request shape your compute node may
receive, alongside Processor and Criteria. The three differ in what they are
allowed to do:
| Callout | Returns | Mutates the entity? |
|---|---|---|
| Processor | an updated entity payload | Yes |
| Criteria | a boolean `matches` | No |
| **Function** | a **declared typed value** | No |
A Function computes and returns a value without side effects. The response
carries a `resultKind` discriminator naming the shape of `result`, so the
caller can validate what it receives.
## 8.1 Request Schema
The request is an `EntityFunctionCalculationRequest`. It mirrors a processor
request, but the callout target is named by **`functionId` / `functionName`** —
there is no `processorName` on this message, so route on `functionName`.
| Field | Required | Description |
|---|---|---|
| `requestId` | YES | Echo back unchanged. |
| `entityId` | YES | Echo back unchanged. |
| `functionId` | YES | Identifier of the invoked function. |
| `functionName` | YES | **The routing key** — the registered `schedule.function.name`. Dispatch on this. |
| `workflow` | YES | The workflow this callout belongs to. |
| `transition` | NO | The transition carrying the schedule. |
| `transactionId` | NO | The originating transaction. |
| `payload` | NO | The entity data — present only when `attachEntity` is `true`. |
| `parameters` | NO | The configured `context` string, forwarded verbatim. |
## 8.2 Response Schema
```json
{
"id": "",
"requestId": "",
"entityId": "",
"success": true,
"resultKind": "Schedule",
"result": { "fireAfterMs": 3600000, "expireAfterMs": 600000 }
}
```
- `resultKind` — names the shape of `result`. **`"Schedule"` is currently the
only defined kind.**
- `result` — the typed value itself.
- `success: false`, or an `error`, fails the dispatch exactly as a processor or
criteria failure does.
## 8.3 The `Schedule` result kind
`Schedule` drives a
[scheduled transition's](/build/workflows-and-processors/#scheduled-transitions)
`schedule.function`, computing when a transition should fire for one specific
entity:
- **Fire time** (required) — exactly one of `fireAt` (absolute epoch-ms) or
`fireAfterMs` (relative to arm time).
- **Expiry** (optional) — at most one of `expireAt` or `expireAfterMs`, the
latter relative to the *resolved fire time* rather than to arm time.
> ⚠️ **This callout runs inside the caller's write transaction.** It is
> invoked synchronously while the entity write that arms the timer is still
> open, and it is re-invoked on *every* re-arm — not once per entity. A slow
> handler slows every write to that entity; a failing or unreachable handler
> **fails the write** with a retryable `503`. Keep it fast, side-effect free,
> and dependent only on data you already have.
>
> Returning a malformed `result`, or one that does not match the declared
> `resultKind`, fails the write with `500 SCHEDULE_FUNCTION_INVALID_RESULT`.
---
# 9. Auth Context on Incoming Requests
The platform attaches [CloudEvents Auth Context extension](https://github.com/cloudevents/spec/blob/main/cloudevents/extensions/authcontext.md) attributes to every `EntityProcessorCalculationRequest` and `EntityCriteriaCalculationRequest`. These attributes identify the authenticated principal whose action triggered the workflow execution (e.g., the user who created or updated the entity).
## 9.1 Extension Attributes
The auth context is carried as CloudEvent extension attributes in the Protobuf `attributes` map — **not** inside the JSON `text_data` payload.
| Attribute | Type | Required | Description |
|---|---|---|---|
| `authtype` | String | YES | Principal kind. Exactly one of: `user`, `service`, `system` |
| `authid` | String | NO | Unique identifier of the principal (UUID). Absent for `system`. |
| `authclaims` | String | NO | **Comma-separated role names** on cyoda-go (e.g. `ROLE_ADMIN,ROLE_USER`). Absent when the principal has no roles. Never contains credentials. |
## 9.2 Auth Type Values
| `authtype` Value | Meaning |
|---|---|
| `user` | A regular authenticated user (JWT-based login) |
| `service` | A machine-to-machine (M2M) technical account |
| `system` | An internal platform trigger with no user context |
The value is driven by the principal's **explicit kind**, recorded when the
principal is established. The platform does not infer it from the roles the
principal carries.
The attribute is always present and always faithful. If a principal's kind is
unset or unrecognized, the platform **fails the callout dispatch** rather than
emitting a normalized placeholder — a bogus `authtype` never reaches your
compute node.
> ⚠️ **The only values are `user`, `service` and `system`.** There is no
> `service_account`, `unauthenticated` or `unknown`. A handler that switches on
> one of those strings never matches it. Do not rely on a `default` or `else`
> branch to catch an unroutable principal either: the platform fails the
> dispatch rather than sending one.
### Attribution vs. execution
`authtype` and `authid` describe the principal the action is **attributed** to,
which is not necessarily the identity it **executes** with. When a user's
action sets off a follow-on — a cascade write from a processor, or a scheduled
transition firing later — the platform executes it with system or service
authority, borrowing no user permissions, while still attributing it to the
principal that caused it. Treat the auth context as provenance for audit and
business logic, not as proof of the executing identity's privileges.
## 9.3 Extracting Auth Context (Java/Kotlin)
The attributes are available in the Protobuf CloudEvent's `attributes` map. The keys are the attribute names listed above (no prefix):
```java
// From the gRPC StreamObserver.onNext(value):
String authType = value.getAttributesMap().get("authtype").getCeString();
String authId = value.getAttributesMap().containsKey("authid")
? value.getAttributesMap().get("authid").getCeString()
: null;
String authClaims = value.getAttributesMap().containsKey("authclaims")
? value.getAttributesMap().get("authclaims").getCeString()
: null;
// cyoda-go sends roles as a comma-separated string, NOT JSON.
List roles = (authClaims == null || authClaims.isEmpty())
? List.of()
: Arrays.asList(authClaims.split(","));
```
The exact accessor depends on your gRPC tooling — in Go, use the generated message's `GetAttributes()` method; in Python, dict-like indexing on `.attributes`. See your language's generated proto bindings.
**Go clients** can skip the manual extraction. cyoda-go ships an
`api/grpc/authctx` helper exposing `Type`, `ID` and `Roles` readers plus
`Require(ce, role)`. `Require` is a **fail-closed** role gate — it returns
`false` for a nil event, for absent or empty claims, and for
`authtype == system`. Prefer it over hand-rolled claim parsing, which tends to
fail *open* on exactly those cases.
## 9.4 Example Claims JSON
On cyoda-go, `authclaims` is a flat comma-separated list of role names:
```
ROLE_USER,ROLE_SUPER_USER
```
For a `service` (M2M) principal:
```
ROLE_M2M
```
> ⚠️ **Do not parse this as JSON.** `objectMapper.readValue(authClaims, Map.class)`
> throws on `ROLE_USER,ROLE_SUPER_USER`. Split on `,`. Go clients should use
> `authctx.Roles`, which does exactly this.
>
> Cyoda Cloud has historically sent a richer JSON claims object including
> `legalEntityId`. If you target both, branch on whether the value starts with
> `{` rather than assuming either shape.
## 9.5 Use Cases
- **Audit logging**: Record which user triggered the processing for compliance.
- **Authorization decisions**: Apply different business logic based on the caller's roles or legal entity.
- **Multi-tenant isolation**: Verify the triggering principal belongs to the expected tenant.
- **Debugging**: Trace processing failures back to the originating user action.
> ⚠️ **Note**: The `authclaims` field never contains credentials (passwords, tokens, secrets). It contains only identity and authorization metadata.
---
# 10. Workflow Configuration
Your calculation member does not exist in isolation — it is invoked by workflow configurations on the platform side. This section describes how workflows reference externalized processors and criteria, so you understand the relationship between your member's tags/handlers and the platform configuration.
## 10.1 Externalized Processor in Workflow JSON
```json
{
"workflows": [{
"version": "1",
"name": "my-workflow",
"initialState": "start",
"states": {
"start": {
"transitions": [{
"name": "process-data",
"next": "processed",
"manual": false,
"processors": [{
"name": "my-processor-function",
"executionMode": "SYNC",
"config": {
"attachEntity": true,
"calculationNodesTags": "my-processor-tag",
"responseTimeoutMs": 60000,
"retryPolicy": "FIXED",
"context": "{\"key\": \"value\"}"
}
}]
}]
},
"processed": {}
}
}]
}
```
## 10.2 Processor Configuration Fields
| Field | Type | Default | Description |
|---|---|---|---|
| `name` | string | — | **Required.** The processor name. Sent as `processorName` in the request. |
| `executionMode` | string | — | **Required.** One of `SYNC`, `ASYNC_SAME_TX`, `ASYNC_NEW_TX`, `COMMIT_BEFORE_DISPATCH`. |
| `config.attachEntity` | boolean | `true` | Whether to send entity data in the request payload. A processor that omits this field is imported with `attachEntity: true`. Set it to `false` explicitly to opt out. |
| `config.calculationNodesTags` | string | `""` | Comma/semicolon-separated tags. Only members whose tags are a superset are eligible. |
| `config.responseTimeoutMs` | long | `30000` | How long the platform waits for your response before timing out. |
| `config.retryPolicy` | string | `FIXED` | `NONE` — no retry. `FIXED` — retry with fixed delay (default: 3 retries, 500ms delay). |
| `config.context` | string | `null` | Arbitrary string passed as `parameters` in the request. Use for handler-specific configuration. |
| `config.asyncResult` | boolean | `false` | Enable async response processing (advanced). |
| `config.crossoverToAsyncMs` | long | `5000` | Time before switching from sync to async response handling (advanced). |
| `startNewTxOnDispatch` | boolean | `false` | Whether a fresh transaction is started when this processor is dispatched. Valid only when `executionMode` is `COMMIT_BEFORE_DISPATCH`; the validator rejects `true` for any other mode. With `COMMIT_BEFORE_DISPATCH` and `startNewTxOnDispatch=false` (the default), callbacks run standalone instead of joining the originating transaction (see §10.3.1). |
## 10.3 Execution Modes
| Mode | Behavior |
|---|---|
| `SYNC` | The workflow engine waits for your response within the same transaction. The transition completes only after your response is applied. |
| `ASYNC_SAME_TX` | The engine sends the request and can process other work. Your response is applied within the same entity transaction. |
| `ASYNC_NEW_TX` | Like `ASYNC_SAME_TX`, but your response is applied in a new transaction. Useful for long-running computations. |
| `COMMIT_BEFORE_DISPATCH` | Commits the originating transaction before dispatching the request, releasing the storage connection for the duration of the external compute; the processor runs outside any transaction unless `startNewTxOnDispatch=true` opens one for it (see §10.3.1). On return, the result is reapplied via CompareAndSave in a new transaction. Relieves connection-pool pressure for slow processors; supersedes `ASYNC_NEW_TX` as the recommended mode for slow external work. |
> For most use cases, **`SYNC`** is the simplest and recommended starting point.
### 10.3.1 Transaction-joined callbacks
Processor and criteria-evaluation callbacks from a compute node **join the originating workflow transaction** `T` rather than running standalone. Before each dispatch the engine mints a signed HMAC transaction token and attaches it to the outbound CloudEvent as the `cyodatxtoken` extension attribute. Your compute node echoes it back on callbacks — as the `X-Tx-Token` HTTP header or the `tx-token` gRPC metadata — and the receiving node verifies the HMAC and routes the callback to the transaction owner (a local join when the owner is this node, or an HTTP reverse-proxy / gRPC forward otherwise).
The practical consequences:
- Callbacks see the cascade's **uncommitted** writes, and their acks stay provisional until `T` commits.
- `ASYNC_NEW_TX` callbacks join `T` via a savepoint, so a processor failure discards its own writes without aborting the whole cascade.
- If no token is present the callback falls back to standalone execution — the normal behaviour for `COMMIT_BEFORE_DISPATCH` with `startNewTxOnDispatch=false`.
- **The token covers the search RPCs as well as the write RPCs.** A callback that presents a valid `tx-token` on `EntitySearch` or `EntitySearchCollection` joins `T`, so a processor's searches see the writes the same processor has already made in that transaction.
- **`pointInTime` selects committed state, even inside a joined transaction.**
A point-in-time read is committed-only on every backend, so it does not see
the writes `T` has not yet committed. Pass it when you want the committed
state as at an instant, which is the usual reason to read history from a
processor. Omit it when you want to read back what this transaction has
written: a current-state read inside `T` is read-your-own-writes correct. An
entity that this transaction created, read back with `pointInTime`, answers
`404 ENTITY_NOT_FOUND`.
- **A request that joins an open transaction cannot carry its own deadline.**
The server rejects `transactionTimeoutMillis`, `transactionSize` and search's
`timeoutMillis` with `400` on a joined callback. The callback does not own
the transaction.
- **The model governs the data you return.** See
[the model governs the data a processor returns](/build/workflows-and-processors/#processors).
Three environment variables tune this (full list in the [configuration reference](/reference/configuration/#all-variables)):
- `CYODA_TX_TOKEN_TTL` — validity of the signed token (default `1m30s`).
- `CYODA_GRPC_NODE_ADDR` — this node's gRPC endpoint advertised to peers (`host:port`, no scheme), used for B→A forwarding.
- `CYODA_COMPUTE_HTTP_BASE` — base URL of the cyoda instance a compute node calls back into (compute-client side).
## 10.4 Externalized Criteria (`type: function`) in Workflow JSON
```json
{
"transitions": [{
"name": "conditional-transition",
"next": "target-state",
"manual": false,
"criterion": {
"type": "function",
"function": {
"name": "my-criteria-function",
"config": {
"attachEntity": true,
"calculationNodesTags": "my-processor-tag",
"responseTimeoutMs": 5000,
"retryPolicy": "NONE"
}
}
}
}]
}
```
Criteria functions use the same `config` fields as processors (except `asyncResult` and `crossoverToAsyncMs`, which are not applicable to criteria).
## 10.5 Retry Policies
| Policy | Behavior |
|---|---|
| `NONE` | No retry. If the member fails or times out, the processing fails. |
| `FIXED` | Retries up to N times (default: 3) with a fixed delay (default: 500ms) between retries. Each retry attempts a **different** member if available (the failed member is excluded from selection). |
---
# 11. BaseEvent Schema
All events on the stream extend the `BaseEvent` schema:
```json
{
"id": "",
"success": true,
"error": {
"code": "",
"message": "",
"retryable": false
},
"warnings": [""]
}
```
- `id` — Every event must have a unique ID (UUID recommended).
- `success` — Defaults to `true`. Set to `false` to indicate an error.
- `error` — Only relevant when `success` is `false`. The `code` and `message` fields are required within the error object.
- `warnings` — Optional array of warning strings.
---
# 12. Production Robustness
## 12.1 Reconnection Strategy
gRPC streams can be terminated by network issues, server restarts, or load balancer timeouts. Implement automatic reconnection:
1. **Detect disconnection** via `onError` or `onCompleted` on the response observer.
2. **Back off exponentially** — start at 1 second, cap at 60 seconds.
3. **Re-join after reconnect** — every new stream requires a fresh `CalculationMemberJoinEvent`.
4. **Refresh the JWT token** before reconnecting if it is near expiry.
```
┌─────────┐ onError/onCompleted ┌──────────┐ delay ┌──────────────┐ success ┌──────┐
│ Connected│ ──────────────────────► │ Backoff │ ────────► │ Reconnecting │ ────────────► │ Join │
└─────────┘ └──────────┘ └──────────────┘ └──────┘
▲ │ failure │
│ ▼ │
│ ┌──────────┐ │
│ │ Backoff │ (increase delay) │
│ └──────────┘ │
└────────────────────────────────────────────────────────────────────────────────────────┘
Greet received
```
## 12.2 Thread Safety
The gRPC `StreamObserver` is **not thread-safe**. If your business logic runs on multiple threads, synchronize all calls to `observer.onNext()`:
```java
synchronized (requestObserver) {
requestObserver.onNext(cloudEvent);
}
```
## 12.3 Response Timeouts
Your client must respond within the configured `responseTimeoutMs` (default **30 seconds** — `defaultResponseTimeoutMs` in the engine). If you exceed this:
- The platform considers the request failed.
- If retry policy is `FIXED`, the platform retries with a different member.
- Late responses are silently discarded.
Design your business logic to complete well within the timeout, accounting for network latency.
## 12.4 Idempotency
In edge cases (e.g., network partitions, retries), you may receive the same request more than once. Use the `requestId` as an idempotency key to avoid processing the same request twice.
## 12.5 Graceful Shutdown
When shutting down your client:
1. Stop accepting new requests (drain in-flight work).
2. Complete any pending responses and send them.
3. Close the gRPC stream via `requestObserver.onCompleted()`.
4. Shut down the `ManagedChannel` with a grace period:
```java
channel.shutdown().awaitTermination(10, TimeUnit.SECONDS);
```
The platform will detect the stream closure and broadcast a member-offline event to the cluster. Pending requests that were in-flight will time out and may be retried on other members.
## 12.6 Multiple Members
You can run **multiple calculation member instances** (same or different processes) with the same tags for horizontal scaling and high availability. The platform selects one eligible member per request, preferring members connected to the local cluster node. Running at least two members ensures continued processing if one goes down.
## 12.7 Monitoring
Track these metrics in your client:
- **Request count** by type (processor vs. criteria) and result (success vs. failure)
- **Response latency** (time from receiving request to sending response)
- **Keep-alive response time**
- **Reconnection count and frequency**
- **Stream errors** (by gRPC status code)
---
# 13. Quick Reference — Message Flow
```
Client Server
│ │
│──── startStreaming() ─────────────────────────►│ (open bidirectional stream)
│ │
│──── CalculationMemberJoinEvent ───────────────►│ (register with tags)
│◄─── CalculationMemberGreetEvent ───────────────│ (server confirms, assigns memberId)
│ │
│◄─── CalculationMemberKeepAliveEvent ───────────│ (periodic heartbeat probe)
│──── EventAckResponse ─────────────────────────►│ (ack the probe)
│ │
│◄─── EntityProcessorCalculationRequest ─────────│ (process this entity)
│──── EntityProcessorCalculationResponse ───────►│ (here's the result)
│ │
│◄─── EntityCriteriaCalculationRequest ──────────│ (evaluate this criterion)
│──── EntityCriteriaCalculationResponse ────────►│ (matches: true/false)
│ │
│──── CalculationMemberKeepAliveEvent ──────────►│ (client-initiated heartbeat)
│◄─── EventAckResponse ─────────────────────────│ (server acks)
│ │
```
---
# 14. Troubleshooting
| Symptom | Likely Cause | Fix |
|---|---|---|
| `UNAUTHENTICATED` on stream open | Missing/invalid/expired JWT token | Refresh JWT before connecting. Ensure `Authorization: Bearer ` header. |
| `NOT_FOUND` after JWT validation | User not found in Cyoda for the given JWT | Verify user enrollment and legal entity configuration. |
| Greet event has `success: false` | Subscription limit exceeded (max client nodes) | Check your subscription plan limits. |
| Stream closed with `DeadlineExceeded` | Nothing sent within `CYODA_KEEPALIVE_TIMEOUT` (default 30 s) | Ensure a non-blocking, fast keep-alive handler; check network latency. Reconnect per [Section 12.1](#121-reconnection-strategy). |
| Requests not arriving | Tags mismatch | Verify your member's tags are a superset of the workflow processor's `calculationNodesTags`. Tags are case-insensitive. |
| Requests not arriving | Member on wrong legal entity | Requests only route to members in the same legal entity as the entity owner. |
| Request timeout | Business logic too slow | Optimize processing time or increase `responseTimeoutMs` in workflow config. |
| Duplicate requests | Retry policy triggered | Implement idempotency using `requestId`. |
| Stream drops unexpectedly | Server restart, network issue, idle timeout | Implement reconnection with exponential backoff (Section 12.1). |
| `authtype` is `system` unexpectedly | Workflow triggered by an internal platform action (e.g., scheduled transition) or no user context was available | This is expected for system-initiated workflows. If you expect a user context, verify the originating API call is authenticated. |
| `authclaims` is missing | The triggering principal is a plain `IUser` without extended claims, or the auth type is `system` | Only `user` and `service` auth types include claims. Check `authtype` before parsing claims. |
| `authtype` is `service`, not `service_account` | `service_account` is not a value the platform emits | Switch on `service` instead. See [Section 9.2](#92-auth-type-values). |
| Callout never arrives; dispatch fails | The originating principal's kind is unset or unrecognized | Dispatch fails closed rather than sending a bogus `authtype`. Check the principal's kind on the platform side. |
---
## build/edge-messages.md
# Edge messages
The edge-message store — a durable, tenant-scoped staging buffer at the platform edge, a peer of the entity store.
An **edge message** is an arbitrary JSON payload stored under a server-generated time-UUID together with a fixed set of AMQP-aligned headers and an optional flat metadata map. The store is standalone: a message is **not** an entity, and creating one does not touch the workflow engine — no transition fires, no processor or criterion runs. Edge messaging is a durable, tenant-scoped staging buffer at the platform edge, a peer of the entity store rather than part of it.
Reach for it when you need to accept and durably hold inbound payloads before they become entities — a landing zone for messages you will validate, correlate, or replay into the entity model on your own schedule.
## Posting a message
```bash
curl -X POST http://localhost:8080/api/message/new/orders-inbound \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"payload": { "orderId": "ORD-42", "raw": "..." },
"metaData": { "source": "edi-gateway", "batch": "2026-07-09-A" }
}'
```
The `{subject}` path segment (`orders-inbound` above) names the logical channel. The optional metadata map is carried under `metaData` (camelCase, symmetric with the response). The server assigns the time-UUID and returns it.
For the full surface — headers, retrieval, and the exact envelope — run `cyoda help messages` against your binary; the callout above links the authoritative reference.
## Where to go next
- [Working with entities](/build/working-with-entities/) — promote a staged message into the entity model via the CRUD API.
- [Client compute nodes](/build/client-compute-nodes/) — react to workflow transitions over gRPC.
---
## build/modeling-entities.md
# Modeling entities
Design patterns for entity schemas — boundaries, evolution, and validation.
Modeling well in Cyoda comes down to drawing the right boundaries between
entities, letting the schema grow with the data, and treating validation as
the job of the platform rather than the application layer. This page covers
the patterns worth knowing before you ship a first model.
## One entity per noun
The simplest rule: every domain noun that has an independent lifecycle is its
own entity. An `Order` has its own states, its own history, and its own audit
trail; so does a `Customer`. They relate via references, not by embedding.
A useful test: *does this thing change on its own clock?* If yes, it's an
entity. Line items on an order often do not — they live inside the order's
state transitions — so they stay embedded. Fulfilment events on an order do —
they have their own lifecycle — so they become their own entity, referenced
by the order.
## Two modes: discover or lock
Cyoda gives you two structural contracts for an entity model. The right
choice depends on how exposed the model is to outside producers.
**Discover (loose).** For a new model you do not write a schema file. You post
a representative sample, and Cyoda records the fields, their types, and the
shape of nested arrays and objects.
Post one JSON object as a single sample document, or a JSON array of objects
as several. Cyoda merges the array elements exactly as it merges successive
imports. Any other body, such as a scalar or an array that holds a non-object,
is `400 VALIDATION_FAILED`. The message names the element that caused the
failure.
New samples **widen** the schema. A field seen first as `INTEGER` and later as
`STRING` declares both types. Use discover mode when you prototype, when you
explore a dataset, or when the contract with upstream producers is not yet
fixed.
The **length** of an array is not part of the model. A field declared as an
array of strings holds an array of any length, at every change level. No path
addresses the count of elements.
**Lock (strict).** Once the shape is stable, lock the model. After
locking, any incoming entity that does not structurally match the current
schema is **rejected**. This is the right default for production systems
with external interface contracts — a trading system receiving FpML
confirmations, a payments pipeline consuming an agreed message format, a
regulated workflow whose processor logic is tailored to a specific
shape. In those contexts a silently widened schema is a latent bug at
best and a compliance failure at worst: if an upstream does an
uncoordinated FpML version upgrade, you want the new-shape messages
rejected at the door, not accepted and fed into processors that were
built against the old shape.
These two modes together cover the spectrum. Cyoda deliberately does
**not** layer a Confluent-style forward/backward/full compatibility
taxonomy on top: "compatible" is not a platform-generic concept when the
workflow (your app code) is part of the contract. Only the application
can judge whether adding an optional field, widening an integer to a
string, or dropping a field leaves its transition logic valid. The
platform contract is the simpler and stricter pair: loose discovery, or
lock-and-reject.
## What a field declares
A field declares a **set of kinds**: scalar, object and array. For a scalar, it
also declares a set of types. Cyoda enforces every kind that the field
declares, and every declared kind is admissible at every change level. A field
declared `STRING` accepts a string. It rejects an array or an object with
`400 VALIDATION_FAILED`, and the message names each kind that the field
declares.
A field declares more than one kind when Cyoda observes it in each kind. This
happens while the model is `UNLOCKED`, or through a `STRUCTURAL` change on a
locked model.
A field admits a **value** when both of these hold: the value's kind is one the
field declares, and the declared type's admission test accepts the value. Cyoda
applies the test per value. For example:
- A field declared `DOUBLE` accepts `1000`, `1000.0`, `1e3` and `2147483648`
with no schema change. The precision and scale of each value fit `DOUBLE`.
- The same field needs a [`TYPE` change](#the-change-level-ladder) for
`9007199254740993`. That value needs
sixteen significant digits, which is more than `DOUBLE` holds exactly. At
`TYPE`, the field widens to `UNBOUND_DECIMAL`, the narrowest type that holds
both values.
- A field declared `STRING` holds `"2026-03-01"` with no schema change, because
`STRING` admits every string. A field acquires a temporal type such as
`LOCAL_DATE` at **registration**, from sample data that shows a date-shaped
value.
`null` follows the declaration like any other value. A scalar field always
accepts `null`. A container field accepts `null` where the model observed it.
`null` does not widen the model.
## Field names must be addressable
A field name must be a valid path segment: one or more ASCII letters, digits,
`_` or `-`. Cyoda rejects any other name with `400 VALIDATION_FAILED`, and the
message names the key and the object that declares it. Rejected characters
include spaces, dots, quotes, brackets, `$`, `@`, `:`, the metacharacters
`*`, `?`, `#`, `|`, `!` and `\`, and any non-ASCII character. An empty name is
also rejected.
Search addresses a field through a `jsonPath` built from this charset, and
there is no escape form. A name outside the charset is therefore not
searchable. For example, `$.a.b` addresses a nested `a` → `b`, not a field
called `a.b`.
The rule applies to the two paths that establish a model's field set:
sample-data import, and the change-level extension an entity write performs. It
does not apply to `PATCH`, or to strict validation, which is a model with no
change level. Neither of those establishes a field.
Cyoda does not migrate a model that already carries a non-conforming field, and
there is no compatibility mode. Rename the key in the source data and establish
the model again.
## Evolving a model
You evolve during discover mode by sending data: fields appear, types widen,
new kinds are declared. None of this is surprising until you lock.
After lock, evolution is **application-controlled**. The model has a
`modelVersion` that the application increments when it wants a new
structural contract. Each revision of each entity is tagged at write
time with the model version in force. Revisions are immutable: old
revisions are **not** re-validated, re-cast, or rewritten when a new
model version appears. A consumer reading an old revision reads it
under its original version; interpretation across versions is
application logic.
Concretely:
- **Add fields (pre-lock).** Send a sample that includes them; the
schema widens automatically.
- **Widen types (pre-lock).** A field observed holding values of more than one
type declares each of them, and a value is admitted when any declared type
admits it. See the [Trino SQL reference](/reference/trino/) for how the
primitive types map onto the analytical surface.
- **Lock.** Freeze evolution once the shape is stable. The default
stance for anything with external producers.
- **Bump `modelVersion` and register the new schema (post-lock).** A
locked model is a frozen contract; to accommodate a changed
structure the application bumps `modelVersion` and **registers the
new schema** for that version. Registration uses the same mechanism
as initial discovery: submit a comprehensive set of representative
samples that span the intended shape, and Cyoda infers the schema
from them. The samples themselves are **not stored** — they exist
only to define the shape of the new version. Once registered, lock
the new version so it too is a hard contract. If data written under
an older version needs to appear under the new shape, migrate it
explicitly via app code; the platform takes no stance on whether
the new shape is "compatible" with the old — that judgment belongs
to the workflow that consumes the data.
### The change-level ladder
A locked model can still be allowed to extend itself as entities are written,
by setting a `changeLevel` on it:
```
POST /model/{entityName}/{modelVersion}/changeLevel/{changeLevel}
```
The four levels are hierarchical, most restrictive first:
| Level | What a write may change |
|---|---|
| `ARRAY_LENGTH` | Nothing. The floor of the ladder — no schema change at all. |
| `ARRAY_ELEMENTS` | An array's element may learn its first scalar type, or widen the one it declares. Nothing outside an array. |
| `TYPE` | An existing field's declared types may widen. |
| `STRUCTURAL` | New fields, and giving a path a kind it does not yet declare. |
Two rules decide which level a write needs:
- A write that gives a path a **kind** it does not declare is a `STRUCTURAL`
change. An object written into a field declared `STRING` is an example.
- A write that gives a path a **value** that no declared type admits is a
`TYPE` change.
There is one exception. A path that declares no kind has nothing to conflict
with. A field observed only as `null`, or an array observed with no content,
learns its first kind at `TYPE`. For the element of an array, it learns its
first kind at `ARRAY_ELEMENTS`.
The change level governs data returned by a **workflow processor** in the same
way as data sent by a client. See
[the model governs the data a processor returns](/build/workflows-and-processors/#processors).
Things to plan explicitly:
- **Renames.** Cyoda does not rename a field for you; if you rename
in the source, you get a new field alongside the old one. Migrate
existing data deliberately.
- **Deletes and deprecations.** Same story — Cyoda will not silently
drop or re-interpret a field across a version boundary. The
application owns the migration.
- **Narrowing types.** Once the schema has observed `STRING` in a
field, you cannot narrow it to `INTEGER` within the same version.
To narrow, introduce a new `modelVersion` with the stricter type
and migrate the data.
- **Field names outside the addressable charset.** See
[field names must be addressable](#field-names-must-be-addressable).
## Who validates what
Cyoda validates **structure** and **types** against the model: the kinds each
field declares, the types its scalars declare, and the shape of nested objects
and array elements. You do not write those validators.
Cyoda also refuses a payload that is valid JSON but not storable. This applies
on every backend and on both transports. See
[what the platform will not store](/build/working-with-entities/#what-the-platform-will-not-store).
Your application is responsible for **semantic** validation that lives inside
transitions: "the order total must equal the sum of line items", "the
payment currency must match the customer's currency". Those belong in
workflow criteria and processors where they can fail a transition and leave
the old revision intact.
## Uniqueness constraints
Beyond structure and types, a model can declare **composite unique keys** — multi-field uniqueness the engine enforces on create and update. Register them on an **UNLOCKED** model:
```
PUT /model/{entityName}/{modelVersion}/unique-keys
```
Each key is an ordered set of scalar field paths, and uniqueness is scoped to `(tenant, model, version)` over live (non-deleted) entities. The null rule is all-or-nothing: if every field in a key is null or absent the entity is exempt; a partial key is rejected with `422 INVALID_UNIQUE_KEY`; a fully-present key is enforced. String comparison is byte-exact, and soft-deleting an entity frees its value-set for reuse.
Composite unique keys are supported by the memory, SQLite, and PostgreSQL backends; the commercial backend returns `422 COMPOSITE_KEY_UNSUPPORTED` until its own support lands. Relevant error codes: `UNIQUE_VIOLATION` (409), `INVALID_UNIQUE_KEY` (422), `COMPOSITE_KEY_UNSUPPORTED` (422), and `INVALID_UNIQUE_KEY_DEFINITION` (422).
## Anti-patterns
- **The god-entity.** One model that tries to represent everything. Split it
along lifecycle boundaries; lifecycles that evolve independently want
separate entities.
- **Premature generalisation.** A model that tries to anticipate every future
field. Let the schema discover itself and lock when you are ready.
- **Shadow workflows.** Implementing state transitions as boolean flags on
the entity. Put states in a workflow; that's what workflows are for.
## Where to go next
- [Entities and lifecycle](/concepts/entities-and-lifecycle/) — the
conceptual model behind an entity.
- [Entity model export](/reference/entity-model-export/) — the wire
format of the SIMPLE_VIEW and JSON_SCHEMA exports: node descriptors,
type descriptors, and the JSON Schema for the response.
- [JSON schema reference](/reference/schemas/) — the REST-API message
schemas generated from cyoda-go.
- [Workflows and events](/concepts/workflows-and-events/) — how state
and transitions are configured.
---
## build/searching-entities.md
# Searching entities
Query sets of entities over REST — direct vs async modes, predicates, pagination, and historical reads.
Cyoda exposes search over REST for any query that returns a set of
entities. Use it when you need more than one entity back, when the filter
goes beyond a single id lookup, or when you want to scope by workflow
state. For single-entity reads, stay on the CRUD endpoints in
[working with entities](/build/working-with-entities/); for cross-entity
analytics, use [SQL](/build/analytics-with-sql/); for event-driven
compute, use [gRPC compute nodes](/build/client-compute-nodes/). For
counts and aggregates without the entity bodies, jump to
[grouped statistics](#grouped-statistics).
## Two query modes
Cyoda splits search into **Immediate** and **Background** modes. Pick by
expected result size and urgency; the filter grammar is identical.
- **Immediate** (API term: `direct`) — synchronous. The request streams
matching entities back as NDJSON. It is **bounded-or-fail**: `limit`
caps the *matched set*, and a query matching more than that fails
outright rather than returning part of the answer. Use it when you
know the filter produces a bounded, small set — a UI list, a lookup,
a small report.
- **Background** (API term: `async`) — queued. The request returns a
job handle; poll it, then page the results. Result size is
**unbounded**. On the Cassandra-backed tier (Cyoda Cloud, or a
licensed Enterprise install), `async` runs distributed across
the cluster: for a fixed query shape, throughput scales roughly
linearly with the number of nodes.
A direct search whose matched set exceeds the effective `limit` returns
`400 SEARCH_RESULT_LIMIT`. It does **not** return the first `limit`
entities. This is deliberate: a truncated page was indistinguishable
from a complete one, so callers silently processed partial data.
- `limit` defaults to **1000** when omitted, and caps at **10000**.
- `limit=0` — which once meant "unbounded" — is rejected with
`400 BAD_REQUEST`, as is any value below 1. gRPC rejects `limit < 1`
identically.
- A matched set exactly equal to `limit` succeeds.
When you hit it, narrow the condition, raise `limit` within the maximum,
or move the query to `async`.
The decision tree is short:
- Small bounded result, UI-facing → `direct`.
- Might be large, can tolerate a second or two of queuing; exports,
reports, batch jobs → `async`.
- Hitting `SEARCH_RESULT_LIMIT` or the request timeout → `async`.
- Ordered top-N over a large model → `async` (see
[sorting](#sorting-results)).
## A direct search
Filter by a combination of entity fields and workflow state:
```bash
curl -X POST 'http://localhost:8080/api/search/direct/orders/1?limit=200' \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"type": "group",
"operator": "AND",
"conditions": [
{ "type": "lifecycle", "field": "state",
"operatorType": "EQUALS", "value": "submitted" },
{ "type": "simple", "jsonPath": "$.customerId",
"operatorType": "EQUALS", "value": "CUST-7" }
]
}'
```
The path is `/api/search/direct/{entityName}/{modelVersion}`, and the request
body is the condition document itself — there is no wrapper object. `limit`,
`pointInTime`, `trackingRead`, `timeoutMillis` and `sort` are **query
parameters**, not body fields.
The response is `application/x-ndjson`: one complete entity envelope per line,
each carrying `data` plus a `meta` block with the id, model key, state, and
timestamps.
```
{"type":"ENTITY","data":{"customerId":"CUST-7"},"meta":{"id":"74807f00-…","state":"submitted","creationDate":"2026-03-01T10:00:00.000000000Z"}}
{"type":"ENTITY","data":{"customerId":"CUST-7"},"meta":{"id":"89abc100-…","state":"submitted","creationDate":"2026-03-02T11:30:00.000000000Z"}}
```
Because it is a stream, parse it line by line rather than buffering the whole
body as a single JSON document.
## An async search
Submit the search to `/api/search/async/{entityName}/{modelVersion}` and
capture the handle:
```bash
curl -X POST http://localhost:8080/api/search/async/orders/1 \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"type": "lifecycle",
"field": "state",
"operatorType": "EQUALS",
"value": "submitted"
}'
```
The response is a bare UUID string — the job id. Poll its status until the job
reports `SUCCESSFUL`, then page the results:
```
GET /api/search/async/{jobId}/status
GET /api/search/async/{jobId}?pageNumber=0&pageSize=1000
GET /api/search/async/{jobId}?pageNumber=1&pageSize=1000
```
The status response carries `searchJobStatus` (`RUNNING`, `SUCCESSFUL`,
`FAILED`, `CANCELLED`, or `NOT_FOUND`), `entitiesCount` for the total match
count, and `expirationDate`. Fetching results before the job is `SUCCESSFUL`
returns `400 BAD_REQUEST`.
Results come back as a paged JSON object — `content` plus a `page` block with
`number`, `size`, `totalElements` and `totalPages` — not as a stream. Job
results expire 24 hours after creation; a single `jobId` can be paged
repeatedly until then.
Async search never returns `SEARCH_RESULT_LIMIT`: it snapshots the whole
matched set and pages over it. An out-of-range `pageSize` or `pageNumber` is a
plain `400 BAD_REQUEST`.
The server translates the condition **before** it stores the job. A condition
that no backend can execute is refused at submission. The server then streams
the results to storage as the scan runs.
### Admission and backpressure
A fixed worker pool serves the submissions. When the workers and the submit
queue are both full, submission fails with a retryable
**`503 SEARCH_QUEUE_FULL`**.
| Variable | Default | Meaning |
|---|---|---|
| `CYODA_SEARCH_ASYNC_WORKERS` | `8` | Jobs that execute at the same time on this node |
| `CYODA_SEARCH_ASYNC_QUEUE` | `256` | Submissions that wait for a worker |
| `CYODA_SEARCH_ASYNC_MAX_PER_TENANT` | `8` | One tenant's share of queued **and** running jobs |
On a single-tenant deployment the in-flight ceiling is **8**, not
`workers + queue` (264). If you submit 50 jobs at once, the server accepts 8
and answers `503 SEARCH_QUEUE_FULL` for 42.
Raise the value, or set `0` to serve submissions first-come-first-served.
### Recovery after the loss of a node
A running job records its liveness every
`CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL` (default `15s`). It starts to do this at
submission, not at the start of the scan.
If the owning node stops before the job reaches a terminal status, a reaper
takes over. The reaper claims the job when the heartbeat has been silent for
`CYODA_SEARCH_JOB_STALE_AFTER` (default `5m`). It deletes the partial results
of the lost executor. It then runs the job again on a live node, at the
`pointInTime` stored with the job. The client sees a longer `RUNNING` period,
and the job ends `SUCCESSFUL`.
A reaped executor that recovers cannot write to a result set that another node
has taken over.
A job ends `FAILED` in three cases:
- The search itself failed.
- The job lost its executor `CYODA_SEARCH_JOB_MAX_ATTEMPTS` times (default `3`).
- The model's schema became unreadable between submission and execution.
A graceful shutdown releases its in-flight jobs immediately for reclaim. A
released claim does not count against the attempt cap, so a rolling restart of
any length is safe.
### Cancelling a job
If a job is no longer needed — the user navigated away, a replacement
query was submitted, the deployment is shutting down — cancel it rather
than letting it run to completion:
```bash
curl -X PUT http://localhost:8080/api/search/async/{jobId}/cancel \
-H "Authorization: Bearer $TOKEN"
```
Cancellation is cooperative. The server stops the work at the next safe point
and deletes any partial results for that `jobId`.
Cancellation succeeds only while the job is `RUNNING`. A job that is already
`SUCCESSFUL`, `FAILED` or `CANCELLED` returns
`400 SEARCH_JOB_ALREADY_TERMINAL`, with `currentStatus` and `snapshotId` in the
response properties.
## The condition DSL
The request body is a **`Condition`** document. Every condition carries a
`type` discriminator. The same DSL is used by workflow and transition criteria,
so what you learn here transfers directly.
**`simple`** — match a JSONPath into the entity payload:
```json
{ "type": "simple", "jsonPath": "$.amount",
"operatorType": "GREATER_OR_EQUAL", "value": 1000 }
```
**`lifecycle`** — match entity metadata rather than payload. `field` is one of
`state`, `creationDate`, `lastUpdateTime`, `transitionForLatestSave` (alias
`previousTransition`), `transactionId`, `id`:
```json
{ "type": "lifecycle", "field": "state",
"operatorType": "EQUALS", "value": "submitted" }
```
**`group`** — combine conditions. `operator` is `AND`, `OR` or `NOT`,
case-sensitive; anything else is `400 INVALID_CONDITION`. Groups nest to a
maximum depth of 50:
```json
{
"type": "group",
"operator": "AND",
"conditions": [
{ "type": "lifecycle", "field": "state", "operatorType": "EQUALS", "value": "submitted" },
{ "type": "simple", "jsonPath": "$.amount", "operatorType": "GREATER_OR_EQUAL", "value": 1000 }
]
}
```
**`array`** — match positional values in a JSON array. The path addresses the
array's **elements**, so it must carry a trailing `[*]`; a bare path is
`400 INVALID_FIELD_PATH`. A `null` entry tests nothing at that index:
```json
{ "type": "array", "jsonPath": "$.laureates[*]",
"values": ["John", null, "Hopfield"] }
```
Each non-null entry is a positional test, and the server combines the tests
with `AND`. The example matches when element 0 equals `"John"` **and** element
2 equals `"Hopfield"`. A `values` array of only `null` entries matches every
entity.
**`function`** — delegate the predicate to a compute node. This clause is
**criteria-only**. Criteria and search share one condition DSL, but search does
not accept a `function` clause. The server rejects a `function` clause at any
depth in a search, async-search, grouped-statistics or conditional-delete body
with `400 INVALID_CONDITION`. See
[workflows and processors](/build/workflows-and-processors/) for its use as a
transition criterion.
`operatorType` also accepts the spellings `operator` and `operation`. The
available operators are:
| Group | Operators |
|---|---|
| Comparison | `EQUALS`, `NOT_EQUAL`, `GREATER_THAN`, `GREATER_OR_EQUAL`, `LESS_THAN`, `LESS_OR_EQUAL` |
| Range | `BETWEEN`, `BETWEEN_INCLUSIVE` — `value` must be a two-element `[low, high]` array |
| Presence | `IS_NULL`, `NOT_NULL` |
| String | `CONTAINS`, `STARTS_WITH`, `ENDS_WITH` and their `NOT_*` inverses |
| Case-insensitive | `IEQUALS`, `INOT_EQUAL`, `ICONTAINS`, `INOT_CONTAINS`, `ISTARTS_WITH`, `INOT_STARTS_WITH`, `IENDS_WITH`, `INOT_ENDS_WITH` |
| Pattern | `LIKE` (anchored glob), `MATCHES_PATTERN` (anchored RE2 regex) |
The server rejects an operator outside this list, and a missing `operatorType`,
with `400 INVALID_CONDITION`. The error detail lists the valid operators. Every
surface that carries a condition uses this code, including workflow import.
`IS_CHANGED` and `IS_UNCHANGED` are change-generation operators, not search
predicates. cyoda-go does not implement them.
An empty body (`{}`), or any body without a `type`, is rejected with
`400 BAD_REQUEST`. To match every entity in the model, send a vacuous `AND`
group:
```json
{ "type": "group", "operator": "AND", "conditions": [] }
```
An `AND` group with no conditions is `true`; an `OR` group with no conditions
is `false`.
## How a field path is written
A `jsonPath` is JSON Path. The server checks it at the API boundary, before
anything executes. One scanner enforces this grammar for search conditions,
workflow criteria, `groupBy` and aggregation fields. A
[sort key](#sorting-results) uses the same segment charset, with one
difference: its `$.` leader is optional.
```
jsonPath = "$." segment ( "." segment )*
segment = name subscript*
name = 1*( ALPHA / DIGIT / "_" / "-" ) ; ASCII only
subscript = "[" ( "*" / 1*DIGIT ) "]" ; the index must fit an int32
```
The `$.` leader is **required**. A bare `amount` is not a path, and it is not
an alias for `$.amount`. The server rejects these paths with
`400 INVALID_FIELD_PATH`:
- A bare name, such as `amount`.
- An empty path.
- An empty or trailing segment, such as `$..a` or `$.a.`.
- Bracket-quoted property access, such as `$['x']` or `$.a["b"]`. Write `$.x`.
- Any character outside the segment set.
**The syntax of a path decides what the path addresses.**
| Path | Addresses | On `{"tags": []}` |
|---|---|---|
| `$.tags` | The array itself | `NOT_NULL` is true |
| `$.tags[*]` | Every element | `IS_NULL` and `NOT_NULL` are both false |
| `$.tags[0]` | One position | `IS_NULL` is true |
A leaf on `$.tags[*]` is true when **some** element satisfies it. For example,
`$.tags[*] EQUALS "red"` selects the entities whose `tags` contains `"red"`.
Write one `[*]` for each array level, as in `$.matrix[*][*]` and
`$.orders[*].lines[*].sku`. A trailing `[*]` over an array of objects under a
scalar operator is `400 INVALID_FIELD_PATH`. The element has no scalar form, so
address the leaf instead: write `$.items[*].sku`, not `$.items[*]`.
The server rejects every other bracket form with `400 INVALID_FIELD_PATH`:
unclosed or unmatched (`$.a[`, `$.a]`), no field name before it (`$.[0]`),
empty (`$.a[]`), negative or signed (`$.a[-1]`), a slice (`$.a[0:2]`), a union
(`$.a[0,1]`), a filter expression (`$.a[?(@.x)]`), whitespace inside
(`$.a[ 0]`), or an index too large for a signed 32-bit integer. The server
scans the full path, so it also rejects text after a valid subscript, such as
`$.a[0]b` or `$.a[0];DROP`.
**A field declared in more than one kind stays searchable through each kind.**
The server accepts a path that is valid for at least one declared branch. For
each entity, the predicate applies to the branch that the entity's data uses.
An entity on a different branch does not match. It is not an error.
For a field declared as both string and array-of-string, `$.a EQUALS "A"`
selects the scalar-shaped entities. `$.a[*] EQUALS "A"` selects the
array-shaped entities. The server accepts both conditions.
This grammar does not apply to lifecycle metadata. A `lifecycle` condition
names a meta field directly.
## Negation with `NOT`
`NOT` inverts the answer of its child condition. `NOT(c)` is true when `c` is
false.
`NOT` takes **exactly one** child condition. Zero children, or two or more, is
`400 INVALID_CONDITION`. To negate a group, nest the group inside the `NOT`:
```json
{
"type": "group",
"operator": "NOT",
"conditions": [
{ "type": "simple", "jsonPath": "$.tags[*]", "operatorType": "EQUALS", "value": "red" }
]
}
```
- **Over a wildcard path, `NOT` is a universal quantifier.** The leaf beneath
it stays existential. `NOT($.tags[*] EQUALS "red")` matches when **no**
element equals `"red"`. `$.tags[*] NOT_EQUAL "red"` matches when **some**
element is different. For `{"tags": ["red", "blue"]}` the first is false and
the second is true.
- **`NOT` matches an empty list, an explicit `null` and an absent field.** The
wrapped leaf is false in all three states. On an entity with no `x`,
`NOT($.x EQUALS "A")` matches. Both `$.x EQUALS "A"` and `$.x NOT_EQUAL "A"`
do not match.
- **The server does not apply De Morgan's laws to `NOT`.** `NOT(EQUALS)` is not
`NOT_EQUAL`. `NOT(IS_NULL)` is not `NOT_NULL`. The server does not distribute
a `NOT` group over its children.
There is no "every element" operator, and `NOT` does not build one. On
`{"tags": ["red", null]}`, `NOT($.tags[*] NOT_EQUAL "red")` looks like "every
tag is red", and it matches: the leaf is false at the `null` element, so the
`NOT` is true. A `null` element makes any such construction report success.
`NOT` is residual-only. No backend pushes a `NOT` into its own query language.
The in-process kernel evaluates it.
## Predicate semantics
Search and workflow criteria run on **one shared evaluation kernel**, so a
predicate means the same thing wherever you write it. The kernel implements
Cyoda Cloud's model; `cyoda help predicates` is the exhaustive reference.
**Comparison is type-directed and same-type.** An operand is parse-tested
against the field's declared type(s), so the JSON number `30` and the string
`"30"` behave identically. There is no cross-type coincidental matching: an
operand that parses only as a number never matches a string-stored value.
Numbers compare at arbitrary precision, so values beyond 2^53 are exact.
**An operator that can never be satisfied still answers.** The server accepts
an operand that parses into at least one declared type, then compares it
against each stored-value type family. Where no stored value of that type can
equal the operand, a **positive** operator answers non-match and a **negative**
operator answers match.
For example, `$.n NOT_EQUAL 12.5` on a field declared `INTEGER` returns every
entity that holds a number at `n`, because no integer equals `12.5`. Take care
with a negative operator in a conditional delete: it selects this wider set.
**Absent and null fields never match a binary operator — including
negatives.** `NOT_EQUAL`, `NOT_CONTAINS`, `INOT_*` and the rest are
null-guarded to non-match rather than evaluated as `!positive`. A missing field
does not satisfy `NOT_EQUAL` just because it fails `EQUALS`. Use `IS_NULL` and
`NOT_NULL` to test presence — they are the only operators that do. `NOT` is not
a binary operator, so this guard does not apply to it. See
[negation](#negation-with-not).
**`LIKE` is a glob.** The server matches the operand directly. It does not
translate the operand into a regular expression, so a regex metacharacter has
no special meaning. Three characters are special:
| Character | Matches |
|---|---|
| `%` | Any sequence of characters, including an empty sequence and a newline |
| `_` | Exactly one character (one UTF-8 rune), including a newline |
| `\` | Escapes the next character to its literal form |
So `\d` matches the letter `d`, and `\\` matches one backslash. The match is
whole-string anchored and case-sensitive. Wildcards match rune by rune, and the
server compares every other character byte by byte. A pattern that ends with an
unpaired `\` is rejected. To match a literal backslash at the end, write
`\\`.
`MATCHES_PATTERN` is a whole-string-anchored RE2 regular expression. RE2 is
different from the Java dialect for some constructs, such as backreferences and
some lookaround. The operand must parse on its own, and it must also compile
when the server anchors it.
**Temporal fields compare chronologically**, not lexically, across
`LOCAL_DATE`, `LOCAL_DATE_TIME`, `LOCAL_TIME`, `ZONED_DATE_TIME`, `YEAR` and
`YEAR_MONTH`. The `creationDate` and `lastUpdateTime` meta fields accept a
*coarser* operand that upscales — `"2024"` or `"2024-09"` are valid against a
full timestamp.
**Validation is parse-based**, evaluated against the target model:
- `400 CONDITION_TYPE_MISMATCH` — the operand parses into none of the field's
declared types. Comparison and range operators only; string and pattern
operators and presence tests carry no operand-type constraint.
- `400 INVALID_FIELD_PATH` — the path is outside the
[grammar](#how-a-field-path-is-written), is unknown to the model, or names a
container with no scalar form: a bare object path, or a `[*]` path over an
array whose elements are only ever objects. Navigate to a scalar leaf
instead. A path declared in more than one kind stays searchable through its
scalar kind — see [how a field path is written](#how-a-field-path-is-written).
`IS_NULL`/`NOT_NULL` are exempt from the container rejection, since they test
presence rather than a value.
- `400 INVALID_CONDITION` — a structural or shape failure rather than a path or
type one: an unknown or missing `operatorType`, a `null`, object or complex
operand on a binary or range operator, a range operand that is not a
two-element array, a malformed `LIKE`/`MATCHES_PATTERN` operand, a string or
pattern operator on a temporal meta field, an `array` clause on a bare path,
or a `function` clause at any depth.
- `500` — the server could not load or parse the model's schema, so it could
not check the condition against the schema. The response carries a ticket id
and no result set. A condition that contains only `lifecycle` clauses needs
no schema, and the server answers it normally.
There is no operator-versus-type rejection on a data path. `CONTAINS` against a
numeric field is a valid request, and it evaluates to a non-match. The
exception is the two temporal meta fields. A string or pattern operator on
`creationDate` or `lastUpdateTime` is `400 INVALID_CONDITION`.
## Historical reads with `pointInTime`
Every search accepts a `pointInTime` parameter to run against the world
as it existed at a given timestamp. Each entity maintains a history of
revisions; point-in-time queries return results using the entity state
that was current at the specified timestamp. The result is the set of
entities that would have matched, using the revision active at that
time.
The rule is canonical across every storage engine and read path: **inclusive of the requested instant** (`<=`), compared at native precision with no millisecond round-up.
`pointInTime` is a **query parameter** (RFC 3339), not a body field:
```bash
curl -X POST 'http://localhost:8080/api/search/direct/orders/1?pointInTime=2026-03-01T00:00:00Z' \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"type": "lifecycle", "field": "state",
"operatorType": "EQUALS", "value": "submitted"
}'
```
This is the primary way to answer audit and regulatory questions from
REST — *what did this customer's open orders look like at quarter
close?* The Trino surface exposes the same capability as a column named
`point_time` (snake-case, matching SQL convention); for the analytical
form, see [`point_time` in analytics](/build/analytics-with-sql/).
## Sorting results
Both search endpoints (direct and async) accept sort keys. Over HTTP, add one or more `sort` query parameters using the grammar `[@]path[:asc|desc]`:
- a bare dotted path sorts on a **scalar data field** (`amount`, `customer.tier`);
- an `@`-prefix sorts on a **meta field** — one of `state`, `creationDate`, `lastUpdateTime`, `transitionForLatestSave`, `transactionId`, `id`;
- direction defaults to `asc`.
```
POST /api/search/direct/orders/1?sort=@state&sort=amount:desc
```
Ordering is **canonical across every backend**: text by byte order, numeric by IEEE-754 double, bool as `false < true`. Meta date fields order chronologically; temporal *data* paths are ordered as text, which for ISO-8601 values coincides with chronological order. Note that this is the **sort** contract — predicate *comparison* uses the arbitrary-precision, type-directed rules described under [predicate semantics](#predicate-semantics). Absent or null values sort last, and the entity id is always the final tiebreaker. An unsortable, array, or unknown path is rejected with `400 INVALID_FIELD_PATH`, as is exceeding the sort-key cap set by `CYODA_SEARCH_MAX_SORT_KEYS` (default `16`; see the [configuration reference](/reference/configuration/#vars-search)).
A sort key is a scalar path over the same segment charset as a condition path,
with one difference: the `$.` leader is optional. `$.year:desc` and `year:desc`
are the same key.
The server rejects an array subscript or projection, such as `$.items[*].name`
or `$.items[0].name`, with `400 INVALID_FIELD_PATH`. An ordering needs one
scalar value per entity.
Over gRPC the same capability is a structured `orderBy` array, over the same
grammar and the same resolver.
Sorting a direct search does not let you take the top N of a large
population. Because direct search is bounded-or-fail, the *whole matched set*
must fit within `limit` before ordering is applied — so `sort` plus a small
`limit` over a large model returns `400 SEARCH_RESULT_LIMIT` rather than the
first N rows.
Run these as async searches, which snapshot the full matched set and page over
it in order.
### Paging (async)
- `pageSize` and `pageNumber` are query parameters on `/search/async/{jobId}`; they apply at result-fetch time, not at job submission. `pageNumber` is zero-indexed.
- A completed `jobId` is stable for its 24-hour retention window — page reads are idempotent.
## Searching inside a transaction
A search issued inside an active transaction is **read-your-own-writes
correct**: it sees that transaction's uncommitted writes, without falling back
to a full-model scan. The memory and SQLite backends overlay the transaction
buffer on the committed stream; PostgreSQL runs the query natively on the
transaction's own connection.
By default the search is a plain snapshot read that records nothing. Pass
`trackingRead=true` to opt into recording the entities the search **returns**
into the transaction's read-set, so that a concurrent commit touching any of
them aborts your transaction with `409 Conflict` at commit time:
```
POST /api/search/direct/orders/1?trackingRead=true
```
The protection is entity-level, the same as a `GetAll` read. Neither setting
protects against **phantoms** — an entity that starts matching your predicate
after the snapshot was taken is not detected either way. The flag is ignored
outside a transaction, and async search does not expose it at all, since it
runs detached.
## Bounding a search
The server translates every condition into a backend query. A condition it
cannot translate is `400 INVALID_CONDITION`, or `400 INVALID_FIELD_PATH` for a
path failure. The same rule applies to search, conditional delete and grouped
statistics, so all three answer a given condition the same way.
No backend meters the rows a search examines, and the server sets no time
budget. It bounds search *results*, not search *time*. A direct search is
bounded-or-fail on `limit`. An async search bounds neither duration nor result
count. Two controls bound the time:
- `timeoutMillis` on a direct search.
- Cancellation on an async job.
If you supply neither, the search is unbounded. The one server-side exception
is an operator-configured ceiling on the async scan,
`CYODA_POSTGRES_SEARCH_STATEMENT_TIMEOUT`.
```
POST /api/search/direct/orders/1?timeoutMillis=5000
```
`timeoutMillis` has no default. When the time elapses, the server stops the
search and fails the request with `408 SEARCH_TIMEOUT`. It returns **no partial
results**.
The server rejects `timeoutMillis` with `400 BAD_REQUEST` on a non-positive
value, and on a request that
[joins an open transaction](/build/client-compute-nodes/#1031-transaction-joined-callbacks).
## Performance notes
- Scope by `state` or a high-selectivity field first — the workflow
state is indexed on every entity and is almost always the right
first predicate.
- Prefer `async` as soon as the result set might be thousands of
entities; the distributed execution on the Cassandra tier makes it
cheaper per entity than a series of `direct` pages.
- Avoid open-ended `pointInTime` scans across every revision — anchor
the query at a specific timestamp or a short window.
- On PostgreSQL, supported predicates push down into SQL — JSONB extraction plus numeric, range, and string comparisons run in the database. Non-pushable operators (regex, case-insensitive) are post-filtered as rows stream. This removes full-model scans and per-document decode; it is a constant-factor win, not a JSON-path index (indexing queried paths remains a separate operational step). SQLite already does this; the in-memory backend filters in memory by design.
- Pushdown is a **narrowing optimization only** — the in-process kernel remains authoritative for every match decision, so results never diverge between backends. Pushdown applies inside transactions too, so an in-transaction search does not degrade into a full-model scan.
- Boolean conditions on PostgreSQL are pushed down correctly as of v0.8.3. Previously an `EQUALS`/`NOT_EQUAL` against a boolean field returned `500`, because the planner bound a raw Go `bool` against a text-typed JSON extraction that the driver cannot encode.
- A `NOT`, and a wildcard path under a scalar operator, are residual. The kernel re-checks them as candidate rows stream. Put a selective pushable predicate in the same `AND` group to narrow the population first.
## Grouped statistics
When you want **counts and aggregates** rather than the entities
themselves — *how many orders are in each state? what is the total
amount per country?* — use the grouped-statistics query instead of
paging a search result and summing client-side. It returns one row per
group and never the underlying entity bodies, so it stays cheap over
large populations.
```http
POST /entity/stats/{entityName}/{modelVersion}/query
```
```bash
curl -X POST http://localhost:8080/api/entity/stats/orders/1/query \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"groupBy": ["state", "$.country"],
"aggregations": [
{ "op": "sum", "field": "$.amount", "as": "totalAmount" },
{ "op": "avg", "field": "$.amount" }
],
"condition": {
"type": "simple",
"jsonPath": "$.channel",
"operation": "EQUALS",
"value": "web"
}
}'
```
The request has four parts:
- **`groupBy`** (required) — an ordered list of dimensions. Each entry is
either the literal `state` (the workflow state) or a `$.`-prefixed
JSONPath into the entity payload. The result `groupKey` is ordered to
match. Duplicate entries are `400 DUPLICATE_GROUP_BY`.
- **`aggregations`** (optional) — per-group numeric aggregates. Each is
`{ "op", "field", "as" }` where `op` is one of `sum`, `avg`, `min`,
`max`, `stdev`, `field` is a JSONPath, and `as` is an optional alias
(defaults to `op(field)`, e.g. `sum($.amount)`). Every group also
carries a `count` whether or not you request aggregations.
- **`condition`** (optional) — a predicate that restricts the population,
using the **same** [condition DSL](#the-condition-dsl) as search.
- **`limit`** (optional) — caps the number of buckets returned; must be
≤ the server's `CYODA_STATS_GROUP_MAX` (default 10000).
The response is one bucket per group:
```json
[
{
"groupKey": [
{ "field": "state", "value": "submitted" },
{ "field": "$.country", "value": "GB" }
],
"count": 31,
"aggregations": { "totalAmount": 48210.0, "avg($.amount)": 1555.16 }
}
]
```
Aggregation values are numeric, or `null` when a group has no eligible
inputs.
Both `groupBy` and an aggregation `field` follow the same
[path grammar](#how-a-field-path-is-written) as a search condition, but they do
not accept array subscripts. A group key must be a single scalar. The server
rejects `$.items[*]` and `$.items[0]` with `400 INVALID_GROUP_BY_PATH` for a
`groupBy` entry, or `400 INVALID_AGGREGATION_FIELD` for an aggregation.
There is also no dotted form for an array position. `$.items.0` names a field
called `0`, not an element.
The server validates each path against the model. A path that names an
undeclared field is rejected.
### Point-in-time statistics
Like search, the query accepts a `pointInTime` to aggregate the world
**as it existed at a past instant** — without standing up a derived
counter entity that processors must maintain on every transition. Add it
to the request body:
```json
{
"groupBy": ["state"],
"pointInTime": "2026-03-31T23:59:59Z"
}
```
This answers end-of-quarter and audit roll-up questions directly — *how
many claims were pending at midnight on the last day of Q1?* When
omitted, the query runs against the current consistency time.
## Where to go next
- [REST API reference](/reference/api/) — authoritative search payload
schema, operator grammar, status and result endpoints.
- [Working with entities](/build/working-with-entities/) — single-entity
CRUD and transitions; the CRUD page for reference on the same
surface.
- [Analytics with SQL](/build/analytics-with-sql/) — heavy analytical
work, cross-entity joins, historical scans via `point_time`.
- [Entities and lifecycle](/concepts/entities-and-lifecycle/) — the
audit/history model behind `pointInTime`.
---
## build/testing-with-digital-twins.md
# Testing with digital twins
In-memory mode as a test harness; running simulations at volumes exceeding production.
In Cyoda, a "digital twin" means the same application code — workflows,
criteria, processors — runs identically on every storage tier. Non-functional
properties (persistence, latency, concurrency model) differ; business logic
does not.
cyoda-go's **in-memory mode** is the built-in test harness. It runs the entire
platform — entity store, workflow engine, API surfaces — in a single process
with no external dependencies and no disk writes. It is the fastest way to
exercise workflow behaviour in CI, and the cheapest way to run large
scenario simulations against your application logic.
## In-memory mode as a test harness
Start cyoda-go with the in-memory profile (or `go run ./cmd/cyoda` against the
default in-memory config). Concretely: set `CYODA_STORAGE_BACKEND=memory`, or
leave it unconfigured — memory is the application default until `cyoda init`
is run. Point your tests at it; tear it down between cases; no database to
seed, no files to clean up.
Properties that matter for testing:
- **Deterministic.** Same inputs, same state, same result.
- **Fast.** Sub-millisecond latencies mean you can run thousands of transitions
per test.
- **Isolated.** Nothing survives the process; tests cannot leak state into
each other.
- **API-identical.** Your application code calls the same REST and gRPC
endpoints it will call in production.
This makes in-memory mode suitable for unit-level tests of your processors,
integration tests of your whole workflow, and smoke tests in CI.
## Digital-twin simulations
Beyond unit tests, in-memory mode is a **digital-twin runtime**: a
behavioural clone of production that you can drive at volumes and rates your
real system could never sustain. Because there is no durable backend, no
rate-limited external API, and no shared-state concern, you can:
- Replay a year of historical transactions in minutes.
- Fan out thousands of concurrent scenario runs across CPUs.
- Stress the workflow with injected event streams that exceed production
peak by multiples.
The application logic — workflows, criteria, processors — is the same
application that runs against PostgreSQL or Cyoda Cloud. The **only**
things that differ between in-memory and durable tiers are non-functional:
persistence, latency profile, and scale ceiling. That's the property that
makes the in-memory run a useful twin of the durable one.
## What stays the same, what changes
Same:
- API contracts (REST, gRPC today; Trino upcoming — see the [Trino reference](/reference/trino/)).
- Workflow semantics: states, transitions, criteria, processors.
- Event ordering within a transition.
- Audit-trail shape.
Different:
- Durability (none in-memory).
- Concurrency model (no multi-node contention).
- Performance envelope (faster, lower variance).
If your test depends on *durable* behaviour — restart recovery, cross-node
consensus, cross-process replay — graduate it to a SQLite or PostgreSQL run
for that suite. For everything else, in-memory is the default.
## Examples
Worked examples live in
[cyoda-go/examples](https://github.com/Cyoda/cyoda-go/tree/main/examples),
including scenario-simulation runners you can adapt as a template. When a
cyoda-go release ships a new example, this page links it.
## Where to go next
- [Digital twins and the growth path](/concepts/digital-twins-and-growth-path/)
— the concept behind same-app-different-tier.
- [Run → overview](/run/) — choosing a tier for the other side of the twin.
---
## build/workflows-and-processors.md
# Workflows and processors
State-machine design, transitions, and external processors — with a preference for gRPC in compute nodes.
> Understanding Cyoda JSON workflow configurations.
## Overview
Cyoda workflows define finite, distributed state machines that govern the lifecycle of business entities in an event-driven environment. Each entity progresses through a sequence of states based on defined transitions, criteria, and processing rules.
:::tip[Use gRPC for compute nodes]
When implementing processors or criteria services, prefer gRPC over
HTTP. gRPC preserves audit hygiene and simplifies authorization.
See [APIs and surfaces](/concepts/apis-and-surfaces/) for the
decision rationale.
:::
The platform supports adaptable entity modeling, allowing business logic to evolve through configuration rather than implementation changes. Workflows declare the set of states, valid transitions, and associated processing steps while preserving immutable persistence for auditability.
## Workflow Architecture
### Core Components
1. **States**: Lifecycle stages of an entity
2. **Transitions**: Directed changes between states
3. **Criteria**: Conditional logic for transition eligibility
4. **Processors**: Executable logic triggered during transitions
## Configuration Schema
You can find the workflow schema in the [API reference](/reference/api/). See the workflow import endpoints for complete schema specifications. Here we explain the structure and meaning of each element.
### Workflow Object
```json
{
"version": "1.4",
"name": "Workflow Name",
"desc": "Workflow description",
"initialState": "StateName",
"active": true,
"criterion": {},
"states": {}
}
```
#### Attributes
- `version`: Workflow schema `MAJOR.MINOR` version. The current version is
`"1.4"` (cyoda-go v0.8.4); the server accepts `"1.1"` through `"1.4"` and
stamps the current version on export. Malformed values such as `"1"` or
`"1.0"` are rejected at import. Run `cyoda help workflows schema-version` for the
authoritative supported range.
- `name`: Identifier for the workflow. Must be unique per entity model.
- `desc`: Detailed description of the workflow
- `initialState`: Starting point for new entities
- `active`: Indicates whether the workflow is active
- `criterion`: Optional criterion for selecting which workflow applies to a given entity. Uses the same condition types as transition criteria (simple, lifecycle, group, function). When multiple workflows are defined for a model, the platform evaluates each workflow's criterion against the entity to determine which workflow governs it.
- `states`: Map of state names to state definitions
### Multiple Workflows per Model
An entity model can have multiple workflows, each with its own `criterion` at
the workflow level. This allows different processing paths for different
categories of entities within the same model.
The engine selects the workflow on **every call**, and it caches nothing
between calls. Five operations select a workflow: entity creation, a named
transition, a loopback re-evaluation, a scheduled transition firing, and
`GET /entity/{entityId}/transitions`.
The engine applies these rules in order:
1. Read the workflows in stored declaration order. Storage keeps the order of
the most recent import, and `MERGE` adds new workflows at the end.
2. Skip each workflow whose `active` flag is `false`. Selection ignores an
inactive workflow, whatever its criterion.
3. Evaluate the `criterion` of each active workflow against the entity payload
and the lifecycle metadata. A `null` or absent criterion always matches.
4. Select the first active workflow whose criterion matches. The engine does
not read the later workflows.
5. If no active workflow matches, use the embedded default workflow. The engine
adds a warning to the response body and writes a log line that carries
`reason=no_criterion_matched`.
To make a workflow a catch-all, place it **last** in the import array and give
it no criterion. An active workflow declared after it is unreachable.
The engine audits selection under the transaction that drives the call. It
records a `WORKFLOW_SKIP` event for each skipped workflow, with the rejection
reason of the criterion, and a `WORKFLOW_FOUND` event for the selected one.
`GET /entity/{entityId}/transitions` is a read and records no event.
Because the engine evaluates selection on every call, two rules apply to the
field that a selection criterion reads.
**Select on a field that the caller cannot rewrite in the same request.** The
engine evaluates the criterion against the payload of the request that it
serves. A criterion over a client-writable field therefore lets one request
choose which definition guards it. Where definitions permit different
operations, the selection field is a security control. Select on an immutable
field, or on lifecycle metadata.
**Select on a condition that stays true for the whole life of the entity.** An
entity whose payload changes can bind to a different definition. If the new
definition does not declare the entity's current state, the engine does **not**
fall through to a definition that declares it. A named transition fails with
`400 WORKFLOW_FAILED`, and a loopback ends as a no-op. A new binding can also
discard a pending scheduled transition: the engine deletes the task when it next
becomes due, and records `SCHEDULED_TRANSITION_CANCEL` at that time, not at the
write.
### Annotations
Workflows, states, and transitions each accept an optional `annotations`
object — arbitrary client-owned JSON metadata that the engine **stores
and round-trips faithfully but never interprets**. Use it to attach
concerns that belong to your application rather than the state machine:
display labels and UI hints, permitted roles for application-level RBAC,
or routing tags consumed by your own tooling.
```json
{
"version": "1.4",
"name": "Payment Request Workflow",
"initialState": "INVALID",
"active": true,
"annotations": {
"ui": { "color": "#0aa7c2", "icon": "payment" },
"rbac": { "editRoles": ["payments-admin"] }
},
"states": {
"INVALID": {
"annotations": { "label": "Needs validation" },
"transitions": []
}
}
}
```
Each `annotations` value must be a JSON object and is capped at **64 KB**
per field. The engine never reads these values; they are yours to
produce and consume.
As of workflow schema **1.2**, the same `annotations` bag extends to the two elements that previously lacked it:
- **Processors** carry an embedded `annotations` object.
- **Criteria** carry a sibling `criterionAnnotations` object on the workflow and on each transition — the criterion tree itself round-trips verbatim and is never parsed to attach metadata.
Two well-known optional keys are recognised uniformly across all five element types (workflow, state, transition, processor, criteria) for renderer and condition-builder use:
- `displayName` — a short human label;
- `description` — a longer explanation.
The same rules apply everywhere: each value is a JSON object, capped at 64 KB, stored and re-emitted compacted, and **never interpreted by the engine**. Processor annotations are additionally stripped before dispatch and never reach compute members. This is an additive change — every existing 1.1 payload remains valid.
## Import and Export
Workflows are managed via import and export API endpoints on the entity
model. The import request supports three modes that control how
existing workflows are reconciled with the payload:
- **`MERGE`** (default): Incremental update. Workflows with matching names are updated; unspecified workflows remain unchanged.
- **`REPLACE`**: Removes all existing workflows for the entity model and retains only the imported ones. Also deletes all unused processors and criteria.
- **`ACTIVATE`**: Similar to REPLACE, but deactivates (rather than deletes) existing workflows and transitions not included in the import. Unused processors and criteria are preserved.
See [API reference](/reference/api/) for endpoint details and the full
request/response schemas.
### Strict validation
From cyoda-go v0.8.1 the import endpoint validates payloads strictly and
rejects the whole request rather than silently absorbing mistakes. A
payload is rejected when it:
- declares a schema `version` outside the supported range (currently
`"1.1"`–`"1.4"`) or malformed such as `"1"`/`"1.0"` (rejected with
`WORKFLOW_SCHEMA_VERSION_UNSUPPORTED`);
- carries unknown or misspelled fields (e.g. `transtions`);
- references a dangling state or reuses a name;
- relies on an empty array to mean "leave unchanged" in `REPLACE` or
`ACTIVATE` mode — an empty array now deletes.
Regenerate any import payloads authored against the older, lenient
contract before upgrading.
## States
States describe lifecycle phases for entities. Names must start with a letter and use only alphanumeric characters, underscores, or hyphens.
### Format
```json
"StateName": {
"transitions": []
}
```
#### Special States
- **Initial state**: The initial state of a new entity
- **Terminal States**: States with no outgoing transitions
## Transitions
Transitions define allowed movements between states, optionally gated by conditions and supported by executable logic.
### Format
```json
{
"name": "TransitionName",
"next": "TargetState",
"manual": true,
"disabled": false,
"criterion": {},
"processors": [],
"schedule": {} // one of delayMs | function
}
```
#### Attributes
- `name`: Name of the transition (required)
- `next`: Target state code (required)
- `manual`: Determines if the transition is manual or automated (required)
- `disabled`: Marks the transition as inactive
- `criterion`: Optional condition for eligibility
- `processors`: Optional processing steps
- `schedule`: Optional timer that fires the transition automatically — see
[Scheduled transitions](#scheduled-transitions). Mutually exclusive with
`manual: true`.
### Manual vs Automated Transitions
Transitions may be either **manual** or **automated**, and are guarded by criteria that determine their eligibility. When an entity enters a new state, the first eligible automated transition is executed immediately within the same transaction. This continues recursively until no further **automated** transitions are applicable, resulting in a stable state. Each transition may trigger one or more attached processes, which can run synchronously or asynchronously, either within the current transaction or in a separate one. This forms the foundation for event flow automation, where processors may create or mutate entities in response, allowing a single transition to initiate a cascade of events and function executions across the system. `CYODA_MAX_STATE_VISITS` configures the per-state visit limit within a single cascade (default 10). A separate hard-coded safety cap of 100 steps limits total cascade depth across all states, preventing runaway automatic-transition chains.
## Scheduled transitions
A third kind of transition fires on a **timer**. Give a transition a `schedule`
object and it fires on its own at a computed time, driven by a background
scheduler independently of any API call or cascade. Timers are durable, stored
by the backend (memory, SQLite, or PostgreSQL) and armed or cancelled
atomically with the entity write that triggered them.
Use it for deadlines and delays that belong to the domain: auto-close a ticket
after 24 hours of inactivity, escalate an unpaid invoice at its due date, expire
a reservation, or poll an external system on a fixed cadence.
There are two timing modes, and exactly one of them is required whenever
`schedule` is present. `schedule` is also mutually exclusive with
`manual: true` — a scheduled transition is by definition not manually fired.
### Static timing — the same delay for every entity
`delayMs` fires the transition `delayMs` after the entity enters the source
state:
```json
{
"name": "AutoClose",
"next": "Closed",
"manual": false,
"schedule": {
"delayMs": 86400000,
"timeoutMs": 600000
}
}
```
- `delayMs` (integer, required in this mode) — milliseconds between source-state
entry and the scheduled time. Must be greater than `0`.
- `timeoutMs` (integer, optional) — how late the scheduler may still pick the
timer up before giving up. It is **not** a second delay: it measures lateness
past the scheduled time, independent of `delayMs`. Absent means no limit; an
explicit `0` is strictest, dropping the timer on any lateness at all.
### Per-entity timing — a Function callout
A static delay fires every entity at the same offset. When the deadline lives on
the entity — an `expiresAt` field, a per-customer SLA, a user-chosen reminder —
use `function` instead, which asks a compute node to compute the time per
entity:
```json
{
"name": "Escalate",
"next": "Escalated",
"manual": false,
"schedule": {
"function": {
"name": "compute-escalation-time",
"resultKind": "Schedule",
"calculationNodesTags": "escalation-service",
"attachEntity": true
}
}
}
```
- `name` (required) — the registered function name.
- `resultKind` (required) — must be `"Schedule"`.
- `calculationNodesTags` (required) — comma-separated routing tags, exactly as
for a processor or criterion.
- `attachEntity` (optional, default `true`) — whether the entity payload is
attached to the request.
- `context` (optional) — a pass-through string forwarded verbatim as the
request's `parameters`.
- `responseTimeoutMs` (optional) — response timeout for this callout.
This is a **Function** callout — a third shape alongside Processor (mutates the
entity) and Criterion (returns a boolean) that returns a declared typed value
and mutates nothing. See
[handling function requests](/build/client-compute-nodes/#8-handling-function-requests) for the compute-node
side. The node replies with a `Schedule` result:
```json
{ "fireAfterMs": 3600000, "expireAfterMs": 600000 }
```
- **Fire time** (required) — exactly one of `fireAt` (absolute epoch-ms) or
`fireAfterMs` (relative to arm time). A time already in the past is not an
error; the transition is simply due immediately.
- **Expiry** (optional) — at most one of `expireAt` (absolute) or
`expireAfterMs` (relative to the *resolved fire time*, not to arm time). Both
absent means no expiry. A resolved expiry after the fire time becomes the
`timeoutMs` lateness window — the gap between the two.
The schedule function is invoked **synchronously, inside the transaction of the
entity write that arms it**. A callout failure therefore fails that write: an
unreachable, disconnected, or timed-out compute node returns a retryable `503`
(`NO_COMPUTE_MEMBER_FOR_TAG`, `DISPATCH_TIMEOUT`,
`COMPUTE_MEMBER_DISCONNECTED`), and a malformed or wrong-kind result returns
`500 SCHEDULE_FUNCTION_INVALID_RESULT`. No state change commits against a
transition that could not be scheduled — there is no silent skip.
The one case where the write still succeeds is **born expired**: if the resolved
expiry falls at or before the resolved fire time, the transition is simply never
armed, any prior scheduling for it is cancelled, and a
`SCHEDULED_TRANSITION_EXPIRE` audit event is recorded.
### How the timer behaves
Both timing modes share the same engine behaviour.
**Arming happens on every settled write.** The timer is armed when the entity
enters the source state — and re-armed on *every* subsequent write that leaves
it in that state, including a routine data update or a self-loop. Each re-arm
fully replaces the previous scheduling decision, and in function mode it makes a
fresh callout.
Because arming resets on every settled write, an entity written more often than
its scheduled interval **never reaches its fire time**. If you are modelling
"escalate 30 minutes after entry", routine touch-writes on a busy entity will
postpone that escalation indefinitely — and, in function mode, make a callout
every time. Model deadlines that must survive activity as an absolute `fireAt`
computed from a field on the entity, not as a relative delay.
**The criterion is evaluated exactly once, at fire time.** A `true` (or absent)
criterion fires the transition normally — processors run, the state advances,
`TRANSITION_MAKE` is recorded. A `false` criterion **declines** it: the entity
stays put and the timer is *not* retried. This is a deliberate one-shot, not a
poll.
**Lateness is bounded by `timeoutMs`.** If the scheduler picks up a due timer
more than `timeoutMs` past its scheduled time, the timer is dropped without
evaluating the criterion and the transition never fires. With no `timeoutMs`,
there is no upper bound — it fires whenever it is eventually picked up.
**A scheduled transition is not manually fireable.** Naming one in an explicit
transition request returns `400 TRANSITION_NOT_FOUND`, with a detail explaining
that it fires automatically. To allow early firing, give the state an ordinary
manual transition alongside the scheduled one.
**Everything is audited.** Arming, firing, expiry, and cancellation each emit a
dedicated event — `SCHEDULED_TRANSITION_ARM`, `SCHEDULED_TRANSITION_FIRE`
(alongside the ordinary `TRANSITION_MAKE`), `SCHEDULED_TRANSITION_EXPIRE`, and
`SCHEDULED_TRANSITION_CANCEL` when the entity leaves the source state before the
timer fires. A loopback that re-arms the same state emits only `ARM`.
### One-shot, or polling?
Since the criterion is evaluated once per fire, there is no built-in
retry-until-true. Three shapes cover the common cases:
- **A deadline gate** — a criterion on the scheduled transition. At the
deadline, fire if the condition holds, otherwise abandon. A `false` criterion
is a deliberate decline.
- **A recurring heartbeat** — an unconditional scheduled cycle
(`S1 →scheduled→ S2 →scheduled→ S1`), which fires every `delayMs`, forever,
for every entity in the cycle.
- **Poll until a condition holds** — an *unconditional* scheduled tick into a
state whose **ordinary** (non-scheduled) transitions carry the condition and
exit when it is met. The retry loop lives in the workflow structure, not in
the timer.
The last two are cycles, and the import-time cycle detector rejects unguarded
automated cycles by default — a delayed cycle is still a cycle. Set
`allowCycles: true` on the import request body to accept one:
```json
{
"importMode": "REPLACE",
"allowCycles": true,
"workflows": []
}
```
### Operational configuration
The scheduler runs on a coordinator elected across the cluster (by default the
member with the lowest node ID), which scans for due timers and distributes them
to peers. Seven environment variables tune it —
`CYODA_SCHEDULER_ENABLED`, `CYODA_SCHEDULER_SCAN_INTERVAL`,
`CYODA_SCHEDULER_BATCH_SIZE`, `CYODA_SCHEDULER_DISTRIBUTION`,
`CYODA_SCHEDULER_COORDINATOR`, `CYODA_SCHEDULER_REDISPATCH_BACKOFF`, and
`CYODA_SCHEDULER_EXPIRY_GRACE`. See the
[configuration reference](/reference/configuration/#vars-scheduler), or run
`cyoda help config scheduler`.
One of these matters for correctness rather than throughput:
`CYODA_SCHEDULER_EXPIRY_GRACE` (default `100ms`) is a grace band above
`timeoutMs` that separates expiry from firing, so clock skew between nodes
cannot produce a contradictory expire-and-fire. Size it to at least your maximum
expected inter-node skew.
## Criteria
Criteria define logic that determines if a transition is permitted. A criterion can be one of five types:
1. **Simple**: Evaluates a single condition on entity data
2. **Group**: Combines multiple criteria with logical operators
3. **Function**: Calls an external function for evaluation (delegated to a calculation node via gRPC)
4. **Lifecycle**: Evaluates a condition on entity lifecycle properties (state, creation date, previous transition)
5. **Array**: Evaluates a condition against an array of values
### Simple Criteria
Simple criteria evaluate a single condition directly on entity data using JSONPath expressions. They are executed directly on the processing node, without involving external compute nodes.
```json
"criterion": {
"type": "simple",
"jsonPath": "$.amount",
"operation": "GREATER_THAN",
"value": 1000
}
```
#### Simple Criteria Attributes
- `jsonPath`: JSONPath expression to extract the value from entity data
- `operation`: Comparison operator (see [Operator Types](#operator-types) below). Also accepts the alias `operatorType`.
- `value`: The value to compare against
### Group Criteria
Group criteria combine multiple conditions using logical operators.
```json
"criterion": {
"type": "group",
"operator": "AND",
"conditions": [
{
"type": "simple",
"jsonPath": "$.status",
"operation": "EQUALS",
"value": "VALIDATED"
},
{
"type": "simple",
"jsonPath": "$.amount",
"operation": "GREATER_THAN",
"value": 500
}
]
}
```
#### Group Criteria Attributes
- `operator`: Logical operator combining conditions — exactly `AND`, `OR` or `NOT`, case-sensitive
- `conditions`: Array of criteria (can be `simple`, `function`, `group`, `lifecycle`, or `array` types — supports arbitrary nesting)
`AND` and `OR` take any number of entries, including zero. An empty `AND` is
`true`, and an empty `OR` is `false`.
**`NOT` takes exactly one entry.** Zero entries, or two or more, is rejected at
the `NOT`.
`NOT` inverts its child's answer. It is not the negative form of the leaf
operator, and the two select different entities. Over a wildcard path, and over
an empty list, an explicit `null` or an absent field, the result is
non-obvious. See
[negation](/build/searching-entities/#negation-with-not) for the contract.
### Function Criteria
Function criteria delegate evaluation to an external compute node via gRPC. The function must return a boolean result.
```json
"criterion": {
"type": "function",
"function": {
"name": "FunctionName",
"config": {
"attachEntity": true,
"calculationNodesTags": "validation,data-quality",
"responseTimeoutMs": 3000,
"retryPolicy": "FIXED",
"context": "optionalContext"
},
"criterion": {
"type": "simple",
"jsonPath": "$.preCheckField",
"operation": "EQUALS",
"value": true
}
}
}
```
#### Function Attributes
- `name`: The name of the function to execute (required)
- `config`: Configuration for the function call (optional):
- `attachEntity`: Whether to pass the entity data to the function
- `calculationNodesTags`: Comma-separated list of tags for routing to specific calculation nodes
- `responseTimeoutMs`: Response timeout in milliseconds
- `retryPolicy`: Retry policy for the function (e.g., `"FIXED"`)
- `context`: Optional string parameter passed to the function for additional context or configuration. The `context` is passed "as is" with the event to the compute node. It can contain any sort of information that is relevant to the function's execution, in any format. The interpretation is up to the function itself.
- `criterion`: Optional quick-exit criterion evaluated locally before calling the (potentially expensive) external function. If this local criterion evaluates to false, the function call is skipped entirely. Useful for avoiding unnecessary network round-trips when the result can be confidently determined from entity data.
### Lifecycle Criteria
Lifecycle criteria evaluate conditions on entity lifecycle properties rather than entity data.
```json
"criterion": {
"type": "lifecycle",
"field": "state",
"operation": "EQUALS",
"value": "VALIDATED"
}
```
#### Lifecycle Criteria Attributes
- `field`: Lifecycle field to evaluate — one of `state`, `creationDate`,
`lastUpdateTime`, `transitionForLatestSave` (accepted under its older name
`previousTransition`), `transactionId`, or `id`. Any other name is rejected at
import with `400 VALIDATION_FAILED`. (The same mistake in a *search* request
body is `400 INVALID_FIELD_PATH` — criteria are validated at import, searches
at request time.)
- `operation`: Comparison operator
- `value`: The value to compare against
`creationDate` and `lastUpdateTime` are temporal and compare chronologically at
millisecond resolution. They accept a coarser operand that upscales — `"2024"`
or `"2024-09"` are valid against a full timestamp — and reject only an operand
that parses into no temporal form at all.
### Array Criteria
Array criteria match values by **position** inside a JSON array.
```json
"criterion": {
"type": "array",
"jsonPath": "$.laureates[*]",
"values": ["John", null, "Hopfield"]
}
```
#### Array Criteria Attributes
- `jsonPath`: JSONPath to the array's **elements**. It must carry a trailing
`[*]` — a bare path addresses the array itself, not its elements, and is
rejected with `400 INVALID_FIELD_PATH`.
- `values`: Positional values, one per array index in order. Each non-null
entry is a test of the element at that index, and the clause is read as an
`AND` of those tests: the example fires when element 0 is `"John"` **and**
element 2 is `"Hopfield"`. A `null` entry tests nothing at that index, so a
`values` array of all `null` matches every entity.
### Operator Types
The following comparison operators are available for simple, lifecycle, and array criteria:
**Basic Comparison:** `EQUALS`, `NOT_EQUAL`, `IS_NULL`, `NOT_NULL`, `GREATER_THAN`, `LESS_THAN`, `GREATER_OR_EQUAL`, `LESS_OR_EQUAL`, `BETWEEN`, `BETWEEN_INCLUSIVE`
**String Operations (Case-Sensitive):** `CONTAINS`, `NOT_CONTAINS`, `STARTS_WITH`, `NOT_STARTS_WITH`, `ENDS_WITH`, `NOT_ENDS_WITH`, `MATCHES_PATTERN`, `LIKE`
**Case-Insensitive String Operations:** `IEQUALS`, `INOT_EQUAL`, `ICONTAINS`, `INOT_CONTAINS`, `ISTARTS_WITH`, `INOT_STARTS_WITH`, `IENDS_WITH`, `INOT_ENDS_WITH`
`IS_CHANGED` and `IS_UNCHANGED` are change-generation operators rather than
search predicates, and cyoda-go does not implement them. For the full
evaluation model — type-directed comparison, null handling, the `LIKE` grammar
— see [predicate semantics](/build/searching-entities/#predicate-semantics);
criteria and search share one kernel, so the rules are identical.
### Criterion validation
Criteria and search conditions follow the same
[path grammar](/build/searching-entities/#how-a-field-path-is-written) and the
same operator catalogue. The engine enforces them in two places.
**At import**, the engine checks each criterion's `jsonPath`, its operator
names, and its `LIKE` and `MATCHES_PATTERN` operands. A failure rejects the
whole import with `400 VALIDATION_FAILED`. A stored workflow continues to
evaluate, and it fails at its next import.
**At evaluation**, a criterion that the engine cannot answer fails the write
that it guards:
- A criterion that names a field that the model does not declare stops the save
with `400 WORKFLOW_FAILED`, and the engine rolls the save back.
- A criterion that carries an operator that no evaluator supports fails the
save.
- A model-store failure during evaluation fails the save, even when another
condition in the same group also fails structurally.
## Processors
Processors implement custom logic to run during transitions. All processors are
**externalized** — delegated to a calculation node over gRPC.
To fire a transition on a delay rather than on an API call or a cascade, you do
not attach a processor: you put a [`schedule`](#scheduled-transitions) on the
transition itself.
The engine validates data that a processor returns in the same way as a client
write. The data must be storable, and it must satisfy the model's schema.
A processor that writes a field that the model does not declare needs the
model's [`changeLevel`](/build/modeling-entities/#the-change-level-ladder) to
permit the change. If the level does not permit it, the transition fails with
`WORKFLOW_FAILED` and rolls back. The engine stores neither the entity nor a
schema change.
### Externalized Processors
Externalized processors delegate execution to a calculation node via gRPC. This is the most common processor type.
```json
{
"type": "externalized",
"name": "ProcessorName",
"executionMode": "SYNC",
"config": {
"attachEntity": true,
"calculationNodesTags": "tag1,tag2",
"responseTimeoutMs": 5000,
"retryPolicy": "FIXED",
"context": "optionalContext"
}
}
```
#### Externalized Processor Attributes
- `type`: `"externalized"` (discriminator)
- `name`: Name of the processor (required)
- `executionMode`: Execution mode (see below). Default: `ASYNC_NEW_TX`.
- `config`: Configuration for the processor call:
- `attachEntity`: Whether to attach entity data to the processor call.
**Defaults to `true`** as of cyoda-go v0.8.3 — a processor that omits the
field is imported with the payload attached, matching `schedule.function` and
the criterion `function` callout. Set it to `false` explicitly to opt out.
- `calculationNodesTags`: Comma-separated list of tags for routing to specific calculation nodes
- `responseTimeoutMs`: Response timeout in milliseconds
- `retryPolicy`: Retry policy for the processor
- `context`: Additional context passed to the processor
- `asyncResult`: Whether to await the result asynchronously, outside of the transaction
- `crossoverToAsyncMs`: Crossover delay in milliseconds to switch to asynchronous processing (effective only when `asyncResult` is true)
#### Execution Modes
- `SYNC`: Inline execution within the transaction. Runs immediately and blocks the current processing thread on the same node.
- `ASYNC_SAME_TX`: Deferred within the current transaction. Commits or rolls back atomically with the triggering transition.
- `ASYNC_NEW_TX`: Deferred execution in a separate, independent transaction. Default mode.
Processors should be idempotent; failed ASYNC_NEW_TX processors may be retried.
Synchronous executions run immediately and block the current processing thread on the same node, making them local and non-distributed. In contrast, asynchronous executions are scheduled for deferred processing and can be handled by any node in the cluster, enabling horizontal scalability and workload distribution, albeit with possibly somewhat higher latency.
### Calculation Nodes Tags
As described in the [Architecture](/architecture/cyoda-cloud-architecture/) section, the execution of processors and criteria is delegated to client compute nodes, i.e. your own infrastructure running your business logic. These nodes can be organized into groups and tagged based on their roles or capabilities. By optionally setting the `calculationNodesTags` property in a processor or criterion definition, you can direct execution to specific groups, giving you fine-grained control over workload distribution across your compute environment.
## Example: Payment Request Workflow
This workflow models the lifecycle of a payment request, covering validation, matching, approval, and notification handling.
It starts in the INVALID state, where the request is either amended or validated.
If validation succeeds and a matching order exists, the request advances automatically to the SUBMITTED state.
If not, it moves to PENDING, where it awaits a matching order or may be retried manually.
Requests in SUBMITTED require an approval decision, leading either to APPROVED, which triggers
asynchronous processing like payment message creation and ACK notifications, or to DECLINED,
which emits a rejection (NACK) notification. Manual amend and retry transitions at key
stages allow users or systems to correct or re-evaluate the request.
The following section walks through the configuration step by step.

### Step 1: Workflow Metadata
```json
{
"version": "1.4",
"name": "Payment Request Workflow",
"desc": "Payment request processing workflow with validation, approval, and notification states",
"initialState": "INVALID",
"active": true
}
```
### Step 2: Define States and Transitions
Start by defining the overall structure of states and transitions.
```json
{
"version": "1.4",
"name": "Payment Request Workflow",
"desc": "Payment request processing workflow with validation, approval, and notification states",
"initialState": "INVALID",
"active": true,
"states": {
"INVALID": {
"transitions": [
{
"name": "VALIDATE",
"next": "PENDING",
"manual": false,
"disabled": false
},
{
"name": "AMEND",
"next": "INVALID",
"manual": true,
"disabled": false
},
{
"name": "CANCEL",
"next": "CANCELED",
"manual": true,
"disabled": false
}
]
},
"PENDING": {
"transitions": [
{
"name": "MATCH",
"next": "SUBMITTED",
"manual": false,
"disabled": false
},
{
"name": "RETRY",
"next": "PENDING",
"manual": true,
"disabled": false
},
{
"name": "CANCEL",
"next": "CANCELED",
"manual": true,
"disabled": false
}
]
},
"SUBMITTED": {
"transitions": [
{
"name": "APPROVE",
"next": "APPROVED",
"manual": true,
"disabled": false
},
{
"name": "DENY",
"next": "DECLINED",
"manual": true,
"disabled": false
}
]
},
"APPROVED": {
"transitions": []
},
"DECLINED": {
"transitions": []
},
"CANCELED": {
"transitions": []
}
}
}
```
### Step 3: Add Criteria
We add criteria to the `VALIDATE` and `MATCH` transitions:
```json
{
"version": "1.4",
"name": "Payment Request Workflow",
"desc": "Payment request processing workflow with validation, approval, and notification states",
"initialState": "INVALID",
"active": true,
"states": {
"INVALID": {
"transitions": [
{
"name": "VALIDATE",
"next": "PENDING",
"manual": false,
"disabled": false,
"criterion": {
"type": "function",
"function": {
"name": "IsValid",
"config": {
"attachEntity": true
}
}
}
},
{
"name": "AMEND",
"next": "INVALID",
"manual": true,
"disabled": false
},
{
"name": "CANCEL",
"next": "CANCELED",
"manual": true,
"disabled": false
}
]
},
"PENDING": {
"transitions": [
{
"name": "MATCH",
"next": "SUBMITTED",
"manual": false,
"disabled": false,
"criterion": {
"type": "function",
"function": {
"name": "HasOrder",
"config": {
"attachEntity": true
}
}
}
},
{
"name": "RETRY",
"next": "PENDING",
"manual": true,
"disabled": false
},
{
"name": "CANCEL",
"next": "CANCELED",
"manual": true,
"disabled": false
}
]
},
"SUBMITTED": {
"transitions": [
{
"name": "APPROVE",
"next": "APPROVED",
"manual": true,
"disabled": false
},
{
"name": "DENY",
"next": "DECLINED",
"manual": true,
"disabled": false
}
]
},
"APPROVED": {
"transitions": []
},
"DECLINED": {
"transitions": []
},
"CANCELED": {
"transitions": []
}
}
}
```
### Step 4: Add Processors
We add two processors to the `APPROVE` transition in the `SUBMITTED` state, respectively, to finish the job.
```json
{
"version": "1.4",
"name": "Payment Request Workflow",
"desc": "Payment request processing workflow with validation, approval, and notification states",
"initialState": "INVALID",
"active": true,
"states": {
"INVALID": {
"transitions": [
{
"name": "VALIDATE",
"next": "PENDING",
"manual": false,
"disabled": false,
"criterion": {
"type": "function",
"function": {
"name": "IsValid",
"config": {
"attachEntity": true
}
}
}
},
{
"name": "AMEND",
"next": "INVALID",
"manual": true,
"disabled": false
},
{
"name": "CANCEL",
"next": "CANCELED",
"manual": true,
"disabled": false
}
]
},
"PENDING": {
"transitions": [
{
"name": "MATCH",
"next": "SUBMITTED",
"manual": false,
"disabled": false,
"criterion": {
"type": "function",
"function": {
"name": "HasOrder",
"config": {
"attachEntity": true
}
}
}
},
{
"name": "RETRY",
"next": "PENDING",
"manual": true,
"disabled": false
},
{
"name": "CANCEL",
"next": "CANCELED",
"manual": true,
"disabled": false
}
]
},
"SUBMITTED": {
"transitions": [
{
"name": "APPROVE",
"next": "APPROVED",
"manual": true,
"disabled": false,
"processors": [
{
"type": "externalized",
"name": "Create Payment Message",
"executionMode": "ASYNC_NEW_TX",
"config": { "attachEntity": true }
},
{
"type": "externalized",
"name": "Send ACK Notification",
"executionMode": "ASYNC_NEW_TX",
"config": { "attachEntity": false }
}
]
},
{
"name": "DENY",
"next": "DECLINED",
"manual": true,
"disabled": false,
"processors": [
{
"type": "externalized",
"name": "Send NACK Notification",
"executionMode": "ASYNC_NEW_TX",
"config": { "attachEntity": false }
}
]
}
]
},
"APPROVED": {
"transitions": []
},
"DECLINED": {
"transitions": []
},
"CANCELED": {
"transitions": []
}
}
}
```
## Best Practices
- Use domain-specific state names
- Match transition granularity to business needs
- Define recovery and cancellation paths
- Prefer asynchronous processing for external dependencies
- Use self-transitions for triggering workflow automation on exit from the current state
## Platform Integration
Cyoda workflows integrate directly with:
- **Entity Models**: Determine which workflows apply to which data types
- **Execution Engine**: Drives state and transition logic
- **External Functions**: Implement validation and custom behavior
- **Event System**: Triggers automated transitions on event reception
---
## build/working-with-entities.md
# Working with entities
Create, read, update, and search entities via the cyoda-go API — worked examples.
This page shows the patterns for interacting with entities through the
platform API. Examples assume a local cyoda-go instance running on the default
port with SQLite persistence; the same requests work against Cyoda Cloud with
the cloud endpoint and an issued token.
The complete endpoint catalogue — parameters, response shapes, error codes —
lives in the [API reference](/reference/api/). Keep that open as you work.
## The shape of the API
Cyoda speaks REST for CRUD, search, and workflow invocation, gRPC for external
processors, and Trino SQL for analytics. This page covers REST; see
[Build → client compute nodes](/build/client-compute-nodes/) for gRPC and the
[APIs and surfaces](/concepts/apis-and-surfaces/) overview for the decision
framework.
Every request is authenticated with a bearer token. Every response includes
the entity's current revision, state, and timestamps.
For durable inbound payloads that are not yet entities — a staging buffer at the platform edge — see [edge messages](/build/edge-messages/).
## Create
Post an entity to its model. The first time you post, Cyoda discovers the
schema from what you send:
```bash
curl -X POST http://localhost:8080/api/entity/JSON/orders/1 \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"orderId": "ORD-42",
"customerId": "CUST-7",
"amount": 120.00,
"currency": "EUR",
"lines": [
{ "sku": "AX-1", "qty": 2, "price": 60.00 }
]
}'
```
The path is `/api/entity/{format}/{entityName}/{modelVersion}` — here `JSON`,
`orders`, and version `1`. The response carries an array whose first element
contains `entityIds[0]`, the **system-assigned UUID** of the new entity, plus
its current state and revision number. Capture the UUID — downstream reads,
updates, and transitions address the entity by that UUID, not by the business
key `orderId`.
## Read
Fetch the current revision by id. The `{entityId}` in these URLs is the UUID
returned in `entityIds[0]` from the create response, not a business key like
`orderId`:
```bash
curl http://localhost:8080/api/entity/${ENTITY_ID} \
-H "Authorization: Bearer $TOKEN"
```
List every entity in a model with `GET /api/entity/{entityName}/{modelVersion}`:
```
GET /api/entity/orders/1
```
For filtered reads — predicates, pagination, result caps, historical reads —
see [searching entities](/build/searching-entities/). The list endpoint does
not accept ad-hoc field filters; those belong to search.
## Update
Direct updates use `PUT /api/entity/{format}/{entityId}` (loopback update — stores a new revision without a named transition) or `PUT /api/entity/{format}/{entityId}/{transition}` (update with a named transition). `PUT` has **wholesale-replace** semantics: any field you omit from the body is destroyed. To change only some fields, use [`PATCH`](#partial-update-patch) instead.
**Mutations that move the entity between lifecycle states should go through a
named transition**, not a bare loopback update. Invoking the `submit` transition
records it in the audit trail and runs any attached processors. The transition
carries the new entity JSON in the request body (the platform stores the updated
entity and records the named transition in one call):
```bash
curl -X PUT http://localhost:8080/api/entity/JSON/${ENTITY_ID}/submit \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{ "orderId": "ORD-42", "status": "submitted" }'
```
See [Build → workflows and processors](/build/workflows-and-processors/) for
how to declare transitions.
### Partial update (PATCH)
When you want to change only the fields that moved — without resending (and risking clobbering) the rest of the entity — use `PATCH`:
```http
PATCH /api/entity/{format}/{entityId}
PATCH /api/entity/{format}/{entityId}/{transition}
```
The body is a sparse JSON object applied to the **stored** entity with RFC 7386 (`application/merge-patch+json`) semantics: a non-null key overwrites, an explicit `null` deletes that key, and an omitted key is left untouched.
```bash
curl -X PATCH http://localhost:8080/api/entity/JSON/${ENTITY_ID} \
-H 'Content-Type: application/merge-patch+json' \
-H "If-Match: ${LAST_TRANSACTION_ID}" \
-H "Authorization: Bearer $TOKEN" \
-d '{ "amount": 130.00, "note": null }'
```
Unlike `PUT`, **`If-Match` is required** — the merge is applied relative to the base you read, so patching a stale base risks a lost update. The token is the `meta.transactionId` from your last `GET`; a missing header returns `428 PRECONDITION_REQUIRED` and a stale one returns `412`. The merged result is validated strictly against the model schema — a `PATCH` never extends the model, even in an extend-permitting mode. The request is JSON-only (XML ⇒ `415`); RFC 6902 JSON Patch is recognised but returns `501` for now.
## Bounding a write
Every entity write accepts `transactionTimeoutMillis`. It bounds the time that
the server spends before the **first commit**:
```
POST /api/entity/JSON/orders/1?transactionTimeoutMillis=10000
```
When the time elapses, the server rolls the transaction back and fails the
request with `408 TRANSACTION_TIMEOUT`. It commits nothing. If you omit the
parameter, the write has no server-side timeout.
A chunked write is an array body that `transactionWindow` splits into chunks.
The parameter covers the first chunk only. If the time elapses after that, the
server reports a `TRANSACTION_TIMEOUT` element in the per-chunk response
instead of an HTTP `408`.
The server rejects the parameter with `400` on a request that
[joins an open transaction](/build/client-compute-nodes/#1031-transaction-joined-callbacks).
The same rule applies to `transactionSize` on a delete and to `timeoutMillis`
on a search.
`503 STORAGE_UNAVAILABLE` reports a problem in the storage layer, and it is
**retryable**. It covers three conditions: the connection pool could not supply
a connection, the database aborted the transaction at its idle ceiling, and the
connection to the database went away.
## When a write is visible
A `2xx` response to a write means that the write is **visible to every later
read on every node**. A caller can write and then read its own data back. Every
storage engine delivers this contract — see
[storage engines](/run/storage-engines/#one-application-contract).
## What the platform will not store
A payload can be valid JSON and still be unstorable. The server rejects five
forms at the boundary with `400`, on every storage backend and over both REST
and gRPC:
- **A NUL character** (U+0000) at any position in the payload.
- **Unpaired UTF-16 surrogates and invalid UTF-8.** The server reads the raw
request bytes for this check. A JSON decoder replaces both forms with U+FFFD,
which would store a character that you did not send.
- **A name that occurs more than once in the same object.** Different parts of
the system read a different occurrence, so the payload has no single meaning.
- **Content after the JSON value**, such as `{"x":1}}}`.
- **A number outside the `numeric` range of PostgreSQL.**
## Delete
Delete a single entity by id, or delete a matched subset of a model with a condition:
```bash
# Delete a single entity by id
curl -X DELETE http://localhost:8080/api/entity/${ENTITY_ID} \
-H "Authorization: Bearer $TOKEN"
```
`DELETE /api/entity/{entityId}` removes exactly the entity with that UUID and
returns its id, model key, and the transaction id of the delete.
```bash
# Delete entities matching a condition (empty body ⇒ every entity in the model)
curl -X DELETE http://localhost:8080/api/entity/orders/1?verbose=true \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer $TOKEN" \
-d '{
"type": "simple",
"jsonPath": "$.status",
"operation": "EQUALS",
"value": "cancelled"
}'
```
The `DELETE /api/entity/{entityName}/{modelVersion}` endpoint honours an `AbstractConditionDto` request body and removes only the matching entities; an **empty body still means all**. `verbose=true` returns the deleted ids, and the response reports matched-vs-removed counts separately. A malformed condition returns `400 INVALID_CONDITION`.
Supplying the condition matters: earlier releases ignored it and wiped the entire model. Always send the condition you intend (or omit the body deliberately when you really do mean "all").
Both forms accept `pointInTime`, so you can scope a delete to the data as it
was at a given instant.
### Deleting in batches
By default, the server removes the whole selection in one transaction. Add
`transactionSize` to remove it in independent, version-guarded batches:
```
DELETE /api/entity/orders/1?transactionSize=500
```
A batch that is already committed stays durable if a later batch fails. The
server records two conditions per id in `deleteResult.idToError`, and does not
retry either:
- A version mismatch. The entity changed after the server selected it.
- A commit failure for the batch.
Without `pointInTime`, the server selects the matching entities again before
each batch. If entities are created at least as fast as the server removes
them, the selection never becomes empty. In that case the server stops at the
batch cap and fails the request with a retryable
**`409 DELETE_NOT_CONVERGED`**. The batches that are already committed stay
deleted. To make a batched delete terminate, supply `pointInTime`.
The server rejects `transactionSize` with `400` on a request that joins an open
transaction.
## Search
Cyoda supports two query modes:
- **Direct** (synchronous, bounded-or-fail) — API term `direct`.
Streams results right away as NDJSON. Good for UI lookups and short
operations. `limit` caps the *matched set* (default 1000, max 10000) and a
query matching more than that returns `400 SEARCH_RESULT_LIMIT` rather than a
truncated page — so `direct` suits queries you know produce a bounded, small
result set.
- **Async** (background, unbounded, paged) — API term `async`.
Queued as a job, returns a handle you can poll. Result size is
unbounded; results are paged. Good for large result sets, periodic
reports, and exports. On the Cassandra-backed tier (Cyoda Cloud, or
a licensed Enterprise install), `async` search runs distributed
across the cluster and scales horizontally: query throughput for a
fixed shape grows roughly linearly with the number of nodes.
Both accept the same filter grammar over entity fields, metadata, and
workflow state. Pick `direct` by default; switch to `async` when a
query would exceed the `direct` limit, would time out, or would hold
resources you need elsewhere. Ordered top-N over a large model belongs on
`async` too. For predicates, pagination, and worked
examples, see [searching entities](/build/searching-entities/).
## Temporal queries
Every entity's history is queryable. Add a `pointInTime` parameter to any read
or search request to retrieve the world as of that timestamp:
```
GET /api/entity/{entityId}?pointInTime=2026-03-01T00:00:00Z
```
Point-in-time reads apply a single canonical rule across every storage engine and read path: **inclusive of the requested instant** (`<=`), compared at native precision with no millisecond round-up. The model-scoped list read (`GET /api/entity/{entityName}/{modelVersion}`) also honours `pointInTime` and stamps `meta.pointInTime` on the result.
This is the primary way to answer regulatory and audit questions: *what did
this customer's balance look like at quarter close?* For the same
parameter applied to searches, see
[searching entities → historical reads](/build/searching-entities/#historical-reads-with-pointintime);
for analytical reads expressed as SQL, see
[analytics with SQL](/build/analytics-with-sql/).
## Change history
Where `pointInTime` answers *what did this look like then*, the change-history
endpoint answers *who changed it, and when*:
```
GET /api/entity/{entityId}/changes
```
Each entry carries `changeType` (`CREATE`, `UPDATE`, or `DELETE`),
`timeOfChange`, and a `user` — the principal the change is **attributed** to,
always present. `transactionId` and `fieldsChangedCount` appear when the
underlying entity version is available.
As of cyoda-go v0.8.3 an entry also carries who actually performed it:
- `attributedKind` — the kind of the attributed `user`: `user`, `service`, or
`system`.
- `executedBy` — `{id, kind}` for the caller that actually executed the change,
independent of attribution.
The two differ whenever an action happened *because of* someone but not *as*
them. A processor cascading writes off a user's transition is attributed to
that user while executing as a service; a scheduled transition firing hours
later is attributed to whoever armed it. Reading `user` alone cannot tell a
service-executed cascade from a direct user action — read both when that
distinction matters. See
[attribution is not authorization](/concepts/authentication-and-identity/#attribution-is-not-authorization)
for how the platform captures it.
Both fields are **absent** on rows written before v0.8.3 rather than present
and `null`, so treat missing as "not recorded" rather than as a value.
## From a compute node
When your code is reacting to a transition — running a processor or
evaluating a criterion — talk to the platform over **gRPC**, not REST. The
gRPC path preserves the audit association between the transition and the
compute call, brokers identity, and supports streaming. See
[Build → client compute nodes](/build/client-compute-nodes/) for the
implementation pattern.
---
## concepts/apis-and-surfaces.md
# APIs and surfaces
REST, gRPC, and Trino SQL — when and why to use each.
Cyoda exposes three distinct API surfaces. Picking the right one for the job
matters; the surfaces are not equivalent, and each carries different guarantees.
## Three surfaces
- **REST** — the default surface for user-facing clients and administrative
operations. CRUD over entities, search, workflow invocations, schema
management, dashboards.
- **gRPC** — the surface for compute. External processors and criteria
services connect to the platform over gRPC, receive work, and return
results. Supports bidirectional streaming.
- **Trino SQL** — the surface for analytics. Cross-entity queries, reporting,
JDBC connections, BI tools. Queries run against a Trino catalogue that
projects entities into virtual SQL tables.
## Which surface, when?
- Building a UI, an admin tool, or a sync integration? **REST.**
- Writing a processor or criterion that runs against transitions? **gRPC.**
- Running analytics, reports, or ad-hoc queries across many entities?
**Trino SQL.**
All three surfaces are backed by the same entity store. A transition recorded
via REST is visible to gRPC compute nodes and queryable through Trino, with
the same audit trail behind it.
## REST: humans and services that speak to the platform
Use REST when the call represents *a user or service interacting with the
platform as a whole*: creating an order, searching for customers, reading
audit history, managing a workflow definition. This is the surface your
front-end, your admin tooling, and most external integrations will use.
REST is synchronous, authenticated with OAuth 2.0 bearer tokens, and
versioned. The full endpoint catalogue lives in the
[API reference](/reference/api/).
## gRPC: external processors that speak for the platform
Use gRPC when your code is *a compute node acting on behalf of a workflow
transition*. Processors and criteria attached to a transition call out to
external services over gRPC; those services stream work units back to the
platform.
**Prefer gRPC for compute** over implementing processors as REST callbacks.
Three reasons:
1. **Audit hygiene.** Every gRPC call is recorded against the transition that
invoked it, inside the platform's audit trail. REST callouts cannot
reconstruct that association reliably.
2. **Authorization is simpler.** The platform brokers the identity and scopes
passed to the compute node; you don't have to manage credentials between
the platform and your processor independently.
3. **Bidirectional streaming.** High-throughput ingest and transformation
workloads benefit from streaming both ways; REST cannot.
For how to implement a compute node, see
[Build → client compute nodes](/build/client-compute-nodes/).
## Trino SQL: cross-entity analytics
:::caution[Upcoming]
Trino SQL is on the roadmap and not yet available in cyoda-go at this release. The section below documents the planned surface; names and shapes may change before release.
:::
Use Trino when the question is *analytical* — joins across entity types,
aggregates, reporting, time-series. Every entity model is projected into a
set of virtual SQL tables; nested arrays and objects expand into separate
tables so relational queries remain natural.
Typical uses:
- Ad-hoc analysis against live data in a notebook or BI tool.
- Scheduled reports that aggregate entities across a tenant.
- Historical queries using the `point_time` column for as-of reads.
The table generation rules, data-type mappings, JDBC connection patterns,
and handling of polymorphic fields are in the
[Trino SQL reference](/reference/trino/). For the Build-side quickstart —
connection recipe, first query, performance notes — see
[Analytics with SQL](/build/analytics-with-sql/).
---
## concepts/authentication-and-identity.md
# Authentication and identity
OAuth 2.0 tokens, machine-to-machine credentials, on-behalf-of exchange, and external key trust — conceptually.
Cyoda is an OAuth 2.0 authorization server. All traffic to the platform — REST,
gRPC, Trino — is authenticated with bearer tokens the platform issues. This
page explains the identity concepts; the mechanics of configuring an IdP,
rotating keys, and provisioning credentials live under Run.
## The platform issues tokens
Every request carries a JWT bearer token. Cyoda both **issues** tokens (as an
OAuth 2.0 authorization server) and **validates** them on every API call. The
token encodes the subject, the scopes, and the tenant the request belongs to;
authorization is evaluated from the token, not from transport-level
credentials.
Clients obtain a token through an OAuth 2.0 flow appropriate to their role:
end-user flows for people, M2M flows for services, on-behalf-of exchange for
downstream calls.
## Machine-to-machine credentials
Services authenticate to Cyoda using **client credentials** (`client_id` and
`client_secret`). The platform issues tokens to those credentials and enforces
the scopes associated with the service account. Use M2M credentials for any
automated integration: ingest pipelines, compute nodes, back-office workers.
Rotate credentials like any other secret; the lifetime and rotation cadence
are enforced per environment.
## On-behalf-of exchange
When one service calls another on a user's behalf — a web app calling an API
that calls a processor, for example — Cyoda supports **token exchange**. The
calling service presents its own token plus the user's token and receives a
new token scoped to the downstream call. This preserves the user identity
through the chain without passing the original bearer token around. In
practice, the calling service includes the user's JWT as the `subject_token`
in a token-exchange request; the issued token carries both identities for
downstream authorization.
The result: the audit trail records who the original user was at every hop,
and each service still only sees a token scoped to what it is allowed to do.
## Principal kinds
Every principal carries an **explicit kind**: `user`, `service`, or `system`.
The kind is recorded when the principal is established, not inferred later from
the roles it happens to carry. Compute nodes see it as the `authtype` attribute
on dispatched CloudEvents, and the platform **fails a dispatch closed** rather
than sending an unset or unrecognized kind downstream.
- `user` — a person, authenticated through an end-user flow.
- `service` — a machine-to-machine technical account.
- `system` — an internal platform trigger with no user context.
## Attribution is not authorization
Some actions happen because of a user, but not *as* that user. A processor
writing other entities in reaction to someone's transition, or a scheduled
transition firing hours after the write that armed it, both run without a
live user request behind them.
Cyoda keeps the two concerns separate:
- **Execution** uses system or service authority. Nobody is impersonated and no
user's permissions are borrowed. What the follow-on action is *allowed* to do
does not depend on who caused it.
- **Attribution** records the principal captured server-side when the follow-on
was created — the transaction's origin for a cascade, propagated unchanged
through every joined write including a cross-node proxied join; the identity
that armed the timer for a scheduled fire.
Origin is **platform-set only**. No request field and no worker input can
declare it, so attribution cannot be spoofed by a caller or a compute node.
This matters when you read history. A change record carries both the attributed
principal and the identity that actually executed it, so a service-executed
cascade is never indistinguishable from a direct user action — see
[the change history](/build/working-with-entities/#change-history). Before
cyoda-go v0.8.3 the follow-on was recorded against whatever ran it: a cascade
appeared as the compute service account, and a scheduled fire as a fabricated
`"scheduler"` user, losing the human who set it off.
## External key trust and OIDC federation
Cyoda can be configured to **trust tokens issued by external identity
providers** — your corporate Okta, Auth0, Keycloak, Entra, or any
spec-compliant OpenID Connect (OIDC) issuer. The platform validates tokens
signed with keys it recognises, maps the external subject and roles onto an
internal identity, and applies the local authorization rules. Users sign in
with their organisation's single sign-on and receive entitlements within Cyoda.
Trust is established **per tenant**. cyoda-go keeps a registry of OIDC
providers: each registration pins an issuer — and optionally the audiences it
will accept and the claim that carries roles — and the platform validates an
incoming token against the local issuer first, then against the registered
providers in turn. Where several tenants share one physical IdP, tokens are
disambiguated by audience and ambiguous tokens are rejected rather than
guessed, so one tenant can never borrow another's trust.
Provider metadata — the JWKS used to verify signatures — is fetched from each
issuer's OIDC discovery document, refreshed across the cluster, and guarded
against server-side request forgery. A reload preserves existing key sources and
re-warms every provider on every node; a warm-up that fails because the identity
provider is unreachable retries every 30 seconds.
## Where this is configured
- **Self-hosted (cyoda-go).** Identity is managed through cyoda-go's IAM
admin API and configuration: bootstrap credentials, JWT signing keys,
machine-to-machine clients, and OIDC provider trust. See
[Reference → Identity and IAM](/reference/identity-and-iam/) for the
endpoints and the configuration that governs them, or run `cyoda help auth`
against your binary.
- **Cyoda Cloud.** Identity is surfaced as a managed service:
[Cyoda Cloud → identity and entitlements](/cyoda-cloud/identity-and-entitlements/).
## What your application does
Applications do not implement OAuth 2.0 flows from scratch; they fetch a token
using their client credentials (or accept one from a user session) and attach
it to every Cyoda call. See [Build → working with entities](/build/working-with-entities/)
for the client patterns.
---
## concepts/design-principles.md
# Design principles
The mental model behind Cyoda: entities as durable state machines, transitions as the unit of change, and history as a first-class query surface.
Cyoda's shape follows from a few connected ideas. Once those click, the rest of the
platform — the APIs, the workflows, the audit trail, the deployment tiers — is just
what falls out of them. This page is the high-level picture; the pages that follow
drill into each idea in depth.
## Everything is an entity
In Cyoda, every piece of persisted data is an **entity**: a JSON document that
belongs to a typed model and carries a lifecycle state. Entities are not rows to be
updated in place and they are not messages passing through a pipe. They are the
objects your system reasons about — customers, orders, documents, trades — with
identity, state, and history.
Models are discovered from the data, not declared up front, and widen as new
shapes arrive. Once a model is good enough to rely on, it can be **locked** so new
data must conform.
## An entity is a durable state machine
Each entity type has a **workflow** — a set of named states, the legal transitions
between them, and the criteria and processors that run along each transition. The
entity lives inside that machine.
Cyoda's state machines are close in spirit to BPM flows but looser: transitions can
be **automatic** (fire on entering a state) or **manual** (invoked by an actor), and
a workflow need not be linear or terminate. Cycles and branches are first-class.
See [Entities and lifecycle](/concepts/entities-and-lifecycle/) for the full model,
including the state-machine diagram.
## Transitions are the unit of change
Nothing in Cyoda is overwritten. Every transition produces a new, durable revision
of the entity, validated against the model at the moment it happened. Processors run
under a defined event contract; criteria gate whether the transition is allowed to
fire at all.
Because revisions accumulate instead of replacing each other, **history is not an
add-on audit layer — it is the storage model**. Point-in-time reads, transition
logs, and schema-lineage queries are all native operations.
## Events drive the machine
Events — "file uploaded", "payment received", "a manual transition issued by an operator" — trigger transitions.
Transitions invoke processors. Processors can be synchronous or asynchronous, and
can run inside or alongside the transition's transaction. The platform keeps the
whole chain observable and replayable.
## Same semantics, every tier
The same entity, workflow, and transition semantics run on every deployment tier
Cyoda supports: in-memory for tests, SQLite on a desktop, Docker for a single
machine, Kubernetes via Helm, or Cyoda Cloud for a managed fleet. Applications
move between tiers without rewriting their domain model.
## TL;DR
- All persisted data is an **entity** with a typed model and a lifecycle state.
- Each entity follows a **workflow** — a state machine of states, transitions,
criteria, and processors.
- **Transitions** are the atomic unit of change; each one produces a new revision.
- Transitions can be **automatic** (fire on state entry) or **manual** (invoked).
- Criteria **guard** transitions; processors **execute** along them, sync or async.
- **History** is the storage model, not an add-on; every revision is addressable.
- **Events** drive transitions; the whole chain is observable and replayable.
- The same semantics apply on every tier, from in-memory tests to the cloud.
## Where to go next
- [Entities and lifecycle](/concepts/entities-and-lifecycle/) — schemas, states,
history, and the state-machine shape of an entity.
- Workflows and events — how transitions, processors, and criteria are wired
together. *(Coming as the Concepts section fills out.)*
- History and audit — query patterns for time travel and schema lineage.
*(Coming.)*
- APIs and surfaces, tiers and deployment options, authentication and identity —
each has its own page in this section.
For the long-form argument behind these ideas, see
[Entity Workflows for Event-Driven Architectures](https://medium.com/@paul_42036/entity-workflows-for-event-driven-architectures-4d491cf898a5)
and [What's an Entity Database?](https://medium.com/@paul_42036/whats-an-entity-database-11f8538b631a).
---
## concepts/digital-twins-and-growth-path.md
# Digital twins and the growth path
Why the same Cyoda app runs on any storage tier, and when to pick each tier.
A Cyoda application is **tier-agnostic**. The entity model, the workflows, the
REST and gRPC surfaces, and the query semantics are the same on every
deployment tier. What changes as you move between tiers is non-functional:
durability, consistency guarantees, scale, and operational cost. We call this
the **digital twin** property — the same logic, running at a different point
on the cost/scale curve.
## The growth path
## When to use each tier
- **In-Memory** — a single-process, zero-dependency runtime. Data is lost on
restart. Use it for functional tests, fast AI iteration loops, and
**digital-twin scenario runs** where you want to drive the same app logic
at volumes and rates that would be prohibitively expensive against a
durable backend.
- **SQLite** — durable, single-file, zero-ops. Use it for edge and IoT
deployments, small-team self-hosting, and local development where you want
data to survive restarts but do not want to operate a separate database.
- **PostgreSQL** — durable storage with `SERIALIZABLE` isolation for
production workloads. Run 3–10 stateless cyoda-go nodes behind a load
balancer for active-active HA, with PostgreSQL as the only external
dependency. This is the recommended production path for teams self-hosting.
- **Cassandra (via Cyoda Cloud)** — a distributed, horizontally scalable
backend available today as a managed service. Use Cyoda Cloud when you need
enterprise-grade identity, multi-tenancy, and provisioning, and do not
want to run the infrastructure yourself.
## Choosing
Most teams make this choice along four axes:
- **Durability** — can the data disappear on a restart? If yes, In-Memory is
fine. Otherwise you need SQLite or up.
- **Write volume and HA** — a single process can go a long way on SQLite, but
active-active HA with concurrent write safety wants PostgreSQL or cloud.
- **Ops appetite** — PostgreSQL is one dependency; SQLite is zero; Cyoda Cloud
is "someone else's problem".
- **Scale ceiling** — in-process stores have limits Cassandra does not.
You do not have to pick forever. The whole point of the growth path is that
the application does not change when you move. A test suite can run on
In-Memory today, the early product on SQLite, the growing service on
PostgreSQL, and the enterprise fleet on Cyoda Cloud — with the same code.
## Where to go next
- [Run → overview](/run/) — practical deployment guidance for each tier.
- [Build → testing with digital twins](/build/testing-with-digital-twins/) —
using In-Memory mode for scenario tests.
---
## concepts/entities-and-lifecycle.md
# Entities and lifecycle
Entities are durable state machines — schemas, states, transitions, and history.
In Cyoda, an **entity** is a durable state machine. It is a JSON document that belongs
to a typed model, sits in a named lifecycle state, and carries a complete audit trail
of every transition it has ever undergone. The entity is not a row to be updated in
place; the entity *is* the state machine.
## The entity IS the state machine
A Cyoda workflow is close in spirit to a BPM process, but the two are not the same.
A BPM flow tends to be linear — it has a start, a sequence of activities, and an end.
A Cyoda entity workflow is a state machine in the strict sense: there is no
requirement for a terminating state, transitions need not follow a linear path, and
an entity can move between states in any topology the model calls for, including
cycles and branches.
That distinction matters in day-to-day modeling. You do not design "the process" and
then attach entities to it; you design the states and transitions of a piece of
business reality, and the entity lives inside that machine for as long as the
business cares about it.
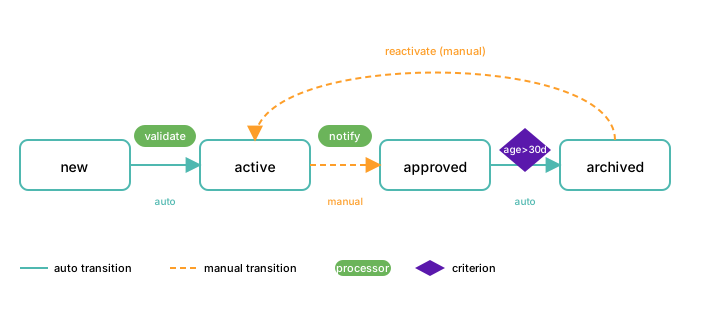
The picture above sketches the building blocks:
- **States** (teal rectangles) — the named stages of the entity's life.
- **Transitions** — the atomic units of change. Auto transitions (solid, teal)
fire as soon as their source state is entered; manual transitions (dashed,
orange) fire only when an actor invokes them.
- **Processors** (green pills on a transition) — code that runs as part of the
transition, under the platform's event contract.
- **Criteria** (purple diamonds on a transition) — predicates that gate whether
the transition is allowed to fire.
Every transition produces a new, durable revision of the entity. Nothing is
overwritten.
## Schema
Every entity belongs to a named **model** identified by `modelName` and
`modelVersion`. Cyoda auto-discovers the model schema from ingested samples
rather than requiring it up front: as records flow in, Cyoda observes the
fields that appear, the types they take, and the shape of nested arrays
and objects. That observed shape is the schema.
A model has two structural modes. While **unlocked**, it evolves by merging
— new fields appear, types widen, a field comes to declare more than one
kind. When **locked**, the
structural contract is frozen and any incoming entity that does not match
is rejected. Lock is the right default for production systems with external
producers, where silently accepting a widened shape would be a compliance
or correctness failure. `modelVersion` is application-controlled; to change
the contract after lock, the application bumps the version and **registers
the new schema** for it — by submitting a comprehensive set of
representative samples (the same mechanism as initial discovery; the
samples themselves are not stored). Old revisions are never re-validated
or re-cast; each remains valid under the model version active at write
time. See [Modeling entities](/build/modeling-entities/) for when to choose
each mode and how to plan evolutions.
The wire format and field conventions for exported models (type
descriptors, array representations, structural markers) are in the
[entity-model export reference](/reference/entity-model-export/).
## History and temporal queries
Because transitions produce revisions rather than overwriting state, the full history
of an entity is always retrievable. You can ask:
- "What did this entity look like at timestamp T?" — point-in-time reconstruction.
- "What transitions has this entity been through, and when?" — transition log.
- "Which version of the model was this revision validated against?" — schema lineage.
This is not an add-on audit layer bolted onto a mutable store; it is the storage model.
See the [API reference](/reference/api/) for the temporal-query grammar.
---
## concepts/what-is-cyoda.md
# What is Cyoda?
An Entity Database Management System — a database engine where the first-class abstraction is a stateful entity with schema, lifecycle, history, and transactional integrity.
Cyoda is an **Entity Database Management System (EDBMS)**. Unlike a relational
database, where the unit is a row in a table, and unlike a document database,
where the unit is a JSON blob, Cyoda's first-class unit is an **entity**: a
typed document that carries a lifecycle state, a complete history of every
change, and transactional integrity.
## An EDBMS, not a database
Most databases answer one question well: *what is the state of the world right
now?* They leave you to glue in a workflow engine, a message bus, an audit
layer, and a schema registry on top.
An EDBMS answers a broader question: *how does this thing evolve, under what
rules, and how do I ask what it looked like last Tuesday?* It folds the
workflow engine, the audit trail, the schema registry, and the event contract
into the storage model. Everything the entity does — transitions, rule
evaluations, processor invocations, revisions — is a first-class, queryable
part of the same store.
Out of the box, an entity in Cyoda has:
- a **schema** discovered from ingested samples, evolving over time, lockable;
- a **lifecycle state** governed by a workflow;
- **transactional transitions** that produce durable, addressable revisions;
- a **temporal history** you can query at any point in the past;
- an **audit trail** of every rule, transition, and processor that touched it.
## Why this shape
Cyoda targets domains where state, rules, and data must evolve together:
financial ledgers, order management, regulatory compliance, digital twins.
These domains share a property — "the row got updated" is not enough
information. You need to know *why* it changed, *under what rules*, and what
the world looked like before. That information has to be engineered into a
normal database as an afterthought; an EDBMS makes it the default.
## Two forms today
Cyoda ships in two closely related forms, with the same semantics:
- **cyoda-go** — an open-source Go implementation, run as a local binary or a
small cluster. Backends are In-Memory, SQLite, or PostgreSQL, chosen at start.
- **Cyoda Cloud** — a managed service backed by the Cassandra-based Cyoda
Platform Library. Horizontally scalable, multi-tenant, with enterprise
identity, observability, and provisioning.
Applications written against one run against the other without rewriting the
domain model.
## The growth path
You can start on a laptop in minutes and graduate — on your schedule — to a
container, to Kubernetes, or to Cyoda Cloud as scale and operational needs
demand. The entity, workflow, and API contracts do not change as you move.
## Where to go next
- [Design principles](/concepts/design-principles/) — the mental model in one
read.
- [Entities and lifecycle](/concepts/entities-and-lifecycle/) — the state
machine shape of an entity, including a worked example diagram.
- Digital twins and the growth path — how the same application runs at every
tier. *(Coming as Concepts fills out.)*
- For per-engine operational characteristics and deployment guidance, see
[Storage engines](/run/storage-engines/).
---
## concepts/workflows-and-events.md
# Workflows and events
State machines as a first-class concept — triggers, external processors, and audit trails.
A **workflow** is the state machine an entity lives inside. It declares the
states an entity can be in, the transitions between them, the criteria that
gate whether a transition is allowed, and the processors that run along the
way. This page explains the concept; the
[Build guide for workflows and processors](/build/workflows-and-processors/)
covers how to configure one.
## State machines define allowed change
Every entity type has a workflow. Nothing changes the entity except a
transition defined in that workflow. A transition is atomic: it produces a new,
durable revision of the entity, runs any attached processors under the
platform's event contract, and either succeeds or has no effect.
Workflows are general state machines, not pipelines. Transitions can be
automatic (fire as soon as their source state is entered and any criteria are
satisfied) or manual (fire only when invoked by an actor). A workflow can
contain cycles, branches, and multiple terminal-looking states that are
actually re-entered later — it does not need to terminate at all.
## Triggers
Transitions fire in one of two ways:
- **Manual** — an actor (a user, a service, an admin) calls the transition by
name through the API.
- **Automatic** — on entering a state, the first valid auto transition fires
within the same transaction, recursing until no further auto transition
applies.
## Processors
A **processor** is code that runs as part of a transition. It can read the
entity, compute a new field, call an external service, persist a side effect,
or reject the transition.
Two flavours:
- **Internal processors** — shipped with the platform for common work
(validation, projection, enrichment) and invoked declaratively.
- **External processors** — your code, hosted anywhere, called by Cyoda over
gRPC. External processors preserve audit hygiene (every call is logged
against the transition), keep authorization simple (the platform brokers
identity), and support bidirectional streaming for high-throughput
workloads. For why gRPC is preferred and how to implement one, see
[Build → client compute nodes](/build/client-compute-nodes/).
Processors can run synchronously within the transition's transaction, or
asynchronously alongside it.
Processors run in one of three modes: **SYNC** (inline, shares the
transition's transaction — failure aborts the transition), **ASYNC_SAME_TX**
(runs asynchronously but in the same transaction context — failure still
aborts), or **ASYNC_NEW_TX** (runs in a separate transaction via savepoint
isolation — failure is logged and the transition succeeds). Choose the mode
based on how atomically the side-effect must compose with the state change.
## Audit trail is the storage model
Because every transition produces a revision and every processor invocation is
recorded against it, the audit trail is not a separate log — it is a view of
the storage. You can query the transitions an entity has been through, the
criteria that were evaluated, the processors that ran, and the inputs and
outputs of each. Point-in-time queries use the same index.
## Why this matters
State machines plus durable transitions plus a queryable audit trail are the
native ingredients for **regulated**, **auditable**, and **replayable**
systems. Replaying a workflow from history does not require an event-sourcing
framework on the side — it is the default behavior of the store.
## Where to go next
- [Entities and lifecycle](/concepts/entities-and-lifecycle/) — the entity
side of the machine, with a state-machine diagram.
- [Build → workflows and processors](/build/workflows-and-processors/) — how
to declare a workflow in practice.
- [Build → client compute nodes](/build/client-compute-nodes/) — how to
implement an external processor over gRPC.
---
## cyoda-cloud.md
# Cyoda Cloud
Managed, isolated cyoda-go environments behind a single control-plane API — coming soon.
Coming soon · In design
**Cyoda Cloud is coming.** It is the managed service for running
systems built on [cyoda-go](https://github.com/Cyoda/cyoda-go):
managed, isolated cyoda-go environments behind a single control-plane
API — provisioning, environment lifecycle, credential brokering for
compute nodes, deployment, and per-environment observability.
The data-plane surface is identical to what you run locally. Entity
models, workflow configuration, and compute-node code carry over
without modification; the control plane adds the cloud-only concerns
and nothing else.
We are currently at the design stage of the new architecture. This
section documents the design and the contracts it will honor; details
will change as the design settles. See
[Status and roadmap](./status-and-roadmap/) for where things stand.
⭐ Star [cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli)
— every star is a vote that shapes our prioritisation — and
[join the waitlist](https://cyoda.com/cloud) to get early access when
the doors open.
## Tiers
| Tier | Storage | Intended use |
| --- | --- | --- |
| Local (OSS, free) | SQLite / Postgres | Development |
| Cloud — shared | Isolated Postgres per environment | Team access, integration, early production |
| Cloud — dedicated | Dedicated Postgres | Production with stricter isolation requirements |
| Cloud — enterprise | `cyoda-go-cassandra` (commercial license) | High-volume production |
Moving between tiers is an infrastructure change; application code and
data models are unaffected.
cyoda-go is Apache-2.0: the local tier is the full engine, not a
feature-limited edition, and Cyoda Cloud is a service, not a license
unlock. Only the enterprise storage engine carries a commercial
license.
## Architecture
Per environment, the data plane consists of:
- **A managed cyoda-go core** — the official engine image, operated by
Cyoda. It exposes the environment's API and acts as the gRPC server
for compute nodes.
- **Isolated storage** — a Postgres schema per environment, with
dedicated credentials. Cross-tenant access is excluded at the
database layer, not by application logic.
- **Your compute nodes** — your code, your image, built and shipped by
your own pipeline. A node dials into the core over a persistent
bidirectional gRPC stream and receives processor and criteria work
pushed down that stream — the same
[client compute node](/build/client-compute-nodes/) contract as a
local instance. Because the node dials out, it can run on cloud
infrastructure, in CI, or on a workstation joined to a cloud core.
Above the data plane sits a single control plane covering environment
lifecycle, provisioning, credential brokering, deployment triggers, and
per-environment observability. It never holds your application source:
your pipeline builds the compute-node image, pushes it to an isolated
per-environment registry under a federated deploy identity, and
triggers a rolling update.
## Control-plane clients
One versioned control-plane API; two peer clients:
- **A dashboard** — workflow visualisation, live entities, audit
timeline, logs, system health.
- **[cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli)** —
the scriptable client for developers and coding agents: data as JSON
on stdout, progress and errors on stderr, stable documented exit
codes, idempotency keys on every mutating call, and a non-interactive
variant of every flow.
Neither has private endpoints: anything the dashboard can do, the API
can do — and therefore the CLI, and therefore an agent driving it.
## In this section
- [Provisioning](./provisioning/) — how environments will be created
and managed.
- [Identity and entitlements](./identity-and-entitlements/) — the
identity and subscription design we are working toward.
- [Status and roadmap](./status-and-roadmap/) — where the rebuild
stands.
---
## cyoda-cloud/identity-and-entitlements.md
# Identity and entitlements (Cyoda Cloud)
The identity and entitlements design we are working towards for Cyoda Cloud — OIDC, signing keys, and subscription tiers.
:::caution[Design — not yet implemented]
Cyoda Cloud is [being rebuilt](./status-and-roadmap/). This page
describes the **current design we are working towards implementing**
for identity and entitlements on Cyoda Cloud. Nothing on this page is
live yet, and details may change as the design settles.
:::
> This page covers identity operations for the **hosted Cyoda Cloud**
> platform. The OIDC provider trust, signing-key, and M2M-client surface
> described here as cloud design now ships in self-hosted **cyoda-go**;
> for running it on your own instance see
> [Reference → Identity and IAM](/reference/identity-and-iam/). The
> data-plane contract is identical, so what you configure locally carries
> over to the managed service.
## Overview
Cyoda Cloud authenticates users and technical clients via JWT access tokens. Tokens can be:
- Issued by Cyoda using internally managed asymmetric signing keys, for technical users (machine-to-machine API clients) and other scenarios where your own infrastructure needs to issue JWTs trusted by Cyoda.
- Issued by an external OpenID Connect (OIDC) provider that Cyoda is configured to trust, allowing you to use your own identity provider for regular and technical users, auto-enroll users from trusted JWT claims, and map IdP roles onto Cyoda authorities.
Once authenticated, what each identity can do on the platform is bounded by the subscription tier and its associated entitlements.
## Signing keys
Cyoda Cloud uses asymmetric JWT signing keys to issue and validate access tokens for technical users and custom integrations.
### JWT signing key attributes
Cyoda Cloud represents each signing key-pair with a set of attributes:
- **Audience (`audience`)**
- Internal Cyoda concept that describes which consumers use tokens signed with this key. This is not the same as the JWT `aud` claim.
- Typical values:
- `human` – tokens issued for the regular users
- `client` – tokens issued for technical users (machine-to-machine access)
- **Algorithm (`algorithm`)**
- Asymmetric signing algorithms only (for example, `RS256`, `RS512`, `ES256`).
- **Validity window (`validFrom`, `validTo`)**
- Optional `validFrom` and `validTo` define when a key becomes valid and when it expires.
- **Key ID (`keyId` / `kid`)**
- Each key-pair has a unique `keyId`.
- This value is included in the JWT header as the `kid` field.
In standard Cyoda Cloud, JWT signing keys for technical users are managed centrally by Cyoda. In custom or on-premise installations, it is also possible to configure an externally injected key-pair file that IAM uses instead of managing keys entirely through the API.
### Managing JWT signing keys
At a high level, you can do the following operations:
1. Create or rotate signing key-pairs for the relevant audience.
2. Invalidate the keys with a grace period and then reactivate them.
3. Delete the key-pairs completely.
#### Example: issue a key for technical users
The following example shows a minimal request for creating a key-pair for technical users:
```json
{
"audience": "client",
"algorithm": "RS256"
}
```
Your token issuer will receive the corresponding `keyId` and the public key. It should use the private key to sign access tokens for technical users and include the `kid` header in each JWT.
#### Example: rotate a key with grace period
To perform a safe rotation with a grace period for technical users:
1. Issue a new key-pair for the `client` audience if you don't have any.
2. Mark the old key as invalid but allow a grace period during which previously issued tokens remain valid, for example:
```json
{
"gracePeriodSec": 3600
}
```
After the grace period expires, you can remove the old key or leave it invalidated.
#### End-to-end example: technical user using a rotated key
Putting it together for a typical environment:
1. **Before rotation**: Your technical user obtains access tokens signed with the old key (for example, `keyId = "old-key-id"`).
2. **Issue new key**: You create a new key for `audience = "client"` and obtain `keyId = "new-key-id"`.
3. **Switch issuer**: Token issuance logic starts using `"new-key-id"` to sign tokens while still accepting tokens with `"old-key-id"` during the grace period.
4. **Verify access**: Both old and new tokens can call Cyoda APIs until the grace period expires.
5. **Finalize rotation**: After the grace period, any remaining tokens signed with `"old-key-id"` are rejected, and you can clean up the old key.
**Key rotation flow**
1. Old active key for the `client` audience
2. Issue a new key for the `client` audience
3. Sign new tokens with the new `keyId`
4. Grace period: accept old and new tokens
5. Invalidate the old key
### Key rotation recommendations
- Rotate keys regularly to limit the potential security risks.
- Separate user and technical-user token lifecycles in your application.
- In custom installations with externally injected key-pairs, align your rotation schedule with how often you replace the external key-pair files.
## OIDC provider configuration
When you register an OIDC provider in Cyoda Cloud, you describe how Cyoda should trust and use tokens from that provider.
Key concepts:
- **Well-known configuration URI**
- The standard OIDC discovery endpoint exposed by your IdP (for example, `https://your-idp/.well-known/openid-configuration`).
- Cyoda fetches the JWKS (public keys) and other metadata from this URL.
- **Issuers list**
- An optional but strongly recommended list of allowed `iss` (issuer) values.
- When present and non-empty, Cyoda requires the JWT `iss` claim to match one of these values.
- When omitted or empty, issuer validation is skipped.
- **Provider state**
- Providers can be active or inactive. Inactive providers are ignored during JWT validation, and any keys loaded for them are treated as untrusted.
In most environments, Cyoda Cloud comes pre-configured with providers for the supported identity options (for example, Auth0 for the default UI). Custom OIDC providers are typically used for enterprise integrations.
### How Cyoda uses OIDC providers
At a high level, Cyoda IAM uses configured OIDC providers to:
1. Validate the JWT signature and basic claims (for example, issuer or expiration).
2. Extract required claims that identify the user and their organization within the Cyoda instance.
3. Apply auto-enrollment logic:
- Create a **user** record based on the token.
- Create a **legal entity** record based on organization-related claims (allowed only in custom installations).
4. Build the authenticated principal with **authorities** derived from role-related claims.
The exact auto-enrollment behavior depends on how your environment is configured, but the required claims listed below must be present for the standard Cyoda Cloud flow to work.
### Configuring your custom OIDC provider
When configuring your IdP (for example, Auth0, Azure AD, or another OIDC provider) to work with Cyoda Cloud:
1. Ensure that access tokens issued for Cyoda APIs include at least:
- `sub`
- `org_id`
- `caas_org_id`
2. Configure a claim (often via custom rules or mappers) that emits `user_roles` as an array of strings for users that need explicit roles.
3. Verify that the token `iss` (issuer) value matches one of the `issuers` configured for the corresponding OIDC provider in Cyoda.
### Operational tips
- Use a dedicated OIDC client/application configuration per environment (dev, test, prod) and reflect that in your `org_id` or `caas_org_id` values as appropriate.
- Keep the list of allowed `issuers` small and explicit to reduce the chance of accepting tokens from an unexpected issuer.
- When rotating keys at your IdP, you can trigger a reload of provider metadata (including JWKS) in Cyoda Cloud using the appropriate API.
### End-to-end example: custom OIDC provider
The following example describes a typical setup using an external OIDC provider as the IdP:
1. **Configure your application in the OIDC provider** representing your Cyoda environment.
2. **Create a rule or action** that adds the following claims to the access token when the audience matches your Cyoda App:
- `sub` (OIDC provider user ID)
- `org_id` (your external organization identifier)
- `caas_org_id` (the Cyoda legal entity identifier for your installation - `your_user_id` for the single-user Cyoda instance)
3. **Register the OIDC provider in Cyoda Cloud** using the OIDC `.well-known/openid-configuration` URL and, optionally, the expected `iss` value.
4. **Test login** via the OIDC provider, obtain an access token, and call a Cyoda API endpoint. Cyoda Cloud validates the token and auto-enrolls the user under your legal entity if needed.
1. **User → OIDC Provider** Login with browser
2. **OIDC Provider → User** Redirect with access token
3. **User → Cyoda Cloud** Call API with bearer token
4. **OIDC Provider → Cyoda Cloud** Serve JWKS so the signature can be validated
5. **Cyoda Cloud → User** Authorized response (user enrolled, roles applied)
## JWT claims → role mapping
When integrating a **custom OIDC provider**, its access tokens must carry specific claims so that Cyoda Cloud can:
- Identify the user
- Identify the organization (legal entity)
- Map roles
The following table summarizes the claims used by the integration:
| Claim name | Type | Required? | Purpose |
|-----------|------|-----------|---------|
| `sub` | string | Yes | Standard OIDC subject. Used as a stable external user identifier. |
| `org_id` | string | Yes | External organization identifier provided by your IdP. Used as the legal entity external key and to build a human-readable name (for example, `"Org. "`). |
| `caas_org_id` | string | Yes (for Cyoda-backed tenants) | Cyoda legal entity identifier (`caas_org_id`). Used as the `owner` of both users and legal entities. |
| `user_roles` | array of strings | Recommended | List of application or user roles. If absent, the user is treated as having no additional roles. |
## Entitlements
Access to Cyoda Cloud will be subscription-tier-based. This section describes the planned subscription tiers and their entitlements.
**Important**: The information below reflects the current design and is not guaranteed to survive into the launched service unchanged. Once Cyoda Cloud is live, the authoritative source for your account's subscription details and entitlements will be the Cyoda Cloud API, at endpoints along these lines:
- **Current account information**: `GET /account` — Retrieve information about the current user's account, including current subscription.
- **All available subscriptions**: `GET /account/subscriptions` — Retrieve all subscriptions available for the current user's legal entity.
For complete API documentation, refer to the [OpenAPI specification](/api-reference/).
### Subscription tiers overview
| Entitlement | Free1 | Developer | Pro | Enterprise License2 |
| --- | --- | --- | --- | --- |
| **Status** | Planned | Draft | Draft | Available |
| **Model Fields (per model)** | 150 | 150 | 500 | Unlimited |
| **Model Fields (cumulative)** | 300 | 300 | 2000 | Unlimited |
| **Models** | 20 | 20 | 100 | Unlimited |
| **Client Nodes** | 1 | 1 | 5 | Unlimited |
| **Payload Size** | 5 MB | 5 MB | 50 MB | Unlimited |
| **Disk Usage** | 2 GB | 2 GB | 1 TB | Unlimited |
| **API Requests** | 300/min | 300/min | 50/sec | Unlimited |
| **External Calls** | 300/min | 300/min | 50/sec | Unlimited |
1 _Free Tier environments will be automatically reset after an expiry period. Contact us for details._
2 _Enterprise License covers the commercial `cyoda-go-cassandra` storage engine for dedicated or self-operated deployments. Contact us for details._
**Status legend:**
- **Planned**: Tier is part of the launch design for the rebuilt Cyoda Cloud.
- **Draft (unavailable)**: Tier is in an earlier planning phase; shape and limits may change substantially.
- **Available**: Offered today as a commercial license, independent of the Cyoda Cloud rebuild.
### Entitlement definitions
The following section provides detailed definitions for each entitlement ID used in the subscription tiers:
| Entitlement ID | Description |
| --- | --- |
| `NUM_MODEL_FIELDS` | Maximum number of fields allowed per individual data model. This controls the complexity of each model you can create. |
| `NUM_MODEL_FIELDS_CUMULATIVE` | Total number of fields allowed across all data models in your account. This is the sum of fields across all your models. |
| `NUM_MODELS` | Maximum number of data models you can create in your account. Each model represents a different data structure or entity type. |
| `NUM_CLIENT_NODES` | Maximum number of client nodes that can connect to your Cyoda Cloud instance simultaneously. This controls concurrent compute capacity. |
| `PAYLOAD_SIZE` | Maximum size in bytes for individual API request payloads. This limits the amount of data you can send in a single API call. |
| `DISK_USAGE` | Maximum disk storage space allocated for your account data in bytes. This includes all stored models, data, and metadata. |
| `API_REQUEST` | Maximum number of API requests allowed per time interval. This controls the rate at which you can make API calls. |
| `EXTERNALIZED_CALL` | Maximum number of external compute calls allowed per time interval. This applies to calls made from your Cyoda Cloud instance to your connected compute nodes. |
---
_This subscription tier information reflects the current design for the rebuilt Cyoda Cloud. Once the service is live, the `/account` API endpoints will be the authoritative source for your specific account entitlements._
---
## cyoda-cloud/provisioning.md
# Provisioning (Cyoda Cloud)
How Cyoda Cloud environments will be provisioned — self-service via the dashboard or the cyoda-cloud-cli.
Coming soon · In design
Cyoda Cloud is being built; this page describes how provisioning
**will** work. The design is still settling — command names and flows
below are the planned surface and may change before launch. See
[Status and roadmap](./status-and-roadmap/) for where things stand.
## Self-service by design
Provisioning is a first-class, user-invoked action — not a back-office
process. Once you have an account, creating an environment is one
authenticated call against the control-plane API, issued either from
the dashboard or from the
[cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli).
Creating an environment provisions, in one idempotent operation:
1. **Isolated storage** — a dedicated Postgres schema with its own
credentials; cross-tenant access is structurally impossible.
2. **A managed cyoda-go core** — the official engine image, wired to
your schema, exposing your environment's API and the gRPC endpoint
your compute nodes join.
3. **Your deploy surface** — an isolated registry and a federated
deploy identity, so *your* pipeline (never Cyoda's) can build and
ship your compute-node image.
4. **Edge routing** — a stable hostname for your environment, with TLS.
Provisioning is tracked as a saga with a coarse, stable status you can
poll (`provisioning → ready`, or `failed` with cleanup of partial
resources). Mutating calls carry idempotency keys, so retries — human
or agent-driven — are always safe.
## The CLI
The developer- and agent-facing way to drive all of this is
[`cyoda-cloud-cli`](https://github.com/Cyoda/cyoda-cloud-cli),
currently being developed in the open alongside the control plane. The
planned command surface:
| Area | Commands | Notes |
| --- | --- | --- |
| Auth | `login`, `logout`, `whoami` | Browser or device flow; tokens stored in your OS keychain. |
| Environments | `env create / list / status / delete` | `--wait` polls until provisioning completes. |
| Compute credentials | `member token mint` | Credentials that let a compute node on your machine or in your CI join your cloud environment. |
| Deploy | `rollout trigger / status` | Trigger and watch rolling updates of your compute node. |
| Observability | `logs tail` | Your environment's logs, tenant-scoped, in your terminal. |
The expected first-environment flow, end to end:
```sh
cyoda-cloud login
cyoda-cloud env create my-app --wait
cyoda-cloud member token mint --env my-app
# point your compute node at the environment's gRPC endpoint + token
```
The CLI is built agent-first from day one: data as JSON on stdout,
progress and errors on stderr, stable documented exit codes, and a
non-interactive variant of every flow. If you drive your development
with an AI coding agent, this CLI is designed to be its hands.
The CLI lives at
[github.com/Cyoda/cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli).
⭐ Star it to tell us you want Cyoda Cloud built, and
[join the waitlist](https://cyoda.com/cloud) for early access.
## What stays out of the CLI
The CLI is a **control-plane** client only: environments, credentials,
deployments, logs. Data-plane work — entity models, workflow
configuration, entity inspection — uses
[cyoda-go's own tool surface](/reference/cli/), which works identically
against a local instance and a cloud core. That split is what keeps the
local-to-cloud hop honest: same data-plane tools throughout, plus one
CLI for the cloud-only concerns.
## Until launch
There is nothing to provision yet. Today you can:
- [Run cyoda-go locally](/run/) — the full engine, free, on your
machine. Everything you build carries over unchanged.
- Star [cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli)
and [join the waitlist](https://cyoda.com/cloud).
- Talk to us on [Discord](https://discord.com/invite/95rdAyBZr2).
---
## cyoda-cloud/status-and-roadmap.md
# Status and roadmap (Cyoda Cloud)
Where the Cyoda Cloud rebuild stands and what is coming next.
## Current status
**🏗️ Rebuilding** — We are rebuilding Cyoda Cloud on
[cyoda-go](https://github.com/Cyoda/cyoda-go), and we are
currently at the **design stage** of the new architecture. There is no
hosted service to sign up for yet.
What's true today:
| Area | Status |
|---|---|
| **Architecture** | New multi-tenant design (managed cyoda-go cores, isolated Postgres per environment, client-owned compute nodes) is in active design. See the [Cyoda Cloud overview](/cyoda-cloud/). |
| **Local development** | Fully available now. [cyoda-go](https://github.com/Cyoda/cyoda-go) is Apache-2.0 OSS and runs on your machine — everything you build will carry over to the cloud unchanged. See [Run](/run/). |
| **CLI** | [cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli) is established and will be developed in the open alongside the control plane. |
| **Identity & entitlements** | Design we're working towards is documented at [Identity and entitlements](./identity-and-entitlements/). |
**⭐ Star [cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli)** to tell us you want Cyoda Cloud built, and **[join the waitlist](https://cyoda.com/cloud)** for early access.
**Reach out to us on [Discord](https://discord.com/invite/95rdAyBZr2)** with questions or feedback — design-stage input has the most leverage.
## Roadmap
In order, deliberately coarse while the design settles:
1. **Design** *(we are here)* — multi-tenant architecture, control
plane, provisioning model, identity and entitlements.
2. **Control plane and provisioning** — environment lifecycle behind
one versioned API, with the dashboard and
[cyoda-cloud-cli](https://github.com/Cyoda/cyoda-cloud-cli)
as peer front ends.
3. **Early access** — first hosted environments for waitlist members.
4. **General availability** — self-service signup, subscription tiers,
and the [dedicated and enterprise tiers](/cyoda-cloud/#tiers) beyond
the shared tier.
We'll keep this page and [Discord](https://discord.com/invite/95rdAyBZr2)
updated as milestones land.
---
## getting-started/install-and-first-entity.md
# Install cyoda-go and create your first entity
Install cyoda-go with SQLite (the default), define an entity model, trigger a workflow, and read state back.
This page takes you from nothing installed to a persisted entity you can query,
running entirely on your own machine. The default backend is **SQLite** — zero
operational overhead, one file on disk, data survives restarts.
## Install Cyoda
cyoda-go ships as a single binary. Pick the flavour that fits your machine; the
authoritative list of installers lives in the
[cyoda-go README](https://github.com/Cyoda/cyoda-go#install).
```bash
# macOS / Linux via Homebrew
brew install cyoda/cyoda-go/cyoda
```
The Homebrew formula is expected to run `cyoda init` automatically, enabling
SQLite persistence with data at `~/.local/share/cyoda/cyoda.db` on macOS/Linux.
If it didn't (or if you installed another way), run `cyoda init` yourself — see
`cyoda help cli init` for what it does. A `curl | sh` installer, Debian
packages, and Fedora RPMs are available for other environments.
## Install Cyoda coding agent skills
Building with Cyoda is easiest with an AI coding assistant. The Cyoda Skills plugin drops in
to Claude Code, Cursor, Codex, and other compatible tools, giving them
the skills to set up a local instance, model entities, design
workflows, and run tests against your Cyoda app. Install it from
github.com/Cyoda/cyoda-skills
and let your assistant lead — the rest of this page walks through the
same steps by hand.
## Why SQLite is the default
SQLite is durable (data survives restarts), zero-ops (no server to run), and
single-file (easy to inspect, back up, or delete). It is the right starting
point for everyone except two groups: teams running functional tests where
latency matters more than durability (use **in-memory** mode — see the callout
below), and teams building production services (graduate to **PostgreSQL** when
you need active-active HA; see [Run → overview](/run/)).
## Start the server
Start the server with the defaults:
```bash
cyoda
```
Running `cyoda` (no subcommand) defaults to **mock auth** (`CYODA_IAM_MODE=mock`): every
request is authenticated as a configurable default user, no bearer token
required. You'll see examples elsewhere in the docs with
`-H "Authorization: Bearer $TOKEN"`; those are written for production
deployments running in JWT mode. On a fresh local install you can drop
the header — or keep it and send any placeholder; mock mode ignores it.
Flip to JWT mode by setting `CYODA_IAM_MODE=jwt` plus
`CYODA_JWT_SIGNING_KEY` (RSA private key, PEM). For the full auth-mode
configuration see [Configuration](/reference/configuration/).
## Discover everything else with `cyoda help`
Every flag, environment variable, endpoint, error code, metric, and operation
is documented in the binary. Browse the topic tree:
```bash
cyoda help
```
Drill in on anything:
```bash
cyoda help config # configuration model and precedence
cyoda help crud # entity CRUD over REST
cyoda help search # query predicates and search modes
cyoda help errors # the error catalogue
cyoda help telemetry # metrics, health, tracing, logs
```
`cyoda help --format=json` emits a machine-readable shape suitable
for tools; `--format=markdown` is the default off a TTY.
## Import a workflow
Before creating an entity, import a workflow so the platform knows which
state machine to apply. Save this as `workflow.json` — two states
(`draft` and `submitted`) with one manual transition. States are keyed by
name; each state owns its outgoing transitions:
```json
{
"workflows": [
{
"version": "1",
"name": "orders-wf",
"initialState": "draft",
"active": true,
"states": {
"draft": {
"transitions": [
{ "name": "submit", "next": "submitted", "manual": true }
]
},
"submitted": {}
}
}
]
}
```
Post it to the import endpoint for the `orders` model at version `1`:
```bash
curl -X POST http://localhost:8080/api/model/orders/1/workflow/import \
-H 'Content-Type: application/json' \
-d @workflow.json
```
Without this step, cyoda-go applies its default workflow (`NONE` →
`CREATED` → `DELETED` with a single automatic transition), and the
`submit` transition used below will not exist.
For the full workflow schema — processors, criteria, automatic
transitions, nested conditions — see
[Build → workflows and processors](/build/workflows-and-processors/).
## Create your first entity
Define a minimal model and push an entity. Cyoda discovers the schema from the
sample you send, so you do not need to declare it up front:
```bash
ENTITY_ID=$(curl -s -X POST http://localhost:8080/api/entity/JSON/orders/1 \
-H 'Content-Type: application/json' \
-d '{ "orderId": "ORD-1", "amount": 42.00, "currency": "EUR" }' \
| jq -r '.[0].entityIds[0]')
echo "$ENTITY_ID"
```
The create response is an array; `entityIds[0]` on the first element is the
**system-assigned UUID** of the new entity. Subsequent reads and transitions
address the entity by that UUID (`${ENTITY_ID}` here), not by the business
key `orderId`.
Automatic transitions (`manual: false`) fire immediately on creation,
cascading the entity through applicable states until it reaches one with
no outgoing auto transitions. The `orders-wf` workflow you just imported
has none, so the entity settles in `draft` and waits for the manual
`submit` transition below.
## Invoke a manual transition
Trigger the `submit` transition on your entity. `{entityId}` (here
`${ENTITY_ID}`) is the system-assigned UUID captured from the create
response, not the business key `orderId`:
```bash
curl -X PUT http://localhost:8080/api/entity/JSON/${ENTITY_ID}/submit
```
## Read state back
Fetch the current state and the transition log:
```bash
curl http://localhost:8080/api/entity/${ENTITY_ID}
```
The response shows the entity in its new `submitted` state plus a record of
every revision it has been through. For the full request and response shapes,
see the [API reference](/reference/api/).
## Next steps
- **Explore the binary.** Every flag, env var, endpoint, and error is
described by a `cyoda help ` action. Browse the full tree at
[Help → topic tree (`cyoda help`)](/help/topic-tree/).
- **Understand the model.** Read [Design principles](/concepts/design-principles/)
and [Entities and lifecycle](/concepts/entities-and-lifecycle/) for the mental
model behind what you just did.
- **Build real applications.** Start with
[Build → working with entities](/build/working-with-entities/) for the
end-to-end patterns.
- **Choose a deployment tier.** See [Run → overview](/run/) when you outgrow
local SQLite.
If you want fast functional tests without durability, run cyoda-go in
**in-memory** mode (`go run ./cmd/cyoda` or the `CYODA_STORAGE_BACKEND=memory` profile).
See [Testing with digital twins](/build/testing-with-digital-twins/) for the
pattern.
---
## help.md
# Browse cyoda help
Static mirror of cyoda-gos `cyoda help` and live HTTP help API, optimized for both humans and AI agents. Pinned to a specific cyoda-go release.
export const topLevelTopics = helpIndex.topics
.filter(t => t.path.length === 1)
.sort((a, b) => a.path[0].localeCompare(b.path[0]));
This section is a static mirror of the cyoda-go binary's help surface
— the same content `cyoda help …` prints on the CLI and the live
HTTP help API serves at runtime. It exists for readers who don't have
a local cyoda-go runtime installed, and for AI agents that need to
discover and consume cyoda-go's help without running the binary.
Every rendered page below has a sibling raw-markdown view at
`.md` and a structured JSON descriptor at `.json`.
For example, [`/help/cli/`](/help/cli/) has
[`/help/cli.md`](/help/cli.md) (markdown body only) and
[`/help/cli.json`](/help/cli.json) (full descriptor with `body`,
`sections`, `see_also`, `children`, etc.).
The pages under `/help/` are pinned to **cyoda-go v{helpIndex.pinnedVersion}**.
The binary you run is the authority for the version you run; if your
binary is newer, prefer its output.
## Browse the tree
{topLevelTopics.map(t => (
))}
{`
.help-card-grid {
display: grid;
gap: 1rem;
/* As many columns as fit at min 22rem each; collapses to one when viewport is narrower. */
grid-template-columns: repeat(auto-fit, minmax(min(100%, 22rem), 1fr));
margin-block: 1.5rem;
}
`}
For a flat view of every topic and subtopic, see
[cyoda help topic tree](/help/topic-tree/).
## For agents
Agents navigate the mirror via three primitives plus a discovery file:
- [`/help/index.json`](/help/index.json) — manifest of every topic
with `topic`, `title`, `stability`, `tagline`, `see_also`. The
envelope is byte-equivalent to the live API's `GET /help` response.
- `/help/.json` — full topic descriptor including `body`,
`sections[]`, `see_also`, `stability`, `actions`, `children`. Same
shape as the live API's `GET /help/{topic}` response.
- `/help/.md` — body only, no frontmatter, no chrome.
- [`/help/versions.json`](/help/versions.json) — version registry.
Discovery hint: [`/help/llms.txt`](/help/llms.txt) and the site-level
[`/llms.txt`](/llms.txt) both advertise these endpoints and the URL
convention.
### URL convention
`cyoda help A B C` ↔ `https://docs.cyoda.net/help/a/b/c/` for the
rendered page, or `.md`/`.json` for the raw payloads. Manifest topic
IDs use the live API's dotted form and may be mixed-case
(`config.database`, `errors.BAD_REQUEST`); replace dots with slashes
**and lowercase** to build the URL — e.g. `errors.BAD_REQUEST` →
`/help/errors/bad_request/`.
---
## help/admin.md
# admin — runtime-switchable admin endpoints
Both endpoint families require `ROLE_ADMIN` on the JWT and update process-local state atomically. State is **not** propagated across nodes; multi-node dep…
cyoda-go version 0.8.4
# admin
## NAME
admin — runtime-switchable controls exposed on the main API listener.
## SYNOPSIS
```
GET /api/admin/log-level
POST /api/admin/log-level
GET /api/admin/trace-sampler
POST /api/admin/trace-sampler
```
## DESCRIPTION
Both endpoint families require `ROLE_ADMIN` on the JWT and update process-local state atomically. State is **not** propagated across nodes; multi-node deployments must hit each node's endpoint separately.
## ENDPOINTS
### log-level
`GET /api/admin/log-level` returns the current effective log level as JSON:
```
{"level": "info"}
```
`POST /api/admin/log-level` changes the level atomically. Request body: `{"level": ""}`. Response: `{"level": "", "previous": ""}`. Valid values: `debug`, `info`, `warn`, `error`.
### trace-sampler
`GET /api/admin/trace-sampler` returns the current OpenTelemetry sampler configuration:
```
{"sampler": "ratio", "ratio": 0.1, "parent_based": true}
```
`POST /api/admin/trace-sampler` changes the sampler atomically. Body shape mirrors the GET response. Valid `sampler` values: `always`, `never`, `ratio`. When `sampler` is `ratio`, `ratio` must be a float in `(0, 1]`. Use `sampler: never` for zero sampling — `ratio: 0` is rejected.
## EXAMPLES
```
# Read current log level
curl -H "Authorization: Bearer $TOKEN" \
http://localhost:8080/api/admin/log-level
# Switch to debug
curl -X POST -H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"level":"debug"}' \
http://localhost:8080/api/admin/log-level
# Sample 10% of traces
curl -X POST -H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"sampler":"ratio","ratio":0.1}' \
http://localhost:8080/api/admin/trace-sampler
# Force 100% sampling on this node regardless of upstream
curl -X POST -H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"sampler":"always","parent_based":false}' \
http://localhost:8080/api/admin/trace-sampler
# Disable local sampling (still honors upstream-sampled traceparent; set parent_based:false to override)
curl -X POST -H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"sampler":"never"}' \
http://localhost:8080/api/admin/trace-sampler
```
## NOTES
- `parent_based` defaults to `true` and respects upstream sampling decisions in the `traceparent` header. With `parent_based: true`, an upstream "do not sample" overrides this node's `sampler: always`. This is standard OpenTelemetry `ParentBased` semantics and is usually correct for distributed-trace integrity. Set `parent_based: false` to override.
- The initial sampler at process start is seeded from the standard OpenTelemetry env vars `OTEL_TRACES_SAMPLER` and `OTEL_TRACES_SAMPLER_ARG`. Supported values are the six standard combinations from the OTel spec (`always_on`, `always_off`, `traceidratio`, and their `parentbased_` variants). The admin endpoint is a runtime override, not a replacement.
- Sampler and log level are process-local. Each node has its own state; multi-node deployments need to hit each node's admin endpoint separately.
- `/metrics` exposes application metrics (OIDC, and — with `CYODA_OTEL_ENABLED=true` — transaction/dispatch) in addition to Go runtime/process metrics. The OIDC metric family is present whenever IAM runs in `jwt` mode. See `telemetry` for authentication options and the full metric catalogue.
## SEE ALSO
- `run` — server lifecycle
- `telemetry` — OpenTelemetry exporters and metrics
- `config.auth` — JWT and `ROLE_ADMIN`
## See also
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help telemetry`](/help/telemetry/) — cyoda-go integrates the OpenTelemetry Go SDK (`go.opentelemetry.io/otel`). The
**metric scrape pipeline is always on**: at startup the binary creates a meter
provider with an OpenTelemetry → Prometheus exporter and serves it at
`:9091/metrics`, regardless of `CYODA_OTEL_ENABLED`. No collector is required to
scrape metrics.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## Raw formats
- [`/help/admin.json`](/help/admin.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/admin.md`](/help/admin.md) — body only
---
## help/analytics.md
# analytics — Trino SQL analytics interface
Cyoda Cloud exposes entity data as Trino SQL tables through a Trino connector. The connector uses the Schema Management REST API to discover table definit…
cyoda-go version 0.8.4
# analytics
**Cloud-only.** The analytics surface documented here is served by Cyoda Cloud (`cloud.cyoda.com`). It is not part of the cyoda-go binary. Running a local cyoda-go server does not expose any of the endpoints below.
## NAME
analytics — Trino SQL analytics interface for querying Cyoda entity data via SQL.
## SYNOPSIS
```
# SQL Schema Management REST API (Cyoda Cloud)
GET /api/sql/schema/{schemaId}
DELETE /api/sql/schema/{schemaId}
GET /api/sql/schema/?schemaName={name}
POST /api/sql/schema/
DELETE /api/sql/schema/?schemaName={name}
PUT /api/sql/schema/putDefault/{schemaName}
GET /api/sql/schema/listAll
GET /api/sql/schema/genTables/{entityModelId}
POST /api/sql/schema/updateTables/{entityModelId}
# WebSocket (STOMP) Messaging API (Cyoda Cloud)
treeNode.getSchemas
treeNode.getSchema
treeNode.getData
treeNode.getRawData
view.getViews
view.addView
view.renameView
view.dropView
reports.runReport
reports.getReportConfigs
reports.getReportDefinition
reports.getReportHistories
reports.getReportStatistics
reports.getReportGroups
reports.getReportRows
reports.deleteReports
```
## DESCRIPTION
Cyoda Cloud exposes entity data as Trino SQL tables through a Trino connector. The connector uses the Schema Management REST API to discover table definitions and the WebSocket (STOMP) messaging API to stream entity rows at query time.
## SQL SCHEMA MANAGEMENT REST API
All endpoints are served under `/api/sql/schema` in Cyoda Cloud.
Authentication is required on all endpoints. Errors follow RFC 7807 Problem Details format: `{ "type", "title", "status", "detail", "instance", "properties" }`.
**GET /api/sql/schema/{schemaId}**
Retrieve a complete schema configuration by its time-based UUID. Returns all fields including hidden ones. Returns `400` if the UUID is not a time-based (version 1) UUID; returns `404` if not found.
- `schemaId` (path): UUID (version 1 / time-based)
Response: `200 OK`, `application/json`, `SchemaConfigDto`.
**DELETE /api/sql/schema/{schemaId}**
Delete a schema by UUID. Requires both read and delete permissions. Returns confirmation string on success.
Response: `200 OK`, `application/json`, string — e.g., `"SQL Schema with id 8824c480-c166-11ee-822a-ae468cd3ed16 deleted"`.
**GET /api/sql/schema/?schemaName={name}**
Retrieve a schema by its unique name. Returns `404` if not found.
- `schemaName` (query, required): case-sensitive string, 1–1024 characters
Response: `200 OK`, `application/json`, `SchemaConfigDto`.
**POST /api/sql/schema/**
Save a schema (create or update). Uses upsert semantics: if a schema with the same `schemaName` exists, its tables are replaced with the incoming definition. If no schema with that name exists, a new one is created.
The `id` field in the request body is ignored; matching is done exclusively by `schemaName`. Returns the time-based UUID of the saved schema.
Validation: `schemaName` must be 1–1024 characters.
Request body: `SchemaConfigDto`.
Response: `200 OK`, `application/json`, UUID string — e.g., `"8824c480-c166-11ee-822a-ae468cd3ed16"`.
**DELETE /api/sql/schema/?schemaName={name}**
Delete a schema by name. Returns `404` if not found.
Response: `200 OK`, `application/json`, string — e.g., `"SQL Schema with name NOBEL_PRIZES deleted"`.
**PUT /api/sql/schema/putDefault/{schemaName}**
Create a new schema by scanning all Entity Models the user has read access to. Generates the complete set of tables (object, array, JSON) for every model. Validates for duplicate table names and duplicate field names within a table. On validation failure, returns `422 Unprocessable Entity`.
- `schemaName` (path): string, 1–1024 characters
Response: `200 OK`, `application/json`, `SchemaConfigDto`.
**GET /api/sql/schema/listAll**
List all schemas the user has read access to. Schemas the user cannot read are silently omitted. Returns all fields including hidden ones.
Response: `200 OK`, `application/json`, array of `SchemaConfigDto`.
**GET /api/sql/schema/genTables/{entityModelId}**
Preview: generate SQL table configurations from a specific Entity Model without saving. Read-only.
- `entityModelId` (path): UUID of the Entity Model
Response: `200 OK`, `application/json`, array of `TableConfigDto`.
**POST /api/sql/schema/updateTables/{entityModelId}**
Merge existing table configurations with the current state of an Entity Model. Read-only; does not save. Tables are matched by `uniformedPath`. Fields from the current model are added; existing table custom settings are preserved.
- `entityModelId` (path): UUID of the Entity Model
Request body: array of `TableConfigDto`.
Response: `200 OK`, `application/json`, array of `TableConfigDto`.
## SCHEMA DTO STRUCTURES
**SchemaConfigDto:**
```json
{
"id": "8824c480-c166-11ee-822a-ae468cd3ed16",
"schemaName": "NOBEL_PRIZES",
"tables": [ ...TableConfigDto... ]
}
```
- `id` — UUID (time-based, version 1); server-assigned; null when creating via POST; required for GET/DELETE by ID
- `schemaName` — string, unique, 1–1024 characters
- `tables` — array of `TableConfigDto`; sorted by `uniformedPath` in responses
**TableConfigDto:**
```json
{
"tableName": "nobel_prize",
"metadataClassId": "a1b2c3d4-e5f6-11ee-b789-0242ac120002",
"uniformedPath": "$",
"fields": [ ...FieldConfigDto... ],
"hidden": false,
"modelUpdateDate": 1702900000
}
```
- `tableName` — SQL table display name; auto-generated from model name, version, and path; customizable
- `metadataClassId` — UUID of the Cyoda Entity Model; all tables from the same model share this value
- `uniformedPath` — structural key identifying which node in the model this table represents. Values: `"$"` (root level), `"$.fieldName"` (nested object outside arrays), `"$.fieldName[*]"` (object table under array element), `"$.fieldName[*]^"` (detached array table — individual array elements), `"json"` (special JSON table, full reconstructed entity as string)
- `fields` — array of `FieldConfigDto`
- `hidden` — boolean; hidden tables excluded from WebSocket schema discovery (`filterHidden=true`) but always included in REST responses
- `modelUpdateDate` — int64 (epoch seconds), nullable; last Entity Model update timestamp
**Table naming rules:**
- Base: `{modelName}` when version = 1; `{modelName}_{version}` when version > 1
- Path segments appended with underscores (e.g., `nobel_prize_laureates` for path `$.laureates`)
- Multi-level array nesting: `_{n}d` suffix (e.g., `_2d` for depth 2)
- Detached arrays: `_array` suffix
- JSON table: `_json` suffix
**FieldConfigDto:**
```json
{
"fieldName": "category",
"fieldKey": "category",
"fieldCategory": "DATA",
"dataType": "STRING",
"isArray": false,
"hidden": false,
"flatten": null,
"arrayFields": null
}
```
- `fieldName` — SQL column name; display name; defaults to `fieldKey` for DATA fields; snake_case aliases for ROOT fields
- `fieldKey` — internal resolution key; interpretation depends on `fieldCategory`
- `fieldCategory` — one of: `DATA` (entity payload fields keyed by value map short key), `ROOT` (entity metadata: `creationDate`, `lastUpdateTime`, `state`), `INDEX` (array index fields keyed by nesting level position), `SPECIAL` (synthetic columns: `ENTITY_ID`, `POINT_TIME`, `JSON`)
- `dataType` — one of: `STRING`, `INTEGER`, `LONG`, `DOUBLE`, `BOOLEAN`, `DATE`, `ZONED_DATE_TIME`, `UUID_TYPE`, `TIME_UUID_TYPE`, `BYTE_ARRAY`
- `isArray` — boolean; when true, `arrayFields` contains element-level sub-fields
- `hidden` — boolean
- `flatten` — boolean or null; for INDEX array fields: `true` flattens indices into separate columns (`index_0`, `index_1`, etc.), `false` keeps as array
- `arrayFields` — array of `FieldConfigDto` or null; sub-fields when `isArray=true`
**Reserved field names (cannot be used for DATA fields):** `index`, `entity_id`, `point_time`, `creation_date`, `last_update_date`, `state`.
**Always-present field categories per table:**
- `SPECIAL`: `entity_id` (`UUID_TYPE`), `point_time` (allows point-in-time queries)
- `ROOT`: `creation_date` (`DATE`), `last_update_date` (`DATE`), `state` (`STRING`)
- `SPECIAL` JSON table only: `entity` (`JSON` key, full reconstructed JSON string)
- `INDEX`: present only on tables derived from array nodes
## WEBSOCKET (STOMP) MESSAGING API
The WebSocket API is served by Cyoda Cloud over STOMP. The concrete WebSocket endpoint URL is environment-specific and not part of this contract.
**TreeNode Data Access (treeNode.*):**
- `treeNode.getSchemas` — retrieve all schemas the user can read (hidden items filtered out); payload: userId string
- `treeNode.getSchema` — retrieve a schema by name (hidden items filtered); payload: schemaName string; runs in anonymous context
- `treeNode.getData` — primary data channel; the Trino connector calls this to fulfil SQL SELECT queries; payload: `DataRequestDto`; runs in authenticated context; returns stream of `EntityContentDto`
- `treeNode.getRawData` — returns raw tree node structure of all entities (diagnostic; no filtering by model, condition, or fields); payload: userId string; returns stream of `RawEntityContentDto`
**DataRequestDto fields:**
- `metaClassId` — UUID — which Entity Model to query
- `path` — string — structural path / `uniformedPath` value of the target table
- `domainCondition` — map of `ColumnCategory` → field key → condition; organized by category (`SPECIAL`, `ROOT`, `INDEX`, `DATA`)
- `expressionCondition` — `GroupConditionDto` — alternative condition format using `AND`/`OR`/`NOT` groups
- `selectedFields` — optional list of value map keys to include; null returns all fields
- `userId` — string — user ID for authenticated context and permission-filtered entity access
Condition pushdown by category:
- `SPECIAL` / `ENTITY_ID` equality — direct entity ID lookup, bypasses full scan
- `SPECIAL` / `POINT_TIME` equality — sets snapshot time for the query (ISO-8601 instant)
- `ROOT` — applied as range conditions on entity-level fields (`creationDate`, `lastUpdateTime`, `state`)
- `INDEX` — applied as in-memory predicates on array index values
- `DATA` — applied as value map conditions, pushed to the storage layer
Data is fetched in pages (default page size: 1000). Point-in-time is derived from the `POINT_TIME` condition; absent means the current committed state.
Point-in-time search uses the canonical inclusive (`<=`, no rounding) bound —
see `cyoda help crud` ("Point-in-time semantics").
**Views (view.*):**
- `view.getViews` — get all views the user can read; payload: userId string; returns stream of `TrinoViewDto`
- `view.addView` — add a view; payload: `TrinoViewDto`; returns null on success, error string on conflict (when `replace=false` and view already exists)
- `view.renameView` — rename a view; payload: `TrinoViewDto` with `newName`; returns null on success, error string on failure
- `view.dropView` — delete a view; payload: `TrinoViewDto`; returns null on success, error string if not found
View identity: composite key of `(schemaName, tableName)`, both automatically lowercased.
**Reports (reports.*):**
- `reports.getReportConfigs` — list saved report configurations (GridConfigs); payload: userId; returns stream of `{id, creationDate}`
- `reports.runReport` — execute a report; payload: `{configId, userId}`; returns reportId string
- `reports.getReportDefinition` — get a saved GridConfig definition; anonymous context
- `reports.getReportHistories` — completed non-failed executions as `Map`; anonymous context
- `reports.getReportStatistics` — all executions as `DistributedReportInfoDto`; anonymous context
- `reports.getReportGroups` — grouping headers for an execution; payload: `{reportId, groupingVersion, userId}`; anonymous context
- `reports.getReportRows` — paginated data rows; payload: `{reportId, groupJsonBase64, startRow, endRow, userId}`; anonymous context
- `reports.deleteReports` — delete report executions; authenticated context
## CATALOG AND SCHEMA LAYOUT
In Trino, cyoda entity data is exposed as tables under the Trino catalog and schema configured by the Trino connector deployment. Table names match `tableName` fields in `TableConfigDto`. Each SQL table corresponds to one `uniformedPath` node in an Entity Model.
A single Entity Model produces multiple tables:
- One object table per object-level node (e.g., root `$`, `$.address`)
- One detached array table per array node (path ending with `^`)
- One JSON table per model (path = `json`)
Querying a table returns one row per entity (object and JSON tables) or one row per array element (detached array tables). The `entity_id` column is the entity UUID. The `point_time` column accepts a point-in-time value for historical queries.
## ERRORS
- `errors.BAD_REQUEST` — `400` — schema name too long (> 1024 chars), UUID is not time-based (version 1)
- `404 Not Found` (RFC 7807) — schema not found by ID or name
- `422 Unprocessable Entity` — default schema generation failed due to duplicate table or field names
## EXAMPLES
**List all schemas:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"https://cloud.cyoda.com/api/sql/schema/listAll"
```
**Get schema by name:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"https://cloud.cyoda.com/api/sql/schema/?schemaName=NOBEL_PRIZES"
```
**Create default schema from all entity models:**
```
curl -s -X PUT \
-H "Authorization: Bearer $TOKEN" \
"https://cloud.cyoda.com/api/sql/schema/putDefault/Nobel_PRIZES"
```
**Preview tables for a model (by model UUID):**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"https://cloud.cyoda.com/api/sql/schema/genTables/a1b2c3d4-e5f6-11ee-b789-0242ac120002"
```
**Save a schema:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"schemaName": "NOBEL_PRIZES",
"tables": [
{
"tableName": "nobel_prize",
"metadataClassId": "a1b2c3d4-e5f6-11ee-b789-0242ac120002",
"uniformedPath": "$",
"fields": [],
"hidden": false
}
]
}' \
"https://cloud.cyoda.com/api/sql/schema/"
```
**Delete a schema by name:**
```
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
"https://cloud.cyoda.com/api/sql/schema/?schemaName=NOBEL_PRIZES"
```
**Trino CLI connection (example; concrete JDBC URL is deployment-specific):**
```
trino --server https://trino.cloud.cyoda.com \
--user "$TRINO_USER" \
--password \
--catalog cyoda \
--schema NOBEL_PRIZES \
--execute "SELECT entity_id, category, year FROM nobel_prize LIMIT 10"
```
## SEE ALSO
- search
- models
- grpc
- errors.BAD_REQUEST
## See also
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
## Raw formats
- [`/help/analytics.json`](/help/analytics.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/analytics.md`](/help/analytics.md) — body only
---
## help/audit.md
# audit — entity audit event API
The audit API exposes a per-entity event log covering entity lifecycle changes (`EntityChange` events) and workflow state-machine progression (`StateMachi…
cyoda-go version 0.8.4
# audit
## NAME
audit — entity audit event API: retrieve change and workflow audit events for a specific entity.
## SYNOPSIS
```
GET /api/audit/entity/{entityId}
GET /api/audit/entity/{entityId}/workflow/{transactionId}/finished
```
Context path prefix is `CYODA_CONTEXT_PATH` (default `/api`). All endpoints require `Authorization: Bearer ` except when `CYODA_IAM_MODE=mock`.
## DESCRIPTION
The audit API exposes a per-entity event log covering entity lifecycle changes (`EntityChange` events) and workflow state-machine progression (`StateMachine` events). Events are returned newest-first and support cursor-based pagination.
A third event type, `System`, is reserved for commercial backends. OSS backends never emit `System` events; the enum value is retained in the contract for wire compatibility with Cyoda Cloud.
## ENDPOINTS
**GET /api/audit/entity/{entityId}** — Search audit events for an entity
- `entityId` (path): UUID — the entity to query
Query parameters (all optional):
- `eventType`: multi-value filter. Accepted values: `StateMachine`, `EntityChange`, `System`. When omitted, defaults to all types except `System`. **`System` events are excluded from the default set. Including them may increase latency and load — use with caution.**
- `severity`: `ERROR`, `INFO`, `WARN`, or `DEBUG`
- `fromUtcTime`: RFC 3339 date-time — include events at or after this time (inclusive)
- `toUtcTime`: RFC 3339 date-time — include events before this time (exclusive)
- `transactionId`: UUID — filter to a single transaction
- `cursor`: opaque string — pass `nextCursor` from the previous response to fetch the next page; omit for the first page
- `limit`: string-encoded integer, 1–1000 (default 20; values above 1000 are clamped to 1000)
Response: `200 OK`, `application/json` — `EntityAuditEventsResponseDto`:
```json
{
"pagination": {
"hasNext": true,
"nextCursor": "20"
},
"items": [
{
"auditEventType": "EntityChange",
"changeType": "UPDATE",
"severity": "INFO",
"utcTime": "2025-08-01T10:05:00.000000000Z",
"microsTime": 1754042700000000,
"entityId": "74807f00-ed0d-11ee-a357-ae468cd3ed16",
"transactionId": "9f1a2b3c-ed0e-11ee-a357-ae468cd3ed16"
},
{
"auditEventType": "StateMachine",
"eventType": "STATE_MACHINE_FINISH",
"severity": "INFO",
"utcTime": "2025-08-01T10:04:55.000000000Z",
"microsTime": 1754042695000000,
"entityId": "74807f00-ed0d-11ee-a357-ae468cd3ed16",
"state": "APPROVED",
"data": {"success": true}
}
]
}
```
**EntityChangeAuditEventDto** fields (discriminated by `auditEventType: "EntityChange"`):
- `changeType`: `"CREATE"`, `"UPDATE"`, or `"DELETE"` — the type of entity change
- `changes`: before/after diff — **not yet emitted by the server (deferred gap)**; the field is declared in the OpenAPI schema but the server currently omits it from all responses. Do not rely on `changes` being present.
- `severity`, `utcTime`, `microsTime`, `entityId`, `transactionId`, `actor` — plus `entityModel`, `consistencyTime`, `details`, `system` — inherited from `AuditEventDto` (see the `openapi` topic for the full schema)
**StateMachineAuditEventDto** fields (discriminated by `auditEventType: "StateMachine"`):
- `eventType`: one of `STATE_MACHINE_START`, `STATE_MACHINE_FINISH`, `CANCEL`, `FORCE_SUCCESS`, `WORKFLOW_FOUND`, `WORKFLOW_NOT_FOUND`, `WORKFLOW_SKIP`, `TRANSITION_MAKE`, `TRANSITION_NOT_FOUND`, `TRANSITION_NOT_MATCH_CRITERION`, `TRANSITION_ABORTED`, `PROCESS_NOT_MATCH_CRITERION`, `PAUSE_FOR_PROCESSING`, `STATE_PROCESS_RESULT`
- `state`: entity state at the time of the event
- `data`: optional event-specific payload (e.g. `{"success": true}` for `STATE_MACHINE_FINISH`; null for most event types). `TRANSITION_ABORTED` carries `{reason, transitionName, expectedTxId, actualTxId}`.
**GET /api/audit/entity/{entityId}/workflow/{transactionId}/finished** — Get workflow finished event
Retrieves the `STATE_MACHINE_FINISH` audit event for a specific entity and transaction. Provides direct access to the workflow outcome without scanning all audit events.
- `entityId` (path): UUID
- `transactionId` (path): UUID
Response: `200 OK`, `application/json` — `StateMachineAuditEventDto` (the finish event for the transaction).
Returns `404` with `ProblemDetail` (`application/problem+json`) when the entity or finished event is not found.
## ERRORS
- `errors.ENTITY_NOT_FOUND` — `404` — entity does not exist, or no events found for the given entity/transaction
- `errors.BAD_REQUEST` — `400` — `limit` parameter is not a valid integer or is less than 1
## EXAMPLES
**Fetch the 20 most recent audit events for an entity:**
```
curl -s \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/audit/entity/$ENTITY_ID"
```
**Filter to EntityChange events only:**
```
curl -s \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/audit/entity/$ENTITY_ID?eventType=EntityChange"
```
**Filter to a specific transaction:**
```
curl -s \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/audit/entity/$ENTITY_ID?transactionId=$TX_ID"
```
**Paginate using a cursor:**
```
NEXT=$(curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/audit/entity/$ENTITY_ID?limit=10" \
| jq -r '.pagination.nextCursor')
curl -s \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/audit/entity/$ENTITY_ID?limit=10&cursor=$NEXT"
```
**Get the workflow finished event for a transaction:**
```
curl -s \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/audit/entity/$ENTITY_ID/workflow/$TX_ID/finished"
```
## SEE ALSO
- crud
- search
- models
- errors.ENTITY_NOT_FOUND
- errors.BAD_REQUEST
- openapi
## See also
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help errors ENTITY_NOT_FOUND`](/help/errors/entity_not_found/) — No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
## Raw formats
- [`/help/audit.json`](/help/audit.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/audit.md`](/help/audit.md) — body only
---
## help/auth.md
# auth — authenticate client applications against cyoda
auth — authenticate client applications against cyoda.
cyoda-go version 0.8.4
# auth
## NAME
auth — authenticate client applications against cyoda.
## GOAL
Every cyoda API call needs an `Authorization: Bearer ` header. This page helps you decide how to get that JWT.
## WHICH PATH DO I NEED?
- **You have a `client_id`/`secret` you'll manage in cyoda** — use the M2M client + token endpoint. Read `auth.clients` then `auth.tokens`.
- **You have an existing IdP (Cognito, Keycloak, Auth0, …)** — federate via OIDC. Read `auth.oidc`.
- **You have a key you sign tokens with yourself, no IdP** — register a trusted key. Read `auth.trusted-keys`.
- **You have an M2M client acting on behalf of a user** — use the token-exchange grant. Read the OBO section of `auth.tokens`.
**Looking for OBO?** The token-exchange (on-behalf-of) grant is documented as a section of `auth.tokens` — there is no separate `auth.obo` page. Run `cyoda help auth tokens` and read the token-exchange section.
**Looking for env vars?** All `CYODA_OIDC_*`, `CYODA_IAM_*`, `CYODA_JWT_*`, `CYODA_HMAC_*`, and `CYODA_BOOTSTRAP_*` knobs live in `config.auth`. Run `cyoda help config auth`.
## TOKEN PRESENTATION
All cyoda APIs accept the JWT via `Authorization: Bearer `. The token claim shape — `sub`, `iss`, `caas_org_id`, `caas_user_id`, `user_roles`, `caas_tier`, `exp`, `iat`, `jti`, optionally `act` — is documented in `auth.tokens`.
## SEE ALSO
- `config.auth` — env-var reference for every auth knob
- `openapi` — run `cyoda help openapi tags` for spec by tag, including OAuth and OIDC
- `errors.UNAUTHORIZED`, `errors.FORBIDDEN` — universal auth-failure codes
## Subtopics
- [`cyoda help auth clients`](/help/auth/clients/) — auth.clients — provision and manage machine-to-machine (M2M) clients that authenticate against cyoda via the `client_credentials` grant.
- [`cyoda help auth oidc`](/help/auth/oidc/) — auth.oidc — register an external OIDC identity provider so JWTs it issues are accepted by cyoda directly, without re-minting at `/oauth/token`.
- [`cyoda help auth tokens`](/help/auth/tokens/) — auth.tokens — exchange credentials for a JWT at `POST /api/oauth/token`. Covers every supported grant and the canonical JWT claim contract that all cyoda tokens (M2M, OBO, federated OIDC, trusted-key) conform to.
- [`cyoda help auth trusted-keys`](/help/auth/trusted-keys/) — auth.trusted-keys — register a public key with cyoda so JWTs you sign offline with the matching private key are accepted, without an IdP or `/oauth/token` round-trip.
## See also
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
## Raw formats
- [`/help/auth.json`](/help/auth.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/auth.md`](/help/auth.md) — body only
---
## help/auth/clients.md
# auth.clients — M2M client lifecycle
auth.clients — provision and manage machine-to-machine (M2M) clients that authenticate against cyoda via the `client_credentials` grant.
cyoda-go version 0.8.4
# auth.clients
## NAME
auth.clients — provision and manage machine-to-machine (M2M) clients that authenticate against cyoda via the `client_credentials` grant.
## GOAL
You want a backend service or CI job to call cyoda APIs. Register an M2M client to obtain a `client_id` + `client_secret`. Your service then mints JWTs via `POST /api/oauth/token` (documented in `auth.tokens`) and presents them as `Authorization: Bearer …` on every request.
Use this path when you control both the service and its cyoda registration. For user-facing flows, federate via `auth.oidc` instead.
## PREREQUISITES
**Admin (cyoda operator) sets up:**
- `CYODA_IAM_MODE=jwt` (mock mode bypasses auth entirely — fine for dev, never for prod)
- `CYODA_JWT_SIGNING_KEY` (PEM RSA key; `_FILE` suffix supported)
- Optionally: `CYODA_BOOTSTRAP_CLIENT_ID` + `CYODA_BOOTSTRAP_CLIENT_SECRET` provisions a single admin M2M at startup, useful for CI. See `config.auth`.
- For admin-scoped M2M creation (`withAdminRole=true`): `CYODA_IAM_M2M_ADMIN_ROLE_ENABLED=true`. Off by default; when off, the `withAdminRole=true` request shape returns `404 FEATURE_DISABLED`.
**Client (you) needs:**
- An `Authorization: Bearer …` token with `ROLE_ADMIN`. Every `/clients` endpoint (list, create, delete, reset-secret) requires admin role today.
- The created client is scoped to the caller's tenant — there is no per-request tenant parameter on these endpoints.
## REQUEST FLOW
The 4 `/clients` operations: provision, list, delete, reset-secret. Field names follow RFC 7591 (snake_case) for the credentials DTOs; list-item DTOs use cyoda's customary camelCase.
### Provision a client
The request takes no body. `withAdminRole` is a query parameter; the only role the new client receives unconditionally is `ROLE_M2M`, and `ROLE_ADMIN` is added when `withAdminRole=true` AND the IAM feature is enabled.
```bash
curl -X POST "https://cyoda.example.com/api/clients?withAdminRole=false" \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
Response (`200 OK`) — schema `TechnicalUserCredentialsDto`:
```json
{
"client_id": "abc523BCD",
"client_secret": "mySecretKey123",
"grant_type": "client_credentials",
"client_secret_expires_at": 0,
"roles": ["ROLE_M2M"]
}
```
**`client_secret` is shown only at creation time.** Capture it now; the server cannot return it again. `client_secret_expires_at = 0` means the secret does not expire (per RFC 7591 §3.2.1).
### List clients in the caller's tenant
```bash
curl -X GET https://cyoda.example.com/api/clients \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
Response (`200 OK`) — array of `TechnicalUserDto` (no secrets):
```json
[
{
"clientId": "abc523BCD",
"creationDate": "2026-06-17T10:02:27.88Z",
"lastUpdateDate": "2026-06-17T10:02:27.88Z",
"roles": ["ROLE_M2M"]
}
]
```
### Delete a client
```bash
curl -X DELETE https://cyoda.example.com/api/clients/${CLIENT_ID} \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
Response (`200 OK`):
```json
{
"message": "M2M client deleted successfully",
"clientId": "abc523BCD"
}
```
The deleted client's tokens remain valid until their natural `exp`; deletion stops new token issuance.
### Reset a client secret
Rotates `client_secret` for an existing client. The verb is `PUT`, not `POST`.
```bash
curl -X PUT https://cyoda.example.com/api/clients/${CLIENT_ID}/secret \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
Response (`200 OK`) is `TechnicalUserCredentialsDto` — same shape as creation, carrying the new `client_secret`. Capture it before the connection closes. Existing JWTs minted with the previous secret remain valid until their natural `exp`; only new `/oauth/token` requests need the new secret.
## TOKEN
Clients are not tokens. After provisioning, the client uses `auth.tokens` (the `/oauth/token` endpoint) to mint JWTs from the `client_id` + `client_secret`. The JWT carries the client's tenant in `caas_org_id` and its roles in `user_roles`. Full claim shape is in `auth.tokens`.
## ERRORS
- `errors.UNAUTHORIZED` (`401`) — bearer token missing, expired, signature invalid, or issuer untrusted.
- `errors.FORBIDDEN` (`403`) — caller lacks `ROLE_ADMIN` (required for every `/clients` endpoint today).
- `errors.M2M_CLIENT_NOT_FOUND` (`404`) — referenced `clientId` does not exist or belongs to a different tenant.
- `errors.FEATURE_DISABLED` (`404`) — `withAdminRole=true` requested with `CYODA_IAM_M2M_ADMIN_ROLE_ENABLED=false`.
- `errors.BAD_REQUEST` (`400`) — query-string parameter invalid (e.g. malformed `withAdminRole` value).
## SEE ALSO
- `auth.tokens` — the `/oauth/token` endpoint and JWT claim contract
- `config.auth` — `CYODA_BOOTSTRAP_*`, `CYODA_IAM_M2M_ADMIN_ROLE_ENABLED`
- `openapi` — `cyoda help openapi tags` and look for the `User, Machine` tag
## See also
- [`cyoda help auth`](/help/auth/) — auth — authenticate client applications against cyoda.
- [`cyoda help auth tokens`](/help/auth/tokens/) — auth.tokens — exchange credentials for a JWT at `POST /api/oauth/token`. Covers every supported grant and the canonical JWT claim contract that all cyoda tokens (M2M, OBO, federated OIDC, trusted-key) conform to.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help errors M2M_CLIENT_NOT_FOUND`](/help/errors/m2m_client_not_found/) — Returned by `/clients` admin endpoints when the supplied `clientId` does not match any registered M2M client in the caller's tenant:
- [`cyoda help errors FEATURE_DISABLED`](/help/errors/feature_disabled/) — Returned by trusted-key endpoints when `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=false` (the default):
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
## Raw formats
- [`/help/auth/clients.json`](/help/auth/clients.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/auth/clients.md`](/help/auth/clients.md) — body only
---
## help/auth/oidc.md
# auth.oidc — federated OIDC providers
auth.oidc — register an external OIDC identity provider so JWTs it issues are accepted by cyoda directly, without re-minting at `/oauth/token`.
cyoda-go version 0.8.4
# auth.oidc
## NAME
auth.oidc — register an external OIDC identity provider so JWTs it issues are accepted by cyoda directly, without re-minting at `/oauth/token`.
## GOAL
You already have an OIDC IdP — Cognito, Keycloak, Auth0, Okta, your own — and you want clients to present that IdP's JWTs to cyoda. Register the provider once; cyoda fetches its JWKS, validates inbound tokens against the keys, maps roles from the configured claim, and binds the resulting identity to a tenant.
Use this path when the IdP is the source of truth for user accounts. For pure M2M, `auth.clients` + `auth.tokens` is simpler.
## PREREQUISITES
**Admin (cyoda operator) sets up:**
- `CYODA_IAM_MODE=jwt` (federated OIDC is unavailable in mock mode).
- `CYODA_OIDC_REQUIRE_HTTPS=true` for production. Set to `false` only for dev IdPs over plain HTTP.
- `CYODA_OIDC_ALLOW_PRIVATE_NETWORKS=false` for production. Setting to `true` disables the SSRF blocklist that prevents `wellKnownConfigUri` resolving to RFC 1918 / loopback / link-local addresses.
- `CYODA_OIDC_ROLES_CLAIM` (default `roles`) — global default JWT claim from which roles are read. Per-provider override available at registration.
- `CYODA_OIDC_CONNECT_TIMEOUT_MS`, `CYODA_OIDC_SOCKET_TIMEOUT_MS`, `CYODA_OIDC_CONNECTION_REQUEST_TIMEOUT_MS` (each default `5000`) — HTTP timeouts for discovery + JWKS fetches.
**Client (you) needs:**
- A working `.well-known/openid-configuration` URL on the IdP.
- A `ROLE_ADMIN` cyoda token to register the provider.
- A **UUID-shaped tenant ID** — the bootstrap convenience literal `default-tenant` is rejected by registration (returns `OIDC_INVALID_TENANT`) because non-UUID tenant identifiers collide in storage.
## REQUEST FLOW
### Register a provider
```bash
curl -X POST https://cyoda.example.com/api/oauth/oidc/providers \
-H "Authorization: Bearer ${ADMIN_TOKEN}" \
-H "Content-Type: application/json" \
-d '{
"wellKnownConfigUri": "https://idp.example.com/.well-known/openid-configuration",
"issuers": ["https://idp.example.com/"],
"expectedAudiences": ["cyoda-prod"],
"rolesClaim": "cognito:groups"
}'
```
Response (`200 OK`) carries the full provider DTO:
```json
{
"id": "f47ac10b-58cc-…",
"wellKnownConfigUri": "https://idp.example.com/.well-known/openid-configuration",
"active": true,
"createdAt": "2026-06-17T12:00:00Z",
"issuers": ["https://idp.example.com/"],
"expectedAudiences": ["cyoda-prod"],
"rolesClaim": "cognito:groups"
}
```
Registration succeeds even when the IdP's discovery / JWKS endpoints are unreachable — cyoda warms them asynchronously after the response and retries failed warm-ups every 30 seconds until the IdP becomes reachable. Tokens issued by an un-warmed provider fail with `401 UNAUTHORIZED` until a warm-up succeeds (or an explicit `/reload`). See **DIAGNOSTICS** below for the operator path.
Behaviour on `expectedAudiences`:
- Omitted, `null`, or empty array → no `aud` enforcement (issuer-binding is the trust anchor).
- Non-empty → inbound JWT `aud` claim must match at least one entry byte-wise.
Behaviour on `issuers`:
- Omitted, `null`, or empty → cyoda enforces the `iss` claim matches the discovery document's `issuer` field byte-wise (OIDC Core 1.0 §2).
- Non-empty → inbound JWT `iss` must match one of the listed values byte-wise.
### List providers
```bash
curl -X GET "https://cyoda.example.com/api/oauth/oidc/providers?activeOnly=true" \
-H "Authorization: Bearer ${TOKEN}"
```
`activeOnly=true` filters out invalidated providers. Available to any authenticated tenant member, not just admin.
### Update a provider (tri-state PATCH)
```bash
curl -X PATCH https://cyoda.example.com/api/oauth/oidc/providers/${PROVIDER_ID} \
-H "Authorization: Bearer ${ADMIN_TOKEN}" \
-H "Content-Type: application/json" \
-d '{
"expectedAudiences": ["cyoda-prod", "cyoda-staging"]
}'
```
Per-field tri-state semantics: absent = unchanged, `null` or `[]` = clear, value = set. Same for `issuers` and `rolesClaim`.
### Invalidate / reactivate / delete
```bash
# Invalidate — token validation stops accepting this provider's JWTs immediately.
curl -X POST https://cyoda.example.com/api/oauth/oidc/providers/${PROVIDER_ID}/invalidate \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
# Reactivate — by default refreshes JWKS from upstream.
curl -X POST https://cyoda.example.com/api/oauth/oidc/providers/${PROVIDER_ID}/reactivate \
-H "Authorization: Bearer ${ADMIN_TOKEN}" \
-H "Content-Type: application/json" \
-d '{"reactivateKeys": true}'
# Delete permanently.
curl -X DELETE https://cyoda.example.com/api/oauth/oidc/providers/${PROVIDER_ID} \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
### Reload JWKS for all providers
```bash
curl -X POST https://cyoda.example.com/api/oauth/oidc/providers/reload \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
Forces an immediate JWKS refresh for every active provider on the receiving node. In a multi-node cluster the reload is broadcast. A provider whose discovery fetch fails during the refresh keeps its previously cached keys (freshness remains subject to the standard JWKS cache TTL).
### Present an IdP-issued JWT
Once registered, clients present the IdP's JWT directly:
```bash
curl -X GET https://cyoda.example.com/api/clients \
-H "Authorization: Bearer ${IDP_ISSUED_JWT}"
```
The token is validated against the provider's JWKS; roles are read from the configured `rolesClaim`; identity is bound to the tenant that registered the provider.
## TOKEN
JWTs issued by the federated IdP must conform to the universal cyoda claim contract documented in `auth.tokens`. In particular:
- `iss` must match per the `issuers` / discovery-document rule above.
- `aud` must match `expectedAudiences` if set.
- The configured `rolesClaim` (per-provider override or `CYODA_OIDC_ROLES_CLAIM`) is looked up as a literal **top-level** JWT claim name. The value at that key may be any of:
1. **JSON array of strings** — `["admin","warehouse"]` → used as-is.
2. **JSON object** — `{ "admin": {…}, "warehouse": {…} }` → roles are the **top-level keys** (`["admin","warehouse"]`); inner values are ignored. This is the shape Zitadel emits for `urn:zitadel:iam:org:project:roles` with `projectRoleAssertion=true`.
3. **String** — `"admin warehouse"` → split on whitespace per RFC 6749 §3.3 / RFC 8693 §4.2; a lone token `"admin"` yields one role.
Empty / absent / non-collection scalar (number, bool) → no roles, no error (the user is authenticated but unprivileged). Role names containing a comma are dropped silently (cyoda comma-joins roles for downstream serialisation; no major IdP emits commas in role names by convention).
Common per-IdP values for `rolesClaim`:
```text
IdP rolesClaim value
------------------------------- -----------------------------------------------
Default (no override) roles
Amazon Cognito cognito:groups
Zitadel (project-wide) urn:zitadel:iam:org:project:roles
Zitadel (per-project) urn:zitadel:iam:org:project::roles
Auth0 (namespaced custom claim) https://your-app.example.com/roles
```
Note: there is no path/dot-walking syntax — whatever string you configure is used as a single literal claim-key lookup against the JWT, so colons, slashes, and dots inside the value are treated as part of the key name (which is exactly what Zitadel, Cognito, and Auth0 need).
Keycloak's default `realm_access.roles` lives one level deep inside the `realm_access` object, which the no-dot-walking rule means cyoda cannot reach. Configure a Keycloak token mapper (hardcoded-claim or role-list, at realm or client scope) to flatten the role list to a top-level `roles` claim, then point `rolesClaim` at that top-level key.
Cyoda does not re-mint federated tokens — they are validated and trusted directly.
## DIAGNOSTICS
**Every token-validation failure surfaces as `401 UNAUTHORIZED` with a uniform problem-detail body. No precise error code distinguishes audience mismatch, expired token, unknown `kid`, JWKS-unreachable, claims-invalid, or ambiguous-tenant routing.** A precise wire code would enumerate IdP / tenant / kid / claim-shape recognition to an unauthenticated caller, so the wire stays uniform by design.
The diagnostic path for every failure mode is **server-side logs**, not the HTTP response. Look at `oidc.registry` (KID resolution), `oidc.validator` (claims + signature), and `oidc.discovery` / `oidc.jwks` (transport) events. The bearer-auth middleware emits one structured WARN per failed request with the failure reason slug.
Symptom → cause map for the common cases:
- **"I get 401 but my token looks valid":** check `oidc.registry` resolve logs. The most common cause is the provider's JWKS hasn't warmed yet (registration succeeds before discovery completes); force-warm via `/oauth/oidc/providers/reload`, or wait for the automatic warm-up retry (every 30 seconds).
- **"After re-registering, valid tokens are rejected":** the second-most-common case — two tenants registered the same IdP with overlapping or empty `expectedAudiences`. Internally `ErrAmbiguousProvider` (`internal/auth/oidc/registry.go`) wraps to `ErrUnknownKID`. To resolve, pick disjoint `expectedAudiences` per tenant.
- **"Tokens reject for the right tenant but the IdP is up":** verify the JWT `iss` claim matches either an explicit `issuers` entry or the discovery document's `issuer` byte-for-byte. Trailing slashes count.
Registration-time failures (these DO carry precise codes — see ERRORS) are SSRF, duplicate URI per tenant, malformed tenant UUID, and provider-not-found / invalid-state for lifecycle ops. Registration succeeds even when the IdP itself is unreachable — discovery failures don't fail the response; they delay the warmup.
## ERRORS
Registration / lifecycle (precise codes — admin-facing surface):
- `errors.OIDC_INVALID_TENANT` (`400`) — caller's tenant ID is not UUID-shaped (commonly: bootstrap `default-tenant` literal).
- `errors.OIDC_SSRF_BLOCKED` (`400`) — `wellKnownConfigUri` resolves to a blocked address range (set `CYODA_OIDC_ALLOW_PRIVATE_NETWORKS=true` for dev).
- `errors.OIDC_PROVIDER_DUPLICATE` (`409`) — same `wellKnownConfigUri` already registered for this tenant.
- `errors.OIDC_PROVIDER_NOT_FOUND` (`404`) — referenced provider ID absent in this tenant.
- `errors.OIDC_PROVIDER_INACTIVE` (`409`) — update or operation attempted on an invalidated provider; reactivate first.
Token validation (always opaque — see DIAGNOSTICS):
- `errors.UNAUTHORIZED` (`401`) — every token-validation failure path. The wire body never distinguishes audience mismatch, expired token, unknown `kid`, JWKS-unreachable, claims-invalid, or ambiguous-tenant routing.
## SEE ALSO
- `auth.tokens` — universal claim contract
- `config.auth` — `CYODA_OIDC_*` env vars
- `openapi` — `cyoda help openapi tags` and look for `OAuth, OIDC Providers`
## See also
- [`cyoda help auth`](/help/auth/) — auth — authenticate client applications against cyoda.
- [`cyoda help auth tokens`](/help/auth/tokens/) — auth.tokens — exchange credentials for a JWT at `POST /api/oauth/token`. Covers every supported grant and the canonical JWT claim contract that all cyoda tokens (M2M, OBO, federated OIDC, trusted-key) conform to.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help errors OIDC_INVALID_TENANT`](/help/errors/oidc_invalid_tenant/) — cyoda treats legal entity identifiers as UUIDs. OIDC provider ownership is
recorded as a `uuid.UUID` `OwnerLegalEntityID` field, which keys both the
per-tenant KV blob storage and the validated user-context tenant binding at
token validation time.
- [`cyoda help errors OIDC_PROVIDER_DUPLICATE`](/help/errors/oidc_provider_duplicate/) — Each tenant may register a given `wellKnownConfigUri` only once. Submitting
`POST /oauth/oidc/providers` with a URI that is already registered for the
caller's tenant returns this error.
- [`cyoda help errors OIDC_PROVIDER_NOT_FOUND`](/help/errors/oidc_provider_not_found/) — The provider UUID supplied in the path parameter does not correspond to a
registered OIDC provider for the caller's tenant. Either the provider was
never registered, was deleted, or the UUID belongs to a different tenant
(cross-tenant existence is not disclosed).
- [`cyoda help errors OIDC_PROVIDER_INACTIVE`](/help/errors/oidc_provider_inactive/) — `PATCH /oauth/oidc/providers/{id}` requires the provider to be in the active
state. If the provider has been invalidated via
`POST /oauth/oidc/providers/{id}/invalidate`, this error is returned.
- [`cyoda help errors OIDC_SSRF_BLOCKED`](/help/errors/oidc_ssrf_blocked/) — When registering an OIDC provider, cyoda validates the `wellKnownConfigUri`
against a blocklist of private address ranges (loopback, RFC1918, link-local,
IPv6 ULA). If the URI's hostname resolves to any blocked range, the
registration is rejected to prevent Server-Side Request Forgery attacks.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
## Raw formats
- [`/help/auth/oidc.json`](/help/auth/oidc.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/auth/oidc.md`](/help/auth/oidc.md) — body only
---
## help/auth/tokens.md
# auth.tokens — /oauth/token grants and JWT claim contract
auth.tokens — exchange credentials for a JWT at `POST /api/oauth/token`. Covers every supported grant and the canonical JWT claim contract that all cyoda …
cyoda-go version 0.8.4
# auth.tokens
## NAME
auth.tokens — exchange credentials for a JWT at `POST /api/oauth/token`. Covers every supported grant and the canonical JWT claim contract that all cyoda tokens (M2M, OBO, federated OIDC, trusted-key) conform to.
## GOAL
You have a way to prove identity (an M2M `client_id`/`secret`, or a JWT minted by a federated IdP, or a JWT you signed offline) and you want a cyoda-issued (or cyoda-validated) JWT to present on subsequent API calls.
This is the single home for the JWT claim contract. `auth.oidc` and `auth.trusted-keys` link here for claim shape.
## PREREQUISITES
**Admin (cyoda operator) sets up:**
- `CYODA_IAM_MODE=jwt`
- `CYODA_JWT_SIGNING_KEY` (PEM RSA private key; tokens cyoda issues are signed with this)
- `CYODA_JWT_ISSUER` (default `cyoda`; populates the `iss` claim)
- `CYODA_JWT_AUDIENCE` (default empty = no `aud` check on inbound tokens)
- `CYODA_JWT_EXPIRY_SECONDS` (default `3600`)
- `CYODA_JWT_BOOTSTRAP_AUDIENCE` (default `client`; controls which key signs M2M tokens)
See `config.auth` for the full env-var reference.
**Client (you) needs:**
- For `client_credentials`: a registered M2M `client_id`/`secret` (see `auth.clients`).
- For token-exchange (OBO): an already-valid subject JWT plus an M2M `client_id`/`secret` to act as the actor.
## REQUEST FLOW
### client_credentials — most common
Mint an M2M JWT with your client credentials:
```bash
curl -X POST https://cyoda.example.com/api/oauth/token \
-u "${CLIENT_ID}:${CLIENT_SECRET}" \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "grant_type=client_credentials"
```
Response (`200 OK`):
```json
{
"access_token": "eyJhbGciOiJSUzI1NiIs…",
"token_type": "Bearer",
"expires_in": 3600
}
```
Use the `access_token` as `Authorization: Bearer …` on every subsequent API call. Mint again when it nears `exp`; cyoda does not issue refresh tokens.
### token-exchange (OBO)
You are an M2M actor (e.g. a backend service) and you want to call cyoda **on behalf of a user** whose token you already hold. The OBO grant re-signs the subject token so cyoda sees the user as the principal and your service as the actor (RFC 8693).
```bash
curl -X POST https://cyoda.example.com/api/oauth/token \
-u "${CLIENT_ID}:${CLIENT_SECRET}" \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "grant_type=urn:ietf:params:oauth:grant-type:token-exchange" \
-d "subject_token=${USER_TOKEN}" \
-d "subject_token_type=urn:ietf:params:oauth:token-type:jwt"
```
Response shape matches `client_credentials` plus a `issued_token_type` field:
```json
{
"access_token": "eyJhbGciOiJSUzI1NiIs…",
"token_type": "Bearer",
"expires_in": 3600,
"issued_token_type": "urn:ietf:params:oauth:token-type:jwt"
}
```
Key constraints:
- The subject token's `caas_org_id` must match the M2M client's tenant. Tenant mismatch → `403 access_denied`.
- The issued OBO token carries `sub` = the subject's `sub`, `user_roles` from the subject token, and an `act` claim `{"sub": ""}` identifying the actor.
- Subject token must already be valid (signature, not expired).
## TOKEN
**Cyoda-minted tokens** (issued via `client_credentials` or token-exchange/OBO at `/oauth/token`, or via the bootstrap key in `auth.trusted-keys`) carry the following claim shape. **Federated OIDC tokens** (`auth.oidc`) are *not* re-minted; they carry the upstream IdP's claim shape, and tenant + user identity are bound server-side from the registered provider's `OwnerLegalEntityID` — claims like `caas_org_id`, `caas_user_id`, `tid` on a federated token are explicitly ignored to prevent attacker-controlled tenant routing.
Claim shape for cyoda-minted tokens:
- `sub` (string) — Principal. `client_id` for M2M, user ID for OBO and federated tokens.
- `iss` (string) — Issuer. Cyoda-minted tokens use `CYODA_JWT_ISSUER`. Federated tokens use the upstream IdP's issuer.
- `aud` (string or string array) — Audience. Checked against `CYODA_JWT_AUDIENCE` if set; against `expectedAudiences` for federated providers.
- `exp` (int unix) — Expiry.
- `iat` (int unix) — Issued-at.
- `jti` (string UUID) — Unique token ID.
- `caas_org_id` (string UUID) — Tenant scope. Every API call is constrained to this tenant.
- `caas_user_id` (string) — User identifier. For M2M tokens this duplicates `sub` (= `client_id`).
- `user_roles` (string array) — Roles granted (e.g. `ROLE_ADMIN`, `ROLE_M2M`). Federated OIDC tokens carry roles from the provider's configured `rolesClaim` (default `roles`; per-provider override available — see `auth.oidc`).
- `caas_tier` (string) — Tier label. cyoda-go: always `"unlimited"`; Cloud distinguishes paid tiers.
- `act` (object) — **OBO only.** `{"sub": ""}` identifying the M2M actor that exchanged the user token. Absent on `client_credentials` tokens.
Cyoda issues tokens signed with `CYODA_JWT_SIGNING_KEY` (RS256). The `kid` header points at the active keypair in the keystore (`/oauth/keys/*`). Federated OIDC tokens are validated against the registered provider's JWKS — never signed by cyoda. Trusted-key tokens are signed by you (offline) with the matching private key for a registered public key.
## ERRORS
- `errors.UNAUTHORIZED` (`401`) — `Authorization` header missing, token expired, signature invalid, issuer untrusted, or `kid` not in any registered keystore / OIDC JWKS / trusted-key registry.
- `errors.FORBIDDEN` (`403`) — token valid but caller lacks the required role for the operation.
- `errors.BAD_REQUEST` (`400`) — malformed `grant_type`, missing form fields, invalid `subject_token` shape.
- The `/oauth/token` endpoint returns OAuth-shaped errors (`{"error": "...", "error_description": "..."}`) per RFC 6749 rather than the generic cyoda error envelope — `invalid_client`, `invalid_grant`, `access_denied`, `server_error`.
## SEE ALSO
- `auth.clients` — provision the M2M client used by `client_credentials` and OBO
- `auth.oidc` — federate an external IdP whose JWTs cyoda will accept directly
- `auth.trusted-keys` — register a public key so JWTs you sign offline are accepted
- `config.auth` — `CYODA_JWT_*`, `CYODA_BOOTSTRAP_*`
- `openapi` — `cyoda help openapi tags` and look for the `IAM` tag
## See also
- [`cyoda help auth`](/help/auth/) — auth — authenticate client applications against cyoda.
- [`cyoda help auth clients`](/help/auth/clients/) — auth.clients — provision and manage machine-to-machine (M2M) clients that authenticate against cyoda via the `client_credentials` grant.
- [`cyoda help auth oidc`](/help/auth/oidc/) — auth.oidc — register an external OIDC identity provider so JWTs it issues are accepted by cyoda directly, without re-minting at `/oauth/token`.
- [`cyoda help auth trusted-keys`](/help/auth/trusted-keys/) — auth.trusted-keys — register a public key with cyoda so JWTs you sign offline with the matching private key are accepted, without an IdP or `/oauth/token` round-trip.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
## Raw formats
- [`/help/auth/tokens.json`](/help/auth/tokens.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/auth/tokens.md`](/help/auth/tokens.md) — body only
---
## help/auth/trusted-keys.md
# auth.trusted-keys — register public keys for offline JWT signing
auth.trusted-keys — register a public key with cyoda so JWTs you sign offline with the matching private key are accepted, without an IdP or `/oauth/token`…
cyoda-go version 0.8.4
# auth.trusted-keys
## NAME
auth.trusted-keys — register a public key with cyoda so JWTs you sign offline with the matching private key are accepted, without an IdP or `/oauth/token` round-trip.
## GOAL
You have a workload that can sign JWTs (a CI job, a controller, an air-gapped service) and you don't want to depend on cyoda being reachable for token minting or an external IdP for discovery. Register the public key once; thereafter your workload signs JWTs locally and cyoda validates them by `kid` lookup against the registry.
Use this path when token minting must work even when cyoda's `/oauth/token` is unreachable, or when you want zero IdP infrastructure.
**Feature flag.** The 5 trusted-key endpoints under `/oauth/keys/trusted/*` are **off by default**. The operator must set `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=true` to enable them; otherwise every endpoint returns `404 FEATURE_DISABLED`. This is intentional — trusted keys move the trust boundary, and that posture should be explicit.
## PREREQUISITES
**Admin (cyoda operator) sets up:**
- `CYODA_IAM_MODE=jwt`.
- `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=true` (gate; see callout above).
- `CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT` (default `10`) — per-tenant cap on currently-valid trusted keys. Counts active + within-validity entries only.
- `CYODA_IAM_TRUSTED_KEY_MAX_VALIDITY_DAYS` (default `365`) — default validity for trusted keys when not specified at registration.
**Client (you) needs:**
- A keypair you generated yourself. cyoda-go v0.8.0 supports `kty: "RSA"` only. Cloud also supports `kty: "EC"` and `kty: "OKP"`; cyoda-go parity is tracked for a future release.
- A `ROLE_ADMIN` cyoda token to register / delete / lifecycle the entry.
## REQUEST FLOW
### Register a public key
```bash
# Generate a keypair locally
openssl genrsa -out signing.pem 2048
openssl rsa -in signing.pem -pubout -out signing.pub
# Convert the public key to JWK shape — your tooling of choice;
# the API expects the JWK members at the top level.
curl -X POST https://cyoda.example.com/api/oauth/keys/trusted \
-H "Authorization: Bearer ${ADMIN_TOKEN}" \
-H "Content-Type: application/json" \
-d '{
"keyId": "my-signing-key-2026-06",
"kty": "RSA",
"n": "",
"e": "AQAB"
}'
```
Response (`200 OK`) echoes the registered key shape plus lifecycle metadata.
Pick a stable, descriptive `keyId`. It becomes the JWT `kid` header you must set when signing.
### List trusted keys
```bash
curl -X GET https://cyoda.example.com/api/oauth/keys/trusted \
-H "Authorization: Bearer ${TOKEN}"
```
Returns the tenant's keys with status (active / invalidated) and validity window.
### Invalidate / reactivate
```bash
# Stop accepting tokens signed with this key, without removing the entry.
curl -X POST https://cyoda.example.com/api/oauth/keys/trusted/${KEY_ID}/invalidate \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
# Re-enable.
curl -X POST https://cyoda.example.com/api/oauth/keys/trusted/${KEY_ID}/reactivate \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
### Delete
```bash
curl -X DELETE https://cyoda.example.com/api/oauth/keys/trusted/${KEY_ID} \
-H "Authorization: Bearer ${ADMIN_TOKEN}"
```
### Sign and present a token
Your workload signs a JWT with the matching private key, setting `kid` to the registered `keyId`:
```text
Header: { "alg": "RS256", "typ": "JWT", "kid": "my-signing-key-2026-06" }
Payload: { universal cyoda claim contract — see auth.tokens }
```
Present it like any other cyoda token:
```bash
curl -X GET https://cyoda.example.com/api/clients \
-H "Authorization: Bearer ${SIGNED_JWT}"
```
cyoda looks up `kid` in the trusted-key registry, validates the RS256 signature against the registered public key, then enforces the universal claim checks (`iss`, `aud`, `exp`, …).
## TOKEN
JWTs you sign with a trusted-key private key must conform to the universal cyoda claim contract documented in `auth.tokens`. In particular:
- `iss` must match `CYODA_JWT_ISSUER` (typically the value you set on the cyoda deployment) — trusted-key tokens are *not* issuer-bound to your IdP because there is no IdP.
- `aud` is checked against `CYODA_JWT_AUDIENCE` if set.
- `caas_org_id` must match the tenant that registered the key.
Cyoda does not mint trusted-key JWTs — you sign them. This page covers the registration + lifecycle of the public key; the claim contract is in `auth.tokens`.
## ERRORS
- `errors.FEATURE_DISABLED` (`404`) — trusted-key endpoints called with `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=false`.
- `errors.TRUSTED_KEY_NOT_FOUND` (`404`) — referenced `keyId` not in the registry (also returned for cross-tenant access — the existence of another tenant's key is never confirmed).
- `errors.TRUSTED_KEY_CAP_REACHED` (`400`) — per-tenant cap reached; delete or invalidate an old key first.
- `errors.KEY_OWNED_BY_DIFFERENT_TENANT` (`409`) — registration request specifies a `keyId` that already belongs to another tenant. Pick a fresh `keyId`.
- `errors.UNSUPPORTED_KEY_TYPE` (`400`) — `kty` is not `"RSA"` (the only type cyoda-go v0.8.0 accepts).
- `errors.UNAUTHORIZED` (`401`) — caller lacks a valid bearer for the management call; or, at validation time, the signing key is unknown / invalidated / expired.
## SEE ALSO
- `auth.tokens` — universal JWT claim contract
- `config.auth` — `CYODA_IAM_TRUSTED_KEY_*` env vars
- `openapi` — `cyoda help openapi tags` and look for the `IAM` tag's `/oauth/keys/trusted/*` operations
## See also
- [`cyoda help auth`](/help/auth/) — auth — authenticate client applications against cyoda.
- [`cyoda help auth tokens`](/help/auth/tokens/) — auth.tokens — exchange credentials for a JWT at `POST /api/oauth/token`. Covers every supported grant and the canonical JWT claim contract that all cyoda tokens (M2M, OBO, federated OIDC, trusted-key) conform to.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help errors TRUSTED_KEY_NOT_FOUND`](/help/errors/trusted_key_not_found/) — Returned by trusted-key admin endpoints when the supplied KID does not match any registered key:
- [`cyoda help errors TRUSTED_KEY_CAP_REACHED`](/help/errors/trusted_key_cap_reached/) — `POST /oauth/keys/trusted` enforces a per-tenant cap (default 10, configurable via `CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT`). The cap counts only currently-valid keys (Active and not past `validTo`). Delete or invalidate older keys, or raise the cap.
- [`cyoda help errors KEY_OWNED_BY_DIFFERENT_TENANT`](/help/errors/key_owned_by_different_tenant/) — Trusted keys are tenant-scoped. When `POST /oauth/keys/trusted` is called with a `keyId` that already belongs to a different tenant, the request is rejected with `409`. Pick a fresh `keyId` (the caller cannot see or affect the other tenant's keys).
- [`cyoda help errors UNSUPPORTED_KEY_TYPE`](/help/errors/unsupported_key_type/) — `POST /oauth/keys/trusted` accepts only `kty: "RSA"` in v0.8.0. Cloud also supports `kty: "EC"` and `kty: "OKP"`; cyoda-go parity is tracked in a v0.8.1 follow-up.
- [`cyoda help errors FEATURE_DISABLED`](/help/errors/feature_disabled/) — Returned by trusted-key endpoints when `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=false` (the default):
## Raw formats
- [`/help/auth/trusted-keys.json`](/help/auth/trusted-keys.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/auth/trusted-keys.md`](/help/auth/trusted-keys.md) — body only
---
## help/cli.md
# cyoda CLI — subcommand reference
cyoda is a Go binary that embeds the full platform: API server, schema engine, workflow runner, and storage plugins. Invoked with no subcommand, it starts…
cyoda-go version 0.8.4
# cli
## NAME
cli — the cyoda command-line interface.
## SYNOPSIS
`cyoda [] []`
## DESCRIPTION
cyoda is a Go binary that embeds the full platform: API server, schema engine, workflow runner, and storage plugins. Invoked with no subcommand, it starts the server using environment-provided configuration. Subcommands provide operational affordances — `init` for first-run bootstrap, `health` for liveness probes, `migrate` for schema migrations.
Global flags `--help` (or `-h`) and `--version` (or `-v`) are recognized before subcommand dispatch.
## SUBCOMMANDS
- `cyoda` (no subcommand) — start the API server. See `cli serve`. Exit codes: `0` clean shutdown after SIGINT/SIGTERM; `1` startup failure (IAM validation, OTel init, port bind, backend connect).
- `cyoda init [--force]` — Write a starter user config enabling sqlite. See `cyoda help cli init`. Exit codes: `0` success or idempotent no-op; `1` I/O error; `2` bad flags.
- `cyoda health` — Probe `/readyz` on the admin listener. See `cyoda help cli health`. Exit codes: `0` readyz returned 200; `1` connection error or non-200 status.
- `cyoda migrate [--timeout ]` — Run schema migrations for the configured backend and exit. See `cyoda help cli migrate`. Exit codes: `0` success or no-op (memory/sqlite); `1` runtime error (bad config, DB unreachable, migration failure, timeout); `2` flag-parse error.
- `cyoda help [...] [--format=]` — Browse the help topic tree. See `cyoda help cli help`. Exit codes: `0` topic found; `1` topic not found.
## OPTIONS
- `--help`, `-h` — Print top-level help summary. Exit code: `0`.
- `--version`, `-v` — Print the binary's ldflag-injected version, commit SHA, and build date. Exit code: `0`.
## CONFIGURATION
All server configuration is via environment variables with the `CYODA_` prefix. Variables can be placed in `.env` files and loaded automatically using profiles. See `cyoda help config` for the full reference.
## EXAMPLES
```
# Start the server with defaults (in-memory storage, mock auth)
cyoda
# First-run bootstrap then start
cyoda init && cyoda
# Check version of an installed binary
cyoda --version
# Run with profiles: postgres storage + observability
CYODA_PROFILES=postgres,otel cyoda
# Run via docker compose (dev helper)
./scripts/dev/run-docker-dev.sh
```
## SEE ALSO
- config
- run
- quickstart
## Subtopics
- [`cyoda help cli health`](/help/cli/health/) — `cyoda health` sends an HTTP GET to `http://127.0.0.1:/readyz` and exits 0 if the server responds with HTTP 200. Any non-200 response or connection error causes exit 1.
- [`cyoda help cli help`](/help/cli/help/) — `cyoda help` is the built-in documentation browser. Topics are organized in a dot-separated tree (`cli`, `cli.serve`, `config.database`, etc.). Invoking `cyoda help` with no arguments prints a summary of all top-level topics. Invoking it with one or more topic segments navigates the tree.
- [`cyoda help cli init`](/help/cli/init/) — `cyoda init` is the recommended first step for local desktop use. It writes a minimal user config file that sets `CYODA_STORAGE_BACKEND=sqlite`, enabling persistent local storage without requiring a database server.
- [`cyoda help cli migrate`](/help/cli/migrate/) — `cyoda migrate` is a short-lived process that applies pending schema migrations for the configured storage backend, then exits cleanly — no admin listener, no background loops, no lingering goroutines.
- [`cyoda help cli serve`](/help/cli/serve/) — Starting with no subcommand loads configuration from environment variables, validates the IAM mode, and binds the REST, gRPC, and admin listeners. The server is single-process, multi-tenant, and stateful — storage is provided by one of the pluggable backends (`memory`, `sqlite`, or `postgres`); see `cyoda help config` for backend selection.
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help quickstart`](/help/quickstart/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memory`, `sqlite`, and `postgres`; authentication modes are `mock` and `jwt`. All configuration is via environment variables with a `CYODA_` prefix.
## Raw formats
- [`/help/cli.json`](/help/cli.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cli.md`](/help/cli.md) — body only
---
## help/cli/health.md
# cyoda health — readiness probe
`cyoda health` sends an HTTP GET to `http://127.0.0.1:/readyz` and exits 0 if the server responds with HTTP 200. Any non-200 response or connection …
cyoda-go version 0.8.4
# cli.health
## NAME
cli.health — probe the admin listener's `/readyz` endpoint.
## SYNOPSIS
`cyoda health`
## DESCRIPTION
`cyoda health` sends an HTTP GET to `http://127.0.0.1:/readyz` and exits 0 if the server responds with HTTP 200. Any non-200 response or connection error causes exit 1.
The probe uses a hard-coded 2-second HTTP client timeout. This timeout is load-bearing: a deadlocked readiness handler looks identical to "server accepts the connection then hangs" from the client's perspective. Without a timeout, Docker's `HEALTHCHECK` would inherit the deadlock and never mark the container unhealthy.
The port is read from `CYODA_ADMIN_PORT` (default: `9091`). The admin listener always binds to `127.0.0.1` from the probe's perspective — `cyoda health` is designed to run inside the same container or on the same host as the server.
Despite the command name, this probes `/readyz` on the admin listener, not `GET /health` on the API listener. The two mirror the same underlying flag — `200`/`ready` while healthy, `503` once a panic has been recovered in engine or store work and the node's state is unverified, latched until the node is replaced (a panic in a probe or a metrics scrape is contained with a ticket but does not latch) — but `/health` is a plain JSON summary for humans and simple scripts, not the deployment probe.
Primary consumers:
- **Docker Compose** — `HEALTHCHECK` stanza in the service definition.
- **Helm chart** — `readinessProbe` invokes `cyoda health` before the pod is marked ready.
## OPTIONS
`cyoda health` accepts no flags.
## ENVIRONMENT VARIABLES
- `CYODA_ADMIN_PORT` — Admin listener port to probe (default: `9091`).
## EXIT CODES
- `0` — Server responded HTTP 200. Instance is ready.
- `1` — Connection failed, timed out, or server returned a non-200 status.
## EXAMPLES
```
# Basic probe (uses CYODA_ADMIN_PORT or default 9091)
cyoda health
# Probe a server on a non-default admin port
CYODA_ADMIN_PORT=19091 cyoda health
# Use in a shell script
if cyoda health; then
echo "server is ready"
else
echo "server not ready" >&2
exit 1
fi
```
## SEE ALSO
- telemetry
## See also
- [`cyoda help telemetry`](/help/telemetry/) — cyoda-go integrates the OpenTelemetry Go SDK (`go.opentelemetry.io/otel`). The
**metric scrape pipeline is always on**: at startup the binary creates a meter
provider with an OpenTelemetry → Prometheus exporter and serves it at
`:9091/metrics`, regardless of `CYODA_OTEL_ENABLED`. No collector is required to
scrape metrics.
## Raw formats
- [`/help/cli/health.json`](/help/cli/health.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cli/health.md`](/help/cli/health.md) — body only
---
## help/cli/help.md
# cyoda help — the help subsystem
`cyoda help` is the built-in documentation browser. Topics are organized in a dot-separated tree (`cli`, `cli.serve`, `config.database`, etc.). Invoking `…
cyoda-go version 0.8.4
# cli.help
## NAME
cli.help — the cyoda help subsystem and topic-tree contract.
## SYNOPSIS
`cyoda help [...] [--format=]`
## DESCRIPTION
`cyoda help` is the built-in documentation browser. Topics are organized in a dot-separated tree (`cli`, `cli.serve`, `config.database`, etc.). Invoking `cyoda help` with no arguments prints a summary of all top-level topics. Invoking it with one or more topic segments navigates the tree.
The help content is embedded in the binary at build time — no network access or external files are needed.
Release archives include a pre-rendered `help/` directory for offline reference.
## OPTIONS
- `--format=` — Default `auto` selects text on a TTY and markdown off-TTY.
## TOPIC ACTIONS
Some topics publish machine-readable actions invoked as `cyoda help `. Actions emit raw content to stdout without rendering the help body.
The `cyoda help` top-level summary lists topics that have actions registered. Each topic's render output includes an `ACTIONS` footer enumerating its actions. The JSON payload of `cyoda help --format=json` carries an `actions` array of the same names.
Actions do not accept `--format` (that flag governs the help body's output form, not action emission).
## REST API
The same topic tree is served over HTTP on the running server. No authentication is required — help content is public. Responses are machine-parseable (`application/json` for topic payloads, `application/problem+json` for errors).
### Endpoints
- `GET {CYODA_CONTEXT_PATH}/help` — returns the full topic tree as a `HelpPayload` JSON document.
- `GET {CYODA_CONTEXT_PATH}/help/{topic}` — returns a single `TopicDescriptor` JSON document for the addressed topic.
`CYODA_CONTEXT_PATH` defaults to `/api`. Both mount points are relative to the configured context path.
### Methods
Only `GET` is accepted by the help handler. CORS preflights (`OPTIONS`) are handled by the unified middleware before reaching this handler. Any other method (`POST`, `PUT`, `DELETE`, `PATCH`) returns `405 Method Not Allowed` with header `Allow: GET` and a `BAD_REQUEST` error body (`application/problem+json`).
### Topic path syntax
`{topic}` uses either the canonical **dotted** form (`errors.VALIDATION_FAILED`, `cli.serve`) or the **slash** form (`errors/VALIDATION_FAILED`, `cli/serve`). Both resolve to the same topic. The dotted form matches the identifier used in the JSON payload (`topic`, `see_also`, `children` fields); the slash form is a REST-idiomatic hierarchy. Mixed separators in a single path (e.g. `cli.serve/examples`) are also accepted.
Valid path characters: `[A-Za-z0-9._/-]+`, starting and ending with alphanumeric. A path with any other character (including URL-encoded spaces `%20`) returns `400 BAD_REQUEST`. An empty path segment (leading separator, trailing separator, or double separator) also returns `400`.
URL-encoded slash (`%2F`) is decoded to a literal `/` by the HTTP stack and treated as a separator — so `GET /api/help/cli%2Fhelp` is equivalent to `GET /api/help/cli/help`.
Note: consecutive slashes (e.g. `cli//help`) are cleaned to a single slash by Go's HTTP stack before the handler runs, so `cli//help` resolves the same as `cli/help`. This is analogous to how a bare `.` path segment redirects to the parent.
### Response — full tree
`GET {CYODA_CONTEXT_PATH}/help` returns a `HelpPayload` object.
```json
{
"schema": 1,
"version": "0.6.1",
"topics": [
{
"topic": "cli.help",
"path": ["cli", "help"],
"title": "cyoda help — the help subsystem",
"synopsis": "the cyoda help subsystem and topic-tree contract.",
"body": "# cli.help\n\n## NAME\n\n...",
"sections": [
{ "name": "NAME", "body": "cli.help — the cyoda help subsystem and topic-tree contract." },
{ "name": "SYNOPSIS", "body": "`cyoda help [...] [--format=]`" }
],
"see_also": ["cli"],
"stability": "stable",
"actions": [],
"children": []
}
]
}
```
`HelpPayload` fields:
- `schema` (integer) — payload schema version. Currently `1`. Consumers must check this before parsing; a higher value signals additive fields were added.
- `version` (string) — ldflag-injected binary version string (e.g. `"0.6.1"`).
- `topics` (array of `TopicDescriptor`) — every topic in the tree, in walk order.
### Response — single topic
`GET {CYODA_CONTEXT_PATH}/help/{topic}` returns a `TopicDescriptor` object.
```json
{
"topic": "cli.help",
"path": ["cli", "help"],
"title": "cyoda help — the help subsystem",
"synopsis": "the cyoda help subsystem and topic-tree contract.",
"body": "# cli.help\n\n## NAME\n\ncli.help — the cyoda help subsystem and topic-tree contract.\n\n...",
"sections": [
{ "name": "NAME", "body": "cli.help — the cyoda help subsystem and topic-tree contract." },
{ "name": "SYNOPSIS", "body": "`cyoda help [...] [--format=]`" },
{ "name": "DESCRIPTION", "body": "..." },
{ "name": "OPTIONS", "body": "..." },
{ "name": "STABILITY", "body": "..." },
{ "name": "EXAMPLES", "body": "..." },
{ "name": "SEE ALSO", "body": "..." }
],
"see_also": ["cli"],
"stability": "stable",
"actions": [],
"children": ["cli.help"]
}
```
`TopicDescriptor` fields:
- `topic` (string) — canonical dotted path (e.g. `"cli.help"`).
- `path` (array of strings) — topic path split into segments (e.g. `["cli", "help"]`).
- `title` (string) — topic title from the front-matter `title:` field.
- `synopsis` (string) — single-line description extracted from the NAME or DESCRIPTION section; inline markers stripped, whitespace collapsed.
- `body` (string) — full raw markdown source of the topic file.
- `sections` (array of objects) — H2-delimited blocks; each object has `name` (string, the H2 heading text) and `body` (string, everything between this H2 and the next H2 or end-of-file, trimmed).
- `see_also` (array of strings) — dotted topic paths from the front-matter `see_also:` list.
- `stability` (string) — one of `"stable"`, `"evolving"`, or `"experimental"`.
- `actions` (array of strings) — names of machine-readable actions the topic supports; empty array when none.
- `children` (array of strings, omitted when empty) — dotted paths of direct child topics.
### Errors
Errors use RFC 9457 Problem Details (`application/problem+json`). See `errors` topic for the full envelope shape.
- `400 BAD_REQUEST` — the `{topic}` path segment contains disallowed characters (fails `^[A-Za-z0-9]([A-Za-z0-9._/-]*[A-Za-z0-9])?$`), or contains an empty segment (leading/trailing separator, double separator). Also returned for any method other than `GET` (with `Allow: GET` response header).
- `404 HELP_TOPIC_NOT_FOUND` — the `{topic}` is well-formed but does not resolve to any topic in the tree.
### Examples
```bash
# Fetch the full topic tree and inspect schema version and binary version
curl -s http://localhost:8080/api/help | jq '{schema: .schema, version: .version}'
# Fetch a single topic — dotted form (canonical)
curl -s http://localhost:8080/api/help/cli.serve | jq .topic
# Fetch the same topic — slash form (REST-idiomatic, equivalent)
curl -s http://localhost:8080/api/help/cli/serve | jq .topic
# Mixed separators also resolve (e.g. errors.VALIDATION_FAILED via slash)
curl -s http://localhost:8080/api/help/errors/VALIDATION_FAILED | jq .topic
# Fetch a single topic and extract its registered actions
curl -s http://localhost:8080/api/help/cli.help | jq '.actions'
# Fetch an unknown topic — observe the 404 HELP_TOPIC_NOT_FOUND body
curl -s -w "\nHTTP %{http_code}\n" http://localhost:8080/api/help/no.such.topic
# Send a disallowed method and confirm 405 with Allow header
curl -si -X POST http://localhost:8080/api/help | grep -E "^HTTP|^Allow:"
```
### CORS
CORS is configured globally — see `config.cors` for the full env-var reference and deployment guidance.
## STABILITY
Topic additions are non-breaking. Renaming or removing a topic requires a deprecation window and an entry in CONTRIBUTING.md. Topic paths are stable for the duration of a major version.
## EXAMPLES
```
# Show all top-level topics
cyoda help
# Show the cli topic
cyoda help cli
# Show the serve subtopic
cyoda help cli serve
# Output JSON for the full topic tree
cyoda help --format=json
# Output JSON for a single topic
cyoda help --format=json cli serve
```
## SEE ALSO
- cli
## See also
- [`cyoda help cli`](/help/cli/) — cyoda is a Go binary that embeds the full platform: API server, schema engine, workflow runner, and storage plugins. Invoked with no subcommand, it starts the server using environment-provided configuration. Subcommands provide operational affordances — `init` for first-run bootstrap, `health` for liveness probes, `migrate` for schema migrations.
## Raw formats
- [`/help/cli/help.json`](/help/cli/help.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cli/help.md`](/help/cli/help.md) — body only
---
## help/cli/init.md
# cyoda init — first-run bootstrap
`cyoda init` is the recommended first step for local desktop use. It writes a minimal user config file that sets `CYODA_STORAGE_BACKEND=sqlite`, enabling …
cyoda-go version 0.8.4
# cli.init
## NAME
cli.init — write a starter user config enabling sqlite.
## SYNOPSIS
`cyoda init [--force]`
## DESCRIPTION
`cyoda init` is the recommended first step for local desktop use. It writes a minimal user config file that sets `CYODA_STORAGE_BACKEND=sqlite`, enabling persistent local storage without requiring a database server.
The user config file is written to the OS-appropriate XDG config path:
- **Linux / macOS:** `$XDG_CONFIG_HOME/cyoda/cyoda.env` (falls back to `~/.config/cyoda/cyoda.env` if `XDG_CONFIG_HOME` is unset).
- **Windows:** `%AppData%\cyoda\cyoda.env` (falls back to `%USERPROFILE%\AppData\Roaming\cyoda\cyoda.env`).
The sqlite database itself defaults to the OS data directory:
- **Linux / macOS:** `$XDG_DATA_HOME/cyoda/cyoda.db` (falls back to `~/.local/share/cyoda/cyoda.db`).
- **Windows:** `%LocalAppData%\cyoda\cyoda.db`.
The database path can be overridden by setting `CYODA_SQLITE_PATH` in the config or shell environment.
**Idempotency:** `cyoda init` is safe to run more than once. Without `--force`, it exits 0 immediately if a config already exists (either system-wide or at the user path). It does not modify, migrate, or overwrite existing configs.
**System config detection:** On Linux, if `/etc/cyoda/cyoda.env` exists, `cyoda init` prints a note and exits 0 without writing a user config — a system-wide config already covers the system. Pass `--force` to write a user config anyway.
## OPTIONS
- `--force` — Overwrite an existing user config, or write a user config even when a system config is present.
## EXIT CODES
- `0` — Success, including the no-op case (config already exists).
- `1` — I/O error (cannot compute user path, cannot create directory, cannot write file).
- `2` — Flag-parse error.
## EXAMPLES
```
# First-run bootstrap: write ~/.config/cyoda/cyoda.env
cyoda init
# Overwrite an existing user config
cyoda init --force
# Typical first-run sequence
cyoda init && cyoda
```
## SEE ALSO
- config
- cli.migrate
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help cli migrate`](/help/cli/migrate/) — `cyoda migrate` is a short-lived process that applies pending schema migrations for the configured storage backend, then exits cleanly — no admin listener, no background loops, no lingering goroutines.
## Raw formats
- [`/help/cli/init.json`](/help/cli/init.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cli/init.md`](/help/cli/init.md) — body only
---
## help/cli/migrate.md
# cyoda migrate — run storage migrations
`cyoda migrate` is a short-lived process that applies pending schema migrations for the configured storage backend, then exits cleanly — no admin listener…
cyoda-go version 0.8.4
# cli.migrate
## NAME
cli.migrate — run schema migrations for the configured storage backend and exit.
## SYNOPSIS
`cyoda migrate [--timeout ]`
## DESCRIPTION
`cyoda migrate` is a short-lived process that applies pending schema migrations for the configured storage backend, then exits cleanly — no admin listener, no background loops, no lingering goroutines.
It loads the same configuration the server does via `app.DefaultConfig`, honoring all `CYODA_*` environment variables and `_FILE` suffix resolution identically to the main server process.
Dispatch is on `CYODA_STORAGE_BACKEND`:
- **memory** — No-op; exits 0. The memory backend has no schema to migrate.
- **sqlite** — No-op; exits 0. SQLite applies migrations lazily on first open; the migrate subcommand is not needed.
- **postgres** — Runs the postgres plugin's embedded migration logic against `CYODA_POSTGRES_URL`. Exits 0 on success, 1 on error.
- **other** — Exits 1 with "unknown storage backend".
The migrate subcommand respects the schema-compatibility contract: it refuses to run if the database schema is newer than the code's embedded maximum version. This prevents a rollback from accidentally downgrading a schema.
The primary consumer is the Helm chart's pre-install and pre-upgrade Job, which runs `cyoda migrate` before starting the server to ensure the schema is up to date.
## OPTIONS
- `--timeout ` — Maximum duration for the migration run (default: 5 minutes). Accepts Go duration strings: `30s`, `2m`, `10m`, etc.
## ENVIRONMENT VARIABLES
- `CYODA_STORAGE_BACKEND` — Selects the backend to migrate (default: `memory`).
- `CYODA_POSTGRES_URL` — PostgreSQL DSN, required when backend is `postgres`. Accepts `CYODA_POSTGRES_URL_FILE` variant.
## EXIT CODES
- `0` — Migration succeeded (or was a no-op for memory/sqlite).
- `1` — Runtime error: bad config, database unreachable, migration failure, or timeout.
- `2` — Flag-parse error.
## EXAMPLES
```
# Migrate postgres schema (reads CYODA_POSTGRES_URL from environment)
CYODA_STORAGE_BACKEND=postgres \
CYODA_POSTGRES_URL="postgres://user:pass@localhost/cyoda" \
cyoda migrate
# Migrate with a custom timeout
CYODA_STORAGE_BACKEND=postgres \
CYODA_POSTGRES_URL="postgres://user:pass@localhost/cyoda" \
cyoda migrate --timeout 2m
# No-op — memory backend
cyoda migrate
```
## ADDING AN INDEX MIGRATION
An index on a table that already holds data must be built with `CREATE INDEX CONCURRENTLY`, alone in its own migration file. A plain `CREATE INDEX` takes a lock that conflicts with every insert, update and delete on that table for the whole build.
`CONCURRENTLY` must be the file's only statement. The migration driver sends a file as a single simple query, and PostgreSQL wraps a multi-statement simple query in an implicit transaction — inside which `CONCURRENTLY` cannot run.
An index created in the same migration as its own table needs no `CONCURRENTLY`: that table is empty and no writer can reach it yet.
## RECOVERING FROM A DIRTY MIGRATION STATE
A migration that dies partway leaves the schema half-applied and the migration state marked dirty. Startup then refuses with `database migration state is dirty at version N`, on both PostgreSQL and SQLite.
Recovery is always the same three steps: undo what the failed migration left behind, point the recorded version back at the last good migration, re-run.
**1. Undo the partial work.** On PostgreSQL the usual cause is a `CREATE INDEX CONCURRENTLY` that failed, which leaves an INVALID index behind. Find it and drop it — concurrently, so live traffic is unaffected:
```sql
SELECT indexrelid::regclass AS index_name FROM pg_index WHERE NOT indisvalid;
DROP INDEX CONCURRENTLY ;
```
Anything else — a partly-created table, a column added but not backfilled — has to be reversed by hand against the failed migration's SQL.
**2. Reset the recorded version.** There is no `cyoda migrate` subcommand for this. Do it in SQL, with no server and no `cyoda migrate` running against the database:
```sql
UPDATE schema_migrations SET version = , dirty = false;
```
If N is 1, delete the row instead — nothing has been applied:
```sql
DELETE FROM schema_migrations;
```
**3. Re-run.** `cyoda migrate` on PostgreSQL; on SQLite, restart the node, which applies migrations at open.
Never edit `schema_migrations` while a node may be migrating. If the flag appeared during a rolling upgrade, confirm no peer is mid-migration first — a node that finishes migrating clears the flag itself.
## SEE ALSO
- config
- cli.init
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help cli init`](/help/cli/init/) — `cyoda init` is the recommended first step for local desktop use. It writes a minimal user config file that sets `CYODA_STORAGE_BACKEND=sqlite`, enabling persistent local storage without requiring a database server.
## Raw formats
- [`/help/cli/migrate.json`](/help/cli/migrate.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cli/migrate.md`](/help/cli/migrate.md) — body only
---
## help/cli/serve.md
# cyoda serve — start the API server
Starting with no subcommand loads configuration from environment variables, validates the IAM mode, and binds the REST, gRPC, and admin listeners. The ser…
cyoda-go version 0.8.4
# cli.serve
## NAME
cli.serve — start the cyoda API server.
## SYNOPSIS
`cyoda` (no subcommand; serving is the default mode)
## DESCRIPTION
Starting with no subcommand loads configuration from environment variables, validates the IAM mode, and binds the REST, gRPC, and admin listeners. The server is single-process, multi-tenant, and stateful — storage is provided by one of the pluggable backends (`memory`, `sqlite`, or `postgres`); see `cyoda help config` for backend selection.
On startup, the binary prints an ASCII banner with version, commit, build date, HTTP port, gRPC port, IAM mode, context path, and active storage profiles. The banner is suppressed by `CYODA_SUPPRESS_BANNER=true`.
The server handles graceful shutdown on `SIGINT` (Ctrl+C) or `SIGTERM`: the HTTP and admin servers drain in-flight requests within a hardcoded 10-second deadline, then the storage backend is closed and the process exits.
## LISTENERS
Three TCP listeners start concurrently:
- **REST API** — `CYODA_HTTP_PORT` (default: 8080). All entity, schema, workflow, and auth endpoints, plus `GET /health` — a health summary for humans and simple scripts, not the deployment probe: `200 {"status":"UP"}` while healthy, `503 {"status":"DOWN"}` after a panic recovered in engine or store work, latched until the node is replaced. Context path prefix: `CYODA_CONTEXT_PATH` (default: `/api`).
- **gRPC** — `CYODA_GRPC_PORT` (default: 9090). Externalized-processor streaming.
- **Admin** — `CYODA_ADMIN_BIND_ADDRESS:CYODA_ADMIN_PORT` (default: `127.0.0.1:9091`). `/livez`, `/readyz`, and `/metrics` endpoints — `/livez` (unconditional) and `/readyz` (mirrors the same flag as `/health`) are the deployment probes. Admin port is bound to localhost by default; the Helm chart overrides `CYODA_ADMIN_BIND_ADDRESS` so the kubelet can reach `/readyz` without traversing the service mesh.
## ENVIRONMENT VARIABLES
All configuration is via environment variables. The subtopics below enumerate the complete per-subsystem variable sets:
- `config` — all top-level server options (HTTP port, log level, OTel, etc.)
- `config.database` — storage backend selection and per-backend connection settings
- `config.auth` — IAM mode, JWT issuer, signing key
- `config.grpc` — gRPC listener and compute-node credentials
- `config.schema` — schema-extension log tuning
Variables read specifically during server boot (not covered by the config subtopics above):
- `CYODA_HTTP_PORT` (int, default: `8080`) — HTTP API listen port.
- `CYODA_GRPC_PORT` (int, default: `9090`) — gRPC listen port.
- `CYODA_ADMIN_PORT` (int, default: `9091`) — admin listener port for `/livez`, `/readyz`, `/metrics`.
- `CYODA_ADMIN_BIND_ADDRESS` (string, default: `127.0.0.1`) — admin listener bind address.
- `CYODA_OTEL_ENABLED` (bool, default: `false`) — initialize the OpenTelemetry SDK at startup.
- `CYODA_LOG_LEVEL` (string, default: `info`) — accepted: `debug|info|warn|error`.
- `CYODA_SUPPRESS_BANNER` (bool, default: `false`) — suppress the ASCII startup banner and mock-auth warning.
## EXIT CODES
- `0` — clean shutdown after SIGINT or SIGTERM.
- `1` — startup failure: IAM validation failed (`CYODA_REQUIRE_JWT` contract not met), OTel SDK initialization error, gRPC port-bind failure, or backend connection failure during `app.New`.
- `2` — hard exit forced by a second SIGINT or SIGTERM delivered while the graceful drain was still running. Nothing is drained or flushed on this path.
## EXAMPLES
```
# Run with defaults (in-memory storage, mock auth)
cyoda
# SQLite backend with debug logging
CYODA_STORAGE_BACKEND=sqlite CYODA_LOG_LEVEL=debug cyoda
# PostgreSQL backend, JWT auth, loaded via profiles
CYODA_PROFILES=postgres,jwt \
CYODA_JWT_SIGNING_KEY="$(cat signing.pem)" \
cyoda
# Suppress startup banner (useful in CI)
CYODA_SUPPRESS_BANNER=true cyoda
```
## SEE ALSO
- config
- run
- quickstart
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help quickstart`](/help/quickstart/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memory`, `sqlite`, and `postgres`; authentication modes are `mock` and `jwt`. All configuration is via environment variables with a `CYODA_` prefix.
## Raw formats
- [`/help/cli/serve.json`](/help/cli/serve.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cli/serve.md`](/help/cli/serve.md) — body only
---
## help/cloudevents.md
# cloudevents — CloudEvent payload JSON Schemas
cyoda-go uses [CloudEvents v1.0](https://cloudevents.io) as the transport envelope for event-driven processing. Every payload carried inside a CloudEvent …
cyoda-go version 0.8.4
# cloudevents
## NAME
cloudevents — JSON Schemas for every CloudEvent payload exchanged over the gRPC `CloudEventsService` bidirectional stream.
## SYNOPSIS
```
cyoda help cloudevents # narrative (this page)
cyoda help cloudevents json # full schemas tree as a single JSON document
```
## DESCRIPTION
cyoda-go uses [CloudEvents v1.0](https://cloudevents.io) as the transport envelope for event-driven processing. Every payload carried inside a CloudEvent — workflow calculation requests, calculation responses, entity transaction events, snapshot state, model descriptors — is validated against a JSON Schema (Draft 2020-12).
The canonical schema tree lives at `docs/cyoda/schema/` in this repo and is embedded into the binary at build time. It is the single source of truth for:
- **Runtime validation** of inbound CloudEvent payloads (in cyoda-go and external compute members).
- **Code generation** via `scripts/generate-events.sh` — the Go types in `api/grpc/events/types.go` are derived from this tree.
- **Downstream tooling**: documentation pipelines and SDK generators extract the tree from the binary (see `cyoda help cloudevents json`), so every version of cyoda ships with a matching, self-describing schema bundle.
## ORGANIZATION
The tree is organized by domain:
- **`common/`** — shared envelope fragments: `BaseEvent`, `DataPayload`, `CloudEventType`, `ModelSpec`, `ErrorCode`. Every domain-specific payload extends `BaseEvent`.
- **`common/statemachine/`** — workflow metadata descriptors: `WorkflowInfo`, `TransitionInfo`, `ProcessorInfo`.
- **`entity/`** — entity create / update / delete / transition / audit requests and responses.
- **`model/`** — model snapshot events and management requests.
- **`processing/`** — compute-member protocol events: `EntityCriteriaCalculationRequest`/`Response`, `EntityProcessorCalculationRequest`/`Response`, `EntityFunctionCalculationRequest`/`Response`, `CalculationMemberJoinEvent`, `CalculationMemberGreetEvent`, `EventAckResponse`.
- **`search/`** — search snapshot lifecycle events.
Every schema carries a `$id` in the form `https://cyoda.com/cloud/event/`. Inter-schema references use relative `$ref` paths (e.g. `../common/BaseEvent.json`) so a materialized filesystem copy resolves out of the box.
## ACTION: `cyoda help cloudevents json`
Emits the entire tree as a single JSON document. Shape:
```json
{
"schema": 1,
"version": "",
"specVersion": "https://json-schema.org/draft/2020-12/schema",
"baseId": "https://cyoda.com/cloud/event/",
"schemas": {
"common/BaseEvent.json": { "$schema": "...", "$id": "...", ... },
"common/statemachine/WorkflowInfo.json": { ... },
"entity/EntityTransactionResponse.json": { ... },
"processing/EntityCriteriaCalculationRequest.json": { ... },
...
}
}
```
- **`schemas`** is a map keyed by relative path (identical to the directory layout). This lets downstream tooling fan the tree out to disk without renaming.
- **Values are complete JSON Schema documents**, structurally identical to the source file after normalizing whitespace and key ordering.
- **`$ref` values stay relative** — they are not rewritten to absolute URLs. A consumer that writes the tree to disk gets working resolution for free.
- **Keys are lexicographically sorted** — output is diff-stable across builds.
- **`baseId`** and **`specVersion`** are constants exposed for consumers that want to construct absolute IDs or validate against a specific meta-schema.
## VERIFICATION
Count emitted schemas:
```bash
cyoda help cloudevents json | jq '.schemas | keys | length'
```
List every schema path:
```bash
cyoda help cloudevents json | jq -r '.schemas | keys[]'
```
Materialize the tree to a directory:
```bash
cyoda help cloudevents json \
| jq -r '.schemas | to_entries[] | "\(.key)\t\(.value | tojson)"' \
| while IFS=$'\t' read -r path body; do
mkdir -p "$(dirname "schemas/$path")"
printf '%s\n' "$body" > "schemas/$path"
done
```
## SEE ALSO
- grpc
- workflows
- errors.DISPATCH_TIMEOUT
- errors.DISPATCH_FORWARD_FAILED
## See also
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
- [`cyoda help errors DISPATCH_FORWARD_FAILED`](/help/errors/dispatch_forward_failed/) — The cluster dispatcher attempted to forward a processor invocation or criteria evaluation to a peer node but the HTTP call to that peer failed (network error, peer crash, or connection refused). The operation has not been executed on the target node.
## Raw formats
- [`/help/cloudevents.json`](/help/cloudevents.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cloudevents.md`](/help/cloudevents.md) — body only
---
## help/cluster.md
# cluster — multi-node topology and operations
Multi-node cyoda is supported only on the `postgres` storage backend. All nodes are stateless and identical: no leader election, no shard ownership, no ex…
cyoda-go version 0.8.4
# cluster
## NAME
cluster — multi-node cyoda topology, peer discovery, and transaction routing.
## SYNOPSIS
```
2–20 stateless cyoda nodes
│
▼ load balancer (HTTP + gRPC)
│
▼ shared PostgreSQL (single primary)
```
## DESCRIPTION
Multi-node cyoda is supported only on the `postgres` storage backend. All nodes are stateless and identical: no leader election, no shard ownership, no external service-discovery infrastructure. PostgreSQL is the single coordination layer. Snapshot Isolation with first-committer-wins (`REPEATABLE READ` + commit-time validation) provides correctness; gossip provides peer awareness; HMAC-signed routing tokens bind in-flight `pgx.Tx` handles to their owning node.
`CYODA_CLUSTER_ENABLED=false` is the default for easy onboarding, not an indication that cluster/HA features are secondary. Multi-node correctness is a primary design target.
## TOPOLOGY
Any node can serve any HTTP or gRPC request. The load balancer does not need session affinity for stateless requests. For requests carrying a transaction-routing token (see `TRANSACTION ROUTING`), the in-process proxy forwards to the node that owns the transaction.
PostgreSQL is the only stateful component. Cluster size is bounded below by quorum-free PostgreSQL replication (typically 3 cyoda nodes minimum for HA) and above by PostgreSQL connection-pool capacity (typically 10 nodes maximum; see `config.database` for connection-pool tuning).
## DISCOVERY
Peer discovery uses SWIM gossip via HashiCorp `memberlist`. Cluster membership is eventually consistent across nodes. New nodes join via a seed-list — at least one peer's `host:gossip_port`. Nodes leave gracefully on SIGTERM and are evicted by gossip after a configurable suspect-then-confirm timeout if they crash.
The gossip protocol is operationally invisible — there are no per-message logs at INFO level. `memberlist`'s own log output is routed to `slog` at DEBUG.
## TRANSACTION ROUTING
PostgreSQL transactions are bound to the connection that begins them (`pgx.Tx` is single-owner). When a node begins a transaction, it issues a routing token containing the owning node's identity, an opaque transaction reference, and an expiry, signed with HMAC-SHA256 keyed on `CYODA_HMAC_SECRET`. The token is returned to the client (HTTP header `X-Tx-Token`, gRPC metadata key `tx-token`) and replayed on subsequent requests against that transaction.
The HTTP and gRPC frontends inspect the token, verify the HMAC, and either handle the request locally (token's owner is this node) or reverse-proxy to the owning node. Failure modes:
- Token signature mismatch, malformed token, or expired token — `400 Bad Request` (codes `BAD_REQUEST` / `TRANSACTION_EXPIRED`); the client must restart the transaction.
- Owner node not in the registry, marked dead by gossip, or unreachable from the proxy — `503 Service Unavailable` (code `TRANSACTION_NODE_UNAVAILABLE`); PostgreSQL has already aborted the connection's transaction on the dead node, so the client retries from scratch. Fail-closed semantics, no orphaned transactions.
`CYODA_HMAC_SECRET` is a deployment secret. All nodes in a cluster must share the same value; it is also the root key for peer-to-peer dispatch authentication (HKDF-derived AEAD), so rotating it requires a cluster-wide restart — see `SECRET ROTATION`.
## OPERATIONS
- **Growing the cluster.** Start a new node with the same `CYODA_HMAC_SECRET` and a seed-list pointing at any existing node. Gossip propagates membership within seconds. The load balancer's health checks (against `/readyz`) decide when to send traffic.
- **Shrinking the cluster.** Send SIGTERM. The node finishes in-flight requests, declares itself dead via gossip, and exits. Outstanding transactions owned by the departing node abort cleanly via PostgreSQL connection close.
- **Rolling restart.** Restart one node at a time, waiting for `/readyz` to report ready before moving on. Transactions in flight on the restarting node abort; clients retry.
- **Network partitions.** A node partitioned from peers but still reachable from PostgreSQL continues to serve requests; gossip-level membership is best-effort and does not gate request handling. A node partitioned from PostgreSQL continues to pass `/readyz` (readiness is a static initialization flag plus the panic-recovery health flag, not a live store probe — see `app/app.go ReadinessCheck`); individual requests fail at query time and the client retries. The full partition analysis (5 phases, dispatch and CRUD-callback paths) is in `docs/ARCHITECTURE.md` §4.5.
## CROSS-NODE DISPATCH FAILOVER
When a callout (processor, criterion, or scheduled function) needs a compute tag no local member serves, the node forwards it to a peer advertising the tag. If the forward fails at the transport level (peer unreachable) or the peer reports it no longer has a matching member, the node fails over to the next tag-matching peer, trying each peer at most once. Failures indicating the callout actually ran on the peer (e.g. `DISPATCH_TIMEOUT`) are never retried on another peer. When all peers are exhausted, the last failure surfaces as a retryable `503`.
## SECRET ROTATION
`CYODA_HMAC_SECRET` is the single root secret for three primitives: gossip encryption, inter-node dispatch authentication (HKDF-derived AES-256-GCM), and transaction-routing token signing. There is no versioned-key support, so nodes holding different secrets cannot interoperate: a node started with a mismatched secret fails its gossip join and exits at startup, and dispatch requests between mismatched nodes are rejected with `403`. Failure is loud — never a silent split-brain.
Rotating the secret therefore requires full-cluster downtime: stop all nodes, update the secret everywhere, start the cluster again. A rolling restart across a secret change is not possible. In-flight transactions and routing tokens do not survive the restart; clients retry from scratch.
## DISPATCH REPLAY PROTECTION
Each node keeps an in-memory replay cache of dispatch-envelope nonces: entries live for 60 seconds (twice the 30-second timestamp-skew window) and the cache holds at most 100 000 nonces, per node. The cache is fail-closed: when full, new dispatch envelopes are rejected as replays until entries expire, surfacing to the forwarding node as a retryable failure (which dispatch failover routes around). The ceiling admits roughly 1 600 sustained inbound cross-node dispatches per second per node (100 000 nonces per 60-second window) — far above realistic callout rates; reaching it indicates a flood, not normal load.
## COMPUTE CALLBACK TRANSACTION ROUTING
When the workflow engine dispatches to a compute node it mints a signed tx-token
and includes it as the `cyodatxtoken` CloudEvent extension attribute. The compute
node MUST echo this token on every callback:
- HTTP CRUD callbacks: `X-Tx-Token` request header
- gRPC EntityManage callbacks: `tx-token` metadata key
The receiving node verifies the token's HMAC and routes the callback to the
transaction-owning node (same proxy mechanism as `TRANSACTION ROUTING` above).
Without the echo the callback runs in a standalone transaction and cannot see
the cascade's uncommitted writes. Callback acks are provisional until the
owning transaction commits.
See `workflows` and `docs/PROCESSOR_EXECUTION_MODES.md` for mode-specific
semantics (`SYNC`, `ASYNC_NEW_TX`, `COMMIT_BEFORE_DISPATCH`).
## COMPOSITE UNIQUE KEY STALENESS
Composite unique keys are part of the model descriptor. They inherit the descriptor's existing cross-cluster coherence: when a model is locked or unlocked, the node that performs the operation invalidates the local model cache and gossip-broadcasts `topicModelInvalidate` so every other node evicts and reloads the descriptor (keys included).
**Changing a key on a live multi-node postgres deployment** requires a destructive teardown: unlock the model (requires zero live entities, so all entities must be deleted first), change the key definitions, then relock. This is an inherently disruptive operation. There is a bounded window during which a node that missed both the unlock and relock gossip messages may still enforce the **old** key set. Data written through that node in the window will carry claim rows under the old key IDs.
**Operator guidance:** after changing a composite unique key on a multi-node deployment, pause writes and allow the cluster to settle for at least one cache-lease TTL before resuming. The cache TTL is the backstop that guarantees every node has reloaded the new descriptor.
The proper fix — acknowledged model-cache invalidation, where the relock waits for every online node to confirm eviction before completing — is a planned cluster enhancement and is out of scope for v0.8.2.
**Scope:** this limitation applies to multi-node postgres only. The memory and sqlite backends are single-process; their cache invalidation is synchronous.
## SEE ALSO
- `config.database` — PostgreSQL is the only multi-node-capable backend
- `config.auth` — `CYODA_HMAC_SECRET` configuration
- `run` — server lifecycle
- `quickstart` — first-run defaults
- `helm` — Kubernetes deployment of multi-node clusters
- `errors` — per-code error reference
## See also
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help quickstart`](/help/quickstart/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memory`, `sqlite`, and `postgres`; authentication modes are `mock` and `jwt`. All configuration is via environment variables with a `CYODA_` prefix.
- [`cyoda help helm`](/help/helm/) — The chart at `deploy/helm/cyoda` deploys cyoda-go on Kubernetes as a StatefulSet backed by an external PostgreSQL database. The chart requires Kubernetes `>=1.31.0`. Chart version: `0.1.0`. App version: `0.1.0` (synchronized to the binary by the `bump-chart-appversion.yml` CI workflow).
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
## Raw formats
- [`/help/cluster.json`](/help/cluster.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/cluster.md`](/help/cluster.md) — body only
---
## help/config.md
# cyoda configuration reference
Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POS…
cyoda-go version 0.8.4
# config
## NAME
config — environment-driven configuration for cyoda.
## SYNOPSIS
All configuration is environment variables prefixed with `CYODA_`. Topics group related variables:
- `config.auth` — IAM mode, JWT issuer, admin controls
- `config.cors` — CORS middleware mode and allowed origins
- `config.database` — storage backend selection, per-backend connection settings
- `config.grpc` — gRPC listener and compute-node credentials
- `config.schema` — schema-extension log tuning
- `config.cluster` — multi-node clustering, gossip, cross-node dispatch
- `config.scheduler` — scheduled-transition scan-loop cadence, distribution, and expiry grace
- `config all` — flat listing of every variable (append `--format=json` for the docs-site JSON)
## DESCRIPTION
### Precedence
Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
### _FILE suffix support
The following variables support the `_FILE` suffix. Setting `CYODA_FOO_FILE=` causes the binary to read the value from the file at ``, trimming trailing whitespace. The `_FILE` variant takes precedence over `CYODA_FOO` when both are set. A set but unreadable `_FILE` path causes immediate startup failure.
- `CYODA_JWT_SIGNING_KEY` / `CYODA_JWT_SIGNING_KEY_FILE`
- `CYODA_HMAC_SECRET` / `CYODA_HMAC_SECRET_FILE`
- `CYODA_BOOTSTRAP_CLIENT_SECRET` / `CYODA_BOOTSTRAP_CLIENT_SECRET_FILE`
- `CYODA_METRICS_BEARER` / `CYODA_METRICS_BEARER_FILE`
### Profile loader
`CYODA_PROFILES` is a comma-separated list of profile names. For each name `N`, a file
`cyoda.N.env` is loaded from the working directory before the process's own environment is
consulted. This supports local development without exporting many variables.
**Example:**
```
CYODA_PROFILES=postgres,otel go run ./cmd/cyoda
```
loads `cyoda.postgres.env` and `cyoda.otel.env` from the working directory.
### Server options
- `CYODA_HTTP_PORT` (int, default: `8080`) — HTTP listen port.
- `CYODA_HTTP_READ_HEADER_TIMEOUT` (duration, default: `10s`) — time allowed to receive a request's headers on the API and admin servers. 0 falls back to `CYODA_HTTP_READ_TIMEOUT`.
- `CYODA_HTTP_READ_TIMEOUT` (duration, default: `5m`) — time allowed to receive a whole request, body included. Does not limit handler execution. 0 disables.
- `CYODA_HTTP_WRITE_TIMEOUT` (duration, default: `0s`) — time from the end of the request headers to the end of the response. Limits handler execution, so it ships disabled; set only if you want the server to cut off long-running requests.
- `CYODA_HTTP_IDLE_TIMEOUT` (duration, default: `2m`) — how long an idle keep-alive connection is held open between requests. 0 falls back to `CYODA_HTTP_READ_TIMEOUT`.
- `CYODA_CONTEXT_PATH` (string, default: `/api`) — URL prefix for all routes.
- `CYODA_ERROR_RESPONSE_MODE` (string, default: `sanitized`) — error detail level: `sanitized` (generic message + ticket UUID for 5xx) or `verbose` (internal error detail included in responses; development use only).
- `CYODA_LOG_LEVEL` (string, default: `info`) — accepted: `debug|info|warn|error`.
- `CYODA_SUPPRESS_BANNER` (bool, default: `false`) — silence startup and mock-auth banners.
- `CYODA_STARTUP_TIMEOUT` (duration, default: `30s`) — deadline for plugin init, TM init, and (cluster mode) the gossip seed-join retry loop.
- `CYODA_DEBUG` — reserved; not currently read by the server.
- `CYODA_MAX_STATE_VISITS` (int, default: `10`) — max visits per state in workflow cascade.
- `CYODA_MODEL_CACHE_LEASE` (duration, default: `5m`) — model cache lease duration; actual expiry is jittered ±10%.
- `CYODA_STATS_GROUP_MAX` (int, default: `10000`) — cardinality ceiling for `POST /api/entity/stats/{entityName}/{modelVersion}/query`. When the grouped-stats result produces more distinct `groupKey` combinations than this value, the request fails with 422 `GROUP_CARDINALITY_EXCEEDED`. Also caps the request `limit` parameter (`limit > max` rejects with 400 `INVALID_LIMIT`). Values `<= 0` are silently clamped to the default (`10000`) — a non-positive cap would disable the ceiling entirely (plugins treat `<= 0` as "unbounded"), defeating the safety net.
### Admin and metrics
- `CYODA_ADMIN_PORT` (int, default: `9091`) — admin port for health and metrics.
- `CYODA_ADMIN_BIND_ADDRESS` (string, default: `127.0.0.1`) — admin listener bind address.
- `CYODA_METRICS_REQUIRE_AUTH` (bool, default: `false`) — require Bearer auth on `/metrics`; startup fails if `true` and `CYODA_METRICS_BEARER` is empty.
- `CYODA_METRICS_BEARER` (string, default: unset) — static Bearer token for `GET /metrics`. Supports `_FILE` suffix.
- `CYODA_OTEL_ENABLED` (bool, default: `false`) — enable OpenTelemetry tracing and metrics.
### Search internals
- `CYODA_SEARCH_SNAPSHOT_TTL` (duration, default: `1h`) — search snapshot TTL.
- `CYODA_SEARCH_REAP_INTERVAL` (duration, default: `5m`) — search snapshot reap interval: how often terminal jobs older than `CYODA_SEARCH_SNAPSHOT_TTL` are deleted. It no longer drives the stale/reclaim sweep — that runs on `CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL`'s ticker instead (see `CYODA_SEARCH_JOB_STALE_AFTER`). This is purely the snapshot-cleanup cadence.
- `CYODA_SEARCH_MAX_SORT_KEYS` (int, default: `16`) — maximum number of `sort` keys per search request. Requests exceeding this cap are rejected with `400 INVALID_FIELD_PATH`. Values `<= 0` are clamped to the default.
- `CYODA_SEARCH_ASYNC_WORKERS` (int, default: `8`) — async-search worker pool size. Config is a QA'd artefact: values `< 1` fail startup rather than being clamped.
- `CYODA_SEARCH_ASYNC_QUEUE` (int, default: `256`) — async-search submit queue capacity beyond the running workers. Once both are exhausted, submission fails with `503 SEARCH_QUEUE_FULL` (retryable). Values `< 0` fail startup.
- `CYODA_SEARCH_ASYNC_MAX_PER_TENANT` (int, default: `8` — tracks `CYODA_SEARCH_ASYNC_WORKERS`) — maximum async-search jobs one tenant may have in flight (queued or running) on a node. Over-cap submissions get the same retryable `503 SEARCH_QUEUE_FULL`, so one tenant's burst cannot fill the shared queue and lock every other tenant out. A tenant may still occupy every worker; it just cannot hold more than this many queue slots. `0` disables the cap. Values `< 0` fail startup.
- `CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL` (duration, default: `15s`) — how often a running async-search executor stamps job liveness and polls for a cross-node cancel/terminal status, starting at submit time (queued or scanning). Config is a QA'd artefact: values `<= 0` fail startup rather than being clamped.
- `CYODA_SEARCH_JOB_STALE_AFTER` (duration, default: `5m`) — how long a `RUNNING` async-search job may go without a heartbeat before the reaper claims it for reclaim (its owning executor most likely crashed or was killed). Config is a QA'd artefact: values below `4 x CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL` fail startup rather than being clamped. The stale/reclaim sweep runs on `CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL`'s ticker (default `15s`) plus once at startup — not on `CYODA_SEARCH_REAP_INTERVAL`, which now drives only the snapshot-TTL reap. A crash therefore hands off within `CYODA_SEARCH_JOB_STALE_AFTER` + one heartbeat interval (~5m15s at defaults); a graceful shutdown or restart releases in-flight jobs immediately, so those hand off within one heartbeat interval — or immediately on the restarted node's own startup sweep. Operational note: on postgres, a node that dies mid-save (inside the `SaveResults` chunk transaction) is reaped by the server's transaction-local idle timeout rather than by this sweep directly, so a mid-save crash's handoff still matches any other crash once that timeout releases the row.
- `CYODA_SEARCH_JOB_MAX_ATTEMPTS` (int, default: `3`) — executions an async-search job may consume before it is failed: the initial run plus one per executor lost without a graceful release. A graceful handoff (release then reclaim) does not count. Config is a QA'd artefact: values `< 1` fail startup rather than being clamped. `1` disables re-execution — a job is failed the first time its executor is lost.
### Cluster and dispatch
See `config.cluster` for multi-node clustering, gossip, and cross-node dispatch variables.
## SEE ALSO
- cli
- run
- config.auth
- config.cors
- config.database
- config.grpc
- config.schema
- config.cluster
## Subtopics
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help config cluster`](/help/config/cluster/) — - `CYODA_CLUSTER_ENABLED` (bool, default: `false`) — enable multi-node clustering.
- `CYODA_NODE_ID` (string, default: unset) — unique node identifier; required when `CYODA_CLUSTER_ENABLED=true`; any non-empty string is accepted.
- `CYODA_NODE_ADDR` (string, default: `http://localhost:8080`) — this node's HTTP base URL; must include scheme (`http://` or `https://`).
- `CYODA_GRPC_NODE_ADDR` (string, default: unset) — this node's gRPC endpoint advertised to peers (`host:port`, no scheme). When set, peers dial this address for cross-node gRPC callback forwarding. When unset, peers derive the gRPC address from this node's HTTP host plus their own `CYODA_GRPC_PORT` (uniform-deployment default).
- `CYODA_GOSSIP_ADDR` (string, default: `:7946`) — gossip protocol listen address; format `[host]:port` — parsed via `net.SplitHostPort`; invalid format causes startup failure.
- `CYODA_GOSSIP_STABILITY_WINDOW` (duration, default: `2s`) — gossip stability window.
- `CYODA_SEED_NODES` (string, default: empty) — comma-separated list of seed node addresses (e.g., `node1.example.com:7946,node2.example.com:7946`); empty means single-node or seed-discovery handled externally.
- `CYODA_HMAC_SECRET` (string, default: unset) — hex-encoded HMAC secret for inter-node dispatch authentication; required when `CYODA_CLUSTER_ENABLED=true`. Supports `_FILE` suffix. Single root secret for gossip encryption, dispatch AEAD, and tx-token signing; no versioned-key rotation — changing it requires a full-cluster stop/start (see the `cluster` help topic, `SECRET ROTATION`).
- `CYODA_PROXY_TIMEOUT` (duration, default: `30s`) — request proxy timeout.
- `CYODA_DISPATCH_WAIT_TIMEOUT` (duration, default: `5s`) — how long the dispatcher polls gossip for a compute member with matching tags.
- `CYODA_DISPATCH_FORWARD_TIMEOUT` (duration, default: `30s`) — HTTP timeout for the cross-node forwarding call.
- `CYODA_TX_TOKEN_TTL` (duration, default: `90s`) — TTL of the signed transaction routing token minted on processor/criteria dispatch; must be ≥ `CYODA_DISPATCH_FORWARD_TIMEOUT` so the token remains valid through the full round-trip and callback verification, including the forwarded-chain case where two budgets stack.
- [`cyoda help config cors`](/help/config/cors/) — config.cors — Cross-Origin Resource Sharing (CORS) controls for the public HTTP surface.
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
- [`cyoda help config grpc`](/help/config/grpc/) — config.grpc — gRPC listener settings and compute-node credentials.
- [`cyoda help config scheduler`](/help/config/scheduler/) — - `CYODA_SCHEDULER_ENABLED` (bool, default: `true`) — kill switch for the coordinator scan loop.
- `CYODA_SCHEDULER_SCAN_INTERVAL` (duration, default: `1s`) — coordinator scan cadence.
- `CYODA_SCHEDULER_BATCH_SIZE` (int, default: `100`) — max due tasks pulled per scan.
- `CYODA_SCHEDULER_DISTRIBUTION` (string, default: `round-robin`) — dispatch-target selection strategy: `round-robin` or `self`. Forced to `self` whenever `CYODA_CLUSTER_ENABLED=false`.
- `CYODA_SCHEDULER_COORDINATOR` (string, default: `lowest-node-id`) — coordinator-election strategy; the member with the lexicographically smallest node ID scans on each tick.
- `CYODA_SCHEDULER_REDISPATCH_BACKOFF` (duration, default: `30s`) — best-effort re-dispatch throttle window applied to a task once it is picked up, so the same due task isn't immediately re-dispatched on the next scan.
- `CYODA_SCHEDULER_EXPIRY_GRACE` (duration, default: `100ms`) — grace band above a scheduled transition's `timeoutMs` before it is expired instead of fired late; size to at least the maximum expected inter-node clock skew.
- [`cyoda help config schema`](/help/config/schema/) — config.schema — schema-extension log tuning.
## See also
- [`cyoda help cli`](/help/cli/) — cyoda is a Go binary that embeds the full platform: API server, schema engine, workflow runner, and storage plugins. Invoked with no subcommand, it starts the server using environment-provided configuration. Subcommands provide operational affordances — `init` for first-run bootstrap, `health` for liveness probes, `migrate` for schema migrations.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help config cors`](/help/config/cors/) — config.cors — Cross-Origin Resource Sharing (CORS) controls for the public HTTP surface.
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
- [`cyoda help config grpc`](/help/config/grpc/) — config.grpc — gRPC listener settings and compute-node credentials.
- [`cyoda help config schema`](/help/config/schema/) — config.schema — schema-extension log tuning.
- [`cyoda help config cluster`](/help/config/cluster/) — - `CYODA_CLUSTER_ENABLED` (bool, default: `false`) — enable multi-node clustering.
- `CYODA_NODE_ID` (string, default: unset) — unique node identifier; required when `CYODA_CLUSTER_ENABLED=true`; any non-empty string is accepted.
- `CYODA_NODE_ADDR` (string, default: `http://localhost:8080`) — this node's HTTP base URL; must include scheme (`http://` or `https://`).
- `CYODA_GRPC_NODE_ADDR` (string, default: unset) — this node's gRPC endpoint advertised to peers (`host:port`, no scheme). When set, peers dial this address for cross-node gRPC callback forwarding. When unset, peers derive the gRPC address from this node's HTTP host plus their own `CYODA_GRPC_PORT` (uniform-deployment default).
- `CYODA_GOSSIP_ADDR` (string, default: `:7946`) — gossip protocol listen address; format `[host]:port` — parsed via `net.SplitHostPort`; invalid format causes startup failure.
- `CYODA_GOSSIP_STABILITY_WINDOW` (duration, default: `2s`) — gossip stability window.
- `CYODA_SEED_NODES` (string, default: empty) — comma-separated list of seed node addresses (e.g., `node1.example.com:7946,node2.example.com:7946`); empty means single-node or seed-discovery handled externally.
- `CYODA_HMAC_SECRET` (string, default: unset) — hex-encoded HMAC secret for inter-node dispatch authentication; required when `CYODA_CLUSTER_ENABLED=true`. Supports `_FILE` suffix. Single root secret for gossip encryption, dispatch AEAD, and tx-token signing; no versioned-key rotation — changing it requires a full-cluster stop/start (see the `cluster` help topic, `SECRET ROTATION`).
- `CYODA_PROXY_TIMEOUT` (duration, default: `30s`) — request proxy timeout.
- `CYODA_DISPATCH_WAIT_TIMEOUT` (duration, default: `5s`) — how long the dispatcher polls gossip for a compute member with matching tags.
- `CYODA_DISPATCH_FORWARD_TIMEOUT` (duration, default: `30s`) — HTTP timeout for the cross-node forwarding call.
- `CYODA_TX_TOKEN_TTL` (duration, default: `90s`) — TTL of the signed transaction routing token minted on processor/criteria dispatch; must be ≥ `CYODA_DISPATCH_FORWARD_TIMEOUT` so the token remains valid through the full round-trip and callback verification, including the forwarded-chain case where two budgets stack.
- [`cyoda help config scheduler`](/help/config/scheduler/) — - `CYODA_SCHEDULER_ENABLED` (bool, default: `true`) — kill switch for the coordinator scan loop.
- `CYODA_SCHEDULER_SCAN_INTERVAL` (duration, default: `1s`) — coordinator scan cadence.
- `CYODA_SCHEDULER_BATCH_SIZE` (int, default: `100`) — max due tasks pulled per scan.
- `CYODA_SCHEDULER_DISTRIBUTION` (string, default: `round-robin`) — dispatch-target selection strategy: `round-robin` or `self`. Forced to `self` whenever `CYODA_CLUSTER_ENABLED=false`.
- `CYODA_SCHEDULER_COORDINATOR` (string, default: `lowest-node-id`) — coordinator-election strategy; the member with the lexicographically smallest node ID scans on each tick.
- `CYODA_SCHEDULER_REDISPATCH_BACKOFF` (duration, default: `30s`) — best-effort re-dispatch throttle window applied to a task once it is picked up, so the same due task isn't immediately re-dispatched on the next scan.
- `CYODA_SCHEDULER_EXPIRY_GRACE` (duration, default: `100ms`) — grace band above a scheduled transition's `timeoutMs` before it is expired instead of fired late; size to at least the maximum expected inter-node clock skew.
## Raw formats
- [`/help/config.json`](/help/config.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config.md`](/help/config.md) — body only
---
## help/config/auth.md
# auth configuration
config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
cyoda-go version 0.8.4
# config.auth
## NAME
config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## SYNOPSIS
cyoda supports two IAM modes: `mock` (development) and `jwt` (production). Configure the
mode via `CYODA_IAM_MODE`. Use `CYODA_REQUIRE_JWT` as a production safety guard to refuse
startup unless JWT mode is properly configured.
## OPTIONS
### IAM mode
- `CYODA_IAM_MODE` — authentication mode: `mock` or `jwt` (default: `mock`)
- `CYODA_REQUIRE_JWT` — production safety floor. When `true`, the binary refuses to
start unless `CYODA_IAM_MODE=jwt` *and* `CYODA_JWT_SIGNING_KEY` are both set.
Prevents accidentally deploying with mock auth enabled. The canonical Helm chart
enables this by default. Desktop and Docker leave it off so the mock-auth fallback
still applies to evaluators. (default: `false`)
### Mock mode (`CYODA_IAM_MODE=mock`)
- `CYODA_IAM_MOCK_ROLES` — comma-separated default user roles assigned to all requests
in mock mode (default: `ROLE_ADMIN,ROLE_M2M`)
- `CYODA_IAM_MOCK_KIND` — principal kind assigned to the default UserContext in
mock mode: `user`, `service`, or `system`. Lets local/CI setups exercise
service- or system-attributed code paths without standing up real JWT auth.
(default: `user`)
When running in mock mode, the binary emits a prominent `MOCK AUTH IS ACTIVE`
warning banner at startup so operators see the security posture of the running
instance. `CYODA_SUPPRESS_BANNER=true` silences both the startup banner and the
mock-auth warning. It is intended only for CI/test harnesses where the warning
is noise — never set it in production, since the banner is the only in-process
signal that requests are unauthenticated.
### JWT mode (`CYODA_IAM_MODE=jwt`)
- `CYODA_JWT_SIGNING_KEY` — RSA private key in PEM format; required in jwt mode
- `CYODA_JWT_SIGNING_KEY_FILE` — file path for `CYODA_JWT_SIGNING_KEY` (takes precedence)
- `CYODA_JWT_ISSUER` — JWT issuer claim (`iss`) (default: `cyoda`)
- `CYODA_JWT_AUDIENCE` — required audience claim (`aud`) on inbound JWTs;
empty string disables the audience check (default: empty)
- `CYODA_JWT_EXPIRY_SECONDS` — token lifetime in seconds (default: `3600`)
- `CYODA_JWT_BOOTSTRAP_AUDIENCE` — audience for the bootstrap signing key
derived from `CYODA_JWT_SIGNING_KEY`. Must be `client` or `human`. The
M2M token-issuance path (`POST /oauth/token`) always uses the
client-audience key. Set to `human` only in deployments where M2M token
issuance is disabled and the bootstrap key signs human tokens through
an external flow. (default: `client`)
### HMAC secret (inter-node dispatch authentication)
- `CYODA_HMAC_SECRET` — hex-encoded HMAC secret for inter-node dispatch auth
- `CYODA_HMAC_SECRET_FILE` — file path for `CYODA_HMAC_SECRET` (takes precedence)
### Bootstrap M2M client
cyoda can provision a machine-to-machine client at startup for automation and CI.
- `CYODA_BOOTSTRAP_CLIENT_ID` — bootstrap M2M client ID (optional)
- `CYODA_BOOTSTRAP_CLIENT_SECRET` — bootstrap M2M client secret; must be set when
`CYODA_BOOTSTRAP_CLIENT_ID` is set (and vice versa)
- `CYODA_BOOTSTRAP_CLIENT_SECRET_FILE` — file path for `CYODA_BOOTSTRAP_CLIENT_SECRET`
(takes precedence)
- `CYODA_BOOTSTRAP_TENANT_ID` — tenant for the bootstrap client (default: `default-tenant`)
- `CYODA_BOOTSTRAP_USER_ID` — user ID for the bootstrap client (default: `admin`)
- `CYODA_BOOTSTRAP_ROLES` — comma-separated roles granted to the bootstrap client
(default: `ROLE_ADMIN,ROLE_M2M`)
### IAM features
These environment variables tune the IAM admin endpoints under `/oauth/keys/*` and `/clients`.
- `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED` — gates all 5 endpoints under
`/oauth/keys/trusted/*`. When `false`, every trusted-key endpoint returns
`404 FEATURE_DISABLED`. (default: `false`)
- `CYODA_IAM_M2M_ADMIN_ROLE_ENABLED` — gates the `withAdminRole=true`
query parameter on `POST /clients`. When `false` (default), that request
shape returns `404` with error code `FEATURE_DISABLED` and no client is
created. When `true`, the created M2M client receives both `ROLE_M2M`
and `ROLE_ADMIN`. Toggling does not affect existing clients. (default: `false`)
- `CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT` — per-tenant cap on registered
trusted keys. Counts only currently-valid keys (active and not past
`validTo`). `0` means unbounded. (default: `10`)
- `CYODA_IAM_TRUSTED_KEY_MAX_VALIDITY_DAYS` — default validity for trusted
keys when the registration request omits `validTo`. No clamp on
user-supplied `validTo` values. (default: `365`)
- `CYODA_IAM_TRUSTED_KEY_MAX_JWK_PROPERTIES` — caps the number of properties
in a registered JWK to guard against absurdly large payloads. (default: `20`)
- `CYODA_IAM_KEYPAIR_DEFAULT_VALIDITY_DAYS` — default validity for both the
bootstrap signing key and runtime-issued keypairs via
`POST /oauth/keys/keypair`. The startup banner emits a `WARN` if the
active bootstrap key expires within 30 days. (default: `365`)
### Auth cache reconciliation
Both per-node auth caches (trusted keys, OIDC providers) push updates to peers
on write and additionally run a periodic KV-reconcile as a backstop against
missed broadcasts. `CYODA_AUTH_CACHE_RECONCILE_INTERVAL` sets that shared
interval; each tick is jittered ±10% to avoid a cross-node reconcile herd. A
cache that goes 10× this interval without a successful reconcile fails closed
on verification rather than serving a potentially stale answer.
- `CYODA_AUTH_CACHE_RECONCILE_INTERVAL` — reconcile interval for both caches
(default: `60s`, floor: `1s`)
### Federated OIDC providers (`POST /oauth/oidc/providers`)
These variables control the federated OIDC provider registration behaviour
(JWT mode only). They apply to all tenants at the process level.
- `CYODA_OIDC_REQUIRE_HTTPS` — when `true`, `POST /oauth/oidc/providers` rejects
any `wellKnownConfigUri` whose scheme is not `https`. Set to `true` in
production to prevent accidental registration of plaintext-HTTP providers.
(default: `true`)
- `CYODA_OIDC_ALLOW_PRIVATE_NETWORKS` — when `true`, the SSRF blocklist check is
bypassed so private-network OIDC providers (e.g. `https://127.0.0.1/...`) can
be registered. Intended for integration tests and local development only.
Never set in production. (default: `false`)
- `CYODA_OIDC_ROLES_CLAIM` — the JWT claim name from which role values are read
for tokens issued by a federated OIDC provider. Overrideable per-provider via
the `rolesClaim` field on the registration or update API. See
`cyoda help auth oidc` for the accepted claim value shapes (string array,
JSON object — keys are roles, space-delimited string). (default: `roles`)
- `CYODA_OIDC_CONNECT_TIMEOUT_MS` — TCP connect timeout in milliseconds for
OIDC discovery and JWKS endpoint fetches. (default: `5000`)
- `CYODA_OIDC_SOCKET_TIMEOUT_MS` — HTTP read timeout in milliseconds for
OIDC discovery and JWKS endpoint fetches. (default: `5000`)
- `CYODA_OIDC_CONNECTION_REQUEST_TIMEOUT_MS` — connection-pool request timeout
in milliseconds for OIDC discovery and JWKS endpoint fetches. (default: `5000`)
### JWT signing keypair rotation
The bootstrap signing key derived from `CYODA_JWT_SIGNING_KEY` (or
`CYODA_JWT_SIGNING_KEY_FILE`) is the default signing key for the
`POST /oauth/token` flow. Its KID is deterministic across nodes sharing
the same PEM (SHA-256 of the public key).
Operators can rotate signing keys at runtime via
`POST /oauth/keys/keypair` (with `algorithm: RS256` and `audience: client`),
optionally setting `invalidateCurrent: true` and
`invalidateGracePeriodSec: N` to overlap the old and new keys.
v0.8.0 limitations:
- Runtime-issued keypairs are held in memory only; they do not survive
process restart. The bootstrap key survives because its KID is derived
deterministically from the PEM input. Persisted signing-key storage is
tracked in a v0.8.x follow-up.
- Bootstrap keys are saved with a finite `validTo` (default 365 days).
After expiry the M2M token-issuance path will return
`404 KEYPAIR_NOT_FOUND` for `getCurrentJwtKeyPair?audience=client`.
Operators should monitor the startup `WARN` and rotate before expiry.
#### Upgrading from v0.7.x
KV-backed trusted-key entries written by versions < v0.8.0 are orphaned.
Within the `trusted-keys` namespace, entries are now keyed `:`
(was bare ``). v0.8.0 does not query the old shape; affected entries are
left in place but not loaded. Operators must re-register affected keys. To audit,
look for entries in the `trusted-keys` namespace whose key contains no `:`
separator (the exact query depends on the KV backend; for the SQLite plugin:
`SELECT key FROM kv_store WHERE namespace='trusted-keys' AND key NOT LIKE '%:%'`).
cyoda-go has no known production users on this surface.
## EXAMPLES
**Development (mock auth):**
```
CYODA_IAM_MODE=mock
CYODA_IAM_MOCK_ROLES=ROLE_ADMIN,ROLE_M2M
```
**Production (JWT auth):**
```
CYODA_IAM_MODE=jwt
CYODA_REQUIRE_JWT=true
CYODA_JWT_SIGNING_KEY_FILE=/etc/secrets/signing.pem
CYODA_JWT_ISSUER=https://auth.example.com
CYODA_JWT_AUDIENCE=cyoda-api
CYODA_JWT_EXPIRY_SECONDS=3600
```
**With bootstrap client:**
```
CYODA_BOOTSTRAP_CLIENT_ID=ci-client
CYODA_BOOTSTRAP_CLIENT_SECRET_FILE=/etc/secrets/ci-secret
CYODA_BOOTSTRAP_ROLES=ROLE_ADMIN,ROLE_M2M
```
**With trusted-key registration enabled:**
```
CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=true
CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT=10
```
**With M2M admin-role grants enabled:**
```
CYODA_IAM_M2M_ADMIN_ROLE_ENABLED=true
```
**With federated OIDC providers (JWT mode):**
```
CYODA_OIDC_REQUIRE_HTTPS=true
CYODA_OIDC_ROLES_CLAIM=roles
```
## SEE ALSO
- config
- run
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/config/auth.json`](/help/config/auth.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/auth.md`](/help/config/auth.md) — body only
---
## help/config/cluster.md
# cyoda cluster & dispatch configuration
- `CYODA_CLUSTER_ENABLED` (bool, default: `false`) — enable multi-node clustering.\n- `CYODA_NODE_ID` (string, default: unset) — unique node identifier; re…
cyoda-go version 0.8.4
# config.cluster
## NAME
config.cluster — multi-node clustering, gossip, and cross-node dispatch env vars.
## DESCRIPTION
- `CYODA_CLUSTER_ENABLED` (bool, default: `false`) — enable multi-node clustering.
- `CYODA_NODE_ID` (string, default: unset) — unique node identifier; required when `CYODA_CLUSTER_ENABLED=true`; any non-empty string is accepted.
- `CYODA_NODE_ADDR` (string, default: `http://localhost:8080`) — this node's HTTP base URL; must include scheme (`http://` or `https://`).
- `CYODA_GRPC_NODE_ADDR` (string, default: unset) — this node's gRPC endpoint advertised to peers (`host:port`, no scheme). When set, peers dial this address for cross-node gRPC callback forwarding. When unset, peers derive the gRPC address from this node's HTTP host plus their own `CYODA_GRPC_PORT` (uniform-deployment default).
- `CYODA_GOSSIP_ADDR` (string, default: `:7946`) — gossip protocol listen address; format `[host]:port` — parsed via `net.SplitHostPort`; invalid format causes startup failure.
- `CYODA_GOSSIP_STABILITY_WINDOW` (duration, default: `2s`) — gossip stability window.
- `CYODA_SEED_NODES` (string, default: empty) — comma-separated list of seed node addresses (e.g., `node1.example.com:7946,node2.example.com:7946`); empty means single-node or seed-discovery handled externally.
- `CYODA_HMAC_SECRET` (string, default: unset) — hex-encoded HMAC secret for inter-node dispatch authentication; required when `CYODA_CLUSTER_ENABLED=true`. Supports `_FILE` suffix. Single root secret for gossip encryption, dispatch AEAD, and tx-token signing; no versioned-key rotation — changing it requires a full-cluster stop/start (see the `cluster` help topic, `SECRET ROTATION`).
- `CYODA_PROXY_TIMEOUT` (duration, default: `30s`) — request proxy timeout.
- `CYODA_DISPATCH_WAIT_TIMEOUT` (duration, default: `5s`) — how long the dispatcher polls gossip for a compute member with matching tags.
- `CYODA_DISPATCH_FORWARD_TIMEOUT` (duration, default: `30s`) — HTTP timeout for the cross-node forwarding call.
- `CYODA_TX_TOKEN_TTL` (duration, default: `90s`) — TTL of the signed transaction routing token minted on processor/criteria dispatch; must be ≥ `CYODA_DISPATCH_FORWARD_TIMEOUT` so the token remains valid through the full round-trip and callback verification, including the forwarded-chain case where two budgets stack.
## SEE ALSO
- config
- run
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/config/cluster.json`](/help/config/cluster.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/cluster.md`](/help/config/cluster.md) — body only
---
## help/config/cors.md
# CORS configuration
config.cors — Cross-Origin Resource Sharing (CORS) controls for the public HTTP surface.
cyoda-go version 0.8.4
# config.cors
## NAME
config.cors — Cross-Origin Resource Sharing (CORS) controls for the public HTTP surface.
## SYNOPSIS
cyoda supports four CORS modes: `disabled`, `loopback` (default), `wildcard`, and `allowlist`.
Configure the mode via `CYODA_CORS_ENABLED` and `CYODA_CORS_ALLOWED_ORIGINS`.
## OPTIONS
- `CYODA_CORS_ENABLED` — enable CORS middleware; set to `false` to disable and handle CORS at
an upstream ingress/proxy layer (default: `true`)
- `CYODA_CORS_ALLOWED_ORIGINS` — comma-separated list of allowed origins, or `*` for wildcard
mode (default: empty — loopback mode)
## MODES
The effective mode is determined by the combination of the two env vars:
- `CYODA_CORS_ENABLED=false` — **disabled** (regardless of `CYODA_CORS_ALLOWED_ORIGINS`)
- `CYODA_CORS_ENABLED=true`, `CYODA_CORS_ALLOWED_ORIGINS` empty — **loopback** (default)
- `CYODA_CORS_ENABLED=true`, `CYODA_CORS_ALLOWED_ORIGINS=*` — **wildcard**
- `CYODA_CORS_ENABLED=true`, `CYODA_CORS_ALLOWED_ORIGINS=https://example.com,...` — **allowlist**
### disabled
CORS middleware is not installed. No `Access-Control-*` headers are emitted. OPTIONS requests
return chi's default 405. Use this when CORS is handled at your ingress layer (nginx, Envoy,
cloud load balancer).
### loopback (default)
Only loopback origins are permitted: `http(s)://localhost`, `http(s)://127.0.0.1`, and
`http(s)://[::1]` on any port. Suitable for local development. Set
`CYODA_CORS_ALLOWED_ORIGINS` to permit additional origins.
### wildcard
`Access-Control-Allow-Origin: *` is emitted for all cross-origin requests. Credentials
(cookies, `Authorization` header) cannot be used with wildcard mode. Appropriate only for
fully public, stateless read APIs.
### allowlist
Only the origins listed in `CYODA_CORS_ALLOWED_ORIGINS` are permitted. Exact scheme+host+port
matching (no wildcards in individual entries). Origins must be absolute URIs with scheme and
host; paths and query strings are not permitted.
## BEHAVIOUR
The following headers are emitted by the CORS middleware when it is installed
(`CYODA_CORS_ENABLED=true`):
**On every response from the installed middleware (preflight, CORS request, or no-`Origin` pass-through):**
- `Vary: Origin` — always appended (never overwrites an existing `Vary` value).
This instructs intermediate caches to key by `Origin` so that a mode change
does not cause a stale no-`Origin` response to be served to an `Origin`-bearing
request.
**Access-Control-Allow-Origin:**
- loopback mode: the matched origin is echoed literally; omitted if no match.
- allowlist mode: the matched origin is echoed literally; omitted if no match.
- wildcard mode: literal `*` for every request, never reflective of `Origin`.
- disabled mode: not emitted.
**On preflight responses only** (`OPTIONS` with `Origin` and
`Access-Control-Request-Method`):
- `Access-Control-Allow-Methods: GET, POST, PUT, PATCH, DELETE, OPTIONS` (static)
- `Access-Control-Allow-Headers: Authorization, Content-Type, traceparent, tracestate` (static)
- `Access-Control-Max-Age: 86400` (static)
These three headers are emitted on every preflight regardless of whether
the origin matched the policy. Only `Access-Control-Allow-Origin` is
omitted when the origin is rejected — a deployer debugging an allowlist
miss will see the static three present alongside the absent ACAO.
**`Access-Control-Allow-Credentials` is NOT emitted in v1.** Authentication is
bearer-in-`Authorization`; cookies and HTTP-auth are not used. Credentials mode
adds attack surface without functional benefit for this auth model.
## TENANT ISOLATION
CORS is a browser-side defence against unauthorized cross-origin reads. It is
**not** a tenant-isolation control. JWT claims and per-request authorization
checks in the data path enforce tenant boundaries. An allowlisted SPA serving
multiple tenants relies entirely on the auth layer, not CORS, to prevent
cross-tenant access. No CORS rule substitutes for or displaces JWT-based authz.
## DEPLOYMENT
**Local dev / docker compose**
No configuration needed. Loopback mode allows `http://localhost`, `http://127.0.0.1`,
and `http://[::1]` on any port by default. Suitable for Vite/webpack dev servers
and local docker-compose SPAs.
**Behind an ingress that handles its own CORS**
Set `CYODA_CORS_ENABLED=false` and configure CORS at the ingress (nginx, Envoy,
cloud load balancer). Do not let both the ingress and cyoda-go emit
`Access-Control-Allow-Origin`: a browser receiving two `Access-Control-Allow-Origin`
values will reject the response.
**Behind a reverse proxy with no CORS handling**
Set `CYODA_CORS_ALLOWED_ORIGINS=https://your.spa.host`. The proxy forwards
requests unchanged; cyoda-go's allowlist middleware emits the correct header
for the matching origin.
## PNA AND CSRF
**Private Network Access (PNA):** cyoda-go does not handle
`Access-Control-Request-Private-Network` / `Access-Control-Allow-Private-Network`.
Deployers needing browsers on a public origin to reach cyoda-go on a private
network should configure PNA at the ingress.
**CSRF:** CSRF is not a threat for bearer-in-header authentication. The SPA
explicitly attaches the bearer on each request rather than relying on ambient
credentials. No anti-CSRF token is required or provided.
## TOGGLING CORS_ENABLED
Toggling `CYODA_CORS_ENABLED` between `true` and `false` requires a
downstream-cache flush. Responses cached during the disabled period lack
`Vary: Origin` and could be served to origins for which the post-toggle policy
disagrees.
## TROUBLESHOOTING
- **Browser logs a CORS error but the service logs the request as `200`** —
the origin was rejected by the allowlist. The middleware omits
`Access-Control-Allow-Origin` and the browser blocks reading the body. Add
the origin to `CYODA_CORS_ALLOWED_ORIGINS` with exact scheme+host+port.
- **Multi-valued `Access-Control-Allow-Origin`** — both the ingress and
cyoda-go are emitting the header. Set `CYODA_CORS_ENABLED=false` and handle
CORS entirely at the ingress.
- **Startup failure: `cors: origin "..." has non-ASCII host; convert to punycode`**
— IDN host names must be supplied in punycode form (`xn--...`).
- **Startup failure: default port rejected** — drop the port from the origin:
use `https://example.com`, not `https://example.com:443`; use `http://example.com`,
not `http://example.com:80`.
- **Startup WARN about wildcard mode** — if wildcard is unintended, set a
specific allowlist with `CYODA_CORS_ALLOWED_ORIGINS=https://your.app.host`.
- **Local SPA on `file://` cannot reach cyoda-go** — `file://` produces
`Origin: null`, which is not auto-allowed in any mode (in wildcard mode,
`null` receives `Access-Control-Allow-Origin: *`, which browsers honour for
non-credentialed requests). Serve the SPA via a local HTTP server (e.g.
`python3 -m http.server`) so a normal `http://localhost` origin is used instead.
## EXAMPLES
**Loopback only (local dev, default):**
```
# nothing to set — loopback is the default when CYODA_CORS_ENABLED=true
```
**Single production origin:**
```
CYODA_CORS_ENABLED=true
CYODA_CORS_ALLOWED_ORIGINS=https://app.example.com
```
**Multiple origins:**
```
CYODA_CORS_ENABLED=true
CYODA_CORS_ALLOWED_ORIGINS=https://app.example.com,https://admin.example.com
```
**Wildcard (public read API):**
```
CYODA_CORS_ENABLED=true
CYODA_CORS_ALLOWED_ORIGINS=*
```
**Disabled (CORS at ingress):**
```
CYODA_CORS_ENABLED=false
```
## SEE ALSO
- config
- run
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/config/cors.json`](/help/config/cors.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/cors.md`](/help/config/cors.md) — body only
---
## help/config/database.md
# database configuration
config.database — storage backend selection and per-backend connection settings.
cyoda-go version 0.8.4
# config.database
## NAME
config.database — storage backend selection and per-backend connection settings.
## SYNOPSIS
Select the backend with `CYODA_STORAGE_BACKEND`. Configure the chosen backend via its
per-backend variables (`CYODA_SQLITE_*` or `CYODA_POSTGRES_*`). The `memory` backend
requires no additional configuration.
## OPTIONS
### Backend selection
- `CYODA_STORAGE_BACKEND` — storage backend to use: `sqlite`, `postgres`, or `memory`
(bare default: `memory`; `cyoda init` writes `CYODA_STORAGE_BACKEND=sqlite` to
`~/.config/cyoda/cyoda.env`, so the effective default after `cyoda init` is `sqlite`)
### SQLite backend (`CYODA_SQLITE_*`)
Used when `CYODA_STORAGE_BACKEND=sqlite`.
- `CYODA_SQLITE_PATH` — path to the SQLite database file (default: `~/.local/share/cyoda/cyoda.db` on Linux/macOS XDG; `%LocalAppData%\cyoda\cyoda.db` on Windows)
- `CYODA_SQLITE_AUTO_MIGRATE` — run embedded SQL migrations on startup (default: `true`)
- `CYODA_SQLITE_BUSY_TIMEOUT` — busy timeout for lock contention (default: `5s`)
- `CYODA_SQLITE_CACHE_SIZE` — SQLite page cache size in KiB, **per connection** (default: `64000`)
- `CYODA_SQLITE_READER_POOL_SIZE` — max concurrent read connections (default: `GOMAXPROCS` clamped to `4`..`8`; minimum 1, and a value below it falls back to the default)
The prefix `CYODA_SQLITE_` is used to namespace all SQLite configuration variables.
**Reader pool and memory.** The page cache is per connection, so resident memory
scales with the pool: the ceiling is `(readers + 1) × CYODA_SQLITE_CACHE_SIZE`
(the writer holds one too) — with the defaults on an 8-CPU host that is
9 × 62.5 MiB ≈ 562 MiB. The pool size derives from `GOMAXPROCS`, which follows
the CPU quota and is blind to the memory limit, so a container that is generous
on cores and tight on memory must set `CYODA_SQLITE_READER_POOL_SIZE` down.
Lower it, not `CYODA_SQLITE_CACHE_SIZE` — that shrinks the writer's cache along
with the readers'. The floor of 4 exists so a small container still keeps an
interactive read off the back of a long streaming scan.
### PostgreSQL backend (`CYODA_POSTGRES_*`)
Used when `CYODA_STORAGE_BACKEND=postgres`.
- `CYODA_POSTGRES_URL` — PostgreSQL connection string, e.g. `postgres://user:pass@host/db`
(required when using postgres backend)
- `CYODA_POSTGRES_URL_FILE` — file path for `CYODA_POSTGRES_URL` (takes precedence)
- `CYODA_POSTGRES_MAX_CONNS` — maximum pool connections (default: `25`)
- `CYODA_POSTGRES_MIN_CONNS` — minimum pool connections (default: `5`)
- `CYODA_POSTGRES_MAX_CONN_IDLE_TIME` — max idle time before closing a connection (default: `5m`)
- `CYODA_POSTGRES_AUTO_MIGRATE` — run embedded SQL migrations on startup (default: `true`)
The prefix `CYODA_POSTGRES_` is used to namespace all PostgreSQL configuration variables.
#### Ceilings
Five limits bound how long the storage layer waits or runs. Each accepts a Go duration
(`30s`, `5m`, `1h`); `0` disables that limit. A malformed value fails startup rather than
falling back to the default — a silently-defaulted ceiling is a silently removed safety
limit.
Two are carried in the connection startup packet, so every pooled connection is bounded
from its first statement:
- `CYODA_POSTGRES_STATEMENT_TIMEOUT` — maximum run time for a single SQL statement (default: `5m`)
- `CYODA_POSTGRES_IDLE_IN_TX_TIMEOUT` — maximum time a connection may sit idle inside an open transaction (default: `5m`)
The other three each bound one path:
- `CYODA_POSTGRES_ACQUIRE_TIMEOUT` — deadline on the wait for a free pooled connection, after which the request fails with `503 STORAGE_UNAVAILABLE`. Applied by the pool, not the server (default: `10s`)
- `CYODA_POSTGRES_MIGRATE_LOCK_TIMEOUT` — maximum lock wait on the migration connection. That connection disables the two ceilings above, so a long index build is not cancelled mid-flight; what stays bounded is waiting (default: `5m`)
- `CYODA_POSTGRES_SEARCH_STATEMENT_TIMEOUT` — statement ceiling applied per async search scan, which legitimately runs far longer than an interactive statement (default: `30m`; `0` disables it, leaving the scan unbounded)
A job that hits the async search ceiling fails with `search exceeded the backend's
async search ceiling — narrow the query, or have the operator raise or disable the
ceiling (see the config.database help topic)`. That ceiling is deliberate operator
configuration and the only bound the server puts on search work: no backend meters
rows or imposes a scan budget of its own. Bounding search **time** is the caller's —
`timeoutMillis` on direct search, job cancellation on async.
`CYODA_POSTGRES_IDLE_IN_TX_TIMEOUT` reclaims a transaction nothing is driving any more.
It must clear the longest legitimate idle gap, which is a compute-node callout bounded by
`responseTimeoutMs` (default `30s`) — set it below that and healthy work is killed
mid-flight. It applies per gap, not per transaction: a cascade writes between callouts,
which restarts the clock, so a long cascade need only keep each gap under the ceiling.
`CYODA_POSTGRES_STATEMENT_TIMEOUT` and `CYODA_POSTGRES_IDLE_IN_TX_TIMEOUT` can also be set
in `CYODA_POSTGRES_URL` (`?statement_timeout=...`). A value there is left alone unless the
environment variable is also set, in which case the environment variable wins and the
override is logged at WARN.
See `cyoda help errors STORAGE_UNAVAILABLE` for what a client sees when a ceiling fires.
### Memory backend
Used when `CYODA_STORAGE_BACKEND=memory`. No additional configuration needed. Data is
not persisted across restarts. Suitable for development and testing only.
## EXAMPLES
**SQLite (default after `cyoda init`):**
```
CYODA_STORAGE_BACKEND=sqlite
CYODA_SQLITE_PATH=/var/data/cyoda.db
CYODA_SQLITE_AUTO_MIGRATE=true
```
**PostgreSQL:**
```
CYODA_STORAGE_BACKEND=postgres
CYODA_POSTGRES_URL=postgres://cyoda:secret@localhost:5432/cyoda
CYODA_POSTGRES_MAX_CONNS=50
```
**In-memory (tests/dev):**
```
CYODA_STORAGE_BACKEND=memory
```
## SEE ALSO
- config
- run
- errors.STORAGE_UNAVAILABLE
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help errors STORAGE_UNAVAILABLE`](/help/errors/storage_unavailable/) — Raised in three cases, all transient:
## Raw formats
- [`/help/config/database.json`](/help/config/database.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/database.md`](/help/config/database.md) — body only
---
## help/config/grpc.md
# grpc configuration
config.grpc — gRPC listener settings and compute-node credentials.
cyoda-go version 0.8.4
# config.grpc
## NAME
config.grpc — gRPC listener settings and compute-node credentials.
## SYNOPSIS
cyoda exposes a gRPC endpoint for compute-node integration. The listener port is configured
via `CYODA_GRPC_PORT`. External compute nodes authenticate with `CYODA_COMPUTE_TOKEN` and
connect to the endpoint specified by `CYODA_COMPUTE_GRPC_ENDPOINT`.
## OPTIONS
### gRPC listener
- `CYODA_GRPC_PORT` — gRPC listen port (default: `9090`)
- `CYODA_KEEPALIVE_INTERVAL` — seconds between server keep-alive pings to each
compute member; also the transport keepalive idle time (default: `10`)
- `CYODA_KEEPALIVE_TIMEOUT` — seconds of inbound silence or write stall before
a compute member is evicted; also the transport keepalive ack timeout
(default: `30`)
### Compute-node client
These variables are used by compute-node clients that connect to a running cyoda instance.
- `CYODA_COMPUTE_GRPC_ENDPOINT` — gRPC endpoint for the compute node to connect to,
e.g. `localhost:9090` (required when running as a compute client)
- `CYODA_COMPUTE_TOKEN` — bearer token for compute-node authentication
(required when running as a compute client)
- `CYODA_COMPUTE_HTTP_BASE` — HTTP base URL of the cyoda instance a compute node
calls back into (e.g. to join the originating transaction); optional, enables
callback-capable processors when set
## EXAMPLES
**Server (default port):**
```
CYODA_GRPC_PORT=9090
```
**Compute node client:**
```
CYODA_COMPUTE_GRPC_ENDPOINT=cyoda.internal:9090
CYODA_COMPUTE_TOKEN=my-token
```
## SEE ALSO
- config
- grpc
- run
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/config/grpc.json`](/help/config/grpc.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/grpc.md`](/help/config/grpc.md) — body only
---
## help/config/scheduler.md
# cyoda scheduled-transition scheduler configuration
- `CYODA_SCHEDULER_ENABLED` (bool, default: `true`) — kill switch for the coordinator scan loop.\n- `CYODA_SCHEDULER_SCAN_INTERVAL` (duration, default: `1s…
cyoda-go version 0.8.4
# config.scheduler
## NAME
config.scheduler — scan-loop cadence, coordinator/distribution strategy, and expiry-grace env vars for the scheduled-transition runtime.
## DESCRIPTION
- `CYODA_SCHEDULER_ENABLED` (bool, default: `true`) — kill switch for the coordinator scan loop.
- `CYODA_SCHEDULER_SCAN_INTERVAL` (duration, default: `1s`) — coordinator scan cadence.
- `CYODA_SCHEDULER_BATCH_SIZE` (int, default: `100`) — max due tasks pulled per scan.
- `CYODA_SCHEDULER_DISTRIBUTION` (string, default: `round-robin`) — dispatch-target selection strategy: `round-robin` or `self`. Forced to `self` whenever `CYODA_CLUSTER_ENABLED=false`.
- `CYODA_SCHEDULER_COORDINATOR` (string, default: `lowest-node-id`) — coordinator-election strategy; the member with the lexicographically smallest node ID scans on each tick.
- `CYODA_SCHEDULER_REDISPATCH_BACKOFF` (duration, default: `30s`) — best-effort re-dispatch throttle window applied to a task once it is picked up, so the same due task isn't immediately re-dispatched on the next scan.
- `CYODA_SCHEDULER_EXPIRY_GRACE` (duration, default: `100ms`) — grace band above a scheduled transition's `timeoutMs` before it is expired instead of fired late; size to at least the maximum expected inter-node clock skew.
## SEE ALSO
- config
- config.cluster
- run
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help config cluster`](/help/config/cluster/) — - `CYODA_CLUSTER_ENABLED` (bool, default: `false`) — enable multi-node clustering.
- `CYODA_NODE_ID` (string, default: unset) — unique node identifier; required when `CYODA_CLUSTER_ENABLED=true`; any non-empty string is accepted.
- `CYODA_NODE_ADDR` (string, default: `http://localhost:8080`) — this node's HTTP base URL; must include scheme (`http://` or `https://`).
- `CYODA_GRPC_NODE_ADDR` (string, default: unset) — this node's gRPC endpoint advertised to peers (`host:port`, no scheme). When set, peers dial this address for cross-node gRPC callback forwarding. When unset, peers derive the gRPC address from this node's HTTP host plus their own `CYODA_GRPC_PORT` (uniform-deployment default).
- `CYODA_GOSSIP_ADDR` (string, default: `:7946`) — gossip protocol listen address; format `[host]:port` — parsed via `net.SplitHostPort`; invalid format causes startup failure.
- `CYODA_GOSSIP_STABILITY_WINDOW` (duration, default: `2s`) — gossip stability window.
- `CYODA_SEED_NODES` (string, default: empty) — comma-separated list of seed node addresses (e.g., `node1.example.com:7946,node2.example.com:7946`); empty means single-node or seed-discovery handled externally.
- `CYODA_HMAC_SECRET` (string, default: unset) — hex-encoded HMAC secret for inter-node dispatch authentication; required when `CYODA_CLUSTER_ENABLED=true`. Supports `_FILE` suffix. Single root secret for gossip encryption, dispatch AEAD, and tx-token signing; no versioned-key rotation — changing it requires a full-cluster stop/start (see the `cluster` help topic, `SECRET ROTATION`).
- `CYODA_PROXY_TIMEOUT` (duration, default: `30s`) — request proxy timeout.
- `CYODA_DISPATCH_WAIT_TIMEOUT` (duration, default: `5s`) — how long the dispatcher polls gossip for a compute member with matching tags.
- `CYODA_DISPATCH_FORWARD_TIMEOUT` (duration, default: `30s`) — HTTP timeout for the cross-node forwarding call.
- `CYODA_TX_TOKEN_TTL` (duration, default: `90s`) — TTL of the signed transaction routing token minted on processor/criteria dispatch; must be ≥ `CYODA_DISPATCH_FORWARD_TIMEOUT` so the token remains valid through the full round-trip and callback verification, including the forwarded-chain case where two budgets stack.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/config/scheduler.json`](/help/config/scheduler.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/scheduler.md`](/help/config/scheduler.md) — body only
---
## help/config/schema.md
# schema configuration
config.schema — schema-extension log tuning.
cyoda-go version 0.8.4
# config.schema
## NAME
config.schema — schema-extension log tuning.
## SYNOPSIS
cyoda maintains a schema-extension log for tracking model schema changes over time. These
variables control savepoint frequency and retry behaviour when extending schemas on storage
backends.
## OPTIONS
- `CYODA_SCHEMA_SAVEPOINT_INTERVAL` — number of schema extensions between savepoint rows in
the schema-extension log (default: `64`, minimum: `1`). Lower values increase write
amplification but reduce recovery time after a crash.
- `CYODA_SCHEMA_EXTEND_MAX_RETRIES` — plugin-layer retry budget for `ExtendSchema` on
backends that support native schema extension with optimistic concurrency
(default: `8`, minimum: `1`). Increase if you observe contention under high concurrency.
The prefix `CYODA_SCHEMA_` is used to namespace all schema-extension configuration variables.
## EXAMPLES
**High-write workload (more frequent savepoints):**
```
CYODA_SCHEMA_SAVEPOINT_INTERVAL=16
CYODA_SCHEMA_EXTEND_MAX_RETRIES=16
```
**Default:**
```
CYODA_SCHEMA_SAVEPOINT_INTERVAL=64
CYODA_SCHEMA_EXTEND_MAX_RETRIES=8
```
## SEE ALSO
- config
- models
- run
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/config/schema.json`](/help/config/schema.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/config/schema.md`](/help/config/schema.md) — body only
---
## help/crud.md
# crud — entity lifecycle API
Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow …
cyoda-go version 0.8.4
# crud
## NAME
crud — entity create, read, update, delete, and transition REST API.
## SYNOPSIS
```
POST /api/entity/{format}/{entityName}/{modelVersion}
POST /api/entity/{format}
GET /api/entity/{entityId}
PUT /api/entity/{format}/{entityId}
PUT /api/entity/{format}/{entityId}/{transition}
PUT /api/entity/{format}
PATCH /api/entity/{format}/{entityId}
PATCH /api/entity/{format}/{entityId}/{transition}
DELETE /api/entity/{entityId}
DELETE /api/entity/{entityName}/{modelVersion}
GET /api/entity/{entityName}/{modelVersion}
GET /api/entity/{entityId}/changes
GET /api/entity/{entityId}/transitions
GET /api/entity/stats
GET /api/entity/stats/states
GET /api/entity/stats/{entityName}/{modelVersion}
GET /api/entity/stats/states/{entityName}/{modelVersion}
POST /api/entity/stats/{entityName}/{modelVersion}/query
GET /api/platform-api/entity/fetch/transitions
```
Context path prefix is `CYODA_CONTEXT_PATH` (default `/api`). All endpoints require `Authorization: Bearer ` except when `CYODA_IAM_MODE=mock`.
## DESCRIPTION
Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
Body size limit on all write endpoints: 10 MiB.
## ENDPOINTS
**POST /api/entity/{format}/{entityName}/{modelVersion}** — Create a single entity
- `format` (path): `JSON` or `XML`
- `entityName` (path): string — model name
- `modelVersion` (path): int32
- `transactionWindow` (query, optional): int32, default `100`, max `1000` — applies only when the request body is a JSON array. Maximum entities per transactional batch. Values outside (0, 1000] are rejected with `400 BAD_REQUEST`. Array bodies exceeding the window are split into multiple transactional batches committed sequentially; each chunk is one transaction. The response is then an array with one element per chunk in commit order; chunks committed before any later failure remain durable.
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
If the request body is a JSON array, each element is treated as a separate entity of the same model and the collection-create chunking contract applies (see `transactionWindow` above and the `POST /api/entity/{format}` partial-success shape below).
Response: `200 OK`, `application/json`. Single-object body returns a one-element array; an array body returns one element per committed chunk in commit order:
```json
[{
"transactionId": "cb91fa80-d4a8-11ee-a357-ae468cd3ed16",
"entityIds": ["74807f00-ed0d-11ee-a357-ae468cd3ed16"]
}]
```
**POST /api/entity/{format}** — Create a collection (mixed models)
- `format` (path): `JSON` or `XML`
- `transactionWindow` (query, optional): int32, default `100`, max `1000` — maximum entities per transactional batch. Values outside (0, 1000] are rejected with `400 BAD_REQUEST`. Collections exceeding the window are split into multiple transactional batches committed sequentially; each chunk is one transaction. The response is an array with one element per chunk in commit order.
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
**IMPORTANT — `payload` is a JSON-encoded string, not an object.**
The `payload` field must be a string containing the JSON-encoded entity body, not a nested JSON object. This is a deliberate API contract — it preserves the payload as an opaque blob through the pipeline.
Correct: `"payload": "{\"category\":\"physics\"}"`
Wrong: `"payload": {"category":"physics"}` (will be rejected with `errors.BAD_REQUEST`)
Request body: JSON array of `CreatePayload` objects:
```json
[
{
"model": { "name": "nobel-prize", "version": 1 },
"payload": "{\"category\":\"physics\",\"year\":\"2024\"}"
}
]
```
Each item may reference a different model. The collection is committed in transactional batches of at most `transactionWindow` items. Within a single chunk the create is all-or-nothing; chunks committed before any later failure remain durable.
Response: `200 OK`, `application/json`, `EntityTransactionResponse` array — one element per committed chunk in commit order:
```json
[{
"transactionId": "cb91fa80-d4a8-11ee-a357-ae468cd3ed16",
"entityIds": [
"74807f00-ed0d-11ee-a357-ae468cd3ed16",
"72428380-0704-11ef-a357-ae468cd3ed16"
]
}]
```
**Partial-success on chunk failure.** If a later chunk fails after earlier chunks have committed, the response is still HTTP 200 carrying the durable chunks plus an error element marking the failed chunk's index. Subsequent chunks are not attempted.
```json
[
{ "transactionId": "tx-0", "entityIds": ["..."] },
{ "transactionId": "tx-1", "entityIds": ["..."] },
{ "error": { "code": "MODEL_NOT_FOUND", "message": "...", "chunkIndex": 2 } }
]
```
When the very first chunk fails (no durable progress), the response is the standard `application/problem+json` 4xx error envelope instead.
**GET /api/entity/{entityId}** — Read a single entity by UUID
- `entityId` (path): UUID string
- `pointInTime` (query, optional): RFC 3339 date-time — load entity state at this instant
- `transactionId` (query, optional): UUID — load entity state as of the end of this transaction
`pointInTime` and `transactionId` are mutually exclusive; supplying both returns `400 BAD_REQUEST`.
Response: `200 OK`, `application/json`:
```json
{
"type": "ENTITY",
"data": { "category": "physics", "year": "2024" },
"meta": {
"id": "74807f00-ed0d-11ee-a357-ae468cd3ed16",
"modelKey": { "name": "nobel-prize", "version": 1 },
"state": "NEW",
"creationDate": "2025-08-01T10:00:00Z",
"lastUpdateTime": "2025-08-01T10:00:00Z",
"transactionId": "cb91fa80-d4a8-11ee-a357-ae468cd3ed16",
"transitionForLatestSave": "loopback"
}
}
```
**PUT /api/entity/{format}/{entityId}** — Update a single entity (loopback transition)
- `format` (path): `JSON` or `XML`
- `entityId` (path): UUID
- `If-Match` (header, optional): transaction ID of last read — optimistic concurrency; if the entity was modified since, returns `412 Precondition Failed`
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
Request body: updated entity JSON/XML payload.
Response: `200 OK`, `application/json`:
```json
{
"transactionId": "733e7180-c055-11ef-a357-ae468cd3ed16",
"entityIds": ["cdcff600-bab1-11ee-a357-ae468cd3ed16"]
}
```
**PUT /api/entity/{format}/{entityId}/{transition}** — Update a single entity with a named transition
- `format` (path): `JSON` or `XML`
- `entityId` (path): UUID
- `transition` (path): string — transition name defined in the model's workflow
- `If-Match` (header, optional): transaction ID
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
Response: `200 OK`, same shape as loopback update.
**PUT /api/entity/{format}** — Update a collection (mixed entities)
- `format` (path): `JSON` (only supported format today; single-item PUT endpoints still accept XML)
- `transactionWindow` (query, optional): int32, default `100`, max `1000` — maximum entities per transactional batch. Values outside (0, 1000] are rejected with `400 BAD_REQUEST`. Collections exceeding the window are split into multiple transactional batches committed sequentially; each chunk is one transaction. The response is an array with one element per chunk in commit order; chunks committed before any later failure remain durable.
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
**IMPORTANT — `payload` is a JSON-encoded string, not an object.**
The `payload` field in each update item must be a string containing the JSON-encoded entity body, not a nested JSON object (same contract as collection create).
Correct: `"payload": "{\"category\":\"physics\"}"`
Wrong: `"payload": {"category":"physics"}` (will be rejected with `errors.BAD_REQUEST`)
Each item may also carry an optional `ifMatch` field — the entity's last-known `meta.transactionId` from a prior read. Items with `ifMatch` get a per-item cross-request optimistic-concurrency precondition: if the entity has been modified since, the item is rejected with `code=ENTITY_MODIFIED` and surfaces in the chunk's `failed` array, **without rolling the chunk back**. Items in the same chunk without `ifMatch` (or with a still-valid one) commit as usual. This mirrors the `If-Match` header on the single-item PUT endpoints, scoped per-item.
Request body: JSON array of update items:
```json
[
{
"id": "8824c480-c166-11ee-9e63-ae468cd3ed16",
"payload": "{\"category\":\"physics\",\"year\":\"2024\"}",
"transition": "UPDATE",
"ifMatch": "733e7180-c055-11ef-a357-ae468cd3ed16"
}
]
```
Failure handling within a chunk:
- **Per-item `ENTITY_MODIFIED` (only when `ifMatch` is supplied):** the item surfaces in `failed[]`; siblings still commit; the chunk's `transactionId` is reported. Per-item ENTITY_MODIFIED conflicts surface inside the `200` response body via the `failed[]` array, **not** as a `4xx` envelope. Inspect `failed[]` to detect them. The `4xx` envelope is reserved for chunk-wide infrastructure failures.
- **Any other per-item failure** (missing entity, validation, non-conflict engine error): the entire chunk rolls back, matching the pre-existing contract. Earlier chunks remain durable; if the first chunk fails the response is a standard `application/problem+json` 4xx envelope.
Each per-item `ENTITY_MODIFIED` is also reflected in the entity's state-machine audit log: the engine emits a paired `STATE_MACHINE_START` plus `TRANSITION_ABORTED` event (with `data.reason = "ENTITY_MODIFIED"`, `data.expectedTxId`, and `data.actualTxId`) so consumers can correlate the failure cleanly without orphaned start events.
Response: `200 OK`, `application/json`, `EntityTransactionResponse` array — one element per committed chunk in commit order. The optional `failed` array is omitted on chunks with no per-item `ENTITY_MODIFIED` failures:
```json
[
{
"transactionId": "733e7180-c055-11ef-a357-ae468cd3ed16",
"entityIds": ["8824c480-c166-11ee-9e63-ae468cd3ed16"],
"failed": [
{
"entityId": "31134900-d9cb-11ee-9e63-ae468cd3ed16",
"error": {
"code": "ENTITY_MODIFIED",
"message": "entity has been modified since last read",
"itemIndex": 1
}
}
]
}
]
```
`itemIndex` is the failing item's zero-based position within its chunk's request slice (per-chunk relative). When every item in a chunk fails its `ifMatch` precondition, the chunk still commits as a zero-write transaction — `entityIds` is empty, `failed[]` lists every item, and `transactionId` remains meaningful for audit correlation.
**PATCH /api/entity/{format}/{entityId}** — Partial update of a single entity (loopback transition)
- `format` (path): `JSON` only — Merge Patch is JSON-only by RFC 7386; `XML` ⇒ `415 Unsupported Media Type`
- `entityId` (path): UUID
- `Content-Type` (header, required): `application/merge-patch+json` (RFC 7386 merge patch, implemented) or `application/json-patch+json` (RFC 6902, returns `501 Not Implemented`); any other value ⇒ `415 Unsupported Media Type`
- `If-Match` (header, required in some form): see the three-state list below
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
Request body: a sparse JSON object (the patch document). The patch is applied to the **stored** entity payload using RFC 7386 merge semantics:
- A key present in the patch with a non-null value overwrites the target key.
- A key whose value is itself an object merges recursively.
- A key present in the patch with an explicit `null` value deletes that key from the stored payload.
- Arrays are replaced wholesale — there are no element-level operations.
- The empty patch `{}` is a valid no-op merge: the data is unchanged, but the request still commits a new transaction and fires the loopback transition (consistent with PUT-with-empty-body).
**If-Match precondition (required).** Unlike `PUT`, where omitting `If-Match` means unconditional replace, PATCH requires `If-Match` to be present in some form, because the merge is applied relative to a base the caller read; silently patching a stale base risks lost updates. The token is the `meta.transactionId` from the caller's last `GET` of this entity — the same field the existing `PUT` `If-Match` uses.
Three states are accepted:
- `If-Match: ""` — Conditional: the stored entity's `transactionId` must still match; returns `412 Precondition Failed` if it has moved since the caller's read.
- `If-Match: *` — Unconditional opt-out: merge onto current state regardless of version (entity must exist); a concurrent-writer race can still surface as `409` (see below).
- Absent — returns `428 Precondition Required`; the response body explains the two valid choices.
Response: `200 OK`, same shape as the single-item PUT update.
**PATCH /api/entity/{format}/{entityId}/{transition}** — Partial update of a single entity with a named transition
- `format` (path): `JSON` only
- `entityId` (path): UUID
- `transition` (path): string — transition name defined in the model's workflow
- `Content-Type` (header, required): same two-value list as the loopback form
- `If-Match` (header, required in some form): same three-state list as the loopback form
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the first commit. Exceeding it rolls back and fails with `408 errors.TRANSACTION_TIMEOUT`; nothing is committed. On a chunked write, only the first chunk is covered — expiry after that surfaces as a `TRANSACTION_TIMEOUT` element in the per-chunk response, not a 408. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
The merge patch is applied first; the named transition's processors then run on the merged state and may further mutate the entity. Response: `200 OK`, same shape as the loopback form.
**Two behaviours to be aware of:**
1. **Strict validation.** The merged result is validated strictly against the model schema — the model is never extended, regardless of its `ChangeLevel`. A PATCH cannot introduce a field that the schema does not already allow, even when the model is in an extend-permitting mode. To add a genuinely new field, use `PUT` (which may extend the schema), then PATCH thereafter.
2. **Processors run after the merge.** Under a named transition, the transition's processors run on the merged entity state and may overwrite fields the patch set. The observable result of a patch with a named transition is not guaranteed to retain the patched values when the transition has mutating processors. This is the same ordering as `PUT` plus a named transition.
**Partial-update error codes:**
- `404 Not Found` — entity does not exist
- `409 Conflict` (retryable) — a concurrent writer committed between the in-transaction base read and this save (read-set conflict at commit); may occur even with `If-Match: *`; caller may retry
- `412 Precondition Failed` — `If-Match: ""` supplied and the stored `transactionId` differs; see `errors.ENTITY_MODIFIED`
- `415 Unsupported Media Type` — `XML` format, or a `Content-Type` other than the two patch media types
- `428 Precondition Required` — no `If-Match` header present
- `501 Not Implemented` — `Content-Type: application/json-patch+json` (RFC 6902 is recognised but not yet implemented)
- Standard `4xx` domain errors — the **merged result** fails strict schema validation (full domain detail + error code)
**DELETE /api/entity/{entityId}** — Delete a single entity by UUID
- `entityId` (path): UUID
Response: `200 OK`, `application/json`:
```json
{
"id": "a2242880-8d30-11ef-9e63-ae468cd3ed16",
"modelKey": {
"name": "nobel-prize",
"version": 4
},
"transactionId": "9fe62d00-a727-11ef-9e63-ae468cd3ed16"
}
```
**DELETE /api/entity/{entityName}/{modelVersion}** — Delete entities for a model (conditional)
- `entityName` (path): string
- `modelVersion` (path): int32
- `transactionSize` (query, optional): int32 — when set, matched entities (including a delete-all with no condition) are deleted in version-guarded batches of this size instead of one transaction. Batches already committed stay durable if a later batch fails. A per-id version mismatch (the entity changed after selection) or a batch's commit failure is reported per-id in `deleteResult.idToError`, not retried. Rejected with `400` on a request that joins an open transaction. Absent means a single transaction. Without `pointInTime`, the batched delete re-selects before each batch; if matching entities keep being created it is stopped at its batch cap and fails `409 DELETE_NOT_CONVERGED` (retryable), with the batches already committed left deleted.
- `pointInTime` (query, optional): RFC 3339 — select the entities that existed at this instant (committed state; the ambient transaction is ignored) and delete their current rows. Absent means the current committed state. An entity selected at the instant but already gone is reported in `deleteResult.idToError`.
- `verbose` (query, optional): boolean, default `false` — when `true`, the response `ids` array lists every entity ID the delete attempted (an empty body lists them too); an ID whose delete failed also appears in `deleteResult.idToError`; on a large model this enumerates every entity of the model in one response.
Request body: optional `AbstractConditionDto` (same condition DSL as `/search/*`). When the body is absent or empty, all entities of the model are deleted.
Response: `200 OK`, `application/json`:
```json
{
"entityModelClassId": "022d9200-0cf0-11ef-9e63-ae468cd3ed16",
"ids": ["ffef9680-26e6-11ef-9e63-ae468cd3ed16"],
"deleteResult": {
"numberOfEntitites": 4,
"numberOfEntititesRemoved": 3,
"idToError": {
"cecbe400-7402-11ef-9e63-ae468cd3ed16": "Some error message"
}
}
}
```
`deleteResult.numberOfEntitites` is the count of entities matched by the condition (or total when no condition). `deleteResult.numberOfEntititesRemoved` is the count actually removed (may be lower if individual deletes failed). Returns `400 INVALID_CONDITION` on a malformed condition body.
**GET /api/entity/{entityName}/{modelVersion}** — List all entities for a model (paginated)
- `entityName` (path): string
- `modelVersion` (path): int32
- `pageSize` (query, optional): int32, default `20`
- `pageNumber` (query, optional): int32, default `0`
- `pointInTime` (query, optional): RFC 3339 — return entities as they existed at this instant (as-at, inclusive)
Response: `200 OK`, `application/json`, array of entity envelopes (same shape as single-entity GET). Returns `404 MODEL_NOT_FOUND` when the model is not registered for the calling tenant. Order is stable and deterministic; the specific order is storage-engine-specific (entity-ID based) — see `docs/plugins/*.md` for each backend's canonical order.
**GET /api/entity/{entityId}/changes** — Get entity change history metadata
- `entityId` (path): UUID
- `pointInTime` (query, optional): RFC 3339 — view history as it existed at this time
Response: `200 OK`, `application/json`, array of change entries in reverse-chronological order (newest first):
```json
[
{
"changeType": "UPDATE",
"timeOfChange": "2025-08-02T09:00:00Z",
"user": "admin",
"transactionId": "733e7180-c055-11ef-a357-ae468cd3ed16"
},
{
"changeType": "CREATE",
"timeOfChange": "2025-08-01T10:00:00Z",
"user": "admin",
"transactionId": "cb91fa80-d4a8-11ee-a357-ae468cd3ed16"
}
]
```
- `changeType`: `CREATE`, `UPDATE`, or `DELETE`
- `transactionId`: present only when `hasEntity` is true (i.e., entity payload exists at that version)
**GET /api/entity/{entityId}/transitions** — List available transitions for an entity
- `entityId` (path): UUID
- `pointInTime` (query, optional): RFC 3339
- `transactionId` (query, optional): UUID — derive point-in-time from transaction submit time. The transaction must belong to the caller's tenant; an unknown or foreign transaction ID returns `400 BAD_REQUEST`.
`pointInTime` and `transactionId` are mutually exclusive; supplying both returns `400 BAD_REQUEST`. When neither is provided, the current time is used.
Response: `200 OK`, `application/json`, array of available transition names (as returned by the workflow engine).
The names come from the workflow the entity's criterion selects — the same definition a subsequent transition will run (see `cyoda help workflows`, *Workflow-level selection*). Because selection is evaluated here, this read carries the same failure modes as a write: `400 WORKFLOW_FAILED` when a criterion cannot be evaluated, `503 NO_COMPUTE_MEMBER_FOR_TAG` when the cause is specifically an unavailable compute member for a `function` criterion's tags. The request fails rather than answering from a different workflow. The read records no audit events.
**GET /api/platform-api/entity/fetch/transitions** — List available transitions (platform-api format)
- `entityClass` (query, required): string in `Name.Version` format, e.g., `Offer.1`
- `entityId` (query, required): UUID string
Response: `200 OK`, `application/json`, array of available transition names.
**GET /api/entity/stats** — Entity count statistics across all models
Response: `200 OK`, `application/json`:
```json
[
{ "modelName": "nobel-prize", "modelVersion": 1, "count": 42 },
{ "modelName": "family-member", "modelVersion": 3, "count": 7 }
]
```
**GET /api/entity/stats/states** — Entity count by state across all models
- `states` (query, optional): comma-separated list of state names to filter by; maximum 1000 entries
Response: `200 OK`, `application/json`:
```json
[
{ "modelName": "nobel-prize", "modelVersion": 1, "state": "NEW", "count": 10 },
{ "modelName": "nobel-prize", "modelVersion": 1, "state": "APPROVED", "count": 32 }
]
```
**GET /api/entity/stats/{entityName}/{modelVersion}** — Entity count for a specific model
- `entityName` (path): string
- `modelVersion` (path): int32
Response: `200 OK`, `application/json`, single `ModelStatsDto`. Returns `404 MODEL_NOT_FOUND` when the model is not registered for the calling tenant.
**GET /api/entity/stats/states/{entityName}/{modelVersion}** — Entity count by state for a specific model
- `entityName` (path): string
- `modelVersion` (path): int32
- `states` (query, optional): list of state names to filter by; maximum 1000 entries
Response: `200 OK`, `application/json`, array of `ModelStateStatsDto`. Returns `404 MODEL_NOT_FOUND` when the model is not registered for the calling tenant.
**POST /api/entity/stats/{entityName}/{modelVersion}/query** — Grouped statistics with optional aggregations
Returns aggregate counts (and optional `sum`/`avg`/`min`/`max`/`stdev`) grouped by entity data fields and/or lifecycle state. Restricts the population by an optional `Condition` DSL predicate (same shape as `/search/*` — see the `search` topic). Supports `pointInTime` historical snapshots.
- `entityName` (path): string
- `modelVersion` (path): int32
Request body: `application/json`. Body size limit: 10 MiB (shared with `/search/*`).
```json
{
"groupBy": ["$.variantId", "state"],
"condition": { "type": "lifecycle", "field": "state", "operatorType": "NOT_EQUAL", "value": "shipped" },
"aggregations": [
{ "op": "sum", "field": "$.costPrice", "as": "totalCost" },
{ "op": "avg", "field": "$.costPrice" },
{ "op": "stdev", "field": "$.costPrice" }
],
"pointInTime": "2026-06-14T12:00:00Z",
"limit": 100
}
```
Request fields:
- `groupBy` (required, 1..N entries): each entry is the reserved token `"state"` or a scalar JSONPath (with the required `$.` leader). Order in the request determines order in the response's `groupKey` array. Duplicate entries → 400 `DUPLICATE_GROUP_BY`. A path outside the grammar below → 400 `INVALID_GROUP_BY_PATH`.
- `condition` (optional): the existing search `Condition` DSL (SimpleCondition, LifecycleCondition, GroupCondition with `AND`/`OR`/`NOT`, ArrayCondition). Omitted → match-all. A FunctionCondition at any depth → 400 `INVALID_CONDITION`; it is a criterion shape, not a search shape. See the `search` topic for the full DSL.
- `aggregations` (optional, 0..N): per entry, `op` ∈ {`sum`, `avg`, `min`, `max`, `stdev`}; `field` is a scalar JSONPath into the entity payload; optional `as` alias for the response key. When `as` is omitted the server synthesizes `_` with the leading `$.` stripped from the field (for example, `field: "$.costPrice"` → alias `sum_costPrice`). The server dedupes identical `(op, field)` pairs. Two aliases colliding on distinct `(op, field)` pairs → 400 `DUPLICATE_AGGREGATION_ALIAS`.
- `pointInTime` (optional RFC 3339): historical snapshot; default = now.
- `limit` (optional positive int): top-N. Must be `≤ CYODA_STATS_GROUP_MAX` (default 10000); `> CYODA_STATS_GROUP_MAX` → 400 `INVALID_LIMIT`. Default = unlimited (up to the cardinality ceiling).
Response: `200 OK`, `application/json`, array of `GroupedStatsBucket`:
```json
[
{
"groupKey": [
{ "path": "$.variantId", "value": "1111" },
{ "path": "state", "value": "available" }
],
"count": 812,
"aggregations": { "totalCost": 41200.00, "avg_costPrice": 50.74, "stdev_costPrice": 18.42 }
},
{
"groupKey": [
{ "path": "$.variantId", "value": null },
{ "path": "state", "value": "available" }
],
"count": 3,
"aggregations": { "totalCost": null, "avg_costPrice": null, "stdev_costPrice": null }
}
]
```
Each bucket's `aggregations` map is keyed by either the explicit `as` alias or the synthesized `_` label. The `aggregations` map is omitted entirely when the request supplied no aggregations.
Sort order is backend-independent: primary key is `count` descending; tiebreaker is `groupKey` lex order (element-wise; `null` sorts before any string; strings compared bytes-wise).
**JSONPath grammar.** Every JSONPath in `groupBy` and aggregation `field` is scalar-only, and is checked at the API boundary — before any storage backend runs — against:
```
path = "$." segment ( "." segment )*
segment = 1*( ALPHA / DIGIT / "_" / "-" ) ; ASCII only
```
The `$.` leader is **required**: these are JSON Paths, and a bare `variantId` is not one. Everything outside the grammar is rejected with 400 `INVALID_GROUP_BY_PATH` (for `groupBy`) or 400 `INVALID_AGGREGATION_FIELD` (for aggregations): a missing leader, bracket-quoted property access (`$['country']`, `$.['country']` — write `$.country`), array subscripts of any form (`$.items[*]`, `$.items[0]`), recursive descent (`$..name`), filter expressions, leading/trailing/doubled dots, `$` on its own, whitespace, quotes, control bytes, and non-ASCII characters. There is no dotted spelling for an array position either: `$.items.0` is a valid path, but it names the field literally called `0` inside `items` — a field name may be entirely digits — not an array element. An array position is not addressable by `groupBy` or an aggregation `field` at all; group or aggregate on a scalar path instead.
This is the same grammar every storage backend enforces on its own query paths, so a request is accepted or rejected identically whichever execution path it takes. A `condition`'s `jsonPath` obeys a superset of this grammar: it additionally permits array subscripts (`$.items[*]`, `$.items[0]`), which a storage backend pushes down where it can and otherwise evaluates itself — see `cyoda help search`. A path is validated, never rewritten: the response's `groupKey` path echoes exactly what the request sent.
The reserved token `"state"` is accepted in `groupBy` only; it is a token, not a path, so it has no leading `$.` and refers to lifecycle state. There is no defined aggregate over lifecycle state, so `"state"` as an aggregation `field` is just an identifier missing its leader and is rejected.
**Aggregation operators.** Five operators: `sum`, `avg`, `min`, `max`, `stdev`. `stdev` is the sample standard deviation (divisor `n − 1`); when `n < 2`, the value is `null` on both the pushdown and streaming paths. `sum`, `avg`, and `stdev` treat non-numeric and absent field values as NULL (the value is skipped, not zero). `min` and `max` are lexicographic over text values and numeric over numeric values; the comparison ordering matches the underlying backend's collation for the pushed-down path.
**Numeric coercion on postgres.** The postgres backend wraps every numeric aggregation argument in the `cyoda_try_float8(text)` SQL function (shipped as a built-in migration). The behavior is exhaustive:
- Empty string → NULL.
- Strict-numeric string matching `-?[0-9]+(\.[0-9]+)?([eE][-+]?[0-9]+)?` and within `float8` range → parsed `float8`.
- Strict-numeric string that overflows `float8` (for example `1e500`) → NULL (the value would be `Infinity`; stripped by an outer `NULLIF`).
- `NaN`, `Infinity`, `-Infinity`, `inf` → NULL (not strict-numeric per the regex above).
- Any other non-numeric string (`"n/a"`, `"unknown"`, etc.) → NULL.
The function is `IMMUTABLE PARALLEL SAFE` (the planner inlines and parallelizes). NULL values are skipped by `SUM`/`AVG`/`STDDEV_SAMP` per standard SQL semantics. A single dirty value does not abort the query.
**Non-scalar runtime values.** When a `groupBy` JSONPath resolves to a JSON object or array at runtime, the bucket key for that dimension is `null`. Numbers and booleans group by their canonical text representation (for example the integer `42` and the string `"42"` both bucket under `"42"`).
**In-transaction behavior.** Calls made under an active transaction (the request carried a transaction context) route through the streaming-tally path via `EntityStore.Iterate`. The native `GroupedAggregator` pushdown is skipped in this case to preserve read-your-writes semantics. Per backend:
- **memory and sqlite** — Inside a transaction, sqlite streams one merged cursor (committed snapshot on the reader connection plus the transaction's own buffered writes, staged deletes suppressed); memory walks a pointer snapshot of the merged view. Neither copies entity payloads beyond the rows it yields, and `trackingRead` records only yielded rows. Non-tx, non-PIT sqlite queries the live `entities` table directly with `planQuery` WHERE-pushdown (no snapshot involved); non-tx with `pointInTime` queries `entity_versions` with `submit_time <= pointInTime` to read the historical snapshot. In-tx with `pointInTime` falls through to the plain PIT path — reads `entity_versions` at the supplied snapshot WITHOUT applying the tx-buffer overlay; PIT is historical-read by definition, so the in-flight buffer is a documented limitation, and the result reflects committed history rather than the caller's uncommitted edits at the requested instant. The fully-pushed-down `GroupedAggregate` query (against `entities`) is skipped in-tx by the SPI dispatcher so the service falls through to the streaming tally over `Iterate`, which now honours RYW.
- **postgres** — `Iterate` selects from the bi-temporal `entity_versions` table with `valid_time <= tx.SnapshotTime AND transaction_time <= CURRENT_TIMESTAMP`, and adds `(doc->'_meta'->>'deleted')::boolean IS NOT TRUE` to skip deletion-marker versions. The `GroupedAggregate` pushdown is skipped in-tx.
**Cardinality ceiling.** `CYODA_STATS_GROUP_MAX` (default 10000) bounds the number of distinct group buckets the endpoint will produce. When the result would exceed the ceiling, the request fails with 422 `GROUP_CARDINALITY_EXCEEDED` (retry with a more selective `condition` or fewer `groupBy` dimensions). The same value caps the request `limit`: `limit > CYODA_STATS_GROUP_MAX` is rejected up-front with 400 `INVALID_LIMIT`.
**Index guidance — postgres.**
- **State grouping/filtering on the non-tx pushdown path is index-backed out of the box.** The shipped migration creates `entities_state_idx` on `(tenant_id, model_name, model_version, (doc->'_meta'->>'state')) WHERE NOT deleted`. Queries grouping by or filtering on `state` use this index without operator action.
- **In-tx and `pointInTime` paths are not covered.** Those read from `entity_versions`, not `entities`. The state index does not apply. Add expression indexes on `entity_versions` if perf demands.
- **Hot data-field dimensions** (the dimensions that appear most often in `groupBy` and `condition`) are caller responsibility on the non-tx path. Example for `variantId`:
```sql
CREATE INDEX entities_variantid_idx
ON entities (tenant_id, model_name, model_version, (doc->>'variantId'))
WHERE NOT deleted;
```
**Index guidance — sqlite.** The shipped schema indexes `(tenant_id, model_name, model_version)` covering the WHERE-clause prefix. For hot grouping dimensions, add expression indexes on the JSON path:
```sql
CREATE INDEX entities_variantid_idx
ON entities (json_extract(data, '$.variantId'));
```
**Memory backend cost.** The snapshot walk is `O(tenant entities)`, not `O(model entities)` — the underlying map is keyed `tenantID → entityID → versions` and is not partitioned by model. A tenant with many models pays a constant per-request walk cost proportional to all their entities, even when querying one model. Relevant for operators running memory-backed deployments with many models per tenant.
Error codes (response carries RFC 9457 problem+json with `properties.errorCode` set to the machine-readable code below):
- `MODEL_NOT_FOUND` — `404` — model not registered for the calling tenant
- `MALFORMED_REQUEST` — `400` — body unreadable, not valid JSON, carrying an unrecognised top-level field (decoding is strict), or carrying a `pointInTime` that is not RFC 3339
- `MISSING_GROUP_BY` — `400` — `groupBy` empty or missing
- `INVALID_GROUP_BY_PATH` — `400` — `groupBy` JSONPath outside the grammar above (missing `$.` leader, bracket-quoted access, array projection, recursive descent, disallowed character)
- `DUPLICATE_GROUP_BY` — `400` — duplicate `groupBy` entries
- `INVALID_AGGREGATION_OP` — `400` — `op` outside the set {`sum`, `avg`, `min`, `max`, `stdev`}
- `INVALID_AGGREGATION_FIELD` — `400` — aggregation `field` outside the same JSONPath grammar
- `DUPLICATE_AGGREGATION_ALIAS` — `400` — two aliases collide on distinct `(op, field)` pairs
- `INVALID_CONDITION` — `400` — `condition` malformed, unknown `type`, `operatorType` outside the canonical list, malformed `LIKE` or `MATCHES_PATTERN` operand, or bad `BETWEEN` arity (propagated from search validator)
- `INVALID_FIELD_PATH` — `400` — a `condition` `jsonPath` is not valid JSON Path, names an unknown meta field, or is absent from the locked schema (propagated from search validator)
- `CONDITION_TYPE_MISMATCH` — `400` — `condition` value type incompatible with the locked DataType (propagated from search validator)
- `INVALID_LIMIT` — `400` — `limit` non-positive or `> CYODA_STATS_GROUP_MAX`
- `GROUP_CARDINALITY_EXCEEDED` — `422` — result buckets would exceed `CYODA_STATS_GROUP_MAX`
- Standard `401` (missing/invalid Bearer), `403` (authenticated but not authorized), `413` (body exceeds 10 MiB), `500` (internal/driver error with ticket UUID; full detail logged server-side) apply as elsewhere.
## POINT-IN-TIME SEMANTICS
A `pointInTime` read returns entity state **as at exactly that instant,
inclusive**: a version whose write timestamp equals `pointInTime` is included
(`<=`), and no rounding is applied to the requested time. The bound is compared
against stored version timestamps at the storage engine's native precision.
Behaviour is identical across every read path — single-entity read, list,
search, grouped statistics, change history, and available transitions — and
across storage backends. Because backends store timestamps at different
precisions (down to milliseconds on some deployments), cross-backend results are
guaranteed to agree at **millisecond granularity**; finer-grained ordering
within a single millisecond is backend-defined. Timestamps are accepted and
emitted as RFC 3339 with full fractional precision.
## ENTITY ENVELOPE
All entity read operations return entities in the standard envelope:
```json
{
"type": "ENTITY",
"data": { ... },
"meta": {
"id": "74807f00-ed0d-11ee-a357-ae468cd3ed16",
"modelKey": { "name": "nobel-prize", "version": 1 },
"state": "NEW",
"creationDate": "2025-08-01T10:00:00.000000000Z",
"lastUpdateTime": "2025-08-01T10:00:00.000000000Z",
"pointInTime": "2025-08-01T10:00:00Z",
"transactionId": "cb91fa80-d4a8-11ee-a357-ae468cd3ed16",
"transitionForLatestSave": "UPDATE"
}
}
```
- `type` — always `"ENTITY"`
- `data` — the entity's JSON payload (decoded with `json.Number` for numeric precision)
- `meta.id` — UUID string
- `meta.modelKey` — object with `name` (string) and `version` (int32) identifying the model; present on all entity reads (single-get, list, search).
- `meta.state` — current workflow state string
- `meta.creationDate` — RFC 3339 with nanoseconds
- `meta.lastUpdateTime` — RFC 3339 with nanoseconds; equals `creationDate` if never updated
- `meta.pointInTime` — the as-at point-in-time for which the entity was retrieved, when supplied
- `meta.transactionId` — present when a transaction ID exists
- `meta.transitionForLatestSave` — transition name that produced the latest save. Valid values: `"loopback"` (loopback update with no transition supplied by the client) or the named transition string. **Known bug:** the server currently stores the literal `"workflow"` for engine-driven initial-state writes; there is no valid `"workflow"` value and this is tracked for fix.
## OPTIMISTIC CONCURRENCY
Entity writes are protected by two independent guards:
1. **Transaction-level (always on):** every write runs under Snapshot Isolation with first-committer-wins (SI+FCW) read-set validation at commit time. A concurrent committer who changes an entity this transaction read will cause this transaction to abort at commit with `409 CONFLICT, retryable: true` (see `errors.CONFLICT`). On the postgres backend, PostgreSQL's own SQLSTATE 40001 detection (under `REPEATABLE READ`) covers write-write races equivalently. Callers do not opt in to this; it cannot be disabled.
2. **Cross-request precondition (opt-in via `If-Match`):** the `If-Match` header carries the `meta.transactionId` from the caller's earlier read in a separate HTTP request. If the entity's current `meta.transactionId` does not match, the server returns `412 Precondition Failed` (see `errors.ENTITY_MODIFIED`). This catches the race window between the caller's GET and PUT — a window the transaction-level guard cannot see, because the GET and PUT happen in different transactions.
To use the cross-request precondition: read the entity (`GET /entity/{id}`), note `meta.transactionId`, include it in `If-Match` on the subsequent update. Omitting `If-Match` does not turn off transaction-level conflict detection, but it does mean the PUT will reconcile against whatever state the entity has at PUT-time — including any concurrent commits that happened between the caller's GET and PUT.
See `cyoda help errors ENTITY_MODIFIED` for the recovery flow on a `412`.
## ERRORS
- `errors.ENTITY_NOT_FOUND` — `404` — entity UUID does not exist
- `errors.ENTITY_MODIFIED` — `412` — `If-Match`-guarded update rejected; supplied transaction ID does not match the entity's current version
- `errors.MODEL_NOT_FOUND` — `404` — model referenced during create does not exist
- `errors.MODEL_NOT_LOCKED` — `409` — model exists but is not in `LOCKED` state; entities cannot be created until the model is locked
- `errors.VALIDATION_FAILED` — `400` — payload fails schema validation against the model
- `errors.INCOMPATIBLE_TYPE` — `400` — entity payload's leaf value type is not assignable to the schema's declared DataType for that field; carries `fieldPath`, `expectedType`, `actualType` in `properties`
- `errors.CONFLICT` — `409` — storage-level transaction serialization conflict (retryable)
- `errors.IDEMPOTENCY_CONFLICT` — `409` — reserved; not yet implemented. Future contract: returned on collection create/update when the `Idempotency-Key` header is re-used with a different payload body
- `errors.UNIQUE_VIOLATION` — `409` — a declared composite unique key already holds this field-value combination
- `errors.INVALID_UNIQUE_KEY` — `422` — a unique-key field is null, missing, or has an out-of-range value
- `errors.TRANSITION_NOT_FOUND` — `400` — named transition does not exist in the workflow
- `errors.WORKFLOW_FAILED` — `400` — the workflow engine rejected the operation: a transition criterion did not match, a processor failed, the workflow selected for the entity does not declare its current state, or a workflow selection criterion could not be evaluated. Reachable on create, a named transition, a transition-less (loopback) update, and both transitions reads — selection runs on every door
- `errors.NO_COMPUTE_MEMBER_FOR_TAG` — `503` — retryable — a `function` criterion or processor needs a compute member for its tags and none is connected. Reachable on the transitions reads too, since they evaluate workflow selection criteria
- `errors.BAD_REQUEST` — `400` — malformed request, invalid UUID, conflicting query parameters, states filter exceeds 1000 entries
- Grouped-stats query (`POST /api/entity/stats/{entityName}/{modelVersion}/query`) — `404 MODEL_NOT_FOUND` when the model is not registered for the calling tenant; `400` for validation failures (`MALFORMED_REQUEST`, `MISSING_GROUP_BY`, `INVALID_GROUP_BY_PATH`, `DUPLICATE_GROUP_BY`, `INVALID_AGGREGATION_OP`, `INVALID_AGGREGATION_FIELD`, `DUPLICATE_AGGREGATION_ALIAS`, `INVALID_LIMIT`); `400` propagated from the search-condition validator (`INVALID_CONDITION`, `INVALID_FIELD_PATH`, `CONDITION_TYPE_MISMATCH`); `422 GROUP_CARDINALITY_EXCEEDED` when distinct buckets would exceed `CYODA_STATS_GROUP_MAX`. The full enumeration with descriptions is in the grouped-stats endpoint section above.
## EXAMPLES
**Create a single entity:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"category":"physics","year":"2024"}' \
"http://localhost:8080/api/entity/JSON/nobel-prize/1"
```
**Read an entity:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/74807f00-ed0d-11ee-a357-ae468cd3ed16"
```
**Read an entity at a point in time:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/74807f00-ed0d-11ee-a357-ae468cd3ed16?pointInTime=2025-08-01T10:00:00Z"
```
**Update an entity with loopback transition:**
```
curl -s -X PUT \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-H "If-Match: cb91fa80-d4a8-11ee-a357-ae468cd3ed16" \
-d '{"category":"chemistry","year":"2024"}' \
"http://localhost:8080/api/entity/JSON/74807f00-ed0d-11ee-a357-ae468cd3ed16"
```
**Update an entity with a named transition:**
```
curl -s -X PUT \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"category":"chemistry","year":"2024"}' \
"http://localhost:8080/api/entity/JSON/74807f00-ed0d-11ee-a357-ae468cd3ed16/APPROVE"
```
**Delete a single entity:**
```
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/74807f00-ed0d-11ee-a357-ae468cd3ed16"
```
**Delete entities for a model (all, or filtered by condition):**
```
# Delete all entities for the model:
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/nobel-prize/1"
# Delete only VALIDATED entities and list the attempted IDs:
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"type":"lifecycle","field":"state","operatorType":"EQUALS","value":"VALIDATED"}' \
"http://localhost:8080/api/entity/nobel-prize/1?verbose=true"
```
**List all entities for a model (page 0, size 20):**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/nobel-prize/1?pageSize=20&pageNumber=0"
```
**Get entity change history:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/74807f00-ed0d-11ee-a357-ae468cd3ed16/changes"
```
**Get available transitions:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/74807f00-ed0d-11ee-a357-ae468cd3ed16/transitions"
```
**Create a multi-model collection:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '[{"model":{"name":"nobel-prize","version":1},"payload":"{\"category\":\"physics\",\"year\":\"2024\"}"}]' \
"http://localhost:8080/api/entity/JSON"
```
**Get statistics by state for a model:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/entity/stats/states/nobel-prize/1"
```
**Grouped statistics — count by state and country, with sum/avg aggregations, top 5000:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"groupBy": ["state", "$.country"],
"condition": {"type":"simple","jsonPath":"$.year","operatorType":"GREATER_OR_EQUAL","value":2000},
"aggregations": [
{"op":"sum","field":"$.amount","as":"totalAmount"},
{"op":"avg","field":"$.amount"}
],
"limit": 5000
}' \
"http://localhost:8080/api/entity/stats/nobel-prize/1/query"
```
**Grouped statistics — count-only (no aggregations), at a historical point in time:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"groupBy": ["$.variantId"],
"pointInTime": "2026-01-01T00:00:00Z"
}' \
"http://localhost:8080/api/entity/stats/nobel-prize/1/query"
```
## SEE ALSO
- models
- search
- workflows
- errors.ENTITY_NOT_FOUND
- errors.ENTITY_MODIFIED
- errors.MODEL_NOT_FOUND
- errors.MODEL_NOT_LOCKED
- errors.VALIDATION_FAILED
- errors.INCOMPATIBLE_TYPE
- errors.CONFLICT
- errors.UNIQUE_VIOLATION
- errors.INVALID_UNIQUE_KEY
- errors.TRANSITION_NOT_FOUND
- messages
- openapi
## See also
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help errors ENTITY_NOT_FOUND`](/help/errors/entity_not_found/) — No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
- [`cyoda help errors ENTITY_MODIFIED`](/help/errors/entity_modified/) — When an entity update request carries an `If-Match` header, the server requires the supplied transaction ID to equal the entity's current `meta.transactionId`. A mismatch means another writer has updated the entity since the caller's last read. The optimistic-concurrency guard rejects the update rather than silently overwrite.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors MODEL_NOT_LOCKED`](/help/errors/model_not_locked/) — Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject writes to prevent schema changes from affecting in-flight data.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
- [`cyoda help errors INCOMPATIBLE_TYPE`](/help/errors/incompatible_type/) — Returned by `POST /entity/{format}/{name}/{version}` and the entity-update surfaces when a leaf field's value cannot be coerced into the model's declared DataType (e.g. submitting `"abc"` against an `INTEGER` field, or `13.111` against an `INTEGER` field on a model whose `changeLevel` is empty so type widening is not in scope).
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors IDEMPOTENCY_CONFLICT`](/help/errors/idempotency_conflict/) — The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
- [`cyoda help errors TRANSACTION_TIMEOUT`](/help/errors/transaction_timeout/) — Fires when the client-supplied `transactionTimeoutMillis` elapses before the first commit. Nothing was committed.
- [`cyoda help errors TRANSITION_NOT_FOUND`](/help/errors/transition_not_found/) — Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the model's workflow definition for the entity's current state. Also occurs when the transition name is misspelled, when the transition is disabled, when it is a scheduled transition (those fire on their timer and are never manually fireable), or when the entity is in a terminal state that allows no further transitions.
- [`cyoda help errors WORKFLOW_FAILED`](/help/errors/workflow_failed/) — During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
- [`cyoda help errors UNIQUE_VIOLATION`](/help/errors/unique_violation/) — The entity payload contains field values that collide with an existing entity's composite unique key. Unlike an optimistic-concurrency CONFLICT (which is retryable), a unique-key violation is a permanent data constraint — retrying the same payload without changing the key field values will produce the same result.
- [`cyoda help errors INVALID_UNIQUE_KEY`](/help/errors/invalid_unique_key/) — A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at least one key field, or the value cannot be normalized to a valid claim (for example, a NaN or ±Infinity for a numeric key field).
- [`cyoda help messages`](/help/messages/) — An edge message is an arbitrary JSON payload stored under a server-generated time-UUID together with a fixed set of AMQP-aligned headers and an optional flat metadata map. The store is standalone: a message is not an entity, and creating one does not touch the workflow engine — no transition fires, no processor or criterion runs. Edge messaging is a durable, tenant-scoped staging buffer at the platform edge, a peer of the entity store rather than part of it.
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
## Raw formats
- [`/help/crud.json`](/help/crud.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/crud.md`](/help/crud.md) — body only
---
## help/errors.md
# cyoda error reference
Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. P…
cyoda-go version 0.8.4
# errors
## NAME
errors — error model and code catalogue.
## SYNOPSIS
REST responses use RFC 9457 Problem Details:
```json
{
"type": "about:blank",
"title": "Not Found",
"status": 404,
"detail": "ENTITY_NOT_FOUND: entity id=abc not found",
"instance": "/api/v1/entities/abc",
"properties": {
"errorCode": "ENTITY_NOT_FOUND",
"retryable": false
}
}
```
gRPC error envelope example (returned in the CloudEvent response payload):
```json
{
"error": {
"code": "ENTITY_NOT_FOUND",
"message": "entity id=abc not found",
"retryable": false
}
}
```
The gRPC response also carries `errorCode` and `retryable` in trailer metadata.
## DESCRIPTION
Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
The `retryable` property is present and `true` only when the operation is safe to retry as-is (e.g., transient cluster conditions). When absent or `false`, the request or system state must change before retrying.
5xx responses include a `ticket` UUID for server-side log correlation. Share this value when reporting issues.
`CYODA_ERROR_RESPONSE_MODE` controls 5xx detail level. `sanitized` (default): generic message plus `ticket` UUID. `verbose`: internal error detail included in the response body; intended for development environments only.
## ERROR CODE INDEX
- `errors.BAD_REQUEST` — `400` — not retryable — request body, query parameter, or header is malformed or structurally invalid
- `errors.CLUSTER_NODE_NOT_REGISTERED` — `503` — retryable — target cluster node is not present in the gossip registry
- `errors.COMPUTE_MEMBER_DISCONNECTED` — `503` — retryable — compute member holding a processor assignment has disconnected
- `errors.CONFLICT` — `409` — retryable — generic 409 used by storage-level transaction serialization aborts (`RetryableConflict`); permanent business-logic conflicts use a specific code instead (e.g. `MODEL_ALREADY_LOCKED`, `ENTITY_MODIFIED`)
- `errors.DELETE_NOT_CONVERGED` — `409` — retryable — batched delete (`transactionSize`) kept finding newly created matching entities and was stopped at its batch cap; earlier batches stay deleted
- `errors.DISPATCH_FORWARD_FAILED` — `503` — retryable — HTTP forwarding call to peer node failed
- `errors.DISPATCH_TIMEOUT` — `503` — retryable (see note) — compute member did not respond within the dispatch timeout; completion on the remote node is not guaranteed
- `errors.DUPLICATE_AGGREGATION_ALIAS` — `400` — not retryable — two grouped-stats aggregations over different `(op, field)` pairs resolve to the same response key
- `errors.DUPLICATE_GROUP_BY` — `400` — not retryable — the same grouped-stats `groupBy` dimension was listed twice
- `errors.ENTITY_MODIFIED` — `412` — not retryable — `If-Match`-guarded entity update rejected; supplied transaction ID does not match the entity's current version
- `errors.ENTITY_NOT_FOUND` — `404` — not retryable — entity UUID does not exist or is not accessible to the caller
- `errors.EPOCH_MISMATCH` — `409` — retryable — writing node's cached shard epoch is stale; another node has since taken ownership
- `errors.FEATURE_DISABLED` — `404` — not retryable — Optional feature not enabled in this deployment.
- `errors.FORBIDDEN` — `403` — not retryable — authenticated caller lacks the required role or the tenant does not match
- `errors.GROUP_CARDINALITY_EXCEEDED` — `422` — not retryable — grouped-stats query produced more distinct buckets than `CYODA_STATS_GROUP_MAX` allows; no partial result is returned
- `errors.HELP_TOPIC_NOT_FOUND` — `404` — not retryable — help topic path does not resolve to any topic in the tree
- `errors.IDEMPOTENCY_CONFLICT` — `409` — not retryable — request with the same idempotency key was received but payload differs from the original
- `errors.INCOMPATIBLE_TYPE` — `400` — not retryable — entity payload's leaf value type is not assignable to the schema's declared DataType for that path; carries `fieldPath`, `expectedType`, `actualType` in `properties` (Cloud's `FoundIncompatibleTypeWithEntityModelException` equivalent)
- `errors.KEY_OWNED_BY_DIFFERENT_TENANT` — `409` — not retryable — Trusted-key registration collides with another tenant.
- `errors.KEYPAIR_NOT_FOUND` — `404` — not retryable — Referenced signing keypair does not exist.
- `errors.INVALID_CHANGE_LEVEL` — `400` — not retryable — `POST /model/{name}/{version}/changeLevel/{changeLevel}` supplied a value that is not one of `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, `STRUCTURAL`
- `errors.INVALID_AGGREGATION_FIELD` — `400` — not retryable — grouped-stats aggregation `field` is outside the scalar JSONPath grammar (most often a missing `$.` leader)
- `errors.INVALID_AGGREGATION_OP` — `400` — not retryable — grouped-stats aggregation `op` is not one of `sum`, `avg`, `min`, `max`, `stdev`
- `errors.INVALID_FIELD_PATH` — `400` — not retryable — search condition references one or more JSONPath field paths absent from the target model's locked schema; bounded refresh did not surface the path
- `errors.INVALID_GROUP_BY_PATH` — `400` — not retryable — grouped-stats `groupBy` entry is neither the reserved `state` token nor a JSONPath denoting a single scalar
- `errors.INVALID_LIMIT` — `400` — not retryable — grouped-stats `limit` is non-positive or greater than `CYODA_STATS_GROUP_MAX`
- `errors.MALFORMED_REQUEST` — `400` — not retryable — grouped-stats request body could not be read or decoded (invalid JSON, unknown top-level field, non-RFC 3339 `pointInTime`)
- `errors.MISSING_GROUP_BY` — `400` — not retryable — grouped-stats request omitted `groupBy` or sent it empty
- `errors.MODEL_ALREADY_LOCKED` — `409` — not retryable — admin operation requires `UNLOCKED` state but the model is `LOCKED` (relock attempt or re-import on a locked model)
- `errors.MODEL_ALREADY_UNLOCKED` — `409` — not retryable — admin operation requires `LOCKED` state but the model is `UNLOCKED` (unlock-of-already-unlocked-model)
- `errors.MODEL_HAS_ENTITIES` — `409` — not retryable — unlock or delete blocked because at least one entity of the model exists
- `errors.MODEL_NOT_FOUND` — `404` — not retryable — referenced entity model does not exist in the tenant's model registry
- `errors.MODEL_NOT_LOCKED` — `409` — not retryable — model exists but is not in `LOCKED` state; entity writes require a locked model
- `errors.NO_COMPUTE_MEMBER_FOR_TAG` — `503` — retryable — no live cluster node advertises the compute tag required by the processor
- `errors.NOT_FOUND` — `404` — not retryable — generic resource not found, used by admin endpoints (key pair lifecycle, trusted-key lifecycle); domain-specific resources have their own codes
- `errors.NOT_IMPLEMENTED` — `501` — not retryable — endpoint is defined but has no functional implementation in this version
- `errors.SEARCH_JOB_ALREADY_TERMINAL` — `400` — not retryable — operation attempted on a search job that has already completed, failed, or been cancelled
- `errors.SEARCH_JOB_NOT_FOUND` — `404` — not retryable — referenced search job does not exist in the current tenant
- `errors.SEARCH_QUEUE_FULL` — `503` — retryable — async-search worker pool has no free worker and its submit queue is at capacity
- `errors.SEARCH_RESULT_LIMIT` — `400` — not retryable — direct search's matched entity count exceeded the requested `limit` (a cap on the matched set, not a page size)
- `errors.SEARCH_SHARD_TIMEOUT` — `503` — retryable — one or more search shards did not respond within the configured timeout
- `errors.SEARCH_TIMEOUT` — `408` — retryable — client-requested search timeout expired before the result set was collected
- `errors.SERVER_ERROR` — `500` — retryable with caution — unclassified internal error; response includes `ticket` UUID for log correlation
- `errors.STORAGE_UNAVAILABLE` — `503` — retryable — storage layer could not supply a connection within its acquire deadline, or the transaction was reclaimed by the idle-in-transaction ceiling
- `errors.TRANSACTION_EXPIRED` — `400` — not retryable — transaction token's `exp` claim is in the past
- `errors.TRANSACTION_NODE_UNAVAILABLE` — `503` — retryable — cluster node that owns the open transaction is unreachable
- `errors.TRANSACTION_NOT_FOUND` — `404` — not retryable — transaction ID does not correspond to an active transaction on this node
- `errors.TRANSACTION_TIMEOUT` — `408` — retryable — client-requested transaction timeout expired before commit
- `errors.TRANSITION_NOT_FOUND` — `400` — not retryable — requested workflow transition is not defined for the entity's current state
- `errors.TRUSTED_KEY_CAP_REACHED` — `400` — not retryable — Per-tenant trusted-key cap reached.
- `errors.TRUSTED_KEY_NOT_FOUND` — `404` — not retryable — referenced trusted-key KID is not present in the registry (delete / invalidate / reactivate target missing)
- `errors.TX_CONFLICT` — `409` — retryable — transaction aborted due to storage-level serialization conflict
- `errors.TX_COORDINATOR_NOT_CONFIGURED` — `503` — not retryable — distributed transaction coordinator is disabled or misconfigured on this node
- `errors.TX_NO_STATE` — `404` — not retryable — coordinator has no state record for the given transaction ID
- `errors.TX_REQUIRED` — `400` — not retryable — operation requires a transaction context but none was provided
- `errors.UNAUTHORIZED` — `401` — not retryable — `Authorization` header is missing, token is expired, signature is invalid, or issuer is untrusted
- `errors.UNSUPPORTED_ALGORITHM` — `400` — not retryable — Requested JWT algorithm not supported in this version.
- `errors.UNSUPPORTED_KEY_TYPE` — `400` — not retryable — JWK `kty` not supported in this version.
- `errors.VALIDATION_FAILED` — `400` — not retryable — payload is structurally valid JSON but fails the model's schema or workflow validation rules
- `errors.WORKFLOW_FAILED` — `400` — not retryable — workflow processor or guard condition returned a failure during state transition
- `errors.WORKFLOW_NOT_FOUND` — `404` — not retryable — workflow definition referenced by the entity model does not exist
## SEE ALSO
- openapi
- grpc
- config
## Subtopics
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help errors CLUSTER_NODE_NOT_REGISTERED`](/help/errors/cluster_node_not_registered/) — The request was routed to or requires a specific cluster node that is not present in the registry. Occurs during startup, rolling restarts, or after a node failure before the gossip layer has converged.
- [`cyoda help errors COMPOSITE_KEY_UNSUPPORTED`](/help/errors/composite_key_unsupported/) — Composite unique key enforcement is an optional capability that storage backends may or may not implement. This error is returned when a model defines one or more unique keys but the backend does not implement the `CompositeUniqueKeyCapable` interface.
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
- [`cyoda help errors CONDITION_TYPE_MISMATCH`](/help/errors/condition_type_mismatch/) — Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors DELETE_NOT_CONVERGED`](/help/errors/delete_not_converged/) — `DELETE /entity/{entityName}/{modelVersion}` with `transactionSize` set (and no `pointInTime`) deletes in batches, re-selecting the matching entities before each batch. It finishes when a selection pass finds nothing left. If entities matching the condition are created at least as fast as they are removed, that pass never comes up empty, so the delete is capped at a fixed number of batches and fails with this code instead of running indefinitely.
- [`cyoda help errors DISPATCH_FORWARD_FAILED`](/help/errors/dispatch_forward_failed/) — The cluster dispatcher attempted to forward a processor invocation or criteria evaluation to a peer node but the HTTP call to that peer failed (network error, peer crash, or connection refused). The operation has not been executed on the target node.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
- [`cyoda help errors DUPLICATE_AGGREGATION_ALIAS`](/help/errors/duplicate_aggregation_alias/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Each bucket's `aggregations` object is keyed by the aggregation's `as` alias, or — when `as` is omitted — by a synthesized `_` with the leading `$.` stripped, so `{"op":"sum","field":"$.amount"}` becomes `sum_amount`. Two aggregations that compute different things cannot share one key, because only one of the two values could be returned under it.
- [`cyoda help errors DUPLICATE_GROUP_BY`](/help/errors/duplicate_group_by/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The reserved token `state` appearing twice, or the same JSONPath appearing twice, is rejected rather than deduplicated: a repeated dimension adds a second copy of the same value to every bucket's `groupKey` and changes nothing about the grouping, so it is more likely a mistake in the request than an intent.
- [`cyoda help errors ENTITY_MODIFIED`](/help/errors/entity_modified/) — When an entity update request carries an `If-Match` header, the server requires the supplied transaction ID to equal the entity's current `meta.transactionId`. A mismatch means another writer has updated the entity since the caller's last read. The optimistic-concurrency guard rejects the update rather than silently overwrite.
- [`cyoda help errors ENTITY_NOT_FOUND`](/help/errors/entity_not_found/) — No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
- [`cyoda help errors EPOCH_MISMATCH`](/help/errors/epoch_mismatch/) — Shard ownership is tracked by an epoch counter that increments whenever the cluster re-partitions. A write is rejected with this error when the writing node's cached epoch is stale — another node has since taken ownership of the shard. This prevents split-brain writes.
- [`cyoda help errors FEATURE_DISABLED`](/help/errors/feature_disabled/) — Returned by trusted-key endpoints when `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=false` (the default):
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
- [`cyoda help errors GROUP_CARDINALITY_EXCEEDED`](/help/errors/group_cardinality_exceeded/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `CYODA_STATS_GROUP_MAX` (default `10000`) bounds the number of distinct buckets the endpoint will build. The bound is enforced on both execution paths — the backend's native GROUP BY pushdown and the in-process streaming tally — so the same query is rejected identically on every storage backend.
- [`cyoda help errors HELP_TOPIC_NOT_FOUND`](/help/errors/help_topic_not_found/) — Returned by `GET {ContextPath}/help/{topic}` when `{topic}` is well-formed (matches `[A-Za-z0-9._-]+`) but does not resolve to any topic in the tree. Clients should `GET {ContextPath}/help` to discover available topic paths.
- [`cyoda help errors IDEMPOTENCY_CONFLICT`](/help/errors/idempotency_conflict/) — The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
- [`cyoda help errors INCOMPATIBLE_TYPE`](/help/errors/incompatible_type/) — Returned by `POST /entity/{format}/{name}/{version}` and the entity-update surfaces when a leaf field's value cannot be coerced into the model's declared DataType (e.g. submitting `"abc"` against an `INTEGER` field, or `13.111` against an `INTEGER` field on a model whose `changeLevel` is empty so type widening is not in scope).
- [`cyoda help errors INVALID_AGGREGATION_FIELD`](/help/errors/invalid_aggregation_field/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. An aggregation `field` obeys exactly the grammar a `groupBy` path does — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`, with no bracket-quoted access, array subscript or projection, recursive descent, whitespace or non-ASCII character. See `cyoda help errors INVALID_GROUP_BY_PATH` for the grammar and the rejected spellings; the message names the offending field and the reason.
- [`cyoda help errors INVALID_AGGREGATION_OP`](/help/errors/invalid_aggregation_op/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The supported operators are `sum`, `avg`, `min`, `max` and `stdev`, spelled lowercase. Anything else — including `count`, an uppercase spelling, or a typo — is rejected, and the message echoes the value that was sent.
- [`cyoda help errors INVALID_CHANGE_LEVEL`](/help/errors/invalid_change_level/) — The `changeLevel` path segment must be exactly one of: `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, or `STRUCTURAL`. Comparison is case-sensitive. Any other value (including the empty string, lower-cased variants, or typos) yields this error.
- [`cyoda help errors INVALID_CONDITION`](/help/errors/invalid_condition/) — Endpoints that accept a search-style condition in the request body — sync and async search, grouped statistics, and the conditional form of delete-by-model — reject a body whose condition cannot be parsed or is otherwise structurally invalid. The condition type is unrecognised, a nested clause is malformed, the JSON does not match the expected condition envelope, an `operatorType` is not one of the canonical operators, a `LIKE` or `MATCHES_PATTERN` operand is not a valid pattern, a `BETWEEN`/`BETWEEN_INCLUSIVE` operator's value is not a two-element array, a `group` clause's `operator` is not `AND`, `OR`, or `NOT`, or a `NOT` group's `conditions` does not hold exactly one entry (zero, or two or more).
- [`cyoda help errors INVALID_FIELD_PATH`](/help/errors/invalid_field_path/) — Three checks emit this code.
- [`cyoda help errors INVALID_GROUP_BY_PATH`](/help/errors/invalid_group_by_path/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Every `groupBy` entry other than `state` must match the wire JSONPath grammar — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`:
- [`cyoda help errors INVALID_LIMIT`](/help/errors/invalid_limit/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `limit` is optional; when present it is a top-N cap on the buckets returned, and it must be greater than zero and no greater than the server's `CYODA_STATS_GROUP_MAX` (default `10000`). A value outside that range is rejected up front rather than clamped, so the response never silently covers a smaller set than the one asked for. The message carries the configured maximum.
- [`cyoda help errors INVALID_UNIQUE_KEY`](/help/errors/invalid_unique_key/) — A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at least one key field, or the value cannot be normalized to a valid claim (for example, a NaN or ±Infinity for a numeric key field).
- [`cyoda help errors INVALID_UNIQUE_KEY_DEFINITION`](/help/errors/invalid_unique_key_definition/) — Each unique key on a model must have a non-empty list of field paths, a unique name within the model, and field paths that resolve to existing, non-ambiguous fields in the model schema. This error is returned when a submitted model definition violates one of these structural requirements.
- [`cyoda help errors KEYPAIR_NOT_FOUND`](/help/errors/keypair_not_found/) — Returned by:
- [`cyoda help errors KEY_OWNED_BY_DIFFERENT_TENANT`](/help/errors/key_owned_by_different_tenant/) — Trusted keys are tenant-scoped. When `POST /oauth/keys/trusted` is called with a `keyId` that already belongs to a different tenant, the request is rejected with `409`. Pick a fresh `keyId` (the caller cannot see or affect the other tenant's keys).
- [`cyoda help errors M2M_CLIENT_NOT_FOUND`](/help/errors/m2m_client_not_found/) — Returned by `/clients` admin endpoints when the supplied `clientId` does not match any registered M2M client in the caller's tenant:
- [`cyoda help errors MALFORMED_REQUEST`](/help/errors/malformed_request/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query` when the body cannot be read from the connection, is not valid JSON, or does not decode into the request shape. Decoding is strict: an unrecognised top-level field is rejected rather than ignored, so a misspelled `agregations` fails here instead of quietly running with no aggregations. A `pointInTime` that is not RFC 3339 also lands here, because it is rejected while the body is being decoded — there is no separate code for it.
- [`cyoda help errors MISSING_GROUP_BY`](/help/errors/missing_group_by/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `groupBy` is required and must carry at least one dimension: the endpoint returns one bucket per distinct group key, and there is no reading of the request that groups by nothing.
- [`cyoda help errors MODEL_ALREADY_LOCKED`](/help/errors/model_already_locked/) — Returned by any admin operation that requires the model be in the `UNLOCKED` state, including:
- [`cyoda help errors MODEL_ALREADY_UNLOCKED`](/help/errors/model_already_unlocked/) — Returned when `POST /model/{name}/{version}/unlock` is issued against a model whose current state is `UNLOCKED`. Distinct from `MODEL_NOT_LOCKED`, which is reserved for the entity-write-without-lock path on the entity service: this code is the symmetric counterpart of `MODEL_ALREADY_LOCKED` for the admin lifecycle.
- [`cyoda help errors MODEL_HAS_ENTITIES`](/help/errors/model_has_entities/) — Both `POST /model/{name}/{version}/unlock` and `DELETE /model/{name}/{version}` require zero entities of the target model. The cardinality check guards against silent loss of data and against schema drift on a model whose lifecycle is presumed frozen.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors MODEL_NOT_LOCKED`](/help/errors/model_not_locked/) — Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject writes to prevent schema changes from affecting in-flight data.
- [`cyoda help errors NOT_FOUND`](/help/errors/not_found/) — Returned by administrative endpoints (key pair lifecycle, trusted-key lifecycle) when the supplied identifier does not match any registered resource. The submitted identifier is never echoed in the response body — only a generic descriptor — so attackers cannot use the response as a reflection oracle. The identifier is logged server-side at INFO for operator correlation.
- [`cyoda help errors NOT_IMPLEMENTED`](/help/errors/not_implemented/) — The route is defined and accepted by the server but the handler returns this error because the feature is pending implementation. Distinct from a `404` — the endpoint exists without a functional implementation.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
- [`cyoda help errors OIDC_INVALID_TENANT`](/help/errors/oidc_invalid_tenant/) — cyoda treats legal entity identifiers as UUIDs. OIDC provider ownership is
recorded as a `uuid.UUID` `OwnerLegalEntityID` field, which keys both the
per-tenant KV blob storage and the validated user-context tenant binding at
token validation time.
- [`cyoda help errors OIDC_PROVIDER_DUPLICATE`](/help/errors/oidc_provider_duplicate/) — Each tenant may register a given `wellKnownConfigUri` only once. Submitting
`POST /oauth/oidc/providers` with a URI that is already registered for the
caller's tenant returns this error.
- [`cyoda help errors OIDC_PROVIDER_INACTIVE`](/help/errors/oidc_provider_inactive/) — `PATCH /oauth/oidc/providers/{id}` requires the provider to be in the active
state. If the provider has been invalidated via
`POST /oauth/oidc/providers/{id}/invalidate`, this error is returned.
- [`cyoda help errors OIDC_PROVIDER_NOT_FOUND`](/help/errors/oidc_provider_not_found/) — The provider UUID supplied in the path parameter does not correspond to a
registered OIDC provider for the caller's tenant. Either the provider was
never registered, was deleted, or the UUID belongs to a different tenant
(cross-tenant existence is not disclosed).
- [`cyoda help errors OIDC_SSRF_BLOCKED`](/help/errors/oidc_ssrf_blocked/) — When registering an OIDC provider, cyoda validates the `wellKnownConfigUri`
against a blocklist of private address ranges (loopback, RFC1918, link-local,
IPv6 ULA). If the URI's hostname resolves to any blocked range, the
registration is rejected to prevent Server-Side Request Forgery attacks.
- [`cyoda help errors PRECONDITION_REQUIRED`](/help/errors/precondition_required/) — PATCH applies a merge patch to the entity's stored state rather than replacing it wholesale. Because the patch is applied relative to the current stored data, cyoda-go requires the caller to state a precondition explicitly via `If-Match`. Omitting the header entirely is rejected.
- [`cyoda help errors SCHEDULE_FUNCTION_INVALID_RESULT`](/help/errors/schedule_function_invalid_result/) — A `TransitionSchedule.function` callout must return `resultKind: "Schedule"` with a value shaped `{fireAt|fireAfterMs, expireAt?|expireAfterMs?}` — exactly one of `fireAt`/`fireAfterMs`, and at most one of `expireAt`/`expireAfterMs`. This error is raised when the compute node returns a different `resultKind`, or a `Schedule` value that is malformed: missing or duplicate fire/expiry fields, an unknown field, or a non-numeric value.
- [`cyoda help errors SEARCH_JOB_ALREADY_TERMINAL`](/help/errors/search_job_already_terminal/) — Search jobs are long-running asynchronous operations. Once a job reaches a terminal state it cannot be cancelled, resumed, or otherwise modified. This error is returned when such an operation is attempted on a finished job — `PUT /search/async/{jobId}/cancel` is the only endpoint that raises it.
- [`cyoda help errors SEARCH_JOB_NOT_FOUND`](/help/errors/search_job_not_found/) — Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one tenant is not visible to another.
- [`cyoda help errors SEARCH_QUEUE_FULL`](/help/errors/search_queue_full/) — `POST /api/search/async/{entityName}/{modelVersion}` runs on a bounded worker pool: a fixed number of workers drain a fixed-capacity queue. Submission fails fast with this error rather than blocking the request or spawning an unbounded goroutine per submission. The rejected submit leaves nothing behind — no job row, no id to poll.
- [`cyoda help errors SEARCH_RESULT_LIMIT`](/help/errors/search_result_limit/) — Direct (synchronous) search is bounded-or-fail: `limit` caps the matched result set rather than paging it. When more entities match than the limit allows, the request is rejected — it never returns a truncated prefix, because a partial result would be indistinguishable from a complete one.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
- [`cyoda help errors SEARCH_TIMEOUT`](/help/errors/search_timeout/) — Fires when the client-supplied `timeoutMillis` elapses before the search result set was fully collected. No partial results are returned.
- [`cyoda help errors SERVER_ERROR`](/help/errors/server_error/) — The server encountered an unclassified internal error. The response body contains a `ticket` UUID that correlates with the server-side error log. No internal details are exposed in the response.
- [`cyoda help errors STORAGE_UNAVAILABLE`](/help/errors/storage_unavailable/) — Raised in three cases, all transient:
- [`cyoda help errors TRANSACTION_EXPIRED`](/help/errors/transaction_expired/) — Transaction tokens are short-lived bearer tokens issued when a transaction is opened. This error fires when the token's `exp` claim is in the past at the time the proxy validates it. The transaction itself may still be active server-side, but the token is no longer valid for routing.
- [`cyoda help errors TRANSACTION_NODE_UNAVAILABLE`](/help/errors/transaction_node_unavailable/) — Transaction state is pinned to the node that opened it. If that node crashes or becomes unreachable while the transaction is in progress, subsequent requests using the transaction token are rejected with this error because the proxy cannot forward them to the owner.
- [`cyoda help errors TRANSACTION_NOT_FOUND`](/help/errors/transaction_not_found/) — The transaction ID supplied in the request does not correspond to an active transaction. The transaction may have been committed, rolled back, expired, or may never have existed. Also occurs when a request is mis-routed to a node that never opened the transaction.
- [`cyoda help errors TRANSACTION_TIMEOUT`](/help/errors/transaction_timeout/) — Fires when the client-supplied `transactionTimeoutMillis` elapses before the first commit. Nothing was committed.
- [`cyoda help errors TRANSITION_NOT_FOUND`](/help/errors/transition_not_found/) — Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the model's workflow definition for the entity's current state. Also occurs when the transition name is misspelled, when the transition is disabled, when it is a scheduled transition (those fire on their timer and are never manually fireable), or when the entity is in a terminal state that allows no further transitions.
- [`cyoda help errors TRUSTED_KEY_CAP_REACHED`](/help/errors/trusted_key_cap_reached/) — `POST /oauth/keys/trusted` enforces a per-tenant cap (default 10, configurable via `CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT`). The cap counts only currently-valid keys (Active and not past `validTo`). Delete or invalidate older keys, or raise the cap.
- [`cyoda help errors TRUSTED_KEY_NOT_FOUND`](/help/errors/trusted_key_not_found/) — Returned by trusted-key admin endpoints when the supplied KID does not match any registered key:
- [`cyoda help errors TX_CONFLICT`](/help/errors/tx_conflict/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors TX_COORDINATOR_NOT_CONFIGURED`](/help/errors/tx_coordinator_not_configured/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors TX_NO_STATE`](/help/errors/tx_no_state/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors TX_REQUIRED`](/help/errors/tx_required/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
- [`cyoda help errors UNIQUE_VIOLATION`](/help/errors/unique_violation/) — The entity payload contains field values that collide with an existing entity's composite unique key. Unlike an optimistic-concurrency CONFLICT (which is retryable), a unique-key violation is a permanent data constraint — retrying the same payload without changing the key field values will produce the same result.
- [`cyoda help errors UNSUPPORTED_ALGORITHM`](/help/errors/unsupported_algorithm/) — cyoda-go v0.8.0 signs and verifies only `RS256`. Other enum values declared in the OpenAPI spec (`RS384`, `RS512`, `PS256`, `PS384`, `PS512`, `ES256`, `ES384`, `ES512`, `EdDSA`) are rejected with this error. Cyoda Cloud supports the full enum; parity is tracked in a v0.8.1 follow-up.
- [`cyoda help errors UNSUPPORTED_KEY_TYPE`](/help/errors/unsupported_key_type/) — `POST /oauth/keys/trusted` accepts only `kty: "RSA"` in v0.8.0. Cloud also supports `kty: "EC"` and `kty: "OKP"`; cyoda-go parity is tracked in a v0.8.1 follow-up.
- [`cyoda help errors UNSUPPORTED_MEDIA_TYPE`](/help/errors/unsupported_media_type/) — Returned by PATCH in two situations:
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
- [`cyoda help errors WORKFLOW_FAILED`](/help/errors/workflow_failed/) — During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
- [`cyoda help errors WORKFLOW_NOT_FOUND`](/help/errors/workflow_not_found/) — Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenant's workflow registry, during entity type registration or when a model references a workflow that was deleted.
- [`cyoda help errors WORKFLOW_SCHEMA_VERSION_UNSUPPORTED`](/help/errors/workflow_schema_version_unsupported/) — Every workflow definition must declare a schema version in `MAJOR.MINOR` format (for example `"version": "1.1"`). This error is returned when the import request contains a version string that does not match any supported schema version.
## See also
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
## Raw formats
- [`/help/errors.json`](/help/errors.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors.md`](/help/errors.md) — body only
---
## help/errors/bad_request.md
# BAD_REQUEST — malformed or invalid request
Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a pa…
cyoda-go version 0.8.4
# errors.BAD_REQUEST
## NAME
BAD_REQUEST — the request body, query parameter, or header is malformed or structurally invalid.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
A payload that parses and then fails against the registered model is not this code — that is `VALIDATION_FAILED`, or `INCOMPATIBLE_TYPE` for a leaf whose DataType does not fit.
Not retryable. The same request produces the same error.
## SEE ALSO
- errors
- errors.VALIDATION_FAILED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
## Raw formats
- [`/help/errors/bad_request.json`](/help/errors/bad_request.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/bad_request.md`](/help/errors/bad_request.md) — body only
---
## help/errors/cluster_node_not_registered.md
# CLUSTER_NODE_NOT_REGISTERED — target node is not in the cluster registry
The request was routed to or requires a specific cluster node that is not present in the registry. Occurs during startup, rolling restarts, or after a nod…
cyoda-go version 0.8.4
# errors.CLUSTER_NODE_NOT_REGISTERED
## NAME
CLUSTER_NODE_NOT_REGISTERED — the target cluster node has not registered itself with the gossip registry.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
The request was routed to or requires a specific cluster node that is not present in the registry. Occurs during startup, rolling restarts, or after a node failure before the gossip layer has converged.
Retryable. Gossip convergence determines when the node becomes available. Persistence beyond the expected convergence window indicates a node health or cluster membership issue.
## SEE ALSO
- errors
- errors.COMPUTE_MEMBER_DISCONNECTED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
## Raw formats
- [`/help/errors/cluster_node_not_registered.json`](/help/errors/cluster_node_not_registered.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/cluster_node_not_registered.md`](/help/errors/cluster_node_not_registered.md) — body only
---
## help/errors/composite_key_unsupported.md
# COMPOSITE_KEY_UNSUPPORTED — backend does not support composite unique keys
Composite unique key enforcement is an optional capability that storage backends may or may not implement. This error is returned when a model defines one…
cyoda-go version 0.8.4
# errors.COMPOSITE_KEY_UNSUPPORTED
## NAME
COMPOSITE_KEY_UNSUPPORTED — the active storage backend does not support composite unique key enforcement.
## SYNOPSIS
HTTP: `422` `Unprocessable Entity`. Retryable: `no`.
## DESCRIPTION
Composite unique key enforcement is an optional capability that storage backends may or may not implement. This error is returned when a model defines one or more unique keys but the backend does not implement the `CompositeUniqueKeyCapable` interface.
To resolve: use a backend that supports composite unique keys, or remove the unique key definitions from the model.
## SEE ALSO
- errors
- errors.UNIQUE_VIOLATION
- errors.INVALID_UNIQUE_KEY_DEFINITION
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors UNIQUE_VIOLATION`](/help/errors/unique_violation/) — The entity payload contains field values that collide with an existing entity's composite unique key. Unlike an optimistic-concurrency CONFLICT (which is retryable), a unique-key violation is a permanent data constraint — retrying the same payload without changing the key field values will produce the same result.
- [`cyoda help errors INVALID_UNIQUE_KEY_DEFINITION`](/help/errors/invalid_unique_key_definition/) — Each unique key on a model must have a non-empty list of field paths, a unique name within the model, and field paths that resolve to existing, non-ambiguous fields in the model schema. This error is returned when a submitted model definition violates one of these structural requirements.
## Raw formats
- [`/help/errors/composite_key_unsupported.json`](/help/errors/composite_key_unsupported.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/composite_key_unsupported.md`](/help/errors/composite_key_unsupported.md) — body only
---
## help/errors/compute_member_disconnected.md
# COMPUTE_MEMBER_DISCONNECTED — compute member dropped from the cluster
The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been …
cyoda-go version 0.8.4
# errors.COMPUTE_MEMBER_DISCONNECTED
## NAME
COMPUTE_MEMBER_DISCONNECTED — a compute member that was holding a workflow or processor assignment has disconnected.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
The server also raises this code when it evicts a member itself — after `CYODA_KEEPALIVE_TIMEOUT` seconds of inbound silence, or when one write to the member has stalled that long — and every callout in flight on that member fails with this code. It is also returned when a member leaves in the instant between being chosen for a callout and the request being handed to it: the caller gets this code immediately rather than waiting out `errors.DISPATCH_TIMEOUT`.
Retryable. The cluster re-routes to an available member. Callers must be idempotent or use an idempotency key when retrying. Persistent failures indicate insufficient compute capacity for the required tags.
## SEE ALSO
- errors
- errors.CLUSTER_NODE_NOT_REGISTERED
- errors.NO_COMPUTE_MEMBER_FOR_TAG
- errors.DISPATCH_TIMEOUT
- grpc
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CLUSTER_NODE_NOT_REGISTERED`](/help/errors/cluster_node_not_registered/) — The request was routed to or requires a specific cluster node that is not present in the registry. Occurs during startup, rolling restarts, or after a node failure before the gossip layer has converged.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
## Raw formats
- [`/help/errors/compute_member_disconnected.json`](/help/errors/compute_member_disconnected.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/compute_member_disconnected.md`](/help/errors/compute_member_disconnected.md) — body only
---
## help/errors/condition_type_mismatch.md
# CONDITION_TYPE_MISMATCH — search condition value type incompatible with field
Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the fields declared DataTypes. For example `\abc\` …
cyoda-go version 0.8.4
# errors.CONDITION_TYPE_MISMATCH
## NAME
CONDITION_TYPE_MISMATCH — a search condition's operand parses into none of the field's declared DataTypes.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
An operator must also apply to the field's type: string and pattern operators require a text field; ordering and range operators require an ordered type (number, text, timestamp). `IS_NULL`/`NOT_NULL` carry no operand-type constraint. A field with no declared types, and paths not present in the schema, carry no constraint here; an unknown field path is instead rejected by a separate validation pass with `INVALID_FIELD_PATH`.
An operand accepted here because it fits at least one of a polymorphic field's declared types is not guaranteed a real comparison against every entity: for an entity whose own stored value is a type family the operand does not fit, `EQUALS` and the other positive comparison operators answer non-match, while `NOT_EQUAL` answers match — see `predicates` for the unsatisfiable-comparison polarity rule. That is an evaluation-time answer about the entity, not a rejection, and is unaffected by this validation.
Temporal meta fields (`creationDate`, `lastUpdateTime`) follow the same rule: a comparison/range operand must parse into a temporal type. A coarse operand (e.g. a bare year, or an offset-less date-time) upscales and is accepted; only an operand that parses into no temporal type is this error.
Both `/search` and the grouped-statistics endpoint (`POST /api/entity/stats/{entityName}/{modelVersion}/query`) enforce this check.
Correct the operand so it denotes a value of one of the target field's declared DataTypes.
## SEE ALSO
- errors
- errors.BAD_REQUEST
- errors.INVALID_FIELD_PATH
- errors.VALIDATION_FAILED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help errors INVALID_FIELD_PATH`](/help/errors/invalid_field_path/) — Three checks emit this code.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
## Raw formats
- [`/help/errors/condition_type_mismatch.json`](/help/errors/condition_type_mismatch.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/condition_type_mismatch.md`](/help/errors/condition_type_mismatch.md) — body only
---
## help/errors/conflict.md
# CONFLICT — optimistic concurrency conflict
The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outco…
cyoda-go version 0.8.4
# errors.CONFLICT
## NAME
CONFLICT — an optimistic concurrency check failed because the entity was modified concurrently.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `yes`.
## DESCRIPTION
The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
Retryable. The full read-modify-write cycle must be repeated using the current entity state; replaying the original write without re-fetching produces stale data.
## SEE ALSO
- errors
- errors.TX_CONFLICT
- errors.IDEMPOTENCY_CONFLICT
- errors.EPOCH_MISMATCH
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TX_CONFLICT`](/help/errors/tx_conflict/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors IDEMPOTENCY_CONFLICT`](/help/errors/idempotency_conflict/) — The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
- [`cyoda help errors EPOCH_MISMATCH`](/help/errors/epoch_mismatch/) — Shard ownership is tracked by an epoch counter that increments whenever the cluster re-partitions. A write is rejected with this error when the writing node's cached epoch is stale — another node has since taken ownership of the shard. This prevents split-brain writes.
## Raw formats
- [`/help/errors/conflict.json`](/help/errors/conflict.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/conflict.md`](/help/errors/conflict.md) — body only
---
## help/errors/delete_not_converged.md
# DELETE_NOT_CONVERGED — a batched delete never ran out of matching entities
`DELETE /entity/{entityName}/{modelVersion}` with `transactionSize` set (and no `pointInTime`) deletes in batches, re-selecting the matching entities befo…
cyoda-go version 0.8.4
# errors.DELETE_NOT_CONVERGED
## NAME
DELETE_NOT_CONVERGED — a batched delete kept finding new matching entities and was stopped before it finished.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `yes`.
## DESCRIPTION
`DELETE /entity/{entityName}/{modelVersion}` with `transactionSize` set (and no `pointInTime`) deletes in batches, re-selecting the matching entities before each batch. It finishes when a selection pass finds nothing left. If entities matching the condition are created at least as fast as they are removed, that pass never comes up empty, so the delete is capped at a fixed number of batches and fails with this code instead of running indefinitely.
Batches that committed before the failure are durable — the matching entities are partially deleted. The request fails rather than returning counts, because those counts would describe only the part of the work that fit inside the cap, not the delete that was asked for.
Do one of:
- stop the writers that keep creating matching entities, then retry;
- narrow the condition so the matching set is one the delete can drain;
- retry as-is if the concurrent writes were a transient burst.
An unbatched delete (`transactionSize` absent) and a `pointInTime`-pinned delete both resolve their target set once and cannot raise this.
Not to be confused with `CONFLICT`, which is a single entity losing an optimistic-concurrency race; the remedy there is to re-read that entity and replay the write.
## SEE ALSO
- errors
- errors.CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
## Raw formats
- [`/help/errors/delete_not_converged.json`](/help/errors/delete_not_converged.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/delete_not_converged.md`](/help/errors/delete_not_converged.md) — body only
---
## help/errors/dispatch_forward_failed.md
# DISPATCH_FORWARD_FAILED — inter-node dispatch forwarding error
The cluster dispatcher attempted to forward a processor invocation or criteria evaluation to a peer node but the HTTP call to that peer failed (network er…
cyoda-go version 0.8.4
# errors.DISPATCH_FORWARD_FAILED
## NAME
DISPATCH_FORWARD_FAILED — forwarding a processor or criteria dispatch request to a peer node failed.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
The cluster dispatcher attempted to forward a processor invocation or criteria evaluation to a peer node but the HTTP call to that peer failed (network error, peer crash, or connection refused). The operation has not been executed on the target node.
Retryable. Persistent failures indicate inter-node network or peer node health issues.
## SEE ALSO
- errors
- errors.DISPATCH_TIMEOUT
- errors.COMPUTE_MEMBER_DISCONNECTED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
## Raw formats
- [`/help/errors/dispatch_forward_failed.json`](/help/errors/dispatch_forward_failed.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/dispatch_forward_failed.md`](/help/errors/dispatch_forward_failed.md) — body only
---
## help/errors/dispatch_timeout.md
# DISPATCH_TIMEOUT — dispatch to compute member timed out
A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callouts own…
cyoda-go version 0.8.4
# errors.DISPATCH_TIMEOUT
## NAME
DISPATCH_TIMEOUT — the dispatcher waited longer than the configured timeout for a compute member to accept and complete a task.
## SYNOPSIS
HTTP: `503` `Service Unavailable`.
## DESCRIPTION
A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
The error message names which of two phases timed out:
- **member not draining** — the compute member had stopped reading its stream, so the request could not even be handed to it.
- **no response** — the member took the request but did not answer in time.
A member that is not draining is evicted within `CYODA_KEEPALIVE_TIMEOUT` seconds; dispatches to it after that return `errors.COMPUTE_MEMBER_DISCONNECTED` and route to another member instead.
Retryable. Completion on the remote node is not guaranteed; retries must be idempotent or carry an idempotency key.
If timeouts recur, check compute member load and network latency. `CYODA_DISPATCH_WAIT_TIMEOUT` and `CYODA_DISPATCH_FORWARD_TIMEOUT` govern cross-node forwarding between cluster nodes, not this timeout — see `cyoda help config cluster`.
## SEE ALSO
- errors
- errors.DISPATCH_FORWARD_FAILED
- errors.NO_COMPUTE_MEMBER_FOR_TAG
- errors.COMPUTE_MEMBER_DISCONNECTED
- grpc
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors DISPATCH_FORWARD_FAILED`](/help/errors/dispatch_forward_failed/) — The cluster dispatcher attempted to forward a processor invocation or criteria evaluation to a peer node but the HTTP call to that peer failed (network error, peer crash, or connection refused). The operation has not been executed on the target node.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
## Raw formats
- [`/help/errors/dispatch_timeout.json`](/help/errors/dispatch_timeout.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/dispatch_timeout.md`](/help/errors/dispatch_timeout.md) — body only
---
## help/errors/duplicate_aggregation_alias.md
# DUPLICATE_AGGREGATION_ALIAS — two aggregations claim the same response key
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Each buckets `aggregations` object is keyed by the aggregations `as` alias, or — w…
cyoda-go version 0.8.4
# errors.DUPLICATE_AGGREGATION_ALIAS
## NAME
DUPLICATE_AGGREGATION_ALIAS — two aggregations over different `(op, field)` pairs resolve to the same key in the response.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Each bucket's `aggregations` object is keyed by the aggregation's `as` alias, or — when `as` is omitted — by a synthesized `_` with the leading `$.` stripped, so `{"op":"sum","field":"$.amount"}` becomes `sum_amount`. Two aggregations that compute different things cannot share one key, because only one of the two values could be returned under it.
The collision can arise between two explicit aliases, or between an explicit alias and a synthesized one (`as: "sum_amount"` on one entry alongside an unaliased `sum` over `$.amount` on another). The message carries the contested alias.
Repeating the *same* `(op, field)` pair does not raise this — identical pairs are deduplicated silently, since both would compute the same value.
Give the colliding aggregations distinct `as` aliases.
## SEE ALSO
- errors
- crud
- errors.INVALID_AGGREGATION_OP
- errors.INVALID_AGGREGATION_FIELD
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors INVALID_AGGREGATION_OP`](/help/errors/invalid_aggregation_op/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The supported operators are `sum`, `avg`, `min`, `max` and `stdev`, spelled lowercase. Anything else — including `count`, an uppercase spelling, or a typo — is rejected, and the message echoes the value that was sent.
- [`cyoda help errors INVALID_AGGREGATION_FIELD`](/help/errors/invalid_aggregation_field/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. An aggregation `field` obeys exactly the grammar a `groupBy` path does — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`, with no bracket-quoted access, array subscript or projection, recursive descent, whitespace or non-ASCII character. See `cyoda help errors INVALID_GROUP_BY_PATH` for the grammar and the rejected spellings; the message names the offending field and the reason.
## Raw formats
- [`/help/errors/duplicate_aggregation_alias.json`](/help/errors/duplicate_aggregation_alias.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/duplicate_aggregation_alias.md`](/help/errors/duplicate_aggregation_alias.md) — body only
---
## help/errors/duplicate_group_by.md
# DUPLICATE_GROUP_BY — the same groupBy dimension was listed twice
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The reserved token `state` appearing twice, or the same JSONPath appearing twice, is…
cyoda-go version 0.8.4
# errors.DUPLICATE_GROUP_BY
## NAME
DUPLICATE_GROUP_BY — two `groupBy` entries name the same dimension.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The reserved token `state` appearing twice, or the same JSONPath appearing twice, is rejected rather than deduplicated: a repeated dimension adds a second copy of the same value to every bucket's `groupKey` and changes nothing about the grouping, so it is more likely a mistake in the request than an intent.
The message names the offending entry. Remove the repeat. Two different paths that happen to resolve to the same value at runtime are not duplicates and are accepted — the comparison is on the request entries, which are validated but never rewritten.
## SEE ALSO
- errors
- crud
- errors.MISSING_GROUP_BY
- errors.INVALID_GROUP_BY_PATH
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors MISSING_GROUP_BY`](/help/errors/missing_group_by/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `groupBy` is required and must carry at least one dimension: the endpoint returns one bucket per distinct group key, and there is no reading of the request that groups by nothing.
- [`cyoda help errors INVALID_GROUP_BY_PATH`](/help/errors/invalid_group_by_path/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Every `groupBy` entry other than `state` must match the wire JSONPath grammar — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`:
## Raw formats
- [`/help/errors/duplicate_group_by.json`](/help/errors/duplicate_group_by.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/duplicate_group_by.md`](/help/errors/duplicate_group_by.md) — body only
---
## help/errors/entity_modified.md
# ENTITY_MODIFIED — If-Match precondition failed; entity changed since last read
When an entity update request carries an `If-Match` header, the server requires the supplied transaction ID to equal the entitys current `meta.transactio…
cyoda-go version 0.8.4
# errors.ENTITY_MODIFIED
## NAME
ENTITY_MODIFIED — an `If-Match`-guarded entity update was rejected because the supplied transaction-ID no longer matches the entity's current version.
## SYNOPSIS
HTTP: `412` `Precondition Failed`. Retryable: `no`.
## DESCRIPTION
When an entity update request carries an `If-Match` header, the server requires the supplied transaction ID to equal the entity's current `meta.transactionId`. A mismatch means another writer has updated the entity since the caller's last read. The optimistic-concurrency guard rejects the update rather than silently overwrite.
The `entityId` property in the problem-detail body identifies the conflicting entity.
Not retryable in the protocol sense — replaying the same payload with the same `If-Match` value will fail again.
## RECOVERY
1. **Re-read the entity:** `GET /api/entity/{entityId}`. The response envelope's `meta.transactionId` is the entity's current version.
2. **Reconcile your change against the current state.** Whatever the concurrent writer changed is now the baseline; merge or override it intentionally rather than blindly replaying your previous payload.
3. **Re-submit the update with the fresh `If-Match`:**
```
curl -X PUT \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-H "If-Match: " \
-d '' \
"http://localhost:8080/api/entity/JSON/{entityId}[/{transition}]"
```
A second `412 ENTITY_MODIFIED` on retry means another writer raced you again. Either accept the loss (drop your change), back off and retry the read-reconcile-write loop with jitter, or escalate to a coarser locking strategy (lock the model, or coordinate writers out of band) — naive looping will livelock under contention.
## RELATIONSHIP TO TRANSACTION-LEVEL CONFLICT DETECTION
`If-Match` is **not** the only conflict guard on entity updates; it is an additional, narrower one. Every PUT runs under Snapshot Isolation with first-committer-wins (SI+FCW) validation at commit time. The handler reads the entity inside the transaction, the read is recorded in the read-set, and any concurrent committer who changes the same entity between this PUT's transaction start and its commit is detected — the commit fails with `409 CONFLICT` and `retryable: true` (the `RetryableConflict` path). On the postgres backend, PostgreSQL's own SQLSTATE 40001 detection (under `REPEATABLE READ`) covers write-write races equivalently. So a PUT *cannot* silently overwrite a concurrent writer that committed during its own transaction window, regardless of whether `If-Match` was supplied.
What `If-Match` adds is a precondition tied to **the caller's earlier read in a different HTTP request**, before this PUT's transaction even began. Two concrete scenarios:
**Cross-request race (caller GET-then-PUT, another writer commits in between).** Caller GETs at `t0` and observes `transactionId` `T0`. Another writer commits a change at `t1`. Caller submits the PUT at `t2`, with `t0 < t1 < t2`. With `If-Match: T0`, the PUT fails `412 ENTITY_MODIFIED` because the entity's current `transactionId` is no longer `T0`. Without `If-Match`, the PUT's own intra-transaction GET at `t2` already sees the writer's change as the current baseline; the PUT proceeds and applies the caller's payload on top of the writer's change — the caller never sees that they overwrote a state they hadn't read.
**Overlapping-transaction race (two PUTs starting from the same baseline).** Two PUTs both begin a transaction and read the same entity version. With `If-Match`, the loser fails fast at write-time as `412 ENTITY_MODIFIED` via `CompareAndSave`. Without `If-Match`, the loser fails at commit-time as `409 CONFLICT` with `retryable: true` via SI+FCW read-set validation.
So omitting `If-Match` does not turn off all concurrency control — but it does silence the cross-request precondition. Use it when reconciling against the live state at PUT-time is what you actually want; supply it when you specifically need to detect that the entity has changed since *your* last read and refuse to clobber.
## SEE ALSO
- errors
- errors.CONFLICT
- errors.IDEMPOTENCY_CONFLICT
- errors.EPOCH_MISMATCH
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors IDEMPOTENCY_CONFLICT`](/help/errors/idempotency_conflict/) — The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
- [`cyoda help errors EPOCH_MISMATCH`](/help/errors/epoch_mismatch/) — Shard ownership is tracked by an epoch counter that increments whenever the cluster re-partitions. A write is rejected with this error when the writing node's cached epoch is stale — another node has since taken ownership of the shard. This prevents split-brain writes.
## Raw formats
- [`/help/errors/entity_modified.json`](/help/errors/entity_modified.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/entity_modified.md`](/help/errors/entity_modified.md) — body only
---
## help/errors/entity_not_found.md
# ENTITY_NOT_FOUND — entity does not exist
No entity with the given ID exists in the tenants data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returne…
cyoda-go version 0.8.4
# errors.ENTITY_NOT_FOUND
## NAME
ENTITY_NOT_FOUND — the requested entity does not exist or is not accessible to the caller.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
Not retryable. Point-in-time lookups require a timestamp within the entity's history.
## SEE ALSO
- errors
- errors.MODEL_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
## Raw formats
- [`/help/errors/entity_not_found.json`](/help/errors/entity_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/entity_not_found.md`](/help/errors/entity_not_found.md) — body only
---
## help/errors/epoch_mismatch.md
# EPOCH_MISMATCH — shard ownership epoch has changed
Shard ownership is tracked by an epoch counter that increments whenever the cluster re-partitions. A write is rejected with this error when the writing no…
cyoda-go version 0.8.4
# errors.EPOCH_MISMATCH
## NAME
EPOCH_MISMATCH — a node attempted to write to a shard it no longer owns because the cluster epoch advanced.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `yes`.
## DESCRIPTION
Shard ownership is tracked by an epoch counter that increments whenever the cluster re-partitions. A write is rejected with this error when the writing node's cached epoch is stale — another node has since taken ownership of the shard. This prevents split-brain writes.
Retryable. The routing layer re-routes to the current shard owner on retry. Frequent recurrence indicates cluster instability or high re-partitioning frequency.
## SEE ALSO
- errors
- errors.CONFLICT
- errors.TX_CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors TX_CONFLICT`](/help/errors/tx_conflict/) — Reserved. Not currently emitted by any cyoda-go code path.
## Raw formats
- [`/help/errors/epoch_mismatch.json`](/help/errors/epoch_mismatch.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/epoch_mismatch.md`](/help/errors/epoch_mismatch.md) — body only
---
## help/errors/feature_disabled.md
# FEATURE_DISABLED — feature is not enabled
Returned by trusted-key endpoints when `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=false` (the default):
cyoda-go version 0.8.4
# errors.FEATURE_DISABLED
## NAME
FEATURE_DISABLED — the operation belongs to an optional feature not enabled in this deployment.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Returned by trusted-key endpoints when `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=false` (the default):
- `GET /oauth/keys/trusted`
- `POST /oauth/keys/trusted`
- `DELETE /oauth/keys/trusted/{keyId}`
- `POST /oauth/keys/trusted/{keyId}/invalidate`
- `POST /oauth/keys/trusted/{keyId}/reactivate`
Enable by setting the env var and restarting. Keypair endpoints (`/oauth/keys/keypair/*`) are unaffected.
Also returned by `POST /clients?withAdminRole=true` when
`CYODA_IAM_M2M_ADMIN_ROLE_ENABLED=false` (the default). Enable by
setting the env var and restarting. Other `/clients` operations
(list, create-without-withAdminRole, delete, reset-secret) are
unaffected.
## SEE ALSO
- errors
- config.auth
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## Raw formats
- [`/help/errors/feature_disabled.json`](/help/errors/feature_disabled.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/feature_disabled.md`](/help/errors/feature_disabled.md) — body only
---
## help/errors/forbidden.md
# FORBIDDEN — caller lacks required role or permission
The request was authenticated successfully but the callers JWT claims do not include the role required by the endpoint (for example, `admin` is required …
cyoda-go version 0.8.4
# errors.FORBIDDEN
## NAME
FORBIDDEN — the authenticated caller does not have the role or permission required to perform the operation.
## SYNOPSIS
HTTP: `403` `Forbidden`. Retryable: `no`.
## DESCRIPTION
The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
Not retryable with the same token. The token's role claims determine access.
## SEE ALSO
- errors
- errors.UNAUTHORIZED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
## Raw formats
- [`/help/errors/forbidden.json`](/help/errors/forbidden.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/forbidden.md`](/help/errors/forbidden.md) — body only
---
## help/errors/group_cardinality_exceeded.md
# GROUP_CARDINALITY_EXCEEDED — too many distinct group buckets
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `CYODA_STATS_GROUP_MAX` (default `10000`) bounds the number of distinct buckets the …
cyoda-go version 0.8.4
# errors.GROUP_CARDINALITY_EXCEEDED
## NAME
GROUP_CARDINALITY_EXCEEDED — the grouped-statistics query produced more distinct group keys than the configured ceiling allows.
## SYNOPSIS
HTTP: `422` `Unprocessable Entity`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `CYODA_STATS_GROUP_MAX` (default `10000`) bounds the number of distinct buckets the endpoint will build. The bound is enforced on both execution paths — the backend's native GROUP BY pushdown and the in-process streaming tally — so the same query is rejected identically on every storage backend.
No partial result is returned: the buckets accumulated so far are a prefix of the answer, not the answer, and returning them would be indistinguishable from a complete result.
Retrying the same request gives the same outcome. Narrow the population with a more selective `condition`, drop a `groupBy` dimension (high-cardinality payload fields such as identifiers are the usual cause), or have an operator raise `CYODA_STATS_GROUP_MAX`. Note that `limit` does not help: it caps the buckets *returned* after the full set has been built, so the ceiling is reached first — a `limit` above the ceiling is itself rejected with `INVALID_LIMIT`.
## SEE ALSO
- errors
- crud
- config
- errors.INVALID_LIMIT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help errors INVALID_LIMIT`](/help/errors/invalid_limit/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `limit` is optional; when present it is a top-N cap on the buckets returned, and it must be greater than zero and no greater than the server's `CYODA_STATS_GROUP_MAX` (default `10000`). A value outside that range is rejected up front rather than clamped, so the response never silently covers a smaller set than the one asked for. The message carries the configured maximum.
## Raw formats
- [`/help/errors/group_cardinality_exceeded.json`](/help/errors/group_cardinality_exceeded.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/group_cardinality_exceeded.md`](/help/errors/group_cardinality_exceeded.md) — body only
---
## help/errors/help_topic_not_found.md
# HELP_TOPIC_NOT_FOUND — help topic not found
Returned by `GET {ContextPath}/help/{topic}` when `{topic}` is well-formed (matches `[A-Za-z0-9._-]+`) but does not resolve to any topic in the tree. Clie…
cyoda-go version 0.8.4
# errors.HELP_TOPIC_NOT_FOUND
## NAME
HELP_TOPIC_NOT_FOUND — requested help topic does not exist.
## SYNOPSIS
HTTP: `404 Not Found`. Retryable: no.
## DESCRIPTION
Returned by `GET {ContextPath}/help/{topic}` when `{topic}` is well-formed (matches `[A-Za-z0-9._-]+`) but does not resolve to any topic in the tree. Clients should `GET {ContextPath}/help` to discover available topic paths.
## SEE ALSO
- errors
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
## Raw formats
- [`/help/errors/help_topic_not_found.json`](/help/errors/help_topic_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/help_topic_not_found.md`](/help/errors/help_topic_not_found.md) — body only
---
## help/errors/idempotency_conflict.md
# IDEMPOTENCY_CONFLICT — duplicate request with conflicting payload
The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
cyoda-go version 0.8.4
# errors.IDEMPOTENCY_CONFLICT
## STATUS
**Not yet implemented.** The error code is reserved and documented here for the future contract, but no API handler currently reads the `Idempotency-Key` header or raises this error. Duplicate collection requests will currently pass through without detection. Tracked for implementation or removal.
## NAME
IDEMPOTENCY_CONFLICT — a request with the same idempotency key was already received but its payload differs from the original.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
The server has already processed (or is currently processing) a request with the same idempotency key, but the new request's body or parameters differ from the first one. Idempotency keys protect against duplicate submissions of identical requests; they do not allow modifying the request after the fact.
Not retryable with the same key and a different payload. A distinct operation requires a distinct idempotency key.
## SEE ALSO
- errors
- errors.CONFLICT
- errors.TX_CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors TX_CONFLICT`](/help/errors/tx_conflict/) — Reserved. Not currently emitted by any cyoda-go code path.
## Raw formats
- [`/help/errors/idempotency_conflict.json`](/help/errors/idempotency_conflict.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/idempotency_conflict.md`](/help/errors/idempotency_conflict.md) — body only
---
## help/errors/incompatible_type.md
# INCOMPATIBLE_TYPE — entity payload value does not match the models declared DataType
Returned by `POST /entity/{format}/{name}/{version}` and the entity-update surfaces when a leaf fields value cannot be coerced into the models declared …
cyoda-go version 0.8.4
# errors.INCOMPATIBLE_TYPE
## NAME
INCOMPATIBLE_TYPE — an entity create or update payload carried a leaf value whose inferred DataType is not assignable to the schema's declared DataType for that path.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Returned by `POST /entity/{format}/{name}/{version}` and the entity-update surfaces when a leaf field's value cannot be coerced into the model's declared DataType (e.g. submitting `"abc"` against an `INTEGER` field, or `13.111` against an `INTEGER` field on a model whose `changeLevel` is empty so type widening is not in scope).
Equivalent to Cloud's `FoundIncompatibleTypeWithEntityModelException`.
The problem-detail body carries the structured fields below in `properties`, so SDKs can branch on the precondition without scraping the message string:
- `entityName` — model name (e.g. `"nobel-prize"`)
- `entityVersion` — model version as a string (e.g. `"1"`)
- `fieldPath` — dotted path of the offending leaf (e.g. `"price"`, `"address.zip"`)
- `expectedType` — array of declared DataType names for that path (e.g. `["INTEGER"]`); usually one entry, more than one when the schema's TypeSet has been widened by a prior extension
- `actualType` — the DataType inferred from the supplied value (e.g. `"DOUBLE"`, `"STRING"`)
Not retryable. The caller must either correct the payload (cast/format the value into the declared type) or, if the model's `changeLevel` permits, request a schema extension that widens the field's TypeSet.
This code is distinct from:
- `errors.CONDITION_TYPE_MISMATCH` — search-side equivalent, raised when a search condition's literal value does not match the field's locked DataType.
- `errors.VALIDATION_FAILED` — every validation failure that is not a leaf type mismatch: a value whose KIND the field does not declare (an object where a scalar is declared), an undeclared field, a structural shape mismatch, or a change the `changeLevel` does not permit. A kind mismatch carries no `expectedType`/`actualType` — there is no `DataType` to report for an object or an array.
## SEE ALSO
- errors
- errors.VALIDATION_FAILED
- errors.BAD_REQUEST
- crud
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
## Raw formats
- [`/help/errors/incompatible_type.json`](/help/errors/incompatible_type.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/incompatible_type.md`](/help/errors/incompatible_type.md) — body only
---
## help/errors/invalid_aggregation_field.md
# INVALID_AGGREGATION_FIELD — aggregation field is not a scalar JSONPath
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. An aggregation `field` obeys exactly the grammar a `groupBy` path does — a required …
cyoda-go version 0.8.4
# errors.INVALID_AGGREGATION_FIELD
## NAME
INVALID_AGGREGATION_FIELD — an aggregation's `field` is not a JSONPath that denotes a single scalar.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. An aggregation `field` obeys exactly the grammar a `groupBy` path does — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`, with no bracket-quoted access, array subscript or projection, recursive descent, whitespace or non-ASCII character. See `cyoda help errors INVALID_GROUP_BY_PATH` for the grammar and the rejected spellings; the message names the offending field and the reason.
The reserved token `state` is groupBy-only. There is no defined aggregate over lifecycle state, so `state` as an aggregation `field` is just an identifier missing its `$.` leader and is rejected here.
A well-formed path whose value is absent or non-numeric at runtime is not an error: those entities are skipped for that aggregation, and a bucket with no numeric samples reports `null`.
## SEE ALSO
- errors
- crud
- errors.INVALID_GROUP_BY_PATH
- errors.INVALID_AGGREGATION_OP
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors INVALID_GROUP_BY_PATH`](/help/errors/invalid_group_by_path/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Every `groupBy` entry other than `state` must match the wire JSONPath grammar — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`:
- [`cyoda help errors INVALID_AGGREGATION_OP`](/help/errors/invalid_aggregation_op/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The supported operators are `sum`, `avg`, `min`, `max` and `stdev`, spelled lowercase. Anything else — including `count`, an uppercase spelling, or a typo — is rejected, and the message echoes the value that was sent.
## Raw formats
- [`/help/errors/invalid_aggregation_field.json`](/help/errors/invalid_aggregation_field.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_aggregation_field.md`](/help/errors/invalid_aggregation_field.md) — body only
---
## help/errors/invalid_aggregation_op.md
# INVALID_AGGREGATION_OP — unknown aggregation operator
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The supported operators are `sum`, `avg`, `min`, `max` and `stdev`, spelled lowercas…
cyoda-go version 0.8.4
# errors.INVALID_AGGREGATION_OP
## NAME
INVALID_AGGREGATION_OP — an aggregation's `op` is not one of the supported operators.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The supported operators are `sum`, `avg`, `min`, `max` and `stdev`, spelled lowercase. Anything else — including `count`, an uppercase spelling, or a typo — is rejected, and the message echoes the value that was sent.
There is no `count` operator because every bucket already carries `count`. `stdev` is the sample standard deviation (divisor `n − 1`) and is `null` when a bucket has fewer than two numeric samples.
## SEE ALSO
- errors
- crud
- errors.INVALID_AGGREGATION_FIELD
- errors.DUPLICATE_AGGREGATION_ALIAS
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors INVALID_AGGREGATION_FIELD`](/help/errors/invalid_aggregation_field/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. An aggregation `field` obeys exactly the grammar a `groupBy` path does — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`, with no bracket-quoted access, array subscript or projection, recursive descent, whitespace or non-ASCII character. See `cyoda help errors INVALID_GROUP_BY_PATH` for the grammar and the rejected spellings; the message names the offending field and the reason.
- [`cyoda help errors DUPLICATE_AGGREGATION_ALIAS`](/help/errors/duplicate_aggregation_alias/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Each bucket's `aggregations` object is keyed by the aggregation's `as` alias, or — when `as` is omitted — by a synthesized `_` with the leading `$.` stripped, so `{"op":"sum","field":"$.amount"}` becomes `sum_amount`. Two aggregations that compute different things cannot share one key, because only one of the two values could be returned under it.
## Raw formats
- [`/help/errors/invalid_aggregation_op.json`](/help/errors/invalid_aggregation_op.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_aggregation_op.md`](/help/errors/invalid_aggregation_op.md) — body only
---
## help/errors/invalid_change_level.md
# INVALID_CHANGE_LEVEL — set-change-level supplied value is not a known ChangeLevel
The `changeLevel` path segment must be exactly one of: `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, or `STRUCTURAL`. Comparison is case-sensitive. Any other …
cyoda-go version 0.8.4
# errors.INVALID_CHANGE_LEVEL
## NAME
INVALID_CHANGE_LEVEL — `POST /model/{name}/{version}/changeLevel/{changeLevel}` was called with a value that is not one of the four accepted `ChangeLevel` enum members.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
The `changeLevel` path segment must be exactly one of: `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, or `STRUCTURAL`. Comparison is case-sensitive. Any other value (including the empty string, lower-cased variants, or typos) yields this error.
The problem-detail body carries the following properties so callers can branch on the precondition without scraping the message string:
- `entityName` — the model's name from the URL path.
- `entityVersion` — the model's integer version from the URL path.
- `suppliedValue` — the offending `changeLevel` string as supplied by the caller.
- `validValues` — the canonical accepted values, in the hierarchy order documented in `models` (most-restrictive to most-permissive): `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, `STRUCTURAL`.
Not retryable: the request will keep failing until the caller sends a valid value. Re-issue the request with one of `validValues`.
## SEE ALSO
- errors
- errors.BAD_REQUEST
- models
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
## Raw formats
- [`/help/errors/invalid_change_level.json`](/help/errors/invalid_change_level.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_change_level.md`](/help/errors/invalid_change_level.md) — body only
---
## help/errors/invalid_condition.md
# INVALID_CONDITION — request condition is malformed or unevaluable
Endpoints that accept a search-style condition in the request body — sync and async search, grouped statistics, and the conditional form of delete-by-mode…
cyoda-go version 0.8.4
# errors.INVALID_CONDITION
## NAME
INVALID_CONDITION — a request body condition (AbstractConditionDto) was malformed, or is well-formed but carries a leaf no backend can evaluate.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Endpoints that accept a search-style condition in the request body — sync and async search, grouped statistics, and the conditional form of delete-by-model — reject a body whose condition cannot be parsed or is otherwise structurally invalid. The condition type is unrecognised, a nested clause is malformed, the JSON does not match the expected condition envelope, an `operatorType` is not one of the canonical operators, a `LIKE` or `MATCHES_PATTERN` operand is not a valid pattern, a `BETWEEN`/`BETWEEN_INCLUSIVE` operator's value is not a two-element array, a `group` clause's `operator` is not `AND`, `OR`, or `NOT`, or a `NOT` group's `conditions` does not hold exactly one entry (zero, or two or more).
A `function` clause at any depth is also rejected here: it is a workflow/transition-criterion shape the engine dispatches to a compute member, and search has no dispatcher for it. Move the predicate into a workflow or transition `criterion`, or express the search with `simple`/`lifecycle`/`group`/`array` clauses.
A **well-formed** condition also lands here when a leaf cannot be evaluated at all. The commonest cause is a comparison against a field the model declares no type for: the type check treats an undeclared field as carrying no constraint and accepts it, and the evaluator then has nothing to compare against. The response reads `condition contains a leaf the backend cannot evaluate`. This is not a parse failure — the body is syntactically correct, so re-checking the JSON will not help. Check that the `jsonPath` names a field the model actually declares, and that the model has observed data for it. A leaf whose operand parses into none of a field's declared types is the distinct `CONDITION_TYPE_MISMATCH` instead.
To resolve: correct the condition body to a valid `AbstractConditionDto` (see `cyoda help search`), or correct the `jsonPath` to a declared field.
## SEE ALSO
- errors
- errors.CONDITION_TYPE_MISMATCH
- errors.BAD_REQUEST
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help errors CONDITION_TYPE_MISMATCH`](/help/errors/condition_type_mismatch/) — Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
## Raw formats
- [`/help/errors/invalid_condition.json`](/help/errors/invalid_condition.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_condition.md`](/help/errors/invalid_condition.md) — body only
---
## help/errors/invalid_field_path.md
# INVALID_FIELD_PATH — search condition references unknown field path
Three checks emit this code.
cyoda-go version 0.8.4
# errors.INVALID_FIELD_PATH
## NAME
INVALID_FIELD_PATH — a condition's `jsonPath`, or a sort key, is not valid JSON Path syntax, or names a field absent from the target model's locked schema.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no` (unless the model schema is then extended via re-import; the request is then valid against the new locked schema).
## DESCRIPTION
Three checks emit this code.
**1. Syntax.** A condition's `jsonPath` is JSON Path nomenclature, so the `$.` leader is required:
```
jsonPath = "$." segment ( "." segment )*
segment = name subscript*
name = 1*( ALPHA / DIGIT / "_" / "-" ) ; ASCII only
subscript = "[" ( "*" / 1*DIGIT ) "]" ; the digit run must fit a signed 32-bit integer
```
`$.amount` and `$.address.city` are paths. A bare `amount` is **not** one and is rejected — it is not a tolerated alias. So are an empty path, an empty or trailing segment (`$..a`, `$.a.`), bracket-quoted property access (`$['x']`, `$.['x']`, `$.a["b"]` — use dotted access instead), and any character outside the segment set.
A **well-formed** array subscript — the wildcard `[*]` or a non-negative index `[0]` — is valid JSON Path and is **accepted** (`$.tags[*].name`, `$.arr[0]`, `$.matrix[*][*]`, `$.orders[*].lines[*].sku`); it cannot be pushed into the storage query, so it is evaluated in memory.
Any other bracket spelling is rejected with this code: an unclosed or unmatched bracket (`$.a[`, `$.a[0`, `$.a]`), a subscript with no field name before it (`$.[0]`), an empty subscript (`$.a[]`), a negative or signed index (`$.a[-1]`, `$.a[+1]`), a slice (`$.a[0:2]`), a union (`$.a[0,1]`), a filter expression (`$.a[?(@.x)]`), and whitespace inside one (`$.a[ 0]`). A positional index must also fit a signed 32-bit integer: `2147483647` is the largest accepted, and a wider digit run (`$.a[2147483648]`) is rejected with this code rather than truncated or wrapped — no entity array is long enough for such an index to address a real position. Characters after a well-formed subscript are checked too — `$.a[0]b`, `$.a[0];DROP` and `$.a[*]..b` are all rejected. These previously slipped through unvalidated and answered `200` with an empty page (or, on the grouped-stats `condition` and workflow-criterion surfaces, wrong buckets and a criterion that silently never fired).
This check is syntactic and runs on every search-shaped surface regardless of whether a schema is loaded: `/search` (sync and async), conditional delete, and the `condition` of a grouped-statistics query.
**2. Schema.** Before executing a search, the server validates that every data-field path referenced by the condition (e.g. `$.price`, `$.profile.email`) resolves against the target model's locked schema. Lifecycle paths (`state`, `previousTransition`, etc.) bypass this check.
A path that is a **pure container** — a known structural interior with substructure (an object with child fields) but no scalar observation of its own — is also rejected this way when compared with a scalar operator: a container has no scalar value to compare against, so the client must navigate to a leaf sub-path. `IS_NULL`/`NOT_NULL` are exempt (they test presence, not a value) and remain valid on a container path. A path observed as **both** an object and a bare scalar across different entities is not a pure container — it is searchable via its scalar type, and the object-valued entities remain reachable through their child leaves.
A path ending in `[*]` addresses the array's **elements**, so the same rule applies to them: an array of scalars (`$.tags[*]`) and an array whose elements were also observed as bare scalars are comparable, while an array of **pure objects** (`$.items[*]`) is a container — write `$.items[*].sku`.
If any referenced path is unknown, the server performs at most one bounded `RefreshAndGet` against the model store to recover from a stale cached schema. If the path is still unknown after the refresh, the request is rejected with HTTP 400 and `errorCode: "INVALID_FIELD_PATH"`. The response detail names every offending path so clients can correct the request without round-tripping to the support team.
A condition referencing an unrecognized lifecycle/meta filter field (not one of the known `state`, `creationDate`, `lastUpdateTime`, `transitionForLatestSave`/`previousTransition`, `transactionId`, `id` fields) is rejected the same way, on both `/search` and the grouped-statistics endpoint (`POST /api/entity/stats/{entityName}/{modelVersion}/query`). Grouped statistics does not have data-model schema access, so it enforces this meta-field check but not the schema-backed data-field-path check described above.
Programmatic clients should branch on `errorCode == "INVALID_FIELD_PATH"` (not on HTTP 400) to distinguish unknown-field-path errors from other 400s such as `BAD_REQUEST` (malformed JSON) or `CONDITION_TYPE_MISMATCH` (incompatible value type).
Common causes:
- The `$.` leader is missing (`amount` instead of `$.amount`).
- Bracket-quoted access (`$['amount']`) instead of dotted access (`$.amount`).
- The condition references a field that has not been declared in the model schema.
- The model has been re-imported with a different shape and the client's condition uses an old field name.
- The path is misspelled (e.g. `$.Name` vs `$.name`).
To resolve: write the path as JSON Path with the `$.` leader, then verify the field against the model's schema (`GET /api/model/.../export`), or extend the model schema and re-lock it before retrying.
The same grammar applies to a grouped-statistics `groupBy` entry and aggregation `field`, but those report `INVALID_GROUP_BY_PATH` / `INVALID_AGGREGATION_FIELD` instead, and additionally reject array subscripts (a group key must be a single scalar). The reserved `groupBy` token `state` is a token, not a path, and needs no leader.
**3. Sort paths.** A sort key — the HTTP `sort` query parameter or a gRPC `orderBy.path` — reports this code too, and is held to the grammar above with one addition and one relaxation. It **rejects array subscripts and projections** (`items[*].name`, `items[0].name`), for the same reason a `groupBy` entry does: an ordering needs a single scalar, and a projection denotes none. Schema membership is not a substitute — a scalar leaf inside an array of objects is a recorded field. And the `$.` leader is **optional** on a sort key: `price` and `$.price` are both accepted, since a bare dotted path is the parameter's own spelling. Sort keys are also rejected with this code when the path is absent from the locked schema, names an array field, names an unknown meta field, duplicates another key, or exceeds `CYODA_SEARCH_MAX_SORT_KEYS`.
## SEE ALSO
- errors
- errors.BAD_REQUEST
- errors.CONDITION_TYPE_MISMATCH
- search
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help errors CONDITION_TYPE_MISMATCH`](/help/errors/condition_type_mismatch/) — Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
## Raw formats
- [`/help/errors/invalid_field_path.json`](/help/errors/invalid_field_path.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_field_path.md`](/help/errors/invalid_field_path.md) — body only
---
## help/errors/invalid_group_by_path.md
# INVALID_GROUP_BY_PATH — groupBy entry is not a scalar JSONPath
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Every `groupBy` entry other than `state` must match the wire JSONPath grammar — a re…
cyoda-go version 0.8.4
# errors.INVALID_GROUP_BY_PATH
## NAME
INVALID_GROUP_BY_PATH — a `groupBy` entry is neither the reserved `state` token nor a JSONPath that denotes a single scalar.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Every `groupBy` entry other than `state` must match the wire JSONPath grammar — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`:
```
path = "$." segment ( "." segment )*
segment = 1*( ALPHA / DIGIT / "_" / "-" )
```
Rejected here: a missing leader (`country` — write `$.country`), bracket-quoted property access (`$['country']`, `$.['country']`), array projections and subscripts (`$.items[*]`, `$.items[0]` — address a position as an ordinary segment, `$.items.0`), recursive descent (`$..name`), filter expressions, empty, leading, trailing or doubled dots, whitespace, quotes, and non-ASCII characters.
Array subscripts are rejected even though a `condition` `jsonPath` accepts them: a group-by dimension must resolve to one scalar, and a projection has no such value. The check runs at the API boundary before any storage backend, so a request is rejected identically whichever execution path would have served it. The message names the offending entry and the reason.
The token `state` is accepted in `groupBy` only, and carries no `$.` leader — it names lifecycle state, not a path. A payload field literally called `state` is written `$.state`.
## SEE ALSO
- errors
- crud
- errors.INVALID_AGGREGATION_FIELD
- errors.INVALID_FIELD_PATH
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors INVALID_AGGREGATION_FIELD`](/help/errors/invalid_aggregation_field/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. An aggregation `field` obeys exactly the grammar a `groupBy` path does — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`, with no bracket-quoted access, array subscript or projection, recursive descent, whitespace or non-ASCII character. See `cyoda help errors INVALID_GROUP_BY_PATH` for the grammar and the rejected spellings; the message names the offending field and the reason.
- [`cyoda help errors INVALID_FIELD_PATH`](/help/errors/invalid_field_path/) — Three checks emit this code.
## Raw formats
- [`/help/errors/invalid_group_by_path.json`](/help/errors/invalid_group_by_path.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_group_by_path.md`](/help/errors/invalid_group_by_path.md) — body only
---
## help/errors/invalid_limit.md
# INVALID_LIMIT — grouped-stats limit is non-positive or above the ceiling
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `limit` is optional; when present it is a top-N cap on the buckets returned, and it …
cyoda-go version 0.8.4
# errors.INVALID_LIMIT
## NAME
INVALID_LIMIT — the grouped-statistics request's `limit` is not a positive integer at or below `CYODA_STATS_GROUP_MAX`.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `limit` is optional; when present it is a top-N cap on the buckets returned, and it must be greater than zero and no greater than the server's `CYODA_STATS_GROUP_MAX` (default `10000`). A value outside that range is rejected up front rather than clamped, so the response never silently covers a smaller set than the one asked for. The message carries the configured maximum.
Omit `limit` for all buckets, up to the cardinality ceiling. If the ceiling itself is too low for the deployment, an operator raises `CYODA_STATS_GROUP_MAX`.
## SEE ALSO
- errors
- crud
- config
- errors.GROUP_CARDINALITY_EXCEEDED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help errors GROUP_CARDINALITY_EXCEEDED`](/help/errors/group_cardinality_exceeded/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `CYODA_STATS_GROUP_MAX` (default `10000`) bounds the number of distinct buckets the endpoint will build. The bound is enforced on both execution paths — the backend's native GROUP BY pushdown and the in-process streaming tally — so the same query is rejected identically on every storage backend.
## Raw formats
- [`/help/errors/invalid_limit.json`](/help/errors/invalid_limit.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_limit.md`](/help/errors/invalid_limit.md) — body only
---
## help/errors/invalid_unique_key.md
# INVALID_UNIQUE_KEY — unique key fields are null or invalid
A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at …
cyoda-go version 0.8.4
# errors.INVALID_UNIQUE_KEY
## NAME
INVALID_UNIQUE_KEY — the engine could not compute a complete composite unique key because one or more required key fields are null or carry an unsupported value type.
## SYNOPSIS
HTTP: `422` `Unprocessable Entity`. Retryable: `no`.
## DESCRIPTION
A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at least one key field, or the value cannot be normalized to a valid claim (for example, a NaN or ±Infinity for a numeric key field).
To resolve: ensure every field listed in the model's unique key definition has a valid, non-null value in the submitted entity payload.
## SEE ALSO
- errors
- errors.UNIQUE_VIOLATION
- errors.INVALID_UNIQUE_KEY_DEFINITION
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors UNIQUE_VIOLATION`](/help/errors/unique_violation/) — The entity payload contains field values that collide with an existing entity's composite unique key. Unlike an optimistic-concurrency CONFLICT (which is retryable), a unique-key violation is a permanent data constraint — retrying the same payload without changing the key field values will produce the same result.
- [`cyoda help errors INVALID_UNIQUE_KEY_DEFINITION`](/help/errors/invalid_unique_key_definition/) — Each unique key on a model must have a non-empty list of field paths, a unique name within the model, and field paths that resolve to existing, non-ambiguous fields in the model schema. This error is returned when a submitted model definition violates one of these structural requirements.
## Raw formats
- [`/help/errors/invalid_unique_key.json`](/help/errors/invalid_unique_key.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_unique_key.md`](/help/errors/invalid_unique_key.md) — body only
---
## help/errors/invalid_unique_key_definition.md
# INVALID_UNIQUE_KEY_DEFINITION — unique key definition is structurally invalid
Each unique key on a model must have a non-empty list of field paths, a unique name within the model, and field paths that resolve to existing, non-ambigu…
cyoda-go version 0.8.4
# errors.INVALID_UNIQUE_KEY_DEFINITION
## NAME
INVALID_UNIQUE_KEY_DEFINITION — a model's unique key definition is structurally invalid and cannot be used.
## SYNOPSIS
HTTP: `422` `Unprocessable Entity`. Retryable: `no`.
## DESCRIPTION
Each unique key on a model must have a non-empty list of field paths, a unique name within the model, and field paths that resolve to existing, non-ambiguous fields in the model schema. This error is returned when a submitted model definition violates one of these structural requirements.
To resolve: correct the unique key definition — ensure every key has a name, at least one field path, no duplicate key names within the model, and that all referenced field paths exist in the model schema.
## SEE ALSO
- errors
- errors.INVALID_UNIQUE_KEY
- errors.COMPOSITE_KEY_UNSUPPORTED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors INVALID_UNIQUE_KEY`](/help/errors/invalid_unique_key/) — A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at least one key field, or the value cannot be normalized to a valid claim (for example, a NaN or ±Infinity for a numeric key field).
- [`cyoda help errors COMPOSITE_KEY_UNSUPPORTED`](/help/errors/composite_key_unsupported/) — Composite unique key enforcement is an optional capability that storage backends may or may not implement. This error is returned when a model defines one or more unique keys but the backend does not implement the `CompositeUniqueKeyCapable` interface.
## Raw formats
- [`/help/errors/invalid_unique_key_definition.json`](/help/errors/invalid_unique_key_definition.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/invalid_unique_key_definition.md`](/help/errors/invalid_unique_key_definition.md) — body only
---
## help/errors/key_owned_by_different_tenant.md
# KEY_OWNED_BY_DIFFERENT_TENANT — trusted-key collision with another tenant
Trusted keys are tenant-scoped. When `POST /oauth/keys/trusted` is called with a `keyId` that already belongs to a different tenant, the request is reject…
cyoda-go version 0.8.4
# errors.KEY_OWNED_BY_DIFFERENT_TENANT
## NAME
KEY_OWNED_BY_DIFFERENT_TENANT — the requested `keyId` is already registered by another tenant.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
Trusted keys are tenant-scoped. When `POST /oauth/keys/trusted` is called with a `keyId` that already belongs to a different tenant, the request is rejected with `409`. Pick a fresh `keyId` (the caller cannot see or affect the other tenant's keys).
## SEE ALSO
- errors
- errors.TRUSTED_KEY_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TRUSTED_KEY_NOT_FOUND`](/help/errors/trusted_key_not_found/) — Returned by trusted-key admin endpoints when the supplied KID does not match any registered key:
## Raw formats
- [`/help/errors/key_owned_by_different_tenant.json`](/help/errors/key_owned_by_different_tenant.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/key_owned_by_different_tenant.md`](/help/errors/key_owned_by_different_tenant.md) — body only
---
## help/errors/keypair_not_found.md
# KEYPAIR_NOT_FOUND — signing keypair not found
Returned by:
cyoda-go version 0.8.4
# errors.KEYPAIR_NOT_FOUND
## NAME
KEYPAIR_NOT_FOUND — the requested JWT signing keypair is not present.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Returned by:
- `DELETE /oauth/keys/keypair/{keyId}` — keyId not present.
- `POST /oauth/keys/keypair/{keyId}/invalidate` — keyId not present.
- `POST /oauth/keys/keypair/{keyId}/reactivate` — keyId not present.
- `GET /oauth/keys/keypair/current?audience=X` — no active key for audience X.
Verify the keyId, or check the bootstrap-key audience configuration via `CYODA_JWT_BOOTSTRAP_AUDIENCE`.
## SEE ALSO
- errors
- errors.NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors NOT_FOUND`](/help/errors/not_found/) — Returned by administrative endpoints (key pair lifecycle, trusted-key lifecycle) when the supplied identifier does not match any registered resource. The submitted identifier is never echoed in the response body — only a generic descriptor — so attackers cannot use the response as a reflection oracle. The identifier is logged server-side at INFO for operator correlation.
## Raw formats
- [`/help/errors/keypair_not_found.json`](/help/errors/keypair_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/keypair_not_found.md`](/help/errors/keypair_not_found.md) — body only
---
## help/errors/m2m_client_not_found.md
# M2M_CLIENT_NOT_FOUND — referenced technical user does not exist
Returned by `/clients` admin endpoints when the supplied `clientId` does not match any registered M2M client in the callers tenant:
cyoda-go version 0.8.4
# errors.M2M_CLIENT_NOT_FOUND
## NAME
M2M_CLIENT_NOT_FOUND — an admin operation referenced a `clientId` that is not present in this tenant's M2M registry.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Returned by `/clients` admin endpoints when the supplied `clientId` does not match any registered M2M client in the caller's tenant:
- `DELETE /clients/{clientId}` — the deletion target does not exist.
- `PUT /clients/{clientId}/secret` — the rotation target does not exist.
The detail field carries a generic `M2M client not found` message; internal store phrasing is never leaked into the response body.
Not retryable. Verify the `clientId` via `GET /clients` before retrying the operation.
Returned uniformly for `clientId`s that do not exist AND `clientId`s owned by another tenant; the response does not distinguish — by design, to prevent cross-tenant existence enumeration.
## SEE ALSO
- errors
- errors.UNAUTHORIZED
- errors.FORBIDDEN
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
## Raw formats
- [`/help/errors/m2m_client_not_found.json`](/help/errors/m2m_client_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/m2m_client_not_found.md`](/help/errors/m2m_client_not_found.md) — body only
---
## help/errors/malformed_request.md
# MALFORMED_REQUEST — grouped-stats request body could not be decoded
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query` when the body cannot be read from the connection, is not valid JSON, or does not deco…
cyoda-go version 0.8.4
# errors.MALFORMED_REQUEST
## NAME
MALFORMED_REQUEST — the grouped-statistics request body could not be read or decoded.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query` when the body cannot be read from the connection, is not valid JSON, or does not decode into the request shape. Decoding is strict: an unrecognised top-level field is rejected rather than ignored, so a misspelled `agregations` fails here instead of quietly running with no aggregations. A `pointInTime` that is not RFC 3339 also lands here, because it is rejected while the body is being decoded — there is no separate code for it.
The message carries the decoder's reason. Correct the body and resend.
A body over the 10 MiB ceiling is a different outcome: `413` with `BAD_REQUEST`. Field-level problems that survive decoding — an empty `groupBy`, a bad JSONPath, an unknown aggregation operator — have their own codes.
Other entity endpoints report an undecodable body as `BAD_REQUEST`; this code is specific to the grouped-statistics endpoint.
## SEE ALSO
- errors
- crud
- errors.BAD_REQUEST
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
## Raw formats
- [`/help/errors/malformed_request.json`](/help/errors/malformed_request.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/malformed_request.md`](/help/errors/malformed_request.md) — body only
---
## help/errors/missing_group_by.md
# MISSING_GROUP_BY — grouped-stats request supplied no groupBy dimension
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `groupBy` is required and must carry at least one dimension: the endpoint returns on…
cyoda-go version 0.8.4
# errors.MISSING_GROUP_BY
## NAME
MISSING_GROUP_BY — the grouped-statistics request omitted `groupBy`, or sent it as an empty array.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. `groupBy` is required and must carry at least one dimension: the endpoint returns one bucket per distinct group key, and there is no reading of the request that groups by nothing.
Supply at least one entry — either the reserved token `state` (lifecycle state) or a scalar JSONPath into the payload, such as `$.country`. For an ungrouped count of a model's entities, use the model statistics endpoint instead.
## SEE ALSO
- errors
- crud
- errors.DUPLICATE_GROUP_BY
- errors.INVALID_GROUP_BY_PATH
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help errors DUPLICATE_GROUP_BY`](/help/errors/duplicate_group_by/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. The reserved token `state` appearing twice, or the same JSONPath appearing twice, is rejected rather than deduplicated: a repeated dimension adds a second copy of the same value to every bucket's `groupKey` and changes nothing about the grouping, so it is more likely a mistake in the request than an intent.
- [`cyoda help errors INVALID_GROUP_BY_PATH`](/help/errors/invalid_group_by_path/) — Raised by `POST /api/entity/stats/{entityName}/{modelVersion}/query`. Every `groupBy` entry other than `state` must match the wire JSONPath grammar — a required `$.` leader followed by dot-separated segments of ASCII letters, digits, `_` and `-`:
## Raw formats
- [`/help/errors/missing_group_by.json`](/help/errors/missing_group_by.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/missing_group_by.md`](/help/errors/missing_group_by.md) — body only
---
## help/errors/model_already_locked.md
# MODEL_ALREADY_LOCKED — model is already in the LOCKED state
Returned by any admin operation that requires the model be in the `UNLOCKED` state, including:
cyoda-go version 0.8.4
# errors.MODEL_ALREADY_LOCKED
## NAME
MODEL_ALREADY_LOCKED — an admin operation requested the model be in the `UNLOCKED` state, but the model is already `LOCKED`.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
Returned by any admin operation that requires the model be in the `UNLOCKED` state, including:
- `DELETE /model/{name}/{version}` — deleting a `LOCKED` model is rejected; unlock first.
- `POST /model/{name}/{version}/lock` — the relock is rejected because the model is already locked.
- `PUT /model/{name}/{version}/unique-keys` — setting unique keys on a `LOCKED` model is rejected.
- Re-importing a model whose existing descriptor is already `LOCKED`.
The problem-detail body carries `entityName` and `entityVersion` on every emit; the relock and delete branches additionally set `expectedState` (always `UNLOCKED`) and `actualState` (always `LOCKED`) so callers can branch on the precondition without scraping the message string.
Not retryable. To proceed, either accept the existing lock or unlock the model first via `POST /model/{name}/{version}/unlock`.
## SEE ALSO
- errors
- errors.MODEL_NOT_FOUND
- errors.MODEL_NOT_LOCKED
- errors.CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors MODEL_NOT_LOCKED`](/help/errors/model_not_locked/) — Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject writes to prevent schema changes from affecting in-flight data.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
## Raw formats
- [`/help/errors/model_already_locked.json`](/help/errors/model_already_locked.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/model_already_locked.md`](/help/errors/model_already_locked.md) — body only
---
## help/errors/model_already_unlocked.md
# MODEL_ALREADY_UNLOCKED — model is already in the UNLOCKED state
Returned when `POST /model/{name}/{version}/unlock` is issued against a model whose current state is `UNLOCKED`. Distinct from `MODEL_NOT_LOCKED`, which i…
cyoda-go version 0.8.4
# errors.MODEL_ALREADY_UNLOCKED
## NAME
MODEL_ALREADY_UNLOCKED — an unlock-transition request was issued against a model that is already `UNLOCKED`. The expected pre-state was `LOCKED`.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
Returned when `POST /model/{name}/{version}/unlock` is issued against a model whose current state is `UNLOCKED`. Distinct from `MODEL_NOT_LOCKED`, which is reserved for the entity-write-without-lock path on the entity service: this code is the symmetric counterpart of `MODEL_ALREADY_LOCKED` for the admin lifecycle.
The problem-detail body carries `entityName`, `entityVersion`, `expectedState` (always `LOCKED`), and `actualState` (always `UNLOCKED`) so callers can branch on the precondition without scraping the message string.
Not retryable. Lock the model first via `POST /model/{name}/{version}/lock` if a subsequent unlock is required.
## SEE ALSO
- errors
- errors.MODEL_ALREADY_LOCKED
- errors.MODEL_NOT_LOCKED
- errors.CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors MODEL_ALREADY_LOCKED`](/help/errors/model_already_locked/) — Returned by any admin operation that requires the model be in the `UNLOCKED` state, including:
- [`cyoda help errors MODEL_NOT_LOCKED`](/help/errors/model_not_locked/) — Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject writes to prevent schema changes from affecting in-flight data.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
## Raw formats
- [`/help/errors/model_already_unlocked.json`](/help/errors/model_already_unlocked.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/model_already_unlocked.md`](/help/errors/model_already_unlocked.md) — body only
---
## help/errors/model_has_entities.md
# MODEL_HAS_ENTITIES — operation blocked because entities of this model exist
Both `POST /model/{name}/{version}/unlock` and `DELETE /model/{name}/{version}` require zero entities of the target model. The cardinality check guards ag…
cyoda-go version 0.8.4
# errors.MODEL_HAS_ENTITIES
## NAME
MODEL_HAS_ENTITIES — an unlock or delete request was rejected because at least one entity of the target model still exists.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
Both `POST /model/{name}/{version}/unlock` and `DELETE /model/{name}/{version}` require zero entities of the target model. The cardinality check guards against silent loss of data and against schema drift on a model whose lifecycle is presumed frozen.
The `entityCount` property in the problem-detail body reports how many entities currently exist for the model on the responding tenant.
Not retryable in the protocol sense. The caller must remove the offending entities (e.g. via condition-delete on the entity surface) and re-issue the lifecycle request.
## SEE ALSO
- errors
- errors.MODEL_ALREADY_LOCKED
- errors.MODEL_ALREADY_UNLOCKED
- errors.CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors MODEL_ALREADY_LOCKED`](/help/errors/model_already_locked/) — Returned by any admin operation that requires the model be in the `UNLOCKED` state, including:
- [`cyoda help errors MODEL_ALREADY_UNLOCKED`](/help/errors/model_already_unlocked/) — Returned when `POST /model/{name}/{version}/unlock` is issued against a model whose current state is `UNLOCKED`. Distinct from `MODEL_NOT_LOCKED`, which is reserved for the entity-write-without-lock path on the entity service: this code is the symmetric counterpart of `MODEL_ALREADY_LOCKED` for the admin lifecycle.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
## Raw formats
- [`/help/errors/model_has_entities.json`](/help/errors/model_has_entities.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/model_has_entities.md`](/help/errors/model_has_entities.md) — body only
---
## help/errors/model_not_found.md
# MODEL_NOT_FOUND — entity model does not exist
The entity type or model name specified in the request does not exist in the tenants model registry. Occurs on write paths (creating entities with an unk…
cyoda-go version 0.8.4
# errors.MODEL_NOT_FOUND
## NAME
MODEL_NOT_FOUND — the referenced entity model (schema) does not exist.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
Not retryable. Register the model before issuing any operation that references it.
## SEE ALSO
- errors
- crud
- search
- errors.ENTITY_NOT_FOUND
- errors.MODEL_NOT_LOCKED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help errors ENTITY_NOT_FOUND`](/help/errors/entity_not_found/) — No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
- [`cyoda help errors MODEL_NOT_LOCKED`](/help/errors/model_not_locked/) — Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject writes to prevent schema changes from affecting in-flight data.
## Raw formats
- [`/help/errors/model_not_found.json`](/help/errors/model_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/model_not_found.md`](/help/errors/model_not_found.md) — body only
---
## help/errors/model_not_locked.md
# MODEL_NOT_LOCKED — model must be locked before writing entities
Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject …
cyoda-go version 0.8.4
# errors.MODEL_NOT_LOCKED
## NAME
MODEL_NOT_LOCKED — the entity model exists but is not in a locked state, which is required before entities of that type can be created or updated.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
Entity creation and bulk write operations require the model to be in the `LOCKED` lifecycle state. Models in `DRAFT` or unlocked-for-editing state reject writes to prevent schema changes from affecting in-flight data.
Not retryable. Entity writes require the model to be in `LOCKED` state.
## SEE ALSO
- errors
- errors.MODEL_NOT_FOUND
- errors.CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
## Raw formats
- [`/help/errors/model_not_locked.json`](/help/errors/model_not_locked.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/model_not_locked.md`](/help/errors/model_not_locked.md) — body only
---
## help/errors/no_compute_member_for_tag.md
# NO_COMPUTE_MEMBER_FOR_TAG — no compute member registered for the required tag
Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the co…
cyoda-go version 0.8.4
# errors.NO_COMPUTE_MEMBER_FOR_TAG
## NAME
NO_COMPUTE_MEMBER_FOR_TAG — the dispatcher found no live cluster node advertising the compute tag required by the workflow or processor.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
Retryable after compute capacity is restored. At least one live node advertising the required tag is required for dispatch to succeed.
## SEE ALSO
- errors
- errors.COMPUTE_MEMBER_DISCONNECTED
- errors.DISPATCH_TIMEOUT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
## Raw formats
- [`/help/errors/no_compute_member_for_tag.json`](/help/errors/no_compute_member_for_tag.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/no_compute_member_for_tag.md`](/help/errors/no_compute_member_for_tag.md) — body only
---
## help/errors/not_found.md
# NOT_FOUND — generic resource not found
Returned by administrative endpoints (key pair lifecycle, trusted-key lifecycle) when the supplied identifier does not match any registered resource. The …
cyoda-go version 0.8.4
# errors.NOT_FOUND
## NAME
NOT_FOUND — the requested resource (key pair, trusted key, or other admin-managed object) does not exist.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Returned by administrative endpoints (key pair lifecycle, trusted-key lifecycle) when the supplied identifier does not match any registered resource. The submitted identifier is never echoed in the response body — only a generic descriptor — so attackers cannot use the response as a reflection oracle. The identifier is logged server-side at INFO for operator correlation.
Domain-specific not-found conditions (entity, model, transition, workflow, search-job) have their own dedicated codes — see SEE ALSO.
Not retryable; the resource must be created or registered before the request can succeed.
## SEE ALSO
- errors
- errors.ENTITY_NOT_FOUND
- errors.MODEL_NOT_FOUND
- errors.KEYPAIR_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors ENTITY_NOT_FOUND`](/help/errors/entity_not_found/) — No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors KEYPAIR_NOT_FOUND`](/help/errors/keypair_not_found/) — Returned by:
## Raw formats
- [`/help/errors/not_found.json`](/help/errors/not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/not_found.md`](/help/errors/not_found.md) — body only
---
## help/errors/not_implemented.md
# NOT_IMPLEMENTED — endpoint is not yet implemented
The route is defined and accepted by the server but the handler returns this error because the feature is pending implementation. Distinct from a `404` — …
cyoda-go version 0.8.4
# errors.NOT_IMPLEMENTED
## NAME
NOT_IMPLEMENTED — the requested endpoint or operation exists in the API contract but has not yet been implemented in this version.
## SYNOPSIS
HTTP: `501` `Not Implemented`. Retryable: `no`.
## DESCRIPTION
The route is defined and accepted by the server but the handler returns this error because the feature is pending implementation. Distinct from a `404` — the endpoint exists without a functional implementation.
Not retryable. The response is identical until a new version is deployed.
## SEE ALSO
- errors
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
## Raw formats
- [`/help/errors/not_implemented.json`](/help/errors/not_implemented.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/not_implemented.md`](/help/errors/not_implemented.md) — body only
---
## help/errors/oidc_invalid_tenant.md
# OIDC_INVALID_TENANT — OIDC provider registration requires UUID-shaped tenant identifier
cyoda treats legal entity identifiers as UUIDs. OIDC provider ownership is\nrecorded as a `uuid.UUID` `OwnerLegalEntityID` field, which keys both the\nper-t…
cyoda-go version 0.8.4
# errors.OIDC_INVALID_TENANT
## NAME
OIDC_INVALID_TENANT — OIDC provider registration requires a UUID-shaped tenant identifier.
## SYNOPSIS
HTTP: `400` `Bad Request` with code `OIDC_INVALID_TENANT` on `POST /oauth/oidc/providers`
when the calling tenant's ID is not a valid UUID.
## DESCRIPTION
cyoda treats legal entity identifiers as UUIDs. OIDC provider ownership is
recorded as a `uuid.UUID` `OwnerLegalEntityID` field, which keys both the
per-tenant KV blob storage and the validated user-context tenant binding at
token validation time.
Non-UUID tenant IDs (e.g. the dev-convenience `default-tenant` string accepted
by `CYODA_BOOTSTRAP_TENANT_ID`) cannot be used to register OIDC providers for
two reasons:
1. **KV collision** — every non-UUID tenant would map to the same
`00000000-0000-0000-0000-000000000000` storage key, allowing cross-tenant
data leakage between all bootstrap deployments.
2. **Synthetic identity** — OIDC-validated tokens issued against such a provider
would carry a fabricated "nil tenant" downstream, breaking tenant-scoped
access control.
Production deployments use UUID-shaped legal entity identifiers and are not
affected by this restriction.
## RESOLUTION
Provision a real tenant with a UUID identifier before registering OIDC providers:
- For bootstrap deployments: set `CYODA_BOOTSTRAP_TENANT_ID` to a valid UUID
(e.g. `CYODA_BOOTSTRAP_TENANT_ID=$(uuidgen)`) and restart the server.
- For non-default tenants in production: ensure the tenant was created with a
UUID identifier and that your M2M credential carries that UUID as `caas_org_id`.
Then retry the `POST /oauth/oidc/providers` registration.
## SEE ALSO
- errors
- errors.OIDC_PROVIDER_DUPLICATE
- config.auth
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors OIDC_PROVIDER_DUPLICATE`](/help/errors/oidc_provider_duplicate/) — Each tenant may register a given `wellKnownConfigUri` only once. Submitting
`POST /oauth/oidc/providers` with a URI that is already registered for the
caller's tenant returns this error.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## Raw formats
- [`/help/errors/oidc_invalid_tenant.json`](/help/errors/oidc_invalid_tenant.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/oidc_invalid_tenant.md`](/help/errors/oidc_invalid_tenant.md) — body only
---
## help/errors/oidc_provider_duplicate.md
# OIDC_PROVIDER_DUPLICATE — provider already registered
Each tenant may register a given `wellKnownConfigUri` only once. Submitting\n`POST /oauth/oidc/providers` with a URI that is already registered for the\ncal…
cyoda-go version 0.8.4
# errors.OIDC_PROVIDER_DUPLICATE
## NAME
OIDC_PROVIDER_DUPLICATE — a provider with the same `wellKnownConfigUri` is already registered for this tenant.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Each tenant may register a given `wellKnownConfigUri` only once. Submitting
`POST /oauth/oidc/providers` with a URI that is already registered for the
caller's tenant returns this error.
To update the existing provider's configuration (issuers, expected audiences,
roles claim), use `PATCH /oauth/oidc/providers/{id}` instead.
## SEE ALSO
- errors
- errors.OIDC_PROVIDER_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors OIDC_PROVIDER_NOT_FOUND`](/help/errors/oidc_provider_not_found/) — The provider UUID supplied in the path parameter does not correspond to a
registered OIDC provider for the caller's tenant. Either the provider was
never registered, was deleted, or the UUID belongs to a different tenant
(cross-tenant existence is not disclosed).
## Raw formats
- [`/help/errors/oidc_provider_duplicate.json`](/help/errors/oidc_provider_duplicate.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/oidc_provider_duplicate.md`](/help/errors/oidc_provider_duplicate.md) — body only
---
## help/errors/oidc_provider_inactive.md
# OIDC_PROVIDER_INACTIVE — provider is invalidated
`PATCH /oauth/oidc/providers/{id}` requires the provider to be in the active\nstate. If the provider has been invalidated via\n`POST /oauth/oidc/providers/{…
cyoda-go version 0.8.4
# errors.OIDC_PROVIDER_INACTIVE
## NAME
OIDC_PROVIDER_INACTIVE — the OIDC provider is currently invalidated and cannot be updated.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
`PATCH /oauth/oidc/providers/{id}` requires the provider to be in the active
state. If the provider has been invalidated via
`POST /oauth/oidc/providers/{id}/invalidate`, this error is returned.
To update an invalidated provider, first reactivate it via
`POST /oauth/oidc/providers/{id}/reactivate`, then apply the update.
## SEE ALSO
- errors
- errors.OIDC_PROVIDER_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors OIDC_PROVIDER_NOT_FOUND`](/help/errors/oidc_provider_not_found/) — The provider UUID supplied in the path parameter does not correspond to a
registered OIDC provider for the caller's tenant. Either the provider was
never registered, was deleted, or the UUID belongs to a different tenant
(cross-tenant existence is not disclosed).
## Raw formats
- [`/help/errors/oidc_provider_inactive.json`](/help/errors/oidc_provider_inactive.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/oidc_provider_inactive.md`](/help/errors/oidc_provider_inactive.md) — body only
---
## help/errors/oidc_provider_not_found.md
# OIDC_PROVIDER_NOT_FOUND — OIDC provider does not exist
The provider UUID supplied in the path parameter does not correspond to a\nregistered OIDC provider for the callers tenant. Either the provider was\nnever …
cyoda-go version 0.8.4
# errors.OIDC_PROVIDER_NOT_FOUND
## NAME
OIDC_PROVIDER_NOT_FOUND — the OIDC provider with the given ID does not exist for this tenant.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
The provider UUID supplied in the path parameter does not correspond to a
registered OIDC provider for the caller's tenant. Either the provider was
never registered, was deleted, or the UUID belongs to a different tenant
(cross-tenant existence is not disclosed).
## SEE ALSO
- errors
- errors.OIDC_PROVIDER_DUPLICATE
- errors.OIDC_PROVIDER_INACTIVE
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors OIDC_PROVIDER_DUPLICATE`](/help/errors/oidc_provider_duplicate/) — Each tenant may register a given `wellKnownConfigUri` only once. Submitting
`POST /oauth/oidc/providers` with a URI that is already registered for the
caller's tenant returns this error.
## Raw formats
- [`/help/errors/oidc_provider_not_found.json`](/help/errors/oidc_provider_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/oidc_provider_not_found.md`](/help/errors/oidc_provider_not_found.md) — body only
---
## help/errors/oidc_ssrf_blocked.md
# OIDC_SSRF_BLOCKED — wellKnownConfigUri blocked by SSRF policy
When registering an OIDC provider, cyoda validates the `wellKnownConfigUri`\nagainst a blocklist of private address ranges (loopback, RFC1918, link-local,\n…
cyoda-go version 0.8.4
# errors.OIDC_SSRF_BLOCKED
## NAME
OIDC_SSRF_BLOCKED — the `wellKnownConfigUri` resolves to a private or link-local
address range that is blocked by the SSRF protection policy.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
When registering an OIDC provider, cyoda validates the `wellKnownConfigUri`
against a blocklist of private address ranges (loopback, RFC1918, link-local,
IPv6 ULA). If the URI's hostname resolves to any blocked range, the
registration is rejected to prevent Server-Side Request Forgery attacks.
Blocked ranges:
- `127.0.0.0/8` — IPv4 loopback
- `169.254.0.0/16` — IPv4 link-local (cloud metadata endpoints)
- `10.0.0.0/8`, `172.16.0.0/12`, `192.168.0.0/16` — RFC1918 private
- `::1/128` — IPv6 loopback
- `fe80::/10` — IPv6 link-local
- `fc00::/7` — IPv6 ULA
In development or controlled environments where private-network OIDC providers
are required, set `CYODA_OIDC_ALLOW_PRIVATE_NETWORKS=true` to bypass this check.
Never use this override in production.
## SEE ALSO
- errors
- config.auth
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## Raw formats
- [`/help/errors/oidc_ssrf_blocked.json`](/help/errors/oidc_ssrf_blocked.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/oidc_ssrf_blocked.md`](/help/errors/oidc_ssrf_blocked.md) — body only
---
## help/errors/precondition_required.md
# PRECONDITION_REQUIRED — PATCH request missing required If-Match header
PATCH applies a merge patch to the entitys stored state rather than replacing it wholesale. Because the patch is applied relative to the current stored d…
cyoda-go version 0.8.4
# errors.PRECONDITION_REQUIRED
## NAME
PRECONDITION_REQUIRED — a PATCH request was submitted without an `If-Match` header, which is mandatory for patch operations.
## SYNOPSIS
HTTP: `428` `Precondition Required`. Retryable: `no`.
## DESCRIPTION
PATCH applies a merge patch to the entity's stored state rather than replacing it wholesale. Because the patch is applied relative to the current stored data, cyoda-go requires the caller to state a precondition explicitly via `If-Match`. Omitting the header entirely is rejected.
This behaviour is specific to PATCH. A PUT without `If-Match` is treated as an unconditional replace and is accepted.
Not retryable as-is — the same request without an `If-Match` header produces the same error.
## RECOVERY
Add an `If-Match` header to the PATCH request. Two modes are supported:
- **Conditional patch** — supply the `transactionId` obtained from your most recent GET of the entity as the `If-Match` value. The patch is applied only if the entity has not changed since that read; a `412 ENTITY_MODIFIED` is returned if another writer has committed in the meantime.
- **Unconditional patch (last-writer-wins)** — supply `If-Match: *` to explicitly accept that the patch will be applied to whatever the current stored state is, without a version check.
Choose the conditional form when you need to detect concurrent modifications; choose `*` when you intentionally want last-writer-wins semantics and have already decided the patch is safe to apply regardless of concurrent changes.
## SEE ALSO
- errors
- errors.ENTITY_MODIFIED
- errors.BAD_REQUEST
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors ENTITY_MODIFIED`](/help/errors/entity_modified/) — When an entity update request carries an `If-Match` header, the server requires the supplied transaction ID to equal the entity's current `meta.transactionId`. A mismatch means another writer has updated the entity since the caller's last read. The optimistic-concurrency guard rejects the update rather than silently overwrite.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
## Raw formats
- [`/help/errors/precondition_required.json`](/help/errors/precondition_required.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/precondition_required.md`](/help/errors/precondition_required.md) — body only
---
## help/errors/schedule_function_invalid_result.md
# SCHEDULE_FUNCTION_INVALID_RESULT — scheduled-transition Function returned an unusable result
A `TransitionSchedule.function` callout must return `resultKind: \Schedule\` with a value shaped `{fireAt|fireAfterMs, expireAt?|expireAfterMs?}` — exactl…
cyoda-go version 0.8.4
# errors.SCHEDULE_FUNCTION_INVALID_RESULT
## NAME
SCHEDULE_FUNCTION_INVALID_RESULT — a scheduled transition's arm-time Function callout completed, but the engine could not interpret its result as a `Schedule`.
## SYNOPSIS
HTTP: `500` `Internal Server Error`. Retryable: `no`.
## DESCRIPTION
A `TransitionSchedule.function` callout must return `resultKind: "Schedule"` with a value shaped `{fireAt|fireAfterMs, expireAt?|expireAfterMs?}` — exactly one of `fireAt`/`fireAfterMs`, and at most one of `expireAt`/`expireAfterMs`. This error is raised when the compute node returns a different `resultKind`, or a `Schedule` value that is malformed: missing or duplicate fire/expiry fields, an unknown field, or a non-numeric value.
A `fireAt` in the past is not an error — the transition is armed to fire immediately. Only a resolved expiry at or before the resolved fire time is treated as a distinct outcome (the arm is skipped and any prior scheduling for the transition is cancelled), not as this error.
The failure is in the compute node's implementation, not the caller's request — the entity write that triggered arming is rejected so no state change commits against an unschedulable transition. Fix the Function's response shape; do not retry until it is corrected.
## SEE ALSO
- errors
- errors.DISPATCH_TIMEOUT
- errors.CONDITION_TYPE_MISMATCH
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
- [`cyoda help errors CONDITION_TYPE_MISMATCH`](/help/errors/condition_type_mismatch/) — Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
## Raw formats
- [`/help/errors/schedule_function_invalid_result.json`](/help/errors/schedule_function_invalid_result.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/schedule_function_invalid_result.md`](/help/errors/schedule_function_invalid_result.md) — body only
---
## help/errors/search_job_already_terminal.md
# SEARCH_JOB_ALREADY_TERMINAL — search job has already completed or failed
Search jobs are long-running asynchronous operations. Once a job reaches a terminal state it cannot be cancelled, resumed, or otherwise modified. This err…
cyoda-go version 0.8.4
# errors.SEARCH_JOB_ALREADY_TERMINAL
## NAME
SEARCH_JOB_ALREADY_TERMINAL — an operation was attempted on a search job that has already reached a terminal state (completed, failed, or cancelled).
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Search jobs are long-running asynchronous operations. Once a job reaches a terminal state it cannot be cancelled, resumed, or otherwise modified. This error is returned when such an operation is attempted on a finished job — `PUT /search/async/{jobId}/cancel` is the only endpoint that raises it.
The response body carries `currentStatus` (`SUCCESSFUL`, `FAILED`, or `CANCELLED`) and `snapshotId`.
Not retryable on the same job. Results from a successfully completed job remain available for retrieval.
## SEE ALSO
- errors
- errors.SEARCH_JOB_NOT_FOUND
- errors.SEARCH_SHARD_TIMEOUT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors SEARCH_JOB_NOT_FOUND`](/help/errors/search_job_not_found/) — Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one tenant is not visible to another.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
## Raw formats
- [`/help/errors/search_job_already_terminal.json`](/help/errors/search_job_already_terminal.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/search_job_already_terminal.md`](/help/errors/search_job_already_terminal.md) — body only
---
## help/errors/search_job_not_found.md
# SEARCH_JOB_NOT_FOUND — search job does not exist
Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one…
cyoda-go version 0.8.4
# errors.SEARCH_JOB_NOT_FOUND
## NAME
SEARCH_JOB_NOT_FOUND — the referenced asynchronous search job does not exist in the current tenant.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one tenant is not visible to another.
Not retryable. The job ID and tenant credentials must match the values used at job submission time.
## SEE ALSO
- errors
- errors.SEARCH_JOB_ALREADY_TERMINAL
- errors.SEARCH_SHARD_TIMEOUT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors SEARCH_JOB_ALREADY_TERMINAL`](/help/errors/search_job_already_terminal/) — Search jobs are long-running asynchronous operations. Once a job reaches a terminal state it cannot be cancelled, resumed, or otherwise modified. This error is returned when such an operation is attempted on a finished job — `PUT /search/async/{jobId}/cancel` is the only endpoint that raises it.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
## Raw formats
- [`/help/errors/search_job_not_found.json`](/help/errors/search_job_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/search_job_not_found.md`](/help/errors/search_job_not_found.md) — body only
---
## help/errors/search_queue_full.md
# SEARCH_QUEUE_FULL — async-search submission was refused for capacity
`POST /api/search/async/{entityName}/{modelVersion}` runs on a bounded worker pool: a fixed number of workers drain a fixed-capacity queue. Submission fai…
cyoda-go version 0.8.4
# errors.SEARCH_QUEUE_FULL
## NAME
SEARCH_QUEUE_FULL — the node refused an async-search submission because its capacity for one is already committed.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
`POST /api/search/async/{entityName}/{modelVersion}` runs on a bounded worker pool: a fixed number of workers drain a fixed-capacity queue. Submission fails fast with this error rather than blocking the request or spawning an unbounded goroutine per submission. The rejected submit leaves nothing behind — no job row, no id to poll.
Two guards raise it, both retryable, both meaning "back off and retry":
- **Node capacity** — no free worker and the submit queue at capacity. Sized by `CYODA_SEARCH_ASYNC_WORKERS` (default `8`) and `CYODA_SEARCH_ASYNC_QUEUE` (default `256`).
- **Tenant share** — your tenant already holds its full share of this node's in-flight jobs. Sized by `CYODA_SEARCH_ASYNC_MAX_PER_TENANT` (default: the worker count; `0` disables the cap). This bound keeps one tenant from consuming the whole pool.
The queue drains as in-flight jobs complete; a client that backs off and retries will typically succeed. Frequent occurrences mean sustained submission volume exceeds what the pool is sized to absorb — raise `CYODA_SEARCH_ASYNC_QUEUE` for burst tolerance, or `CYODA_SEARCH_ASYNC_WORKERS` for sustained throughput (bounded by the storage backend's connection budget: each running job holds a scan connection plus, per chunk, a save connection).
See `cyoda help config` (Search internals) for the variables.
## SEE ALSO
- errors
- errors.SEARCH_SHARD_TIMEOUT
- errors.STORAGE_UNAVAILABLE
- config
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
- [`cyoda help errors STORAGE_UNAVAILABLE`](/help/errors/storage_unavailable/) — Raised in three cases, all transient:
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
## Raw formats
- [`/help/errors/search_queue_full.json`](/help/errors/search_queue_full.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/search_queue_full.md`](/help/errors/search_queue_full.md) — body only
---
## help/errors/search_result_limit.md
# SEARCH_RESULT_LIMIT — search result set exceeds the allowed limit
Direct (synchronous) search is bounded-or-fail: `limit` caps the matched result set rather than paging it. When more entities match than the limit allows,…
cyoda-go version 0.8.4
# errors.SEARCH_RESULT_LIMIT
## NAME
SEARCH_RESULT_LIMIT — the search query's matched entity count exceeded the requested `limit`, a cap on the matched set, not a page size.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Direct (synchronous) search is bounded-or-fail: `limit` caps the matched result set rather than paging it. When more entities match than the limit allows, the request is rejected — it never returns a truncated prefix, because a partial result would be indistinguishable from a complete one.
Not retryable with the same parameters. Narrow the condition, raise `limit` (up to the documented maximum), or use async search, which snapshots the full result set and pages over it.
## SEE ALSO
- errors
- errors.SEARCH_JOB_NOT_FOUND
- errors.SEARCH_SHARD_TIMEOUT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors SEARCH_JOB_NOT_FOUND`](/help/errors/search_job_not_found/) — Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one tenant is not visible to another.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
## Raw formats
- [`/help/errors/search_result_limit.json`](/help/errors/search_result_limit.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/search_result_limit.md`](/help/errors/search_result_limit.md) — body only
---
## help/errors/search_shard_timeout.md
# SEARCH_SHARD_TIMEOUT — a search shard did not respond in time
Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked fail…
cyoda-go version 0.8.4
# errors.SEARCH_SHARD_TIMEOUT
## NAME
SEARCH_SHARD_TIMEOUT — one or more search shards did not respond within the configured timeout, causing the search job to fail.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
Retryable. Frequent timeouts indicate that the query scope, result limit, or cluster configuration requires adjustment.
## SEE ALSO
- errors
- errors.SEARCH_JOB_NOT_FOUND
- errors.DISPATCH_TIMEOUT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors SEARCH_JOB_NOT_FOUND`](/help/errors/search_job_not_found/) — Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one tenant is not visible to another.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
## Raw formats
- [`/help/errors/search_shard_timeout.json`](/help/errors/search_shard_timeout.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/search_shard_timeout.md`](/help/errors/search_shard_timeout.md) — body only
---
## help/errors/search_timeout.md
# SEARCH_TIMEOUT — search timeout expired before results collected
Fires when the client-supplied `timeoutMillis` elapses before the search result set was fully collected. No partial results are returned.
cyoda-go version 0.8.4
# errors.SEARCH_TIMEOUT
## NAME
SEARCH_TIMEOUT — the client-supplied `timeoutMillis` expired before the search result set was collected.
## SYNOPSIS
HTTP: `408` `Request Timeout`. Retryable: `yes`.
## DESCRIPTION
Fires when the client-supplied `timeoutMillis` elapses before the search result set was fully collected. No partial results are returned.
## SEE ALSO
- errors
- errors.SEARCH_SHARD_TIMEOUT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
## Raw formats
- [`/help/errors/search_timeout.json`](/help/errors/search_timeout.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/search_timeout.md`](/help/errors/search_timeout.md) — body only
---
## help/errors/server_error.md
# SERVER_ERROR — unexpected internal server error
The server encountered an unclassified internal error. The response body contains a `ticket` UUID that correlates with the server-side error log. No inter…
cyoda-go version 0.8.4
# errors.SERVER_ERROR
## NAME
SERVER_ERROR — an unexpected error occurred on the server that prevented the request from being fulfilled.
## SYNOPSIS
HTTP: `500` `Internal Server Error`. Retryable: `yes` (with caution).
## DESCRIPTION
The server encountered an unclassified internal error. The response body contains a `ticket` UUID that correlates with the server-side error log. No internal details are exposed in the response.
Retryable with caution. Simple reads may be retried safely. Writes must be treated as potentially applied — the write outcome must be verified before retrying to avoid duplicates. The `ticket` value identifies the server-side error log entry.
## SEE ALSO
- errors
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
## Raw formats
- [`/help/errors/server_error.json`](/help/errors/server_error.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/server_error.md`](/help/errors/server_error.md) — body only
---
## help/errors/storage_unavailable.md
# STORAGE_UNAVAILABLE — storage could not serve the request in time
Raised in three cases, all transient:
cyoda-go version 0.8.4
# errors.STORAGE_UNAVAILABLE
## NAME
STORAGE_UNAVAILABLE — the storage layer could not supply a connection, or the transaction the request was running in is gone.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
Raised in three cases, all transient:
- The connection pool could not supply a connection within `CYODA_POSTGRES_ACQUIRE_TIMEOUT` (default `10s`). Writes, and reads that need a second connection while your transaction already holds one (a point-in-time read or an async-search submit issued inside a transaction), fail fast here rather than queueing behind a saturated pool.
- An operation found its transaction already aborted because the connection sat idle inside it for longer than `CYODA_POSTGRES_IDLE_IN_TX_TIMEOUT` (default `5m`). The usual cause is a workflow processor whose `responseTimeoutMs` exceeds that ceiling.
- The database connection went away underneath the operation — the session was terminated, or the network dropped it.
Retryable. The same request may well succeed on a second attempt. Repeated occurrences mean the pool is undersized for the offered load, a workflow holds transactions open across a callout longer than the ceiling allows, or the link to the database is unstable.
A statement cancelled by `CYODA_POSTGRES_STATEMENT_TIMEOUT` is **not** reported here. Re-running it would exceed the same ceiling again, so it is a `500` with a ticket rather than a retryable `503`; the server log names the setting that fired.
See `cyoda help config database` for the pool and ceiling settings.
## SEE ALSO
- errors
- errors.CONFLICT
- config.database
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
## Raw formats
- [`/help/errors/storage_unavailable.json`](/help/errors/storage_unavailable.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/storage_unavailable.md`](/help/errors/storage_unavailable.md) — body only
---
## help/errors/transaction_expired.md
# TRANSACTION_EXPIRED — transaction token has expired
Transaction tokens are short-lived bearer tokens issued when a transaction is opened. This error fires when the tokens `exp` claim is in the past at the …
cyoda-go version 0.8.4
# errors.TRANSACTION_EXPIRED
## NAME
TRANSACTION_EXPIRED — the transaction token presented to the proxy is past its expiry time.
## SYNOPSIS
HTTP: `410` `Gone`. Retryable: `no`.
## DESCRIPTION
Transaction tokens are short-lived bearer tokens issued when a transaction is opened. This error fires when the token's `exp` claim is in the past at the time the proxy validates it. The transaction itself may still be active server-side, but the token is no longer valid for routing.
Not retryable with the same token. The original transaction must be committed or rolled back before opening a new one.
## SEE ALSO
- errors
- errors.TRANSACTION_NOT_FOUND
- errors.TRANSACTION_NODE_UNAVAILABLE
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TRANSACTION_NOT_FOUND`](/help/errors/transaction_not_found/) — The transaction ID supplied in the request does not correspond to an active transaction. The transaction may have been committed, rolled back, expired, or may never have existed. Also occurs when a request is mis-routed to a node that never opened the transaction.
- [`cyoda help errors TRANSACTION_NODE_UNAVAILABLE`](/help/errors/transaction_node_unavailable/) — Transaction state is pinned to the node that opened it. If that node crashes or becomes unreachable while the transaction is in progress, subsequent requests using the transaction token are rejected with this error because the proxy cannot forward them to the owner.
## Raw formats
- [`/help/errors/transaction_expired.json`](/help/errors/transaction_expired.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/transaction_expired.md`](/help/errors/transaction_expired.md) — body only
---
## help/errors/transaction_node_unavailable.md
# TRANSACTION_NODE_UNAVAILABLE — the node owning the transaction is unreachable
Transaction state is pinned to the node that opened it. If that node crashes or becomes unreachable while the transaction is in progress, subsequent reque…
cyoda-go version 0.8.4
# errors.TRANSACTION_NODE_UNAVAILABLE
## NAME
TRANSACTION_NODE_UNAVAILABLE — the cluster node that owns the open transaction is not alive or reachable.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `yes`.
## DESCRIPTION
Transaction state is pinned to the node that opened it. If that node crashes or becomes unreachable while the transaction is in progress, subsequent requests using the transaction token are rejected with this error because the proxy cannot forward them to the owner.
Retryable by opening a new transaction. The in-progress transaction is likely lost. Mid-transaction node failure requires the client to restart the transaction from scratch.
## SEE ALSO
- errors
- errors.TRANSACTION_EXPIRED
- errors.TRANSACTION_NOT_FOUND
- errors.CLUSTER_NODE_NOT_REGISTERED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TRANSACTION_EXPIRED`](/help/errors/transaction_expired/) — Transaction tokens are short-lived bearer tokens issued when a transaction is opened. This error fires when the token's `exp` claim is in the past at the time the proxy validates it. The transaction itself may still be active server-side, but the token is no longer valid for routing.
- [`cyoda help errors TRANSACTION_NOT_FOUND`](/help/errors/transaction_not_found/) — The transaction ID supplied in the request does not correspond to an active transaction. The transaction may have been committed, rolled back, expired, or may never have existed. Also occurs when a request is mis-routed to a node that never opened the transaction.
- [`cyoda help errors CLUSTER_NODE_NOT_REGISTERED`](/help/errors/cluster_node_not_registered/) — The request was routed to or requires a specific cluster node that is not present in the registry. Occurs during startup, rolling restarts, or after a node failure before the gossip layer has converged.
## Raw formats
- [`/help/errors/transaction_node_unavailable.json`](/help/errors/transaction_node_unavailable.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/transaction_node_unavailable.md`](/help/errors/transaction_node_unavailable.md) — body only
---
## help/errors/transaction_not_found.md
# TRANSACTION_NOT_FOUND — transaction ID does not exist
The transaction ID supplied in the request does not correspond to an active transaction. The transaction may have been committed, rolled back, expired, or…
cyoda-go version 0.8.4
# errors.TRANSACTION_NOT_FOUND
## NAME
TRANSACTION_NOT_FOUND — no transaction with the given ID exists on this node.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
The transaction ID supplied in the request does not correspond to an active transaction. The transaction may have been committed, rolled back, expired, or may never have existed. Also occurs when a request is mis-routed to a node that never opened the transaction.
Not retryable. Transaction state (committed, rolled back, expired) determines whether the transaction existed.
## SEE ALSO
- errors
- errors.TRANSACTION_EXPIRED
- errors.TRANSACTION_NODE_UNAVAILABLE
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TRANSACTION_EXPIRED`](/help/errors/transaction_expired/) — Transaction tokens are short-lived bearer tokens issued when a transaction is opened. This error fires when the token's `exp` claim is in the past at the time the proxy validates it. The transaction itself may still be active server-side, but the token is no longer valid for routing.
- [`cyoda help errors TRANSACTION_NODE_UNAVAILABLE`](/help/errors/transaction_node_unavailable/) — Transaction state is pinned to the node that opened it. If that node crashes or becomes unreachable while the transaction is in progress, subsequent requests using the transaction token are rejected with this error because the proxy cannot forward them to the owner.
## Raw formats
- [`/help/errors/transaction_not_found.json`](/help/errors/transaction_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/transaction_not_found.md`](/help/errors/transaction_not_found.md) — body only
---
## help/errors/transaction_timeout.md
# TRANSACTION_TIMEOUT — transaction timeout expired before commit
Fires when the client-supplied `transactionTimeoutMillis` elapses before the first commit. Nothing was committed.
cyoda-go version 0.8.4
# errors.TRANSACTION_TIMEOUT
## NAME
TRANSACTION_TIMEOUT — the client-supplied `transactionTimeoutMillis` expired before the first commit.
## SYNOPSIS
HTTP: `408` `Request Timeout`. Retryable: `yes`.
## DESCRIPTION
Fires when the client-supplied `transactionTimeoutMillis` elapses before the first commit. Nothing was committed.
On multi-commit operations (chunked collections, commit-before-dispatch workflows) the timeout applies only until the first commit — failures after that surface through the per-chunk contract instead.
## SEE ALSO
- errors
- errors.TRANSACTION_EXPIRED
- crud
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TRANSACTION_EXPIRED`](/help/errors/transaction_expired/) — Transaction tokens are short-lived bearer tokens issued when a transaction is opened. This error fires when the token's `exp` claim is in the past at the time the proxy validates it. The transaction itself may still be active server-side, but the token is no longer valid for routing.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
## Raw formats
- [`/help/errors/transaction_timeout.json`](/help/errors/transaction_timeout.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/transaction_timeout.md`](/help/errors/transaction_timeout.md) — body only
---
## help/errors/transition_not_found.md
# TRANSITION_NOT_FOUND — workflow transition does not exist
Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the mode…
cyoda-go version 0.8.4
# errors.TRANSITION_NOT_FOUND
## NAME
TRANSITION_NOT_FOUND — the requested workflow transition is not defined for the entity's current state.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the model's workflow definition for the entity's current state. Also occurs when the transition name is misspelled, when the transition is disabled, when it is a scheduled transition (those fire on their timer and are never manually fireable), or when the entity is in a terminal state that allows no further transitions.
The workflow consulted is the one the entity's selection criterion binds it to, not merely one that declares the state — see `cyoda help workflows`, *Workflow-level selection*. On a model with several workflows, a transition can therefore be valid for one entity and absent for another in the same state.
Not retryable. The workflow definition and the entity's current state determine which transition names are valid.
## SEE ALSO
- errors
- errors.WORKFLOW_NOT_FOUND
- errors.WORKFLOW_FAILED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors WORKFLOW_NOT_FOUND`](/help/errors/workflow_not_found/) — Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenant's workflow registry, during entity type registration or when a model references a workflow that was deleted.
- [`cyoda help errors WORKFLOW_FAILED`](/help/errors/workflow_failed/) — During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
## Raw formats
- [`/help/errors/transition_not_found.json`](/help/errors/transition_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/transition_not_found.md`](/help/errors/transition_not_found.md) — body only
---
## help/errors/trusted_key_cap_reached.md
# TRUSTED_KEY_CAP_REACHED — tenant trusted-key cap reached
`POST /oauth/keys/trusted` enforces a per-tenant cap (default 10, configurable via `CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT`). The cap counts only currently-…
cyoda-go version 0.8.4
# errors.TRUSTED_KEY_CAP_REACHED
## NAME
TRUSTED_KEY_CAP_REACHED — the tenant has reached the maximum registered trusted keys.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
`POST /oauth/keys/trusted` enforces a per-tenant cap (default 10, configurable via `CYODA_IAM_TRUSTED_KEY_MAX_PER_TENANT`). The cap counts only currently-valid keys (Active and not past `validTo`). Delete or invalidate older keys, or raise the cap.
## SEE ALSO
- errors
- config.auth
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## Raw formats
- [`/help/errors/trusted_key_cap_reached.json`](/help/errors/trusted_key_cap_reached.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/trusted_key_cap_reached.md`](/help/errors/trusted_key_cap_reached.md) — body only
---
## help/errors/trusted_key_not_found.md
# TRUSTED_KEY_NOT_FOUND — referenced trusted key does not exist
Returned by trusted-key admin endpoints when the supplied KID does not match any registered key:
cyoda-go version 0.8.4
# errors.TRUSTED_KEY_NOT_FOUND
## NAME
TRUSTED_KEY_NOT_FOUND — an admin operation referenced a trusted-key KID that is not present in the registry.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Returned by trusted-key admin endpoints when the supplied KID does not match any registered key:
- `DELETE /oauth/keys/trusted/{keyId}` — the deletion target does not exist.
- `POST /oauth/keys/trusted/{keyId}/invalidate` — the lifecycle target does not exist.
- `POST /oauth/keys/trusted/{keyId}/reactivate` — the lifecycle target does not exist.
The detail field carries a generic `key not found` message; internal store phrasing (e.g. backend-specific KID echoes) is never leaked into the response body. Operators can correlate the request via the slog event emitted server-side at INFO level with `kid` and the underlying error.
Not retryable. Verify the KID via `GET /oauth/keys/trusted` before retrying the operation.
Returned uniformly for kids that don't exist AND kids owned by another tenant; the response does not distinguish — by design, to prevent cross-tenant existence enumeration.
## SEE ALSO
- errors
- errors.UNAUTHORIZED
- errors.FORBIDDEN
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors UNAUTHORIZED`](/help/errors/unauthorized/) — Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
## Raw formats
- [`/help/errors/trusted_key_not_found.json`](/help/errors/trusted_key_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/trusted_key_not_found.md`](/help/errors/trusted_key_not_found.md) — body only
---
## help/errors/tx_conflict.md
# TX_CONFLICT — transaction-level conflict
Reserved. Not currently emitted by any cyoda-go code path.
cyoda-go version 0.8.4
# errors.TX_CONFLICT
## NAME
TX_CONFLICT — the operation was aborted because of a transaction-level conflict.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `yes`.
## DESCRIPTION
Reserved. Not currently emitted by any cyoda-go code path.
Storage-layer serialization failures (e.g., PostgreSQL `40001`/`40P01`) surface
as `CONFLICT` (not `TX_CONFLICT`) in the current implementation. `TX_CONFLICT`
is reserved to distinguish a future transaction-level conflict signal from the
existing entity-level `CONFLICT` code — for example, a conflict detected at
the transaction boundary rather than at an individual entity write.
Retryable. The full transaction — including any reads performed inside it —
must be restarted from the beginning.
## SEE ALSO
- errors
- errors.CONFLICT
- errors.EPOCH_MISMATCH
- errors.IDEMPOTENCY_CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors EPOCH_MISMATCH`](/help/errors/epoch_mismatch/) — Shard ownership is tracked by an epoch counter that increments whenever the cluster re-partitions. A write is rejected with this error when the writing node's cached epoch is stale — another node has since taken ownership of the shard. This prevents split-brain writes.
- [`cyoda help errors IDEMPOTENCY_CONFLICT`](/help/errors/idempotency_conflict/) — The idempotency key is supplied via the `Idempotency-Key` HTTP header on collection create and update requests. See `crud` for the request shape.
## Raw formats
- [`/help/errors/tx_conflict.json`](/help/errors/tx_conflict.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/tx_conflict.md`](/help/errors/tx_conflict.md) — body only
---
## help/errors/tx_coordinator_not_configured.md
# TX_COORDINATOR_NOT_CONFIGURED — distributed transaction coordination not available
Reserved. Not currently emitted by any cyoda-go code path.
cyoda-go version 0.8.4
# errors.TX_COORDINATOR_NOT_CONFIGURED
## NAME
TX_COORDINATOR_NOT_CONFIGURED — a requested capability requires distributed transaction coordination that is not available on this node.
## SYNOPSIS
HTTP: `503` `Service Unavailable`. Retryable: `no`.
## DESCRIPTION
Reserved. Not currently emitted by any cyoda-go code path.
cyoda-go does not run a distributed two-phase-commit coordinator. Transactions
are request-scoped and owned by the node that began them. A signed tx-token
(`{NodeID, TxRef}`) carries the owning node's identity so that callbacks and
subsequent requests in the same transaction are routed to the correct node
without any external coordinator.
This error code is reserved for a future capability where distributed
multi-transaction coordination may be required. If you receive it from a
current cyoda-go release, it indicates an unexpected condition; raise a support
ticket.
## SEE ALSO
- errors
- errors.TX_REQUIRED
- errors.TX_NO_STATE
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TX_REQUIRED`](/help/errors/tx_required/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors TX_NO_STATE`](/help/errors/tx_no_state/) — Reserved. Not currently emitted by any cyoda-go code path.
## Raw formats
- [`/help/errors/tx_coordinator_not_configured.json`](/help/errors/tx_coordinator_not_configured.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/tx_coordinator_not_configured.md`](/help/errors/tx_coordinator_not_configured.md) — body only
---
## help/errors/tx_no_state.md
# TX_NO_STATE — no transaction state record found
Reserved. Not currently emitted by any cyoda-go code path.
cyoda-go version 0.8.4
# errors.TX_NO_STATE
## NAME
TX_NO_STATE — no state record exists for the referenced transaction.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Reserved. Not currently emitted by any cyoda-go code path.
In the current model, transaction outcomes are tracked in-memory on the owning
node for a bounded TTL window. There is no persistent two-phase-commit state
log tracking prepare/commit/abort phases. A transaction that has expired from
the in-memory window is reported as `TRANSACTION_NOT_FOUND`.
This error code is reserved for a future capability involving persistent
per-transaction state records. If you receive it from a current cyoda-go
release, it indicates an unexpected condition; raise a support ticket.
## SEE ALSO
- errors
- errors.TX_REQUIRED
- errors.TX_COORDINATOR_NOT_CONFIGURED
- errors.TRANSACTION_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TX_REQUIRED`](/help/errors/tx_required/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors TX_COORDINATOR_NOT_CONFIGURED`](/help/errors/tx_coordinator_not_configured/) — Reserved. Not currently emitted by any cyoda-go code path.
- [`cyoda help errors TRANSACTION_NOT_FOUND`](/help/errors/transaction_not_found/) — The transaction ID supplied in the request does not correspond to an active transaction. The transaction may have been committed, rolled back, expired, or may never have existed. Also occurs when a request is mis-routed to a node that never opened the transaction.
## Raw formats
- [`/help/errors/tx_no_state.json`](/help/errors/tx_no_state.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/tx_no_state.md`](/help/errors/tx_no_state.md) — body only
---
## help/errors/tx_required.md
# TX_REQUIRED — operation must be performed inside a transaction
Reserved. Not currently emitted by any cyoda-go code path.
cyoda-go version 0.8.4
# errors.TX_REQUIRED
## NAME
TX_REQUIRED — the requested operation can only be performed within an open transaction but no transaction context was provided.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Reserved. Not currently emitted by any cyoda-go code path.
This error code is reserved for future capabilities where certain operations
explicitly require an open transaction context. In the current model,
transactions are opened automatically per request and the caller does not
supply a pre-existing transaction ID to standard CRUD endpoints.
Not retryable without a transaction context.
## SEE ALSO
- errors
- errors.TX_CONFLICT
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TX_CONFLICT`](/help/errors/tx_conflict/) — Reserved. Not currently emitted by any cyoda-go code path.
## Raw formats
- [`/help/errors/tx_required.json`](/help/errors/tx_required.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/tx_required.md`](/help/errors/tx_required.md) — body only
---
## help/errors/unauthorized.md
# UNAUTHORIZED — authentication required or token invalid
Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted …
cyoda-go version 0.8.4
# errors.UNAUTHORIZED
## NAME
UNAUTHORIZED — the request does not include valid authentication credentials or the provided token failed verification.
## SYNOPSIS
HTTP: `401` `Unauthorized`. Retryable: `no`.
## DESCRIPTION
Returned when the `Authorization` header is missing, the bearer token is expired, the token signature is invalid, or the token was issued by an untrusted issuer. Also returned when a request reaches a protected route with no identity context established by the auth middleware.
Not retryable with the same token. A fresh `Authorization: Bearer ` header is required.
## SEE ALSO
- errors
- errors.FORBIDDEN
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors FORBIDDEN`](/help/errors/forbidden/) — The request was authenticated successfully but the caller's JWT claims do not include the role required by the endpoint (for example, `admin` is required for administrative operations). Tenant mismatch — where the caller's tenant does not match the resource — also produces this error.
## Raw formats
- [`/help/errors/unauthorized.json`](/help/errors/unauthorized.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/unauthorized.md`](/help/errors/unauthorized.md) — body only
---
## help/errors/unique_violation.md
# UNIQUE_VIOLATION — composite unique key constraint violated
The entity payload contains field values that collide with an existing entitys composite unique key. Unlike an optimistic-concurrency CONFLICT (which is …
cyoda-go version 0.8.4
# errors.UNIQUE_VIOLATION
## NAME
UNIQUE_VIOLATION — a write was rejected because it would create a duplicate entry for a declared composite unique key.
## SYNOPSIS
HTTP: `409` `Conflict`. Retryable: `no`.
## DESCRIPTION
The entity payload contains field values that collide with an existing entity's composite unique key. Unlike an optimistic-concurrency CONFLICT (which is retryable), a unique-key violation is a permanent data constraint — retrying the same payload without changing the key field values will produce the same result.
To resolve: change the values of the fields that form the unique key so they no longer duplicate an existing entity.
On write-time backends (PostgreSQL) this can also fire within one transaction when a value is claimed before its holder is freed; free-before-claim is portable (see `cyoda help models`).
## SEE ALSO
- errors
- errors.CONFLICT
- errors.INVALID_UNIQUE_KEY
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors CONFLICT`](/help/errors/conflict/) — The server detected that the entity was modified by another writer between the time it was read and the time the current write was committed. Normal outcome under concurrent load.
- [`cyoda help errors INVALID_UNIQUE_KEY`](/help/errors/invalid_unique_key/) — A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at least one key field, or the value cannot be normalized to a valid claim (for example, a NaN or ±Infinity for a numeric key field).
## Raw formats
- [`/help/errors/unique_violation.json`](/help/errors/unique_violation.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/unique_violation.md`](/help/errors/unique_violation.md) — body only
---
## help/errors/unsupported_algorithm.md
# UNSUPPORTED_ALGORITHM — algorithm not supported
cyoda-go v0.8.0 signs and verifies only `RS256`. Other enum values declared in the OpenAPI spec (`RS384`, `RS512`, `PS256`, `PS384`, `PS512`, `ES256`, `ES…
cyoda-go version 0.8.4
# errors.UNSUPPORTED_ALGORITHM
## NAME
UNSUPPORTED_ALGORITHM — the requested JWT algorithm is not implemented in this version.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
cyoda-go v0.8.0 signs and verifies only `RS256`. Other enum values declared in the OpenAPI spec (`RS384`, `RS512`, `PS256`, `PS384`, `PS512`, `ES256`, `ES384`, `ES512`, `EdDSA`) are rejected with this error. Cyoda Cloud supports the full enum; parity is tracked in a v0.8.1 follow-up.
Use `algorithm: RS256` or omit the field.
## SEE ALSO
- errors
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
## Raw formats
- [`/help/errors/unsupported_algorithm.json`](/help/errors/unsupported_algorithm.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/unsupported_algorithm.md`](/help/errors/unsupported_algorithm.md) — body only
---
## help/errors/unsupported_key_type.md
# UNSUPPORTED_KEY_TYPE — JWK kty not supported
`POST /oauth/keys/trusted` accepts only `kty: \RSA\` in v0.8.0. Cloud also supports `kty: \EC\` and `kty: \OKP\`; cyoda-go parity is tracked in a v0.8.1 f…
cyoda-go version 0.8.4
# errors.UNSUPPORTED_KEY_TYPE
## NAME
UNSUPPORTED_KEY_TYPE — the JWK `kty` is not supported by this cyoda-go version.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
`POST /oauth/keys/trusted` accepts only `kty: "RSA"` in v0.8.0. Cloud also supports `kty: "EC"` and `kty: "OKP"`; cyoda-go parity is tracked in a v0.8.1 follow-up.
## SEE ALSO
- errors
- errors.UNSUPPORTED_ALGORITHM
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors UNSUPPORTED_ALGORITHM`](/help/errors/unsupported_algorithm/) — cyoda-go v0.8.0 signs and verifies only `RS256`. Other enum values declared in the OpenAPI spec (`RS384`, `RS512`, `PS256`, `PS384`, `PS512`, `ES256`, `ES384`, `ES512`, `EdDSA`) are rejected with this error. Cyoda Cloud supports the full enum; parity is tracked in a v0.8.1 follow-up.
## Raw formats
- [`/help/errors/unsupported_key_type.json`](/help/errors/unsupported_key_type.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/unsupported_key_type.md`](/help/errors/unsupported_key_type.md) — body only
---
## help/errors/unsupported_media_type.md
# UNSUPPORTED_MEDIA_TYPE — PATCH format or Content-Type not supported
Returned by PATCH in two situations:
cyoda-go version 0.8.4
# errors.UNSUPPORTED_MEDIA_TYPE
## NAME
UNSUPPORTED_MEDIA_TYPE — the PATCH request used a format or `Content-Type` that is not supported.
## SYNOPSIS
HTTP: `415` `Unsupported Media Type`. Retryable: `no`.
## DESCRIPTION
Returned by PATCH in two situations:
- The `{format}` path segment is not `JSON`. Merge patch is JSON-only; other format values (e.g. `CSV`) are not accepted for PATCH requests.
- The `Content-Type` header names a patch dialect that is not recognised. Only `application/merge-patch+json` (RFC 7386) is implemented.
Note that `application/json-patch+json` (RFC 6902, JSON Patch) is a recognised dialect but is not implemented; requests using that content type receive `501 NOT_IMPLEMENTED`, not `415`.
Not retryable as-is — the same request produces the same error until the format or content type is corrected.
## RECOVERY
Use `JSON` as the `{format}` path segment and set `Content-Type: application/merge-patch+json` in the request. Merge patch (RFC 7386) describes the delta as a JSON object whose keys are merged into the stored entity; keys present in the patch overwrite stored values, and keys explicitly set to `null` remove the field.
## SEE ALSO
- errors
- errors.NOT_IMPLEMENTED
- errors.BAD_REQUEST
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors NOT_IMPLEMENTED`](/help/errors/not_implemented/) — The route is defined and accepted by the server but the handler returns this error because the feature is pending implementation. Distinct from a `404` — the endpoint exists without a functional implementation.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
## Raw formats
- [`/help/errors/unsupported_media_type.json`](/help/errors/unsupported_media_type.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/unsupported_media_type.md`](/help/errors/unsupported_media_type.md) — body only
---
## help/errors/validation_failed.md
# VALIDATION_FAILED — payload fails model schema validation
Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed a…
cyoda-go version 0.8.4
# errors.VALIDATION_FAILED
## NAME
VALIDATION_FAILED — the request payload is structurally valid JSON but fails the model's schema or workflow validation rules.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
- a field the model does not declare (`unexpected field not present in model`)
- a value whose JSON kind the field does not declare (`expected scalar, got array`)
- a change the model's `changeLevel` does not permit
- a field name the wire `jsonPath` grammar cannot address
On a workflow import (`POST /model/{entityName}/{modelVersion}/workflow/import`), this is also the code for a structural content violation, including a criterion `group` clause whose `operator` is not `AND`, `OR`, or `NOT`, or a `NOT` group whose `conditions` does not hold exactly one entry — see `workflows` and `predicates`. This is a grammar-only check at import time; it does not verify that the model declares every field a criterion names (see `errors.WORKFLOW_FAILED`).
It is also returned by the model import for sample data that is neither a document nor a collection of documents, and by the workflow import for a structural violation. The error detail names the offending path or key.
A leaf value whose DataType is not assignable carries the more specific `INCOMPATIBLE_TYPE` instead, with `fieldPath`, `expectedType` and `actualType` in `properties`. Missing fields are NOT an error: a model describes the structure it has observed, not a set of required fields.
Correct the payload to match the model, or extend the model — export it and compare.
## SEE ALSO
- errors
- errors.BAD_REQUEST
- errors.WORKFLOW_FAILED
- workflows
- predicates
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help errors WORKFLOW_FAILED`](/help/errors/workflow_failed/) — During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help predicates`](/help/predicates/) — predicates — operator catalog and evaluation semantics for the `Condition` DSL used by search (`cyoda help search`) and workflow/transition criteria (`cyoda help workflows`). Both consume the same kernel, so everything here applies identically to both.
## Raw formats
- [`/help/errors/validation_failed.json`](/help/errors/validation_failed.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/validation_failed.md`](/help/errors/validation_failed.md) — body only
---
## help/errors/workflow_failed.md
# WORKFLOW_FAILED — workflow processor returned an error
During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of th…
cyoda-go version 0.8.4
# errors.WORKFLOW_FAILED
## NAME
WORKFLOW_FAILED — a workflow processor or guard condition returned a failure during entity state transition, or returned data the model rejects.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
Three further causes are not processor failures at all, and reach the read endpoints `GET /entity/{entityId}/transitions` and `GET /platform-api/entity/fetch/transitions` as well as the write paths:
- The workflow selected for the entity does not declare its current state. Selection is by criterion and is re-evaluated on every call, so a data change can bind an entity to a definition that does not model the state it is parked in. The engine rejects rather than falling through to another definition that happens to declare it.
- A workflow selection criterion could not be evaluated. Where the cause is an unavailable compute member the error is `NO_COMPUTE_MEMBER_FOR_TAG` (`503`, retryable) instead.
- **A transition or workflow criterion cannot be evaluated.** Import validates a criterion's path grammar, operator names, and pattern operands, but not against the model — a model may legitimately be declared after the workflow that references it. If, when the criterion is evaluated, it names a field the model still does not declare, or names an operator nobody recognises, or carries an operand a declared type cannot satisfy, the save that triggered the evaluation is aborted and rolled back — no entity write, no state transition, no partial effect. This applies to every operator, including a `NOT` group's child leaf. See `docs/cloud-parity/unevaluable-criterion-fails-save.md`.
Not retryable unless the underlying condition has changed. The failure originates from application logic in the processor, or from the workflow configuration; the data, the processor implementation, or the workflow configuration determines the outcome.
## SEE ALSO
- errors
- errors.WORKFLOW_NOT_FOUND
- errors.TRANSITION_NOT_FOUND
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors WORKFLOW_NOT_FOUND`](/help/errors/workflow_not_found/) — Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenant's workflow registry, during entity type registration or when a model references a workflow that was deleted.
- [`cyoda help errors TRANSITION_NOT_FOUND`](/help/errors/transition_not_found/) — Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the model's workflow definition for the entity's current state. Also occurs when the transition name is misspelled, when the transition is disabled, when it is a scheduled transition (those fire on their timer and are never manually fireable), or when the entity is in a terminal state that allows no further transitions.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
## Raw formats
- [`/help/errors/workflow_failed.json`](/help/errors/workflow_failed.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/workflow_failed.md`](/help/errors/workflow_failed.md) — body only
---
## help/errors/workflow_not_found.md
# WORKFLOW_NOT_FOUND — workflow definition does not exist
Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenants wor…
cyoda-go version 0.8.4
# errors.WORKFLOW_NOT_FOUND
## NAME
WORKFLOW_NOT_FOUND — the workflow definition referenced by the entity model or the request does not exist.
## SYNOPSIS
HTTP: `404` `Not Found`. Retryable: `no`.
## DESCRIPTION
Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenant's workflow registry, during entity type registration or when a model references a workflow that was deleted.
Not retryable. Associating a model with a workflow requires the workflow to exist in the tenant's registry.
## SEE ALSO
- errors
- errors.TRANSITION_NOT_FOUND
- errors.WORKFLOW_FAILED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help errors TRANSITION_NOT_FOUND`](/help/errors/transition_not_found/) — Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the model's workflow definition for the entity's current state. Also occurs when the transition name is misspelled, when the transition is disabled, when it is a scheduled transition (those fire on their timer and are never manually fireable), or when the entity is in a terminal state that allows no further transitions.
- [`cyoda help errors WORKFLOW_FAILED`](/help/errors/workflow_failed/) — During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
## Raw formats
- [`/help/errors/workflow_not_found.json`](/help/errors/workflow_not_found.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/workflow_not_found.md`](/help/errors/workflow_not_found.md) — body only
---
## help/errors/workflow_schema_version_unsupported.md
# WORKFLOW_SCHEMA_VERSION_UNSUPPORTED — workflow schema version not accepted
Every workflow definition must declare a schema version in `MAJOR.MINOR` format (for example `\version\: \1.1\`). This error is returned when the import r…
cyoda-go version 0.8.4
# errors.WORKFLOW_SCHEMA_VERSION_UNSUPPORTED
## NAME
WORKFLOW_SCHEMA_VERSION_UNSUPPORTED — the workflow definition uses a schema version that this server does not accept.
## SYNOPSIS
HTTP: `400` `Bad Request`. Retryable: `no`.
## DESCRIPTION
Every workflow definition must declare a schema version in `MAJOR.MINOR` format (for example `"version": "1.1"`). This error is returned when the import request contains a version string that does not match any supported schema version.
Common causes:
- The `"version"` field is a bare integer (e.g. `"1"`) instead of `MAJOR.MINOR` (e.g. `"1.1"`).
- The `"version"` field refers to a future or deprecated schema revision not supported by this server build. v0.8.0 retires the `1.0` minor used by release/v0.7.x; payloads stamped `"1.0"` are rejected and must be regenerated against `1.1`.
- The `"version"` field is missing from one or more workflow objects in the import payload.
Correct the `"version"` field in every workflow object within the `workflows` array to use `"1.1"` (or the current supported version), then resubmit the import request.
Discover the current supported set via `cyoda help workflows schema-version versions` or `GET /help/workflows/schema-version/versions`.
## SEE ALSO
- errors
- workflows.schema-version
- errors.WORKFLOW_NOT_FOUND
- errors.VALIDATION_FAILED
## See also
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help workflows schema-version`](/help/workflows/schema-version/) — workflows schema-version — semver `MAJOR.MINOR` contract identifying the workflow-import DTO shape that a workflow definition was authored against.
- [`cyoda help errors WORKFLOW_NOT_FOUND`](/help/errors/workflow_not_found/) — Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenant's workflow registry, during entity type registration or when a model references a workflow that was deleted.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
## Raw formats
- [`/help/errors/workflow_schema_version_unsupported.json`](/help/errors/workflow_schema_version_unsupported.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/errors/workflow_schema_version_unsupported.md`](/help/errors/workflow_schema_version_unsupported.md) — body only
---
## help/grpc.md
# grpc — gRPC service contract
cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.…
cyoda-go version 0.8.4
# grpc
## NAME
grpc — gRPC service contract for compute members and entity management.
## SYNOPSIS
```
grpcurl -plaintext localhost:9090 list
grpcurl -plaintext localhost:9090 org.cyoda.cloud.api.grpc.CloudEventsService/StartStreaming
```
## DESCRIPTION
cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
The primary use case is the compute member protocol: external workflow processors subscribe via `StartStreaming`, receive processor and criteria calculation requests, and respond over the same bidirectional stream.
The secondary use case is programmatic entity and model management: `entityManage`, `entityManageCollection`, `entityModelManage`, `entitySearch`, and `entitySearchCollection` allow gRPC clients to perform the same CRUD operations as the REST API.
## CONNECTION
**Endpoint**: `host:CYODA_GRPC_PORT` (default `localhost:9090`).
**Transport**: plaintext TCP by default. TLS termination is handled by the ingress or service mesh in production deployments.
**Authentication**: Bearer token passed as gRPC metadata key `authorization`. The value is the same `Bearer ` string as used in the HTTP API. Both mock IAM and JWT modes apply identically to gRPC connections — the auth interceptor extracts the `authorization` metadata value, builds an `http.Request` with that `Authorization` header, and delegates to the configured `AuthenticationService`.
**OTel tracing**: when `CYODA_OTEL_ENABLED=true`, the gRPC server installs an `otelgrpc.NewServerHandler()` stats handler that creates spans for every inbound RPC.
## SERVICES
The proto package is `org.cyoda.cloud.api.grpc`. The Go package is `github.com/cyoda-platform/cyoda-go/api/grpc/cyoda`.
```proto
syntax = "proto3";
package org.cyoda.cloud.api.grpc;
service CloudEventsService {
rpc startStreaming(stream io.cloudevents.v1.CloudEvent)
returns (stream io.cloudevents.v1.CloudEvent);
rpc entityModelManage(io.cloudevents.v1.CloudEvent)
returns (io.cloudevents.v1.CloudEvent);
rpc entityManage(io.cloudevents.v1.CloudEvent)
returns (io.cloudevents.v1.CloudEvent);
rpc entityManageCollection(io.cloudevents.v1.CloudEvent)
returns (stream io.cloudevents.v1.CloudEvent);
rpc entitySearch(io.cloudevents.v1.CloudEvent)
returns (io.cloudevents.v1.CloudEvent);
rpc entitySearchCollection(io.cloudevents.v1.CloudEvent)
returns (stream io.cloudevents.v1.CloudEvent);
}
```
**startStreaming** — bidirectional streaming RPC for compute member lifecycle. Requires `ROLE_M2M`. First message must be `CalculationMemberJoinEvent`. Server sends processor and criteria requests; client sends responses and keep-alive acknowledgments.
**entityModelManage** — unary RPC for entity model operations. Accepts: `EntityModelImportRequest`, `EntityModelExportRequest`, `EntityModelTransitionRequest`, `EntityModelDeleteRequest`, `EntityModelGetAllRequest`.
**entityManage** — unary RPC for single-entity operations. Accepts: `EntityCreateRequest`, `EntityUpdateRequest`, `EntityDeleteRequest`, `EntityDeleteAllRequest`, `EntityTransitionRequest`.
**entityManageCollection** — server-streaming RPC for batch entity operations. Accepts: `EntityCreateCollectionRequest`, `EntityUpdateCollectionRequest`. Streams one response CloudEvent per entity.
**entitySearch** — unary RPC for entity retrieval. Accepts: `EntityGetRequest`, `EntityGetAllRequest`, `EntitySnapshotSearchRequest`, `EntitySearchRequest`, `SnapshotCancelRequest`, `SnapshotGetRequest`, `SnapshotGetStatusRequest`, `EntityStatsGetRequest`, `EntityStatsByStateGetRequest`, `EntityChangesMetadataGetRequest`.
**entitySearchCollection** — server-streaming RPC for collection retrieval. Streams results.
## MESSAGE TYPES
All CloudEvents are encoded in the Protobuf CloudEvent format. The `type` field selects the operation. The `text_data` field carries the JSON-encoded payload.
**CloudEvent envelope** (`io.cloudevents.v1.CloudEvent`):
```proto
message CloudEvent {
string id = 1; // UUID
string source = 2; // "cyoda"
string spec_version = 3; // "1.0"
string type = 4; // event type constant
map attributes = 5;
oneof data {
bytes binary_data = 6;
string text_data = 7; // JSON payload
google.protobuf.Any proto_data = 8;
}
}
```
**Streaming event types** (compute member protocol):
- `CalculationMemberJoinEvent` — first message from client; registers the member
- `CalculationMemberGreetEvent` — server response to join; includes assigned member ID
- `CalculationMemberKeepAliveEvent` — bidirectional; server sends on interval, client echoes
- `EntityProcessorCalculationRequest` — server → client; processor dispatch request
- `EntityProcessorCalculationResponse` — client → server; processor result
- `EntityCriteriaCalculationRequest` — server → client; criteria dispatch request
- `EntityCriteriaCalculationResponse` — client → server; criteria result
- `EntityFunctionCalculationRequest` — server → client; function dispatch request
- `EntityFunctionCalculationResponse` — client → server; function result
- `EventAckResponse` — client → server; acknowledges any server event
**EventAckResponse `text_data` JSON shape:**
```json
{
"id": "",
"sourceEventId": "",
"success": true,
"warnings": [],
"error": null
}
```
Fields:
- `id` (string, required) — unique identifier for this ack message; any UUID
- `sourceEventId` (string, required) — the `id` field from the server CloudEvent being acknowledged
- `success` (boolean, optional, default `true`) — set to `true` for a normal ack; `false` if the client is reporting a processing error
- `warnings` (string array, optional) — diagnostic messages; may be omitted
- `error` (object, optional) — present only when `success=false`; shape: `{"code":"","message":"","retryable":}`
The full CloudEvent envelope for an ack:
```json
{
"id": "",
"source": "client",
"spec_version": "1.0",
"type": "EventAckResponse",
"text_data": "{\"id\":\"\",\"sourceEventId\":\"\",\"success\":true}"
}
```
`EventAckResponse` updates the member's last-seen timestamp, preventing keep-alive timeout. It is used to acknowledge any server event for which the client has no substantive response (e.g. a keep-alive or a greet event).
**Entity management event types**:
- `EntityCreateRequest` / `EntityTransactionResponse`
- `EntityCreateCollectionRequest` / `EntityTransactionResponse` (streamed)
- `EntityUpdateRequest` / `EntityTransactionResponse`
- `EntityUpdateCollectionRequest` / `EntityTransactionResponse` (streamed)
- `EntityDeleteRequest` / `EntityDeleteResponse`
- `EntityDeleteAllRequest` / `EntityDeleteAllResponse`
- `EntityTransitionRequest` / `EntityTransitionResponse`
- `EntityPatchRequest` / `EntityTransactionResponse` — partial update; `PatchFormat` selects the dialect (`MERGE_PATCH`, RFC 7386 `application/merge-patch+json`, or `JSON_PATCH` `application/json-patch+json`). Requires `ifMatch` (the `transactionId` from the last read, or `"*"` for last-writer-wins); an optional `transition` names the transition to fire.
**Model management event types**:
- `EntityModelImportRequest` / `EntityModelImportResponse`
- `EntityModelExportRequest` / `EntityModelExportResponse`
- `EntityModelTransitionRequest` / `EntityModelTransitionResponse`
- `EntityModelDeleteRequest` / `EntityModelDeleteResponse`
- `EntityModelGetAllRequest` / `EntityModelGetAllResponse`
- `EntityModelSetUniqueKeysRequest` / `EntityModelSetUniqueKeysResponse`
**Search / query event types**:
- `EntityGetRequest` / `EntityResponse`
- `EntityGetAllRequest` / `EntityResponse` (streamed via entitySearchCollection)
- `EntitySnapshotSearchRequest` / `EntitySnapshotSearchResponse`
- `EntitySearchRequest` / `EntityResponse`
- `SnapshotCancelRequest` / `EntitySnapshotSearchResponse`
- `SnapshotGetRequest` / `EntitySnapshotSearchResponse`
- `SnapshotGetStatusRequest` / `EntitySnapshotSearchResponse`
- `EntityStatsGetRequest` / `EntityStatsResponse`
- `EntityStatsByStateGetRequest` / `EntityStatsByStateResponse`
- `EntityChangesMetadataGetRequest` / `EntityChangesMetadataResponse`
## COMPUTE MEMBER PROTOCOL
The compute member protocol allows external processes to serve as workflow processor and criteria nodes.
**Join sequence:**
1. Client opens `startStreaming` with `Authorization: Bearer ` metadata. Token must carry `ROLE_M2M`.
2. Client sends `CalculationMemberJoinEvent` as the first message:
```json
{
"id": "",
"tags": ["approval-service", "notification"],
"joinedLegalEntityId": "acme-corp"
}
```
`joinedLegalEntityId` must match the tenant ID in the bearer token. When present and mismatched, the server returns `codes.PermissionDenied`. When absent, the server uses the token's tenant ID implicitly. Include `joinedLegalEntityId` in all join messages — clients that omit it against a strict server may fail if validation is tightened.
3. Server registers the member and responds with `CalculationMemberGreetEvent`:
```json
{
"id": "",
"memberId": "",
"joinedLegalEntityId": "",
"success": true
}
```
**What a compute member must do:**
- The greet is always the first event on the stream, before any request.
- Read the stream continuously — a member that stops reading is treated as frozen and evicted after `CYODA_KEEPALIVE_TIMEOUT` seconds, and every callout in flight on it fails with `COMPUTE_MEMBER_DISCONNECTED`.
- Write to the stream from one goroutine at a time — the gRPC streaming API forbids concurrent sends on one stream.
- Answer requests, acknowledge events, or echo the server's keep-alive at least once per `CYODA_KEEPALIVE_TIMEOUT` seconds.
**Processor dispatch (server → client):**
Server sends `EntityProcessorCalculationRequest` when a workflow transition invokes an `externalized` processor whose `calculationNodesTags` matches one of the member's declared tags:
```json
{
"id": "",
"requestId": "",
"entityId": "",
"processorId": "notify-approval",
"processorName": "notify-approval",
"workflow": {"id": "prize-lifecycle", "name": "prize-lifecycle"},
"transition": {"id": "APPROVE", "name": "APPROVE"},
"transactionId": "",
"success": true,
"payload": {
"type": "JSON",
"data": {},
"meta": {
"id": "",
"modelKey": {"name": "nobel-prize", "version": 1},
"state": "NEW",
"creationDate": "2025-08-02T13:31:48.141053Z",
"lastUpdateTime": "2025-08-02T13:31:48.141053Z",
"transactionId": ""
}
}
}
```
`payload` is omitted when `attachEntity=false` in the processor config.
Client responds with `EntityProcessorCalculationResponse`:
```json
{
"requestId": "",
"success": true,
"payload": {
"type": "JSON",
"data": {}
},
"warnings": [],
"error": null
}
```
When `success=false`, the workflow engine fails the processor dispatch. When `payload.data` is non-null, the engine replaces the entity's data with the returned value before continuing the workflow.
Returned data is subject to the same checks as an HTTP client write: it must be storable, and it must satisfy the model's schema. A processor may introduce a field the model does not declare only where the model's `changeLevel` would allow a client to — otherwise the transition fails with `WORKFLOW_FAILED` and rolls back. The engine holds no privilege here: whatever it stores, the API must be able to accept back.
**Criteria dispatch (server → client):**
Server sends `EntityCriteriaCalculationRequest` when a workflow transition evaluates a `function`-type criterion:
```json
{
"id": "",
"requestId": "",
"entityId": "",
"criteriaId": "my-criteria-fn",
"criteriaName": "my-criteria-fn",
"target": "TRANSITION",
"workflow": {"id": "prize-lifecycle", "name": "prize-lifecycle"},
"transition": {"id": "APPROVE", "name": "APPROVE"},
"transactionId": "",
"success": true,
"payload": { ...same shape as processor payload... }
}
```
Client responds with `EntityCriteriaCalculationResponse`:
```json
{
"requestId": "",
"success": true,
"matches": true,
"warnings": [],
"error": null
}
```
On `matches: false`, the response may also carry a `reason` string explaining
why the criterion blocked the passage (capped at 2 KiB). It surfaces in two
places: the manual-transition `400 WORKFLOW_FAILED` body
(`detail: transition "" criterion not matched: ` — the
guaranteed, backend-independent delivery for a manual rejection), and the
`TRANSITION_NOT_MATCH_CRITERION` / `WORKFLOW_SKIP` state-machine audit events'
`data.reason` — durable there only for the automated-cascade and
workflow-selection paths, since a manual rejection rolls its transaction back.
An omitted `reason` defaults to `"criterion did not match"` in the audit and
is left out of the 400 detail (bare `criterion not matched`).
**Function callout wire shape:**
`EntityFunctionCalculationRequest`/`EntityFunctionCalculationResponse` are the wire types for the Function callout — a third callout shape alongside processor and criteria that returns a declared typed value instead of a boolean or entity payload (e.g. computing a scheduled state transition's fire time). Request shape mirrors the processor request, naming the callout target `functionId`/`functionName`:
```json
{
"id": "",
"requestId": "",
"entityId": "",
"functionId": "compute-fire-at",
"functionName": "compute-fire-at",
"workflow": {"id": "prize-lifecycle", "name": "prize-lifecycle"},
"transition": {"id": "APPROVE", "name": "APPROVE"},
"transactionId": "",
"success": true
}
```
Response replaces criteria's `matches`/`reason` with `result` (an arbitrary JSON object) plus a `resultKind` discriminator string identifying its shape:
```json
{
"requestId": "",
"success": true,
"result": {"fireAt": 1},
"resultKind": "Schedule",
"warnings": [],
"error": null
}
```
`resultKind: "Schedule"` is the only shape currently defined — it drives a
scheduled transition's `schedule.function` (see `cyoda help workflows`).
`success: false` or an `error` fails the dispatch the same way a processor
or criteria failure does; a `result` that doesn't parse against the
declared `resultKind` is rejected by the caller (a scheduled transition's
`SCHEDULE_FUNCTION_INVALID_RESULT`), not by this wire contract. Full JSON
Schemas for both messages: `docs/cyoda/schema/processing/EntityFunctionCalculationRequest.json`
and `EntityFunctionCalculationResponse.json` (see `cyoda help cloudevents`).
**Auth context on dispatched events:**
The server attaches CloudEvent Auth Context extension attributes to every dispatched request:
- `authtype` — `"user"`, `"service"`, or `"system"`, driven by the originating
principal's explicit kind (not sniffed from roles). **Wire change:** this was
previously `"user"` / `"service_account"` inferred from a `ROLE_M2M` role;
it is now one of exactly these three values, always. Dispatch fails closed
— no callout is sent — if the principal's kind is unset or unrecognized, so
a bogus or absent `authtype` never reaches a compute node.
- `authid` — the user ID of the originating request
- `authclaims` — comma-separated roles of the originating user
## KEEPALIVE
The server sends `CalculationMemberKeepAliveEvent` to each connected member
every `CYODA_KEEPALIVE_INTERVAL` seconds, and evicts a member when either of
two things happens within `CYODA_KEEPALIVE_TIMEOUT` seconds: no inbound
activity has been seen from it, or one outbound write to it has stalled that
long. Processor responses, criteria responses, function responses, and
`EventAckResponse` all count as inbound activity, the same as a keep-alive
echo — any of them resets the eviction clock.
The same two values also drive grpc-go's HTTP/2 transport keepalive: a PING
is sent after `CYODA_KEEPALIVE_INTERVAL` seconds of transport idleness, and
the connection is closed if it goes unacknowledged for
`CYODA_KEEPALIVE_TIMEOUT` seconds — a second, independent layer that catches
a peer whose TCP connection is alive but whose process is gone. The
enforcement policy the server advertises to clients is deliberately
permissive — pings from a client are accepted no more often than every 5
seconds, well below grpc-go's default 5-minute floor, so a compute node
pinging on a normal cadence is never disconnected for it.
- `CYODA_KEEPALIVE_INTERVAL` — seconds between server-sent keep-alive events and the transport keepalive idle time (default: `10`)
- `CYODA_KEEPALIVE_TIMEOUT` — seconds of inactivity (or write stall) before the server evicts the member, and the transport keepalive ack timeout (default: `30`)
Both variables are applied to the gRPC server at construction. A value that
parses to zero or a negative number is a startup error; an unparseable value
falls back to the default.
## TAG ROUTING
A compute member declares its tags in `CalculationMemberJoinEvent.tags` as a string slice. The server routes a processor or criteria request to a member whose tags overlap with `calculationNodesTags` (comma-separated) from the processor or criteria config.
`FindByTags` selects the first matching member for the authenticated tenant by iterating over the internal member map. Tag matching uses intersection: the member must declare at least one tag that appears in the processor's `calculationNodesTags`. Because the internal store is a Go map, iteration order is random (non-deterministic per Go specification). When multiple members share a tag, the selected member is chosen at random on each dispatch. Clients requiring deterministic routing must use distinct tags per member.
When `calculationNodesTags` is empty, any member for the authenticated tenant matches (still chosen at random when multiple exist).
In cluster mode, the `ClusterDispatcher` propagates member tag sets across nodes via gossip so any node can forward dispatches to a node that has a matching member.
## ERRORS
gRPC error codes returned by the service:
- `codes.Unauthenticated` — missing or invalid `authorization` metadata
- `codes.PermissionDenied` — `ROLE_M2M` required for `startStreaming`; tenant mismatch on join
- `codes.InvalidArgument` — first message is not `CalculationMemberJoinEvent`; malformed CloudEvent; invalid join payload
- `codes.DeadlineExceeded` — member timed out (keep-alive timeout exceeded)
- `codes.Internal` — server-side error constructing a response CloudEvent
Within `text_data` payloads, errors are reported as:
```json
{
"success": false,
"error": {
"code": "SERVER_ERROR",
"message": "SERVER_ERROR: internal error [ticket: ]",
"retryable": null
}
}
```
Operational 4xx errors carry the domain code (e.g. `CLIENT_ERROR`) and a human-readable message. Internal errors use `SERVER_ERROR` with a ticket UUID for server-side log correlation.
Processor dispatch errors surfaced to the workflow engine:
- `errors.NO_COMPUTE_MEMBER_FOR_TAG` — no member registered for the requested tags
- `errors.COMPUTE_MEMBER_DISCONNECTED` — member disconnected while a dispatch was in flight (all pending requests receive `"member disconnected"` error)
- `errors.DISPATCH_TIMEOUT` — processor or criteria response not received within `responseTimeoutMs`
- `errors.DISPATCH_FORWARD_FAILED` — cluster forwarder failed to forward dispatch to remote node
## EXAMPLES
**List services (plaintext, no auth):**
```
grpcurl -plaintext localhost:9090 list
```
**List methods on CloudEventsService:**
```
grpcurl -plaintext localhost:9090 list org.cyoda.cloud.api.grpc.CloudEventsService
```
**Describe the CloudEventsService:**
```
grpcurl -plaintext \
-import-path ./proto \
-proto cyoda/cyoda-cloud-api.proto \
localhost:9090 \
describe org.cyoda.cloud.api.grpc.CloudEventsService
```
**Connect as a compute member (mock auth — no token required):**
```
grpcurl -plaintext \
-import-path ./proto \
-proto cyoda/cyoda-cloud-api.proto \
-d '{"id":"join-1","source":"client","spec_version":"1.0","type":"CalculationMemberJoinEvent","text_data":"{\"id\":\"join-1\",\"tags\":[\"my-service\"],\"joinedLegalEntityId\":\"mock-tenant\"}"}' \
localhost:9090 \
org.cyoda.cloud.api.grpc.CloudEventsService/StartStreaming
```
**Connect as a compute member (JWT auth):**
```
grpcurl -plaintext \
-H "authorization: Bearer $TOKEN" \
-import-path ./proto \
-proto cyoda/cyoda-cloud-api.proto \
-d '{"id":"join-1","source":"client","spec_version":"1.0","type":"CalculationMemberJoinEvent","text_data":"{\"id\":\"join-1\",\"tags\":[\"my-service\"],\"joinedLegalEntityId\":\"acme-corp\"}"}' \
localhost:9090 \
org.cyoda.cloud.api.grpc.CloudEventsService/StartStreaming
```
## ACTION DETAILS
- `cyoda help grpc proto` — emit raw `.proto` source for `cyoda-cloud-api.proto` and `cloudevents.proto` (concatenated with separator comments)
- `cyoda help grpc json` — emit the gRPC service `FileDescriptorSet` as JSON (standard protobuf descriptor form)
## SEE ALSO
- config.grpc
- workflows
- errors.COMPUTE_MEMBER_DISCONNECTED
- errors.NO_COMPUTE_MEMBER_FOR_TAG
- errors.DISPATCH_TIMEOUT
- errors.DISPATCH_FORWARD_FAILED
## See also
- [`cyoda help config grpc`](/help/config/grpc/) — config.grpc — gRPC listener settings and compute-node credentials.
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help cloudevents`](/help/cloudevents/) — cyoda-go uses [CloudEvents v1.0](https://cloudevents.io) as the transport envelope for event-driven processing. Every payload carried inside a CloudEvent — workflow calculation requests, calculation responses, entity transaction events, snapshot state, model descriptors — is validated against a JSON Schema (Draft 2020-12).
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
- [`cyoda help errors DISPATCH_TIMEOUT`](/help/errors/dispatch_timeout/) — A workflow processor, criteria evaluation, or function callout was dispatched to a compute member but the response did not arrive within the callout's own `responseTimeoutMs` (a field on the processor, criteria, or function config; default `30000` ms) — not any cluster forwarding timeout.
- [`cyoda help errors SCHEDULE_FUNCTION_INVALID_RESULT`](/help/errors/schedule_function_invalid_result/) — A `TransitionSchedule.function` callout must return `resultKind: "Schedule"` with a value shaped `{fireAt|fireAfterMs, expireAt?|expireAfterMs?}` — exactly one of `fireAt`/`fireAfterMs`, and at most one of `expireAt`/`expireAfterMs`. This error is raised when the compute node returns a different `resultKind`, or a `Schedule` value that is malformed: missing or duplicate fire/expiry fields, an unknown field, or a non-numeric value.
- [`cyoda help errors DISPATCH_FORWARD_FAILED`](/help/errors/dispatch_forward_failed/) — The cluster dispatcher attempted to forward a processor invocation or criteria evaluation to a peer node but the HTTP call to that peer failed (network error, peer crash, or connection refused). The operation has not been executed on the target node.
## Raw formats
- [`/help/grpc.json`](/help/grpc.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/grpc.md`](/help/grpc.md) — body only
---
## help/helm.md
# helm — Helm chart for Kubernetes deployment
The chart at `deploy/helm/cyoda` deploys cyoda-go on Kubernetes as a StatefulSet backed by an external PostgreSQL database. The chart requires Kubernetes …
cyoda-go version 0.8.4
# helm
## NAME
helm — the `deploy/helm/cyoda` Helm chart: values, Kubernetes objects, secrets provisioning, and install/upgrade commands.
## SYNOPSIS
```
helm install cyoda ./deploy/helm/cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt
```
## DESCRIPTION
The chart at `deploy/helm/cyoda` deploys cyoda-go on Kubernetes as a StatefulSet backed by an external PostgreSQL database. The chart requires Kubernetes `>=1.31.0`. Chart version: `0.1.0`. App version: `0.1.0` (synchronized to the binary by the `bump-chart-appversion.yml` CI workflow).
The chart is not published to a Helm repository. Install directly from a local checkout or from the GitHub repository source tree. The canonical install form is `helm install cyoda ./deploy/helm/cyoda`.
Cyoda-go pods are stateless: all persistent state is in PostgreSQL. The chart renders a StatefulSet (not a Deployment) to give each pod a stable DNS identity for gossip peer discovery. Pod management policy is `Parallel` — pods start simultaneously rather than sequentially. Cluster mode is always enabled at the chart level; at `replicas=1` the binary runs as a cluster of one.
Credentials (Postgres DSN, JWT signing key, HMAC secret, metrics bearer token, optional bootstrap client secret) are never stored in the ConfigMap. They are mounted via projected Secret volumes and read by the binary through `CYODA_*_FILE` env vars.
## CHART REPOSITORY
The chart is not yet published to an OCI registry or a tgz repository. Install from a local path:
```
helm install cyoda ./deploy/helm/cyoda [--set ...]
```
For a GitOps workflow, package the chart manually:
```
helm package ./deploy/helm/cyoda
helm install cyoda cyoda-0.1.0.tgz [--set ...]
```
## VALUES
All top-level keys in `deploy/helm/cyoda/values.yaml`, with type, default, and purpose.
**`replicas`** — integer — default `1`
Number of cyoda pods. Scale up for multi-node cluster. At `replicas=1` the binary runs as a "cluster of one". When `autoscaling.enabled=true`, the HPA owns the replica count and the `replicas` value becomes the initial scale only.
**`logLevel`** — string — default `info`
Log level. Accepted values: `debug`, `info`, `warn`, `error`. Written to the ConfigMap as `CYODA_LOG_LEVEL`.
**`image.repository`** — string — default `ghcr.io/cyoda/cyoda`
Container image repository.
**`image.tag`** — string — default `""` (resolved to `.Chart.AppVersion`)
Image tag. When empty, the chart uses `.Chart.AppVersion`.
**`image.pullPolicy`** — string — default `IfNotPresent`
Image pull policy. Accepted values: `Always`, `IfNotPresent`, `Never`.
**`imagePullSecrets`** — list — default `[]`
List of `{name: }` entries for private registries. Example: `[{name: ghcr-pull-secret}]`.
**`resources.requests.cpu`** — string — default `100m`
CPU request for cyoda containers.
**`resources.requests.memory`** — string — default `256Mi`
Memory request for cyoda containers.
**`resources.limits.cpu`** — string — default `1000m`
CPU limit for cyoda containers.
**`resources.limits.memory`** — string — default `512Mi`
Memory limit for cyoda containers.
**`postgres.existingSecret`** — string — default `""` — **REQUIRED**
Name of the Kubernetes Secret containing the Postgres DSN. The Secret must exist before install. The DSN value must be a full connection string: `postgres://user:pass@host:5432/db?sslmode=require`.
**`postgres.existingSecretKey`** — string — default `dsn`
Key within `postgres.existingSecret` whose value is the Postgres DSN.
**`jwt.existingSecret`** — string — default `""` — **REQUIRED**
Name of the Kubernetes Secret containing the PEM-encoded RSA private key for JWT signing.
**`jwt.existingSecretKey`** — string — default `signing-key.pem`
Key within `jwt.existingSecret` whose value is the PEM-encoded RSA private key.
**`jwt.issuer`** — string — default `cyoda`
JWT issuer claim. Written to ConfigMap as `CYODA_JWT_ISSUER`.
**`jwt.expirySeconds`** — integer — default `3600`
JWT token expiry in seconds. Written to ConfigMap as `CYODA_JWT_EXPIRY_SECONDS`.
**`cluster.hmacSecret.existingSecret`** — string — default `""`
Name of an operator-managed Secret containing the HMAC secret. When empty, the chart auto-generates the Secret on first install using `lookup` to detect existing state. GitOps controllers (Argo CD) must set this to a pre-created Secret; the chart fails with an error if rendered without live cluster access (e.g. `helm template`, `--dry-run`) and no `existingSecret` is provided.
**`cluster.hmacSecret.existingSecretKey`** — string — default `secret`
Key within the HMAC Secret whose value is the hex-encoded HMAC secret. The binary reads it via `CYODA_HMAC_SECRET_FILE` and decodes hex to raw bytes.
**`bootstrap.clientId`** — string — default `""`
Bootstrap M2M client ID. Bootstrap provisioning is opt-in. When empty, no bootstrap Secret is rendered and no bootstrap credential is set. When non-empty, the chart provisions the bootstrap M2M client. The binary's coupled predicate (both ID and Secret set, or both empty) applies.
**`bootstrap.clientSecret.existingSecret`** — string — default `""`
Name of an operator-managed Secret containing the bootstrap client secret. When `bootstrap.clientId` is non-empty and this is empty, the chart auto-generates the Secret. GitOps safety guard applies (same pattern as HMAC).
**`bootstrap.clientSecret.existingSecretKey`** — string — default `secret`
Key within the bootstrap client Secret.
**`bootstrap.tenantId`** — string — default `default-tenant`
Bootstrap tenant ID. Written to ConfigMap as `CYODA_BOOTSTRAP_TENANT_ID`.
**`bootstrap.userId`** — string — default `admin`
Bootstrap user ID. Written to ConfigMap as `CYODA_BOOTSTRAP_USER_ID`.
**`bootstrap.roles`** — string — default `ROLE_ADMIN,ROLE_M2M`
Comma-separated roles for the bootstrap client. Written to ConfigMap as `CYODA_BOOTSTRAP_ROLES`.
**`extraEnv`** — list — default `[]`
Arbitrary additional env vars injected into the StatefulSet container. Each entry is `{name, value}` or `{name, valueFrom}`. Use for OTel configuration (`CYODA_OTEL_ENABLED`, `OTEL_EXPORTER_OTLP_ENDPOINT`, etc.), feature flags, and tuning knobs. Do not set `CYODA_*_FILE` credential vars or the four chart-managed credential env vars here — the chart sets those and Kubernetes rejects duplicates.
**`service.type`** — string — default `ClusterIP`
Kubernetes Service type for the main Service (ports 8080, 9090, 9091). Accepted values: `ClusterIP`, `NodePort`, `LoadBalancer`.
**`gateway.enabled`** — boolean — default `true`
Enable Gateway API routing. Renders `HTTPRoute` (port 8080) and `GRPCRoute` (port 9090). Mutually exclusive with `ingress.enabled`; both enabled triggers a `fail`. When `true`, `gateway.parentRefs` MUST be set to a non-empty list of operator-provided Gateway references; an empty list causes install to fail.
**`gateway.parentRefs`** — list — default `[]` — **REQUIRED when `gateway.enabled=true`**
List of Gateway API parent references (operator-provided Gateway). The chart does not render the Gateway itself.
**`gateway.http.hostnames`** — list — default `[]`
HTTP hostnames for the `HTTPRoute`. When empty, the route matches all hostnames.
**`gateway.grpc.hostnames`** — list — default `[]`
gRPC hostnames for the `GRPCRoute`. When empty, the route matches all hostnames.
**`ingress.enabled`** — boolean — default `false`
Enable Ingress routing (transitional; `gateway.enabled=true` is preferred). Mutually exclusive with `gateway.enabled`.
**`ingress.className`** — string — default `""`
`ingressClassName` for the Ingress objects.
**`ingress.http.host`** — string — default `""`
Hostname for the HTTP Ingress rule.
**`ingress.http.paths`** — list — default `[{path: /, pathType: Prefix}]`
Path rules for the HTTP Ingress.
**`ingress.http.annotations`** — map — default `{}`
Annotations on the HTTP Ingress object.
**`ingress.http.tls`** — list — default `[]`
TLS configuration for the HTTP Ingress.
**`ingress.grpc.host`** — string — default `""`
Hostname for the gRPC Ingress rule.
**`ingress.grpc.paths`** — list — default `[{path: /, pathType: Prefix}]`
Path rules for the gRPC Ingress.
**`ingress.grpc.annotations`** — map — default `{nginx.ingress.kubernetes.io/backend-protocol: GRPC}`
Annotations on the gRPC Ingress object.
**`ingress.grpc.tls`** — list — default `[]`
TLS configuration for the gRPC Ingress.
**`monitoring.metricsBearer.existingSecret`** — string — default `""`
Name of an operator-managed Secret containing the static bearer token for `GET /metrics` authentication. When empty, the chart auto-generates the Secret. GitOps safety guard applies.
**`monitoring.metricsBearer.existingSecretKey`** — string — default `bearer`
Key within the metrics bearer Secret.
**`monitoring.serviceMonitor.enabled`** — boolean — default `false`
Render a `ServiceMonitor` (Prometheus Operator CRD). When enabled, Prometheus Operator scrapes `GET :9091/metrics` using the bearer token from `monitoring.metricsBearer` Secret.
**`monitoring.serviceMonitor.interval`** — string — default `30s`
Prometheus scrape interval.
**`monitoring.serviceMonitor.labels`** — map — default `{}`
Additional labels on the `ServiceMonitor` (used by Prometheus Operator's `serviceMonitorSelector`).
**`networkPolicy.enabled`** — boolean — default `true`
Render a `NetworkPolicy`. Restricts port 9091 (admin/metrics) ingress to namespaces declared in `metricsFromNamespaces`. Restricts port 7946 (gossip) ingress to chart-managed pods. Ports 8080 and 9090 are unrestricted at the NetworkPolicy layer (boundary is the Gateway/Ingress). Requires a CNI that enforces NetworkPolicy (Calico, Cilium, Weave). kindnet and some managed CNIs do not enforce NetworkPolicy — set `enabled=false` on those clusters.
**`networkPolicy.metricsFromNamespaces`** — list — default `[{matchLabels: {kubernetes.io/metadata.name: monitoring}}]`
Namespace selectors permitted to reach port 9091. Must be non-empty when `networkPolicy.enabled=true`.
**`autoscaling.enabled`** — boolean — default `false`
Render a `HorizontalPodAutoscaler` targeting the StatefulSet. When enabled, the HPA owns the replica count; the static `replicas` value becomes the initial count only.
**`autoscaling.minReplicas`** — integer — default `1`
HPA minimum replica count.
**`autoscaling.maxReplicas`** — integer — default `3`
HPA maximum replica count.
**`autoscaling.targetCPUUtilizationPercentage`** — integer — default `80`
HPA CPU utilization target. Omit or set to `0` to disable CPU-based scaling.
**`autoscaling.targetMemoryUtilizationPercentage`** — integer — not set by default
HPA memory utilization target. Uncomment in `values.yaml` to enable memory-based scaling.
**`autoscaling.behavior`** — map — default `{}`
HPA `behavior` block for stabilization windows and scale-up/scale-down policies (`autoscaling/v2` schema).
**`migrate.activeDeadlineSeconds`** — integer — default `600`
`activeDeadlineSeconds` for the pre-upgrade migration Job.
**`migrate.backoffLimit`** — integer — default `2`
`backoffLimit` for the migration Job.
**`migrate.resources.requests.cpu`** — string — default `100m`
CPU request for the migration Job container.
**`migrate.resources.requests.memory`** — string — default `128Mi`
Memory request for the migration Job container.
**`migrate.resources.limits.cpu`** — string — default `500m`
CPU limit for the migration Job container.
**`migrate.resources.limits.memory`** — string — default `256Mi`
Memory limit for the migration Job container.
**`podDisruptionBudget.enabled`** — boolean — default `true`
Render a `PodDisruptionBudget`. Rendered only when `replicas > 1` or `autoscaling.enabled=true` with `maxReplicas > 1`.
**`podDisruptionBudget.minAvailable`** — integer — default `1`
Minimum available pods during voluntary disruptions.
**`serviceAccount.create`** — boolean — default `true`
Create a dedicated `ServiceAccount`. The ServiceAccount is a Helm pre-install/pre-upgrade hook with weight `-10` so it exists before the migration Job (weight `0`).
**`serviceAccount.name`** — string — default `""` (resolved to the chart fullname)
Name of the ServiceAccount. When empty, the chart fullname is used.
**`serviceAccount.annotations`** — map — default `{}`
Annotations on the ServiceAccount (e.g. for IRSA/Workload Identity).
**`podAnnotations`** — map — default `{}`
Annotations added to all pods in the StatefulSet.
**`podLabels`** — map — default `{}`
Labels added to all pods in the StatefulSet.
**`nodeSelector`** — map — default `{}`
Node selector for the StatefulSet pod spec.
**`tolerations`** — list — default `[]`
Tolerations for the StatefulSet pod spec.
**`affinity`** — map — default `{}`
Affinity rules for the StatefulSet pod spec.
**`nameOverride`** — string — default `""`
Override the chart name component of generated resource names.
**`fullnameOverride`** — string — default `""`
Override the full generated resource name prefix.
## CRDS / OBJECTS
The chart renders the following Kubernetes objects. Conditional objects note their enabling value.
**Always rendered:**
- `StatefulSet` (`apps/v1`) — the cyoda workload. `podManagementPolicy: Parallel`. `updateStrategy: RollingUpdate`. No `volumeClaimTemplates` (cyoda is stateless vs. PostgreSQL). Mounts a projected Secret volume at `/etc/cyoda/secrets` (mode `0400`) and an `emptyDir` at `/tmp`. Runs as UID/GID 65532, non-root, `readOnlyRootFilesystem: true`, `allowPrivilegeEscalation: false`, all capabilities dropped, `seccompProfile: RuntimeDefault`.
- `Service` (`v1`) — ClusterIP Service exposing ports `8080` (http), `9090` (grpc), `9091` (metrics).
- `Service` (headless, `v1`) — `clusterIP: None`, `publishNotReadyAddresses: true`. Exposes port `7946` TCP and UDP for gossip (memberlist). Used as the `serviceName` for the StatefulSet.
- `ConfigMap` (`v1`) — non-sensitive env vars loaded via `envFrom`. Contains: `CYODA_HTTP_PORT`, `CYODA_GRPC_PORT`, `CYODA_ADMIN_PORT`, `CYODA_ADMIN_BIND_ADDRESS`, `CYODA_METRICS_REQUIRE_AUTH`, `CYODA_IAM_MODE`, `CYODA_REQUIRE_JWT`, `CYODA_STORAGE_BACKEND`, `CYODA_POSTGRES_AUTO_MIGRATE`, `CYODA_CLUSTER_ENABLED`, `CYODA_SEED_NODES`, `CYODA_LOG_LEVEL`, `CYODA_JWT_ISSUER`, `CYODA_JWT_EXPIRY_SECONDS`, `CYODA_BOOTSTRAP_TENANT_ID`, `CYODA_BOOTSTRAP_USER_ID`, `CYODA_BOOTSTRAP_ROLES`, and `CYODA_BOOTSTRAP_CLIENT_ID` (when `bootstrap.clientId` is set). Is a Helm pre-install/pre-upgrade hook with weight `-10`.
- `Job` (`batch/v1`) — migration Job running `cyoda migrate`. Helm pre-install/pre-upgrade hook (weight `0`, delete policy `before-hook-creation,hook-succeeded`). Mounts only the Postgres DSN Secret (principle of least privilege). Uses `restartPolicy: Never`.
- `NetworkPolicy` (`networking.k8s.io/v1`) — rendered when `networkPolicy.enabled=true`. (Conditional.)
- `Secret` (HMAC) — rendered when `cluster.hmacSecret.existingSecret=""`. Manages the hex-encoded HMAC secret. Auto-generates on first install; reuses on re-render via `lookup`. GitOps safety guard: fails if rendered without live cluster access. (Conditional.)
- `Secret` (metrics bearer) — rendered when `monitoring.metricsBearer.existingSecret=""`. Manages the static bearer token for `/metrics`. Auto-generates (48-char alphanumeric). GitOps safety guard applies. (Conditional.)
**Conditional:**
- `ServiceAccount` (`v1`) — rendered when `serviceAccount.create=true`. Helm hook weight `-10`.
- `Secret` (bootstrap) — rendered when `bootstrap.clientId != ""` and `bootstrap.clientSecret.existingSecret=""`. Auto-generates (48-char alphanumeric). GitOps safety guard applies.
- `HorizontalPodAutoscaler` (`autoscaling/v2`) — rendered when `autoscaling.enabled=true`.
- `PodDisruptionBudget` (`policy/v1`) — rendered when `podDisruptionBudget.enabled=true` and `replicas > 1` or `autoscaling.maxReplicas > 1`.
- `HTTPRoute` (`gateway.networking.k8s.io/v1`) — rendered when `gateway.enabled=true`. Routes port 8080.
- `GRPCRoute` (`gateway.networking.k8s.io/v1`) — rendered when `gateway.enabled=true`. Routes port 9090.
- `Ingress` (HTTP, `networking.k8s.io/v1`) — rendered when `ingress.enabled=true`. Mutually exclusive with `gateway.enabled`.
- `Ingress` (gRPC, `networking.k8s.io/v1`) — rendered when `ingress.enabled=true`.
- `ServiceMonitor` (`monitoring.coreos.com/v1`) — rendered when `monitoring.serviceMonitor.enabled=true`. References the metrics bearer Secret for scrape authentication.
## GENERATING SECRETS
**JWT signing key** — generate an RSA-2048 private key and load it into a Kubernetes Secret:
```
openssl genpkey -algorithm RSA -pkeyopt rsa_keygen_bits:2048 -out signing.pem
kubectl create secret generic cyoda-jwt -n cyoda \
--from-file=signing-key.pem=signing.pem
```
**HMAC secret** — generate 32 bytes of entropy (64 hex chars) and load into a Kubernetes Secret:
```
kubectl create secret generic cyoda-hmac -n cyoda \
--from-literal=secret="$(openssl rand -hex 32)"
```
See `quickstart` for accepted key formats and format-specific `openssl` commands.
## SECRETS PROVISIONING
The chart never stores credentials in the ConfigMap. All credentials are mounted via a projected Secret volume at `/etc/cyoda/secrets` and read by the binary through `CYODA_*_FILE` env vars. The file paths and corresponding env vars are set in the StatefulSet env block:
- `CYODA_POSTGRES_URL_FILE=/etc/cyoda/secrets/postgres-dsn` — sourced from `postgres.existingSecret` key `postgres.existingSecretKey`.
- `CYODA_JWT_SIGNING_KEY_FILE=/etc/cyoda/secrets/jwt-signing-key.pem` — sourced from `jwt.existingSecret` key `jwt.existingSecretKey`.
- `CYODA_HMAC_SECRET_FILE=/etc/cyoda/secrets/hmac-secret` — sourced from the chart-managed or operator-provided HMAC Secret.
- `CYODA_METRICS_BEARER_FILE=/etc/cyoda/secrets/metrics-bearer` — sourced from the chart-managed or operator-provided metrics bearer Secret.
- `CYODA_BOOTSTRAP_CLIENT_SECRET_FILE=/etc/cyoda/secrets/bootstrap-client-secret` — sourced from the chart-managed or operator-provided bootstrap Secret. Mounted only when `bootstrap.clientId` is non-empty.
The projected volume `defaultMode` is `0400` (owner read-only). The pod `securityContext.fsGroup=65532` ensures mounted Secret files are readable by the non-root container user.
The migration Job mounts only the Postgres DSN Secret (principle of least privilege). It does not receive JWT, HMAC, metrics bearer, or bootstrap credentials.
**GitOps safety guard (HMAC, metrics bearer, bootstrap secrets):** When `existingSecret` is empty, the chart uses `lookup` to detect whether the Secret already exists. On first install with live cluster access, it generates a random value. On subsequent renders, it reuses the existing value. When `lookup` returns no result (because Helm is run without live cluster access — `helm template`, `--dry-run`, Argo CD, first-time `--create-namespace`), the chart fails with an explicit error message. To avoid this: either pre-create the Secret and set `existingSecret`, use `external-secrets-operator`, or create the namespace first with `kubectl create namespace`.
**CYODA_METRICS_REQUIRE_AUTH:** The ConfigMap always sets `CYODA_METRICS_REQUIRE_AUTH=true` on Helm deployments. This forces the binary's coupled-predicate validator to refuse startup if the metrics bearer Secret is absent or empty, providing a belt-and-braces guard against chart misconfiguration.
## INSTALL / UPGRADE / UNINSTALL
**Install (pre-create secrets, then install):**
```
kubectl create secret generic cyoda-pg \
--from-literal=dsn="postgres://cyoda:secret@pg-host:5432/cyoda?sslmode=require"
kubectl create secret generic cyoda-jwt \
--from-literal=signing-key.pem="$(cat signing.pem)"
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--create-namespace \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set cluster.hmacSecret.existingSecret=cyoda-hmac
```
Note: `--create-namespace` triggers the GitOps safety guard (namespace does not yet exist when Helm renders). Pre-create the namespace first:
```
kubectl create namespace cyoda
kubectl create secret generic cyoda-pg -n cyoda \
--from-literal=dsn="postgres://cyoda:secret@pg-host:5432/cyoda?sslmode=require"
kubectl create secret generic cyoda-jwt -n cyoda \
--from-literal=signing-key.pem="$(cat signing.pem)"
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt
```
**Upgrade:**
```
helm upgrade --install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--reuse-values
```
**Uninstall:**
```
helm uninstall cyoda --namespace cyoda
```
Uninstall does not delete PersistentVolumeClaims, Secrets not managed by the chart, or the namespace. Delete chart-managed Secrets manually if desired:
```
kubectl delete secret cyoda-hmac cyoda-metrics-bearer -n cyoda
```
**Dry-run (template rendering without cluster access — HMAC/metrics secret must be pre-created):**
```
kubectl create secret generic cyoda-hmac -n cyoda --from-literal=secret=placeholder
kubectl create secret generic cyoda-metrics-bearer -n cyoda --from-literal=bearer=placeholder
helm template cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set cluster.hmacSecret.existingSecret=cyoda-hmac \
--set monitoring.metricsBearer.existingSecret=cyoda-metrics-bearer
```
## EXAMPLES
**Minimal install (pre-created postgres + jwt secrets):**
**Bare-cluster install** — `gateway.enabled=false` disables the Gateway API route objects. Use this form on clusters without Gateway API CRDs (kind, minikube, most vanilla clusters). The chart falls back to the built-in `Service` for traffic ingress.
```
kubectl create namespace cyoda
kubectl create secret generic cyoda-pg -n cyoda \
--from-literal=dsn="postgres://cyoda:pass@db.example.com:5432/cyoda?sslmode=require"
kubectl create secret generic cyoda-jwt -n cyoda \
--from-literal=signing-key.pem="$(cat signing.pem)"
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set gateway.enabled=false
```
**Multi-replica cluster with HPA:**
```
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set replicas=3 \
--set autoscaling.enabled=true \
--set autoscaling.minReplicas=3 \
--set autoscaling.maxReplicas=10
```
**With OTel tracing (via extraEnv):**
```
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set extraEnv[0].name=CYODA_OTEL_ENABLED \
--set extraEnv[0].value=true \
--set extraEnv[1].name=OTEL_EXPORTER_OTLP_ENDPOINT \
--set extraEnv[1].value=http://otel-collector.monitoring.svc.cluster.local:4318 \
--set extraEnv[2].name=OTEL_SERVICE_NAME \
--set extraEnv[2].value=cyoda
```
**With ServiceMonitor for Prometheus Operator:**
```
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set monitoring.serviceMonitor.enabled=true \
--set monitoring.serviceMonitor.labels.release=prometheus
```
**With bootstrap M2M client:**
```
kubectl create secret generic cyoda-bootstrap -n cyoda \
--from-literal=secret="$(openssl rand -base64 36)"
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set bootstrap.clientId=m2m-api-client \
--set bootstrap.clientSecret.existingSecret=cyoda-bootstrap \
--set bootstrap.tenantId=acme \
--set-string 'bootstrap.roles=ROLE_ADMIN\,ROLE_M2M'
```
Helm treats commas in `--set` as array separators. Use `--set-string` with an escaped comma (`\,`) or provide the value via a `values.yaml` file to preserve the single string.
**With Gateway API (requires operator-provided Gateway):**
```
helm install cyoda ./deploy/helm/cyoda \
--namespace cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt \
--set "gateway.parentRefs[0].name=prod-gateway" \
--set "gateway.parentRefs[0].namespace=gateway-system" \
--set "gateway.http.hostnames[0]=api.example.com" \
--set "gateway.grpc.hostnames[0]=grpc.example.com"
```
## SEE ALSO
- run
- config
- config.database
- config.auth
- quickstart
## See also
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help quickstart`](/help/quickstart/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memory`, `sqlite`, and `postgres`; authentication modes are `mock` and `jwt`. All configuration is via environment variables with a `CYODA_` prefix.
## Raw formats
- [`/help/helm.json`](/help/helm.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/helm.md`](/help/helm.md) — body only
---
## help/messages.md
# messages — edge message store API
An edge message is an arbitrary JSON payload stored under a server-generated time-UUID together with a fixed set of AMQP-aligned headers and an optional f…
cyoda-go version 0.8.4
# messages
## NAME
messages — edge message create, read, and delete REST API.
## SYNOPSIS
```
POST /api/message/new/{subject}
GET /api/message/{messageId}
DELETE /api/message/{messageId}
DELETE /api/message
```
Context path prefix is `CYODA_CONTEXT_PATH` (default `/api`). All endpoints require `Authorization: Bearer ` except when `CYODA_IAM_MODE=mock`. No role is required beyond a valid token.
## DESCRIPTION
An edge message is an arbitrary JSON payload stored under a server-generated time-UUID together with a fixed set of AMQP-aligned headers and an optional flat metadata map. The store is standalone: a message is not an entity, and creating one does not touch the workflow engine — no transition fires, no processor or criterion runs. Edge messaging is a durable, tenant-scoped staging buffer at the platform edge, a peer of the entity store rather than part of it.
The surface is HTTP-only; there is no gRPC message service.
Messages are keyed by `(tenant, messageId)`. The tenant is derived from the authenticated caller, never from a request parameter, so a message ID only resolves within the tenant that created it (see TENANT ISOLATION).
Body size limit on all write endpoints: 10 MiB.
## MESSAGE SHAPE
The create request and the read response are different shapes: you POST a payload plus metadata, and you GET back the same payload and metadata wrapped alongside the stored header. The metadata values round-trip unchanged — a flat map in, the same flat map out.
**Create request** — a single JSON object:
- `payload` (required): any valid JSON value — object, array, string, number, boolean, or `null`. It is stored verbatim (whitespace is compacted). `Content-Type` is informational only; the store does not parse the payload against it. Non-JSON content must be stringified by the client (for example base64) and sent as a JSON string.
- `metaData` (optional): a flat map of string keys to JSON values, stored alongside the message and returned verbatim on read. There is no message-query endpoint — messages are retrieved by ID, not searched by metadata.
**Read response** (`EdgeMessageDto`) — three top-level fields:
- `header`: the stored `EdgeMessageHeader` (below); empty optional fields are omitted.
- `metaData`: the metadata map, returned flat and unchanged — the same `metaData` supplied at creation.
- `content`: the payload, echoed back verbatim as it was stored.
**Header** (`EdgeMessageHeader`) — AMQP-aligned:
- `subject` (string): taken from the `{subject}` path segment on create.
- `contentType` (string): from the `Content-Type` request header; informational.
- `contentLength` (int64): from the `Content-Length` request header.
- `contentEncoding` (string): from the `Content-Encoding` request header (default `UTF-8`).
- `messageId`, `userId`, `recipient`, `replyTo`, `correlationId` (all optional strings): from the `X-Message-ID`, `X-User-ID`, `X-Recipient`, `X-Reply-To`, `X-Correlation-ID` request headers respectively. These are caller-supplied envelope fields and are distinct from the server-generated store ID in the URL.
## ENDPOINTS
**POST /api/message/new/{subject}** — Create and store a message
- `subject` (path): string matching `^[a-zA-Z0-9._-]{1,256}$`
- `Content-Type` (header, required): MIME type of the payload (informational)
- `Content-Length` (header, required): payload size in bytes
- `Content-Encoding` (header, optional): default `UTF-8`
- `X-Message-ID`, `X-User-ID`, `X-Recipient`, `X-Reply-To`, `X-Correlation-ID` (headers, optional): AMQP envelope fields, each 1..1024 chars
- `transactionTimeoutMillis` (query, optional): int64 — maximum time the server may spend before the message save begins. Exceeding it fails with `408 errors.TRANSACTION_TIMEOUT` before anything is stored; the save itself, once started, is shielded and always completes. Rejected with `400` on a request that joins an open transaction. Absent means no server-side timeout.
Request body: a `NewMessageRequest` object `{ payload, metaData }` as described in MESSAGE SHAPE. Missing `payload` returns `400 BAD_REQUEST`.
The server generates a time-UUID for the message and a separate time-UUID for the transaction. Response: `200 OK`, `application/json`, an `EntityTransactionResponse` array with a single element:
```json
[{
"entityIds": ["8824c480-c166-11ee-bf9f-ae468cd3ed16"],
"transactionId": "9f3a0000-c166-11ee-bf9f-ae468cd3ed16"
}]
```
**GET /api/message/{messageId}** — Retrieve a message by ID
- `messageId` (path): UUID
Response: `200 OK`, `application/json`, an `EdgeMessageDto`:
```json
{
"header": {
"subject": "nobel.prize.events",
"contentType": "application/json",
"contentLength": 1024,
"contentEncoding": "UTF-8",
"messageId": "msg-nobel-2024-physics",
"userId": "nobel-committee",
"recipient": "scientific-community",
"replyTo": "announcements@nobelprize.org",
"correlationId": "nobel-2024-physics-announcement"
},
"metaData": {
"eventType": "nobel.prize.announced",
"timestamp": "2024-10-09T12:00:00Z"
},
"content": { "category": "physics", "year": "2024" }
}
```
A malformed `messageId` returns `400 BAD_REQUEST`; a well-formed UUID that does not exist for the calling tenant returns `404 ENTITY_NOT_FOUND`.
**DELETE /api/message/{messageId}** — Delete a single message
- `messageId` (path): UUID
Deletes the message and its payload blob. Returns `404 ENTITY_NOT_FOUND` if the ID does not exist for the tenant. Response: `200 OK`, `application/json`, a `MessageDeleteResponse`:
```json
{ "entityIds": ["8824c480-c166-11ee-bf9f-ae468cd3ed16"] }
```
Message delete is not transactional in the same sense as entity create/update.
**DELETE /api/message** — Delete multiple messages by ID
- `transactionSize` (query, optional): int32 — number of message IDs deleted per batch. Without it, all IDs are deleted in one call and the response is a single element covering the whole set. With it, IDs are deleted in batches of this size, one response element per batch; a batch failure does not stop later batches from running. Rejected with `400` on a request that joins an open transaction. Absent means a single call.
Request body: a JSON array of UUID strings. Every element must parse as a UUID; otherwise `400 BAD_REQUEST`. Response: `200 OK`, `application/json`, a `MessageDeleteBatchResponse` array, one element per batch (or one element for the whole set when `transactionSize` is absent):
```json
[{
"entityIds": [
"8824c480-c166-11ee-9cc7-ae468cd3ed16",
"31134900-d9cb-11ee-9cc7-ae468cd3ed16"
],
"success": true
}]
```
Message delete is not part of an entity transaction and does not roll back as a unit — a batch's `success` reflects only whether its own `DeleteBatch` call returned an error, and a `false` does not guarantee none of the batch's IDs were removed. On postgres, a batch is one `DELETE ... WHERE message_id = ANY(...)` statement, so it fully applies or fully fails. On memory, a batch is deleted ID-by-ID and stops at the first error, so a mid-batch failure can leave earlier IDs already removed while `success: false` is reported for the whole batch. On sqlite, a batch over 500 IDs is split into internal 500-ID `DELETE ... IN (...)` statements; a failure in a later internal chunk leaves earlier chunks' IDs already removed under the same `success: false`.
## TENANT ISOLATION
Every operation is scoped to the authenticated caller's tenant. The tenant is resolved from the user context, and each backend keys and filters messages by `(tenant, messageId)`:
- postgres / sqlite — the primary key is `(tenant_id, message_id)` and every query filters on `tenant_id`.
- memory — metadata is held per tenant and each payload blob lives under a per-tenant directory.
A message ID is an unguessable time-UUID and is only ever retrievable or deletable by the tenant that created it. A cross-tenant read or delete resolves to `404 ENTITY_NOT_FOUND`, not a leak.
## ERRORS
Errors are RFC 9457 `application/problem+json` with `properties.errorCode` set to the machine-readable code:
- `errors.BAD_REQUEST` — `400` — invalid JSON, missing `payload`, malformed `messageId`, a delete body that is not a JSON array of UUID strings, an invalid `transactionSize`/`transactionTimeoutMillis`, or either param sent on a request that joins an open transaction
- `errors.ENTITY_NOT_FOUND` — `404` — no message with this ID exists for the calling tenant (get and single-delete)
- `errors.TRANSACTION_TIMEOUT` — `408` — `transactionTimeoutMillis` elapsed before the message save began (create only); nothing was stored
- `413` — request body exceeds the 10 MiB limit (create and batch-delete)
- `401` — missing or invalid Bearer token
- `403` — authenticated but not authorized
- `500` — internal error; generic message plus a ticket UUID, full detail logged server-side
## EXAMPLES
**Create a message:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-H "X-Correlation-ID: nobel-2024-physics" \
-d '{
"metaData": { "eventType": "nobel.prize.announced" },
"payload": { "category": "physics", "year": "2024" }
}' \
"http://localhost:8080/api/message/new/nobel.prize.events"
```
**Retrieve a message:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/message/8824c480-c166-11ee-bf9f-ae468cd3ed16"
```
**Delete a single message:**
```
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/message/8824c480-c166-11ee-bf9f-ae468cd3ed16"
```
**Delete several messages by ID:**
```
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '["8824c480-c166-11ee-9cc7-ae468cd3ed16","31134900-d9cb-11ee-9cc7-ae468cd3ed16"]' \
"http://localhost:8080/api/message"
```
## SEE ALSO
- crud
- cloudevents
- openapi
- errors.ENTITY_NOT_FOUND
- errors.BAD_REQUEST
## See also
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help cloudevents`](/help/cloudevents/) — cyoda-go uses [CloudEvents v1.0](https://cloudevents.io) as the transport envelope for event-driven processing. Every payload carried inside a CloudEvent — workflow calculation requests, calculation responses, entity transaction events, snapshot state, model descriptors — is validated against a JSON Schema (Draft 2020-12).
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
- [`cyoda help errors ENTITY_NOT_FOUND`](/help/errors/entity_not_found/) — No entity with the given ID exists in the tenant's data store, or the entity existed at a point-in-time that precedes the requested snapshot. Also returned for audit log lookups when the specified event or message cannot be found.
- [`cyoda help errors BAD_REQUEST`](/help/errors/bad_request/) — Fired when the server cannot parse or structurally process the incoming request. Common triggers include invalid JSON, unsupported format specifiers, a parameter outside its allowed range, and mutually exclusive parameters set together.
- [`cyoda help errors TRANSACTION_TIMEOUT`](/help/errors/transaction_timeout/) — Fires when the client-supplied `transactionTimeoutMillis` elapses before the first commit. Nothing was committed.
## Raw formats
- [`/help/messages.json`](/help/messages.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/messages.md`](/help/messages.md) — body only
---
## help/models.md
# models — entity model schema system
A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(ent…
cyoda-go version 0.8.4
# models
## NAME
models — entity model schema system: registration, lifecycle, import, export, and validation.
## SYNOPSIS
```
GET /api/model/
GET /api/model/export/{converter}/{entityName}/{modelVersion}
POST /api/model/import/{dataFormat}/{converter}/{entityName}/{modelVersion}
POST /api/model/validate/{entityName}/{modelVersion}
DELETE /api/model/{entityName}/{modelVersion}
POST /api/model/{entityName}/{modelVersion}/changeLevel/{changeLevel}
PUT /api/model/{entityName}/{modelVersion}/lock
PUT /api/model/{entityName}/{modelVersion}/unlock
PUT /api/model/{entityName}/{modelVersion}/unique-keys
GET /api/model/{entityName}/{modelVersion}/workflow/export
POST /api/model/{entityName}/{modelVersion}/workflow/import
```
Context path prefix is `CYODA_CONTEXT_PATH` (default `/api`).
## DESCRIPTION
A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
Models have two lifecycle states: `UNLOCKED` and `LOCKED`. A `LOCKED` model blocks further imports. An `UNLOCKED` model accepts re-import and schema merging. Entities can only be created against a `LOCKED` model. Deletion is blocked while any entities reference the model.
Schema inference is additive: importing sample data against an existing model merges the incoming schema with the stored one. The model's `changeLevel` field controls which structural changes are allowed during entity ingestion on a locked model.
**Sample data is a document, or a collection of documents.** A JSON object is one sample document. A JSON array is several — each element must itself be an object, and the derived model is their merge, the same result successive imports produce. Any other body (a scalar, an array holding a non-object) is rejected with `400 VALIDATION_FAILED`, naming the offending element.
**A value's kind must be one the field declares.** A field declared as a scalar accepts a scalar; declared as an array, an array; declared as an object, an object. A value of any other kind is rejected with `400`, at every depth including array elements. On a model with no `changeLevel` (and on PATCH) that is `VALIDATION_FAILED` — `expected scalar, got array`, naming every kind the field does declare. With a `changeLevel` set the write also proposes a schema change, so the answer turns on the level: giving a path a kind it does not declare is a `STRUCTURAL` change, refused below that level and accepted at it.
A field may declare more than one kind — observed in each while the model is `UNLOCKED` (successive imports, or one import of several sample documents), or added by a write at `STRUCTURAL`. Every declared kind is admissible at every `changeLevel`, and the export names each branch.
A path that declares no kind at all is the exception worth knowing: a field observed only as `null`, or an array observed with no content, has nothing to conflict with, so it learns its first kind at `TYPE` (or `ARRAY_ELEMENTS` for an array's element) rather than at `STRUCTURAL`.
**A value costs a `TYPE`-level change only if the field does not already admit it.** A field admits a value when the value's JSON kind matches one of the field's declared types and that type's own admission test accepts the value — the model changes only when it does not. This is not "the value's classified type widens into what's declared"; it is a direct, per-value test against each declared type.
For a number the test is per numeric family, not "inside the declared type's range": `INTEGER`/`LONG`/`BIG_INTEGER` admit a whole number within the type's own bounds; `UNBOUND_INTEGER` admits any whole number; `DOUBLE` admits a value within its range **and** representable in at most 15 significant digits with a scale of at most 292; `BIG_DECIMAL` admits by magnitude alone; `UNBOUND_DECIMAL` admits everything. Writing `1000`, `1000.0`, `1e3` — or `2147483648`, ten digits and still exactly representable — to a field declared `DOUBLE` proposes no schema change and is accepted at every `changeLevel`, `ARRAY_LENGTH` included, because each value's own precision and scale fit `DOUBLE`'s admission test.
A larger whole number can still force a change: `9007199254740993` needs sixteen significant digits, past what `DOUBLE`'s 53-bit mantissa can hold exactly, so writing it to a `DOUBLE` field is a real type change — refused below `TYPE`, and at `TYPE` it widens the field to `UNBOUND_DECIMAL`, the narrowest type that holds both. A decimal into a field declared `INTEGER` is a type change for the same reason: the integer family never admits a fractional value. See `docs/numeric-classification.md` for the full per-family predicate and why the range alone is not the test.
**A `STRING` field admits any string, including one shaped like a date or timestamp, without changing the model.** Writing `"2026-03-01"` to a field declared `STRING` is not a type change — `STRING` admits every string — and the field's declared types are unaffected. A field that is *also* declared as a temporal type (`LOCAL_DATE`, `ZONED_DATE_TIME`, and so on) holds a value under that type only when the string's own classification is exactly that type: a `ZONED_DATE_TIME`-declared field does not hold a bare `"2026"` (a year, not a timestamp), and a `LOCAL_DATE_TIME`-declared field does not hold a string carrying a UTC offset (that string denotes a different instant than the one truncating the offset would give). An entity write to a text-declared field no longer learns a temporal subtype the way a write once did — **registration is how a field acquires a temporal type**: importing sample data that shows both a plain string and a date-shaped one yields a field declared both `STRING` and, say, `LOCAL_DATE`; an ordinary write to an already-`STRING` field does not grow that declaration on its own.
`null` follows the declaration like any other value: a scalar field always accepts it, and a container field accepts it only where the model observed one (the sample data had `null` there). It is not a kind of its own, so it never widens the model.
**Field names must be searchable.** A field name is accepted only if it is a valid `jsonPath` segment: one or more ASCII letters, digits, `_` or `-`. Spaces, dots, quotes, brackets, `$`, `@`, `:`, the evaluator's own metacharacters (`*`, `?`, `#`, `|`, `!`, `\`), any non-ASCII character, and the empty name are rejected with `400 VALIDATION_FAILED`, naming the offending key and the object that declares it. Search addresses a field by a `jsonPath` built from exactly this charset and offers no escape hatch, so a field outside it could be written and never queried — it is refused at the door instead.
This applies to both paths that establish a model's field set: sample-data import, and the `changeLevel`-driven schema extension an entity write performs. Strict validation (a model with no `changeLevel`, and PATCH) does not establish fields, so the rule does not apply there. A model that already carries a non-conforming field is not migrated and there is no compatibility path: rename the key in the source data and re-establish the model.
## ENDPOINTS
**GET /api/model/**
List all models for the authenticated tenant.
Response: `200 OK`, `application/json`, array of `EntityModelDto`.
**POST /api/model/import/{dataFormat}/{converter}/{entityName}/{modelVersion}**
Import or update a model schema from sample data. Body size limit: 10 MiB.
- `dataFormat` (path): `JSON` or `XML`
- `converter` (path): `SAMPLE_DATA` (only supported converter; `JSON_SCHEMA` and `SIMPLE_VIEW` are defined in the OpenAPI but return `400 BAD_REQUEST` in this implementation)
- `entityName` (path): string — model name
- `modelVersion` (path): int32 — model version number
If the model does not exist, it is created with state `UNLOCKED`. If it exists and is `UNLOCKED`, the incoming schema is merged (additive). If it exists and is `LOCKED`, returns `409 CONFLICT`.
Response: `200 OK`, `application/json`, UUID string — the model ID.
**GET /api/model/export/{converter}/{entityName}/{modelVersion}**
Export a model schema in the specified format.
- `converter` (path): `JSON_SCHEMA` or `SIMPLE_VIEW`
- `entityName` (path): string
- `modelVersion` (path): int32
Response: `200 OK`, `application/json` — format depends on converter.
**POST /api/model/validate/{entityName}/{modelVersion}**
Validate a JSON payload against the model's schema. Returns a result object, not an HTTP error, on validation failure.
- `entityName` (path): string
- `modelVersion` (path): int32
Request body: any JSON object.
Response: `200 OK`, `application/json`, `EntityModelActionResultDto`.
**DELETE /api/model/{entityName}/{modelVersion}**
Delete a model. Blocked if the model is `LOCKED` or if any entities reference it (entity count > 0).
Response: `200 OK`, `application/json`, `EntityModelActionResultDto` on success. `409 MODEL_ALREADY_LOCKED` if the model is locked; `409 MODEL_HAS_ENTITIES` if entities reference it.
**POST /api/model/{entityName}/{modelVersion}/changeLevel/{changeLevel}**
Set or update the change level on a model. Meaningful for locked models; unlocked models always allow all changes.
- `changeLevel` (path): `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, or `STRUCTURAL`
Change levels are hierarchical (most restrictive to most permissive):
- `ARRAY_LENGTH` — permits no schema change at all: the floor of the ladder. An array's length is not part of the model, so a longer array is held here exactly as at every other level
- `ARRAY_ELEMENTS` — allows an array's element to learn its first scalar type, or to widen the one it declares; nothing outside an array may change
- `TYPE` — permits modifications to existing types
- `STRUCTURAL` — allows fundamental model changes: new fields, and giving a path a kind it does not yet declare
Response: `200 OK`, `application/json`, `EntityModelActionResultDto`.
**PUT /api/model/{entityName}/{modelVersion}/lock**
Lock a model. The model must be `UNLOCKED`. Returns `409 CONFLICT` if already locked.
Response: `200 OK`, `application/json`, `EntityModelActionResultDto`.
**PUT /api/model/{entityName}/{modelVersion}/unlock**
Unlock a model. The model must be `LOCKED` and have zero associated entities. Returns `409 CONFLICT` if entities exist or model is not locked.
Response: `200 OK`, `application/json`, `EntityModelActionResultDto`.
**PUT /api/model/{entityName}/{modelVersion}/unique-keys**
Declare composite unique keys for a model. Allowed only while the model is `UNLOCKED`. This call is idempotent — it replaces the model's entire key list atomically.
Request body (`application/json`):
```json
{
"uniqueKeys": [
{ "id": "by-email", "fields": ["$.email"] },
{ "id": "by-org-and-handle", "fields": ["$.org", "$.handle"] }
]
}
```
- `uniqueKeys` — array of key definitions; `[]` clears all keys.
- `id` — stable string identifier, unique within the model.
- `fields` — ordered array of scalar leaf field paths (dotted paths matching the model's inferred schema). Array, object, and wildcard paths are rejected.
Validation is immediate: field paths must be known scalar leaves in the model's schema; duplicate `id` values and empty `fields` arrays are rejected.
Returns `200 OK` with `EntityModelActionResultDto` on success.
- `422 COMPOSITE_KEY_UNSUPPORTED` — the active storage backend does not support composite unique keys.
- `409 MODEL_ALREADY_LOCKED` — model is not in `UNLOCKED` state.
- `422 INVALID_UNIQUE_KEY_DEFINITION` — a field path references a non-scalar/unknown/array field, a key `id` is duplicated, or `fields` is empty.
**Transactional ordering.** When one transaction (e.g. a workflow) both frees a unique-key value — by deleting or re-keying its holder — and claims it on another entity, free it before claiming. Free-then-claim works on every backend; the reverse is rejected on write-time backends (PostgreSQL) and accepted on commit-time ones (in-memory, SQLite), so free-before-claim for portable behavior.
**GET /api/model/{entityName}/{modelVersion}/workflow/export**
Export all workflow configurations for the model. Returns `404 WORKFLOW_NOT_FOUND` if no workflows exist.
Response: `200 OK`, `application/json`:
```json
{
"entityName": "nobel-prize",
"modelVersion": 1,
"workflows": []
}
```
**POST /api/model/{entityName}/{modelVersion}/workflow/import**
Import or replace workflow configurations for the model. See `workflows` topic.
## REQUEST SCHEMAS
**EntityModelDto** (returned by `GET /api/model/`):
```json
{
"id": "31134900-d9cb-11ee-b913-ae468cd3ed16",
"modelName": "nobel-prize",
"modelVersion": 1,
"currentState": "LOCKED",
"modelUpdateDate": "2025-08-02T13:31:48.141053-07:00"
}
```
- `id` — UUID (deterministic v5, derived from name+version)
- `modelName` — string
- `modelVersion` — int32
- `currentState` — `"LOCKED"` or `"UNLOCKED"`
- `modelUpdateDate` — RFC 3339 timestamp, nullable
**EntityModelActionResultDto** (returned by lock, unlock, delete, changeLevel, validate):
```json
{
"success": true,
"message": "Model nobel-prize:1 locked",
"modelId": "cee334fa-c0ac-11f0-ba79-ae468cd3ed16",
"modelKey": {
"name": "nobel-prize",
"version": 1
}
}
```
- `success` — boolean
- `message` — human-readable result string
- `modelId` — UUID
- `modelKey.name` — string
- `modelKey.version` — int32
**Import request body** (sample data, JSON format):
```json
{
"category": "physics",
"year": "2024",
"laureates": [
{
"firstname": "John",
"surname": "Hopfield",
"id": "1037",
"motivation": "for foundational discoveries",
"share": "2"
}
]
}
```
The importer walks the JSON structure and infers a typed schema. Subsequent imports are merged additively. A JSON array body is read as several sample documents and merged the same way.
**Export — SIMPLE_VIEW format**:
```json
{
"currentState": "LOCKED",
"model": {
"$": {
"#.laureates": "OBJECT",
".category": "STRING",
".year": "STRING"
},
"$.laureates[*]": {
"#": "ARRAY_ELEMENT",
".firstname": "STRING",
".id": "STRING",
".motivation": "STRING",
".share": "STRING",
".surname": "STRING"
}
},
"uniqueKeys": [
{ "id": "by-email", "fields": ["$.email"] }
]
}
```
The `"$"` bucket includes a `"#.fieldname": "OBJECT"` entry for each array field in the root object. The `"$.fieldname[*]"` bucket contains the array element schema with `"#": "ARRAY_ELEMENT"` as a type marker. `uniqueKeys` is omitted when the model declares no composite unique keys.
An array of arrays is spelled one `[*]` hop per level — `".m[*][*]": "STRING"`, and `"$.m[*][*]"` for the bucket when its elements are objects — matching the `jsonPath` a search uses to address them.
A field declared in more than one kind names each branch it declares: `".poly": "STRING"` alongside `".poly[*]": "STRING"`, or `".o": "STRING"` alongside `"#.o": "OBJECT"`. Both are enforced, so both are shown.
**Export — JSON_SCHEMA format**:
```json
{
"currentState": "LOCKED",
"model": {
"type": "object",
"properties": {
"category": { "type": "string" },
"year": { "type": "string" },
"laureates": {
"type": "array",
"items": {
"type": "object",
"properties": {
"firstname": { "type": "string" },
"share": { "type": "string" },
"id": { "type": "string" },
"surname": { "type": "string" },
"motivation": { "type": "string" }
}
}
}
}
},
"uniqueKeys": [
{ "id": "by-email", "fields": ["$.email"] }
]
}
```
## LIFECYCLE
A model moves between two states:
- `UNLOCKED` — initial state after first import; re-import is permitted; entities cannot be created
- `LOCKED` — entities can be created; re-import is blocked; change-level controls in-flight schema extension
Transitions:
- `UNLOCKED` → `LOCKED` via `PUT /model/{name}/{version}/lock`
- `LOCKED` → `UNLOCKED` via `PUT /model/{name}/{version}/unlock` (only when entity count is zero)
The `changeLevel` field controls schema evolution on locked models. When set, entity ingestion that introduces new structure triggers an additive schema extension (delta computed via `schema.Diff`, appended via `ModelStore.ExtendSchema`, committed with the entity transaction).
Entity ingestion here includes data returned by a workflow processor, not just data sent by a client. A processor that writes a field the model does not declare needs `changeLevel` set exactly as a client would.
## ERRORS
- `errors.MODEL_NOT_FOUND` — `404` — model does not exist for the given name and version
- `errors.MODEL_ALREADY_LOCKED` — `409` — re-import, relock, or delete attempted on a model already in `LOCKED` state
- `errors.MODEL_ALREADY_UNLOCKED` — `409` — unlock attempted on a model already in `UNLOCKED` state
- `errors.MODEL_HAS_ENTITIES` — `409` — unlock or delete blocked because entities of the model exist (`entityCount` in `properties`)
- `errors.INVALID_CHANGE_LEVEL` — `400` — `POST /model/{name}/{version}/changeLevel/{changeLevel}` supplied a value that is not one of `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, `STRUCTURAL` (`entityName`, `entityVersion`, `suppliedValue`, `validValues` in `properties`)
- `errors.VALIDATION_FAILED` — `400` — workflow import validation failed (static analysis); sample data that is neither a document nor a collection of documents; a field name that is not addressable
- `errors.BAD_REQUEST` — `400` — unsupported converter, or a malformed body
- `errors.UNIQUE_VIOLATION` — `409` — entity write rejected because it would duplicate a composite unique key value-set held by another live entity
- `errors.INVALID_UNIQUE_KEY` — `422` — entity write rejected because a key is partially filled (all-or-nothing rule), the numeric value exceeded the allowed precision bound, or a key field path resolves to a non-scalar value
- `errors.COMPOSITE_KEY_UNSUPPORTED` — `422` — composite unique key declared on a backend that does not support the feature
- `errors.INVALID_UNIQUE_KEY_DEFINITION` — `422` — key declaration rejected: non-scalar or unknown field path, duplicate key `id`, or empty `fields` array
## EXAMPLES
**Import a model from sample JSON:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"category":"physics","year":"2024","laureates":[{"firstname":"John","surname":"Hopfield","id":"1037"}]}' \
"http://localhost:8080/api/model/import/JSON/SAMPLE_DATA/nobel-prize/1"
```
Response: `"1d1e1b10-1155-11f0-bcd5-ae468cd3ed16"`
**Lock the model:**
```
curl -s -X PUT \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/model/nobel-prize/1/lock"
```
**Set change level (allow structural evolution on locked model):**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/model/nobel-prize/1/changeLevel/STRUCTURAL"
```
**List all models:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/model/"
```
**Export as SIMPLE_VIEW:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/model/export/SIMPLE_VIEW/nobel-prize/1"
```
**Validate a payload against the model:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"category":"physics","year":"2024"}' \
"http://localhost:8080/api/model/validate/nobel-prize/1"
```
**Delete a model (must be unlocked and have zero entities):**
```
curl -s -X DELETE \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/model/nobel-prize/1"
```
## SEE ALSO
- crud
- workflows
- search
- errors.MODEL_NOT_FOUND
- errors.MODEL_ALREADY_LOCKED
- errors.MODEL_ALREADY_UNLOCKED
- errors.MODEL_HAS_ENTITIES
- errors.INVALID_CHANGE_LEVEL
- errors.VALIDATION_FAILED
- errors.UNIQUE_VIOLATION
- errors.INVALID_UNIQUE_KEY
- errors.COMPOSITE_KEY_UNSUPPORTED
- errors.INVALID_UNIQUE_KEY_DEFINITION
- openapi
## See also
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors MODEL_ALREADY_LOCKED`](/help/errors/model_already_locked/) — Returned by any admin operation that requires the model be in the `UNLOCKED` state, including:
- [`cyoda help errors MODEL_ALREADY_UNLOCKED`](/help/errors/model_already_unlocked/) — Returned when `POST /model/{name}/{version}/unlock` is issued against a model whose current state is `UNLOCKED`. Distinct from `MODEL_NOT_LOCKED`, which is reserved for the entity-write-without-lock path on the entity service: this code is the symmetric counterpart of `MODEL_ALREADY_LOCKED` for the admin lifecycle.
- [`cyoda help errors MODEL_HAS_ENTITIES`](/help/errors/model_has_entities/) — Both `POST /model/{name}/{version}/unlock` and `DELETE /model/{name}/{version}` require zero entities of the target model. The cardinality check guards against silent loss of data and against schema drift on a model whose lifecycle is presumed frozen.
- [`cyoda help errors INVALID_CHANGE_LEVEL`](/help/errors/invalid_change_level/) — The `changeLevel` path segment must be exactly one of: `ARRAY_LENGTH`, `ARRAY_ELEMENTS`, `TYPE`, or `STRUCTURAL`. Comparison is case-sensitive. Any other value (including the empty string, lower-cased variants, or typos) yields this error.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
- [`cyoda help errors UNIQUE_VIOLATION`](/help/errors/unique_violation/) — The entity payload contains field values that collide with an existing entity's composite unique key. Unlike an optimistic-concurrency CONFLICT (which is retryable), a unique-key violation is a permanent data constraint — retrying the same payload without changing the key field values will produce the same result.
- [`cyoda help errors INVALID_UNIQUE_KEY`](/help/errors/invalid_unique_key/) — A composite unique key requires every declared field to be present and non-null. This error is returned when the entity payload is missing a value for at least one key field, or the value cannot be normalized to a valid claim (for example, a NaN or ±Infinity for a numeric key field).
- [`cyoda help errors COMPOSITE_KEY_UNSUPPORTED`](/help/errors/composite_key_unsupported/) — Composite unique key enforcement is an optional capability that storage backends may or may not implement. This error is returned when a model defines one or more unique keys but the backend does not implement the `CompositeUniqueKeyCapable` interface.
- [`cyoda help errors INVALID_UNIQUE_KEY_DEFINITION`](/help/errors/invalid_unique_key_definition/) — Each unique key on a model must have a non-empty list of field paths, a unique name within the model, and field paths that resolve to existing, non-ambiguous fields in the model schema. This error is returned when a submitted model definition violates one of these structural requirements.
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
## Raw formats
- [`/help/models.json`](/help/models.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/models.md`](/help/models.md) — body only
---
## help/openapi.md
# openapi — OpenAPI 3 spec and discovery endpoints
cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `…
cyoda-go version 0.8.4
# openapi
## NAME
openapi — OpenAPI 3.1 specification and discovery endpoints for the cyoda-go REST API.
## SYNOPSIS
```
GET /openapi.json
GET /docs
GET {CYODA_CONTEXT_PATH}/help
GET {CYODA_CONTEXT_PATH}/help/{topic}
```
Discovery endpoints are served at the root of the HTTP listener (port `CYODA_HTTP_PORT`, default 8080). They are mounted outside `CYODA_CONTEXT_PATH` — no prefix is applied.
## DESCRIPTION
cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
The `/openapi.json` and `/docs` endpoints require no authentication. The help endpoints (`/help`, `/help/{topic}`) also require no authentication.
## DISCOVERY ENDPOINTS
**GET /openapi.json**
Returns the OpenAPI 3.1 specification as JSON. The `servers` array is overridden at request time to reflect the actual runtime host and `CYODA_CONTEXT_PATH`. The scheme (`http` or `https`) is derived from whether the incoming connection is TLS.
Response: `200 OK`, `application/json`.
The spec itself sets `info.version` to `"1.0"` (a fixed spec version, not the binary version). The binary version is reported separately in the `GET /help` payload under the `version` field.
**GET /docs**
Returns an HTML page embedding the Scalar API Reference UI. The UI loads the spec from `/openapi.json` and provides an interactive browser. No JavaScript execution is required on the server side — the HTML page references the Scalar CDN script.
Response: `200 OK`, `text/html; charset=utf-8`.
**GET {CYODA_CONTEXT_PATH}/help**
Returns the full help topic tree as JSON. The response includes the binary version string and an array of all topic descriptors.
Response: `200 OK`, `application/json`:
```json
{
"schema": 1,
"version": "dev",
"topics": [
{
"topic": "quickstart",
"title": "cyoda quickstart — minimum invocations",
"stability": "stable",
"tagline": "minimum commands to run a cyoda-go server.",
"see_also": ["cli", "config"]
}
]
}
```
**GET {CYODA_CONTEXT_PATH}/help/{topic}**
Returns a single help topic descriptor by dotted path. The `topic` path segment uses dots as separators (e.g. `config.database`, `errors.MODEL_NOT_FOUND`). Topics are resolved via the embedded help tree.
Response: `200 OK`, `application/json` — same shape as a single element of the `topics` array above, with the addition of a `body` field containing the full Markdown content.
`404 HELP_TOPIC_NOT_FOUND` when the topic path does not exist.
`400 BAD_REQUEST` when the topic path contains disallowed characters (only `A-Za-z0-9`, `.`, `_`, `-` are allowed; no leading/trailing dots or hyphens).
## SPEC SHAPE
The spec declares 83 paths across these tag groups:
- **Entity Management** — create, update, delete, transition, and stats endpoints under `/entity/`
- **Entity Model** — model import, export, lock, unlock, delete, changeLevel, and workflow under `/model/`
- **Search** — snapshot and direct search under `/search/`
- **User, Account** — account info and subscriptions under `/account/`
- **User, Machine** — M2M client management under `/clients/`
- **Entity, Audit** — audit log retrieval under `/audit/`
- **Messaging** — message CRUD under `/message/`
- **IAM** — OAuth token and key management under `/oauth/`. As of v0.8.0, the 10 `/oauth/keys/*` admin operations (keypair + trusted-key lifecycle), the 7 `/oauth/oidc/providers/*` operations, and the 4 `/clients` operations are conformant. Remaining stubbed surface across `/account/*` and adjacent paths is tracked in `docs/cyoda/cloud-divergences.md`.
- **SQL Schema** — SQL schema generation and management under `/sql/schema/` (excluded from cyoda-go — see below)
- **Platform API** — stream-data operations under `/platform-api/stream-data/` (excluded from cyoda-go — see below)
The **Stream Data** and **SQL-Schema** tag groups (22 operations) are excluded from the cyoda-go
shipped API via `api/config.yaml`'s `exclude-tags` list. These operations are not served by
cyoda-go and are filtered from the generated `ServerInterface` and from E2E coverage tracking.
Named schemas added or refined since the initial spec import:
- `Envelope` — entity get/list response wrapper `{type, data, meta}`
- `EdgeMessagePayload` — polymorphic message content schema
- `MessageDeleteResponse` — single-message delete response `{entityIds: []string}`
- `MessageDeleteBatchResponse` — batch message delete response `{entityIds, success}`
- `TransitionNameList` — transitions query response (array of strings)
- `WorkflowImportSuccessDto` — workflow import 200 response `{success: bool}`
- `AuditEvent` discriminator union — `EntityChangeAuditEvent` / `StateMachineAuditEvent`
All paths in the spec are relative to the `servers[0].url`, which is set at runtime to `{scheme}://{host}{CYODA_CONTEXT_PATH}`. The default context path is `/api`, so `GET /entity/{entityId}` is served at `http://localhost:8080/api/entity/{entityId}`.
## AUTHENTICATION
The spec declares two security schemes:
```yaml
components:
securitySchemes:
bearerAuth:
type: http
scheme: bearer
description: >-
Authorization header: `Bearer `
basicAuth:
type: http
scheme: basic
```
Global security is applied to all operations: `security: [{bearerAuth: []}]`. The `basicAuth` scheme is declared for spec validity — it is referenced by Platform API (Stream Data) operations that are out of scope for the cyoda-go server. Discovery endpoints (`/openapi.json`, `/docs`) and help endpoints are not part of the spec and carry no security requirement.
When `CYODA_IAM_MODE=mock`, the server accepts requests without a token. When `CYODA_IAM_MODE=jwt`, a valid JWT Bearer token is required on all protected endpoints.
## CONFORMANCE VALIDATOR
The E2E test suite (`internal/e2e/`) includes an OpenAPI conformance validator
(`internal/e2e/openapivalidator/`) that runs in the background during every E2E
test run. For each HTTP response the in-process test server produces, the
middleware captures the status code and body and validates them against the
spec's declared schema for that operation.
The validator operates in two modes:
- **Record mode** (default): mismatches are collected and written to
`internal/e2e/_openapi-conformance-report.md` after the suite completes.
No tests fail due to spec drift.
- **Enforce mode**: any mismatch immediately fails the test that triggered it,
and the suite-level conformance report test also fails if any mismatches
remain at the end.
The conformance layer also tracks which operationIds are exercised across the
E2E suite. Operations that appear in the spec but have no E2E coverage are
reported as "uncovered" (in enforce mode, this fails the suite unless the
operation is listed in `knownUncoveredOps`). See ADR 0001 in
`docs/superpowers/specs/` for the design rationale.
## CONTEXT PATH
`CYODA_CONTEXT_PATH` (default `/api`) is the prefix applied to all API routes. It affects:
- The `servers[0].url` field in the served `/openapi.json` response.
- All route registrations for entity, model, search, audit, messaging, OAuth, and SQL endpoints.
- The help route prefix (`{CYODA_CONTEXT_PATH}/help` and `{CYODA_CONTEXT_PATH}/help/{topic}`).
The discovery routes `/openapi.json` and `/docs` are always at the root — `CYODA_CONTEXT_PATH` does not prefix them.
Setting `CYODA_CONTEXT_PATH=` (empty string) mounts all routes at root with no prefix.
## VERSIONING
The spec `info.version` field is `"1.0"` — a fixed spec format version. It does not track the binary version.
The binary version is injected at build time via `-ldflags` and reported in:
- The startup banner printed to stderr.
- The `GET {CYODA_CONTEXT_PATH}/help` JSON payload's `version` field.
## ERRORS
The REST API uses `application/problem+json` (RFC 9457 Problem Details) error responses. See `errors` for the canonical shape and the full error code catalogue.
Error response shape (4xx example):
```json
{
"type": "about:blank",
"title": "Not Found",
"status": 404,
"detail": "MODEL_NOT_FOUND: model nobel-prize:1 not found",
"instance": "/api/model/nobel-prize/1",
"properties": {
"errorCode": "MODEL_NOT_FOUND",
"retryable": false
}
}
```
Error response shape (5xx example):
```json
{
"type": "about:blank",
"title": "Internal Server Error",
"status": 500,
"detail": "SERVER_ERROR: internal error [ticket: 3fa85f64-5717-4562-b3fc-2c963f66afa6]",
"instance": "/api/entity/abc",
"ticket": "3fa85f64-5717-4562-b3fc-2c963f66afa6",
"properties": {
"errorCode": "SERVER_ERROR"
}
}
```
`CYODA_ERROR_RESPONSE_MODE=sanitized` (default) suppresses internal detail from 5xx `detail` fields. `CYODA_ERROR_RESPONSE_MODE=verbose` includes full error detail — for development environments only.
## EXAMPLES
**Fetch the OpenAPI spec:**
```
curl -s http://localhost:8080/openapi.json | jq '.info'
```
**Fetch with custom context path:**
```
CYODA_CONTEXT_PATH=/v1 \
curl -s http://localhost:8080/openapi.json | jq '.servers'
```
Response:
```json
[{"url": "http://localhost:8080/v1"}]
```
**Open the interactive UI:**
```
curl -s -o /dev/null -w "%{http_code}" http://localhost:8080/docs
```
**Fetch the full help topic tree:**
```
curl -s http://localhost:8080/api/help | jq '.topics[].topic'
```
**Fetch a specific help topic:**
```
curl -s http://localhost:8080/api/help/models | jq '.title'
```
**Fetch the spec from a Docker container:**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-e CYODA_STORAGE_BACKEND=memory \
ghcr.io/cyoda/cyoda:latest &
sleep 2
curl -s http://localhost:8080/openapi.json | jq '.paths | keys | length'
```
## ACTION DETAILS
- `cyoda help openapi json` — emit the embedded OpenAPI spec as JSON to stdout
- `cyoda help openapi yaml` — emit the embedded OpenAPI spec as YAML to stdout
- `cyoda help openapi tags` — list every tag in the spec as `` pairs (tabular, sorted by slug)
- `cyoda help openapi ` — emit a standalone OpenAPI 3.1 document scoped to the named tag; paths filtered to operations carrying that tag, components pruned to only the transitively-referenced members. Pass `--format=yaml` to emit YAML instead of the default JSON. Discover valid slugs via `cyoda help openapi tags`. Unknown slugs exit 2 with the full valid-slug list in the error.
The emitted spec is the binary's compile-time baseline. The `servers` array reflects whatever is embedded at build time; the running server's HTTP endpoint (`GET /openapi.json`) rewrites `servers` per request, but the CLI does not.
Per-tag filtering is useful for AI agents and downstream tooling that only need the slice of the API corresponding to one concern (e.g. just `entity-management` or just `search`) — the pruned spec is typically 3-5× smaller than the full spec and is still a valid standalone OpenAPI 3.1 document (every `$ref` resolves within its own `components`).
## SEE ALSO
- crud
- models
- search
- workflows
- errors
- config.auth
- cli.serve
## See also
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help errors`](/help/errors/) — Every error response from the Cyoda REST API carries a structured `errorCode` in the `properties` object. Multiple codes may share the same HTTP status. Programmatic handling keys on `errorCode`, not HTTP status.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help cli serve`](/help/cli/serve/) — Starting with no subcommand loads configuration from environment variables, validates the IAM mode, and binds the REST, gRPC, and admin listeners. The server is single-process, multi-tenant, and stateful — storage is provided by one of the pluggable backends (`memory`, `sqlite`, or `postgres`); see `cyoda help config` for backend selection.
## Raw formats
- [`/help/openapi.json`](/help/openapi.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/openapi.md`](/help/openapi.md) — body only
---
## help/predicates.md
# predicates — search & criteria condition semantics
predicates — operator catalog and evaluation semantics for the `Condition` DSL used by search (`cyoda help search`) and workflow/transition criteria (`cyo…
cyoda-go version 0.8.4
# predicates
## NAME
predicates — operator catalog and evaluation semantics for the `Condition` DSL used by search (`cyoda help search`) and workflow/transition criteria (`cyoda help workflows`). Both consume the same kernel, so everything here applies identically to both.
## OPERATORS
**Unary** (test presence, no operand type constraint):
- `IS_NULL` — the leaf is absent or JSON `null`.
- `NOT_NULL` — the leaf is present and non-null.
**Range** (operand is a two-element `[low, high]` array):
- `BETWEEN` — exclusive bounds.
- `BETWEEN_INCLUSIVE` — inclusive bounds.
**Binary — comparison** (same-type `compareTo`):
- `EQUALS`, `NOT_EQUAL`, `GREATER_THAN`, `GREATER_OR_EQUAL`, `LESS_THAN`, `LESS_OR_EQUAL`.
- `IEQUALS` (case-insensitive equals), `INOT_EQUAL` (case-insensitive not-equal).
**Binary — string** (case-sensitive; `I*`/`INOT_*` fold both sides):
- `CONTAINS`, `STARTS_WITH`, `ENDS_WITH`, and their `NOT_*` inverses.
- `ICONTAINS`/`INOT_CONTAINS`, `ISTARTS_WITH`/`INOT_STARTS_WITH`, `IENDS_WITH`/`INOT_ENDS_WITH`.
**Binary — pattern:**
- `LIKE` — anchored glob, see LIKE GRAMMAR below.
- `MATCHES_PATTERN` — anchored regular expression, see MATCHES_PATTERN below.
**Not supported:** `IS_CHANGED`/`IS_UNCHANGED` are change-generation operators, not search predicates — cyoda-go does not implement them.
## GROUP OPERATORS
`AND`, `OR`, and `NOT` combine conditions (`GroupCondition`, see `cyoda help search`). `NOT` takes **exactly one** child condition — `NOT(c)` is true exactly when `c` is false — and is never rewritten by De Morgan into a leaf's negative twin: `NOT(EQUALS)` is not `NOT_EQUAL`, and `NOT(IS_NULL)` is not `NOT_NULL`. Over a wildcard path `NOT` is a universal quantifier where the leaf beneath it is existential — `NOT($.tags[*] EQUALS "red")` means no element equals `"red"`, a different question from `$.tags[*] NOT_EQUAL "red"` (some element differs). See `cyoda help search` for the full contract, including the one-condition rule and the absent-field/presence-test asymmetries.
## TYPE-DIRECTED COMPARISON
A condition's operand is compared against the target field's **declared type(s)** (a leaf may carry more than one, e.g. a field seen as both an integer and a string across entities). The operand is treated as a string and parse-tested against every declared type — a numeric-looking string operand (`"30"`) and a JSON number operand (`30`) are parsed identically and are **treated the same**. There is no cross-type coincidental matching: an operand that parses as a number only compares against numerically-stored values; an operand that parses only as a string compares against string-stored values. Numbers compare precisely (arbitrary-precision, not `float64` — correct beyond 2^53). String and pattern operators apply to text fields only.
**An unsatisfiable comparison follows operator polarity.** This applies only once an operand has been accepted — it parses into at least one of the field's declared types (see `errors.CONDITION_TYPE_MISMATCH`). Evaluation still runs per stored-value type family: when a given family's declared type produced no surviving sub-condition for that operand, a **positive** operator (`EQUALS`, `GREATER_THAN`, the string operators, …) answers non-match for an entity in that family, and a **negative** operator (`NOT_EQUAL`, `NOT_CONTAINS`, `INOT_*`, …) answers match instead. `$.n NOT_EQUAL 12.5` on an `INTEGER` field matches every entity holding a number there, because no integer equals `12.5` — the same answer PostgreSQL gives for `5::int <> 12.5`. This is a determinate answer about the entity, not a rejection, and null/absent values are unaffected (see NULL SEMANTICS below). An operand that parses into none of a known field's declared types at all is rejected before evaluation instead (`400 CONDITION_TYPE_MISMATCH`). A field carrying no declared type at all is a different failure with a different code: there is no declared-type check to run, so the operand is accepted here and the leaf instead fails at preparation with `400 INVALID_CONDITION`.
## NULL SEMANTICS
A missing (absent) or JSON-`null` leaf **never matches any binary operator — including negatives**. `NOT_EQUAL`, `NOT_CONTAINS`, `INOT_*`, and every other negated op are **null-guarded to non-match**, not `!positive` — a null/absent field does not satisfy a negative condition just because it fails the positive one. `IS_NULL` / `NOT_NULL` are the only operators that test presence directly.
**`NOT` is not a binary operator and is not subject to this guard.** `NOT` sits outside the operator it wraps and inverts whatever two-valued answer that operator gives, including a null-guarded non-match: on an entity missing `x`, `NOT($.x EQUALS "A")` **matches** even though both `$.x EQUALS "A"` and `$.x NOT_EQUAL "A"` do not. See `cyoda help search` for the full `NOT` contract.
## LIKE GRAMMAR
`LIKE` is a glob matched directly — not translated into a regular expression, so
no regex metacharacter has any meaning in a `LIKE` operand. Only these three
characters are special:
- `%` — matches any sequence of characters, including empty and including newlines.
- `_` — matches exactly one character (one UTF-8 rune, not one byte), including a newline.
- `\` — escapes the character after it to its literal form. It escapes **any**
character, not only `%`, `_` and `\`: `\a` matches a literal `a`, and `\\`
matches a single backslash.
The match is **whole-string anchored** (the entire stored value must match, not a
substring) and **case-sensitive**. Everything outside the three characters above
is literal text compared bytewise, so an operand carrying invalid UTF-8 matches
the byte-identical stored value rather than being transcoded.
A pattern that ends with an unpaired `\` has nothing to escape and is invalid.
The request is rejected — see VALIDATION below. Use `\\` for a literal trailing
backslash.
## MATCHES_PATTERN
`MATCHES_PATTERN` compiles the operand as a Go RE2 regular expression, whole-string anchored (equivalent to Java's `Pattern.matches`), case-sensitive. RE2 and the Java regex dialect diverge on some constructs (e.g. backreferences, some lookaround); this is an accepted, bounded divergence — not reconciled.
The operand must parse **on its own** as well as compile anchored. Anchoring wraps it as `\A(?:operand)\z`, and that wrapper's own parentheses can rebalance a body whose parens are unmatched: `)|(` would become an alternation matching every stored value. Requiring a standalone parse keeps that family unrepresentable, so an accepted pattern never matches more than it says.
## VALIDATION
Validation is **parse-based**, evaluated at request time against the target model. The codes below are search's; a workflow or transition criterion is validated identically at import and surfaces the same rejections as `400 VALIDATION_FAILED` (see `workflows`).
- `400 CONDITION_TYPE_MISMATCH` — the operand parses into **none** of the field's declared types, or the operator does not apply to the field's type: string and pattern operators require a text field; ordering and range operators require an ordered type (number, text, timestamp). `IS_NULL`/`NOT_NULL` carry no operand-type constraint.
- `400 INVALID_FIELD_PATH` — the field path is unknown to the model, **or** it names a container path with no scalar form: a bare object path, or a `[*]` path over an array whose elements are only ever objects. A scalar operator cannot compare against structure — navigate to a scalar leaf sub-path instead. (A path observed as both a container and a scalar across entities — a field, or an array's elements, holding a plain value on some entities and an object on others — remains searchable via its scalar branch; see `cyoda help search`.) `IS_NULL`/`NOT_NULL` are exempt from the container-path rejection since they test presence, not a value.
- `400 INVALID_CONDITION` — `operatorType` is missing or names no operator in the catalog above, the operand is `null` on a binary/range operator, a range operator's value is not a two-element array, the operand is an object/complex value, or a `LIKE`/`MATCHES_PATTERN` operand is not a valid pattern. Pattern operands are checked against the same derivation the evaluator uses, so anything accepted here evaluates everywhere — on both the sync and async paths, and on every backend. This is the code on every surface that carries a condition, workflow import included — there is no surface where an unknown operator falls through to the coarser `400 BAD_REQUEST`.
## SEE ALSO
- search
- workflows
- errors.CONDITION_TYPE_MISMATCH
- errors.INVALID_FIELD_PATH
- errors.INVALID_CONDITION
## See also
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help errors CONDITION_TYPE_MISMATCH`](/help/errors/condition_type_mismatch/) — Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
- [`cyoda help errors INVALID_FIELD_PATH`](/help/errors/invalid_field_path/) — Three checks emit this code.
- [`cyoda help errors INVALID_CONDITION`](/help/errors/invalid_condition/) — Endpoints that accept a search-style condition in the request body — sync and async search, grouped statistics, and the conditional form of delete-by-model — reject a body whose condition cannot be parsed or is otherwise structurally invalid. The condition type is unrecognised, a nested clause is malformed, the JSON does not match the expected condition envelope, an `operatorType` is not one of the canonical operators, a `LIKE` or `MATCHES_PATTERN` operand is not a valid pattern, a `BETWEEN`/`BETWEEN_INCLUSIVE` operator's value is not a two-element array, a `group` clause's `operator` is not `AND`, `OR`, or `NOT`, or a `NOT` group's `conditions` does not hold exactly one entry (zero, or two or more).
## Raw formats
- [`/help/predicates.json`](/help/predicates.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/predicates.md`](/help/predicates.md) — body only
---
## help/quickstart.md
# cyoda quickstart — minimum invocations
cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memor…
cyoda-go version 0.8.4
# quickstart
## NAME
quickstart — minimum commands to run a cyoda-go server.
## SYNOPSIS
```
cyoda init && cyoda
```
## DESCRIPTION
cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memory`, `sqlite`, and `postgres`; authentication modes are `mock` and `jwt`. All configuration is via environment variables with a `CYODA_` prefix.
The binary starts with no required configuration. Default mode: sqlite storage (enabled by `cyoda init`), mock IAM, REST on port 8080, gRPC on port 9090, admin on port 9091.
## DEFAULTS
Without any environment variables, after `cyoda init`:
- `CYODA_STORAGE_BACKEND` = `memory` (before `cyoda init`; `sqlite` after init writes the user config)
- `CYODA_SQLITE_PATH` = `~/.local/share/cyoda/cyoda.db` (Linux/macOS XDG; `%LocalAppData%\cyoda\cyoda.db` on Windows)
- `CYODA_SQLITE_AUTO_MIGRATE` = `true`
- `CYODA_SQLITE_BUSY_TIMEOUT` = `5s`
- `CYODA_SQLITE_CACHE_SIZE` = `64000` (KiB)
- `CYODA_IAM_MODE` = `mock` (all requests accepted without authentication)
- `CYODA_IAM_MOCK_ROLES` = `ROLE_ADMIN,ROLE_M2M`
- `CYODA_HTTP_PORT` = `8080`
- `CYODA_GRPC_PORT` = `9090`
- `CYODA_ADMIN_PORT` = `9091`
- `CYODA_ADMIN_BIND_ADDRESS` = `127.0.0.1`
- `CYODA_CONTEXT_PATH` = `/api`
- `CYODA_LOG_LEVEL` = `info`
- `CYODA_REQUIRE_JWT` = `false`
- `CYODA_OTEL_ENABLED` = `false`
- `CYODA_CLUSTER_ENABLED` = `false`
- `CYODA_SUPPRESS_BANNER` = `false`
The admin listener binds to `127.0.0.1` by default. `/livez` and `/readyz` are unauthenticated.
**Warning:** mock auth accepts all requests without a token. An instance in mock mode must not be exposed to untrusted networks.
## PRODUCTION CHECKLIST
Env vars required to move from defaults to a production-shaped deployment.
**Storage — switch from sqlite to postgres:**
- `CYODA_STORAGE_BACKEND` = `postgres` (required)
- `CYODA_POSTGRES_URL` = `postgres://user:pass@host:5432/dbname` (required when backend is postgres)
- `CYODA_POSTGRES_URL_FILE` — file path for `CYODA_POSTGRES_URL`; takes precedence over the plain var
- `CYODA_POSTGRES_MAX_CONNS` = `25` (default)
- `CYODA_POSTGRES_MIN_CONNS` = `5` (default)
- `CYODA_POSTGRES_MAX_CONN_IDLE_TIME` = `5m` (default)
- `CYODA_POSTGRES_AUTO_MIGRATE` = `true` (default)
**Auth — switch from mock to JWT:**
- `CYODA_IAM_MODE` = `jwt` (required)
- `CYODA_REQUIRE_JWT` = `true` — refuse startup unless jwt mode and signing key are set
- `CYODA_JWT_SIGNING_KEY` — RSA private key, PEM-encoded (required in jwt mode)
- `CYODA_JWT_SIGNING_KEY_FILE` — file path for `CYODA_JWT_SIGNING_KEY`; takes precedence
- `CYODA_JWT_ISSUER` = `cyoda` (default; set to your issuer URI)
- `CYODA_JWT_AUDIENCE` = `` (default empty; set to require audience claim validation)
- `CYODA_JWT_EXPIRY_SECONDS` = `3600` (default)
**Inter-node dispatch auth (cluster mode):**
- `CYODA_HMAC_SECRET` — hex-encoded HMAC secret for inter-node dispatch authentication
- `CYODA_HMAC_SECRET_FILE` — file path for `CYODA_HMAC_SECRET`; takes precedence
**Bootstrap M2M client (optional):**
- `CYODA_BOOTSTRAP_CLIENT_ID` — M2M client ID to provision at startup
- `CYODA_BOOTSTRAP_CLIENT_SECRET` — M2M client secret (required when client ID is set)
- `CYODA_BOOTSTRAP_CLIENT_SECRET_FILE` — file path for `CYODA_BOOTSTRAP_CLIENT_SECRET`; takes precedence
- `CYODA_BOOTSTRAP_TENANT_ID` = `default-tenant` (default)
- `CYODA_BOOTSTRAP_USER_ID` = `admin` (default)
- `CYODA_BOOTSTRAP_ROLES` = `ROLE_ADMIN,ROLE_M2M` (default)
**Admin metrics auth (optional):**
- `CYODA_METRICS_BEARER` — static bearer token required on `GET /metrics`
- `CYODA_METRICS_REQUIRE_AUTH` = `false` (default; set `true` to enforce metrics auth at startup)
### Generating secrets
**JWT signing key** — RSA private key, PEM-encoded. The binary accepts PKCS#8 (`BEGIN PRIVATE KEY`) and PKCS#1 (`BEGIN RSA PRIVATE KEY`) formats. Only RSA keys are accepted; the signature algorithm is always RS256. Minimum recommended size: 2048 bits.
Generate a PKCS#8 RSA-2048 key (preferred):
```
openssl genpkey -algorithm RSA -pkeyopt rsa_keygen_bits:2048 -out signing.pem
```
Generate a PKCS#1 RSA-2048 key (also accepted):
```
openssl genrsa -out signing.pem 2048
```
Pass to the binary via file reference (recommended):
```
export CYODA_JWT_SIGNING_KEY_FILE=/run/secrets/signing.pem
```
**HMAC secret** — hex-encoded shared secret for inter-node dispatch authentication. The binary decodes the value from hex to raw bytes. Minimum: 32 bytes of entropy (64 hex characters).
Generate a 32-byte secret (64 hex chars):
```
openssl rand -hex 32
```
Pass to the binary via file reference (recommended):
```
# Write the hex string to a file, then:
export CYODA_HMAC_SECRET_FILE=/run/secrets/hmac-secret
```
Or pass inline (dev only — not suitable for production):
```
export CYODA_HMAC_SECRET="$(openssl rand -hex 32)"
```
## EXAMPLES
**First-run default (sqlite + mock auth):**
```
cyoda init
cyoda
```
`cyoda init` writes `~/.config/cyoda/cyoda.env` with `CYODA_STORAGE_BACKEND=sqlite`. Running `cyoda` then loads that file and starts the server on port 8080. No other configuration required.
**Postgres + mock auth:**
```
export CYODA_STORAGE_BACKEND=postgres
export CYODA_POSTGRES_URL=postgres://cyoda:secret@localhost:5432/cyoda
cyoda
```
**Postgres + JWT required (production-shaped):**
```
export CYODA_STORAGE_BACKEND=postgres
export CYODA_POSTGRES_URL_FILE=/run/secrets/postgres-url
export CYODA_IAM_MODE=jwt
export CYODA_REQUIRE_JWT=true
export CYODA_JWT_SIGNING_KEY_FILE=/run/secrets/signing.pem
export CYODA_JWT_ISSUER=https://auth.example.com
export CYODA_JWT_AUDIENCE=cyoda-api
cyoda
```
**Docker (sqlite + mock auth):**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-p 127.0.0.1:9090:9090 \
-p 127.0.0.1:9091:9091 \
-e CYODA_STORAGE_BACKEND=sqlite \
-e CYODA_SQLITE_PATH=/var/lib/cyoda/cyoda.db \
-e CYODA_ADMIN_BIND_ADDRESS=0.0.0.0 \
-v cyoda-data:/var/lib/cyoda \
ghcr.io/cyoda/cyoda:latest
```
The image pre-stages `/var/lib/cyoda` owned by UID 65532. The container runs as non-root (65532:65532). `/livez` and `/readyz` are served on port 9091. Set `CYODA_ADMIN_BIND_ADDRESS=0.0.0.0` so the health endpoint is reachable from outside the container.
**Docker Compose (sqlite + mock auth):**
```
curl -O https://raw.githubusercontent.com/cyoda/cyoda-go/main/deploy/docker/compose.yaml
docker compose up
```
The bundled `compose.yaml` at `deploy/docker/compose.yaml` uses `CYODA_STORAGE_BACKEND=sqlite` and a named volume `cyoda-data` for persistence. For production JWT auth, mount the signing key file and set `CYODA_JWT_SIGNING_KEY_FILE` — do not pass `CYODA_JWT_SIGNING_KEY` inline; multi-line PEM does not survive shell or YAML env-var interpolation. See `run` for the full docker compose JWT configuration.
## SEE ALSO
- cli
- cli.init
- config
- config.database
- config.auth
- run
## See also
- [`cyoda help cli`](/help/cli/) — cyoda is a Go binary that embeds the full platform: API server, schema engine, workflow runner, and storage plugins. Invoked with no subcommand, it starts the server using environment-provided configuration. Subcommands provide operational affordances — `init` for first-run bootstrap, `health` for liveness probes, `migrate` for schema migrations.
- [`cyoda help cli init`](/help/cli/init/) — `cyoda init` is the recommended first step for local desktop use. It writes a minimal user config file that sets `CYODA_STORAGE_BACKEND=sqlite`, enabling persistent local storage without requiring a database server.
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help run`](/help/run/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
## Raw formats
- [`/help/quickstart.json`](/help/quickstart.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/quickstart.md`](/help/quickstart.md) — body only
---
## help/run.md
# run — runtime modes and operational semantics
cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via e…
cyoda-go version 0.8.4
# run
## NAME
run — supported ways to start cyoda-go: binary, Docker, Docker Compose, Kubernetes (Helm), and development scripts.
## SYNOPSIS
```
# Binary (default mode — no flags)
cyoda
# Docker
docker run --rm -p 127.0.0.1:8080:8080 -p 127.0.0.1:9090:9090 -p 127.0.0.1:9091:9091 \
ghcr.io/cyoda/cyoda:latest
# Docker Compose (bundled compose.yaml)
docker compose -f deploy/docker/compose.yaml up
# Helm (Kubernetes)
helm install cyoda ./deploy/helm/cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt
# Dev script (in-memory, mock auth)
./scripts/dev/run-local.sh
```
## DESCRIPTION
cyoda-go is a single-process, multi-tenant REST and gRPC API server. It starts in serving mode when invoked with no subcommand. All configuration is via environment variables with a `CYODA_` prefix. The binary, Docker image, and Helm chart run the same binary; only the environment configuration differs across run modes.
The process binds three TCP listeners concurrently: the REST API (default port 8080), gRPC (default port 9090), and an admin server (default port 9091). The admin server hosts health probes and the Prometheus metrics endpoint. On receiving `SIGINT` or `SIGTERM`, the server drains in-flight HTTP and admin requests within a 10-second deadline, then closes the storage backend and exits.
No systemd unit files ship in the repository. Process supervision (systemd, runit, s6, etc.) is the operator's responsibility when running the binary directly outside of Docker or Kubernetes.
## RUN MODES
### Binary
The prebuilt binary is the canonical artifact. Build from source or download from the GitHub release page.
**Build from source:**
```
go build -o bin/cyoda ./cmd/cyoda
```
**Run (default — in-memory storage, mock auth):**
```
./bin/cyoda
```
**Run with SQLite after init:**
```
cyoda init
cyoda
```
`cyoda init` writes `~/.config/cyoda/cyoda.env` with `CYODA_STORAGE_BACKEND=sqlite`. The binary loads that file via `app.LoadEnvFiles()` at startup.
**Required env vars for postgres + JWT mode:**
```
export CYODA_STORAGE_BACKEND=postgres
export CYODA_POSTGRES_URL=postgres://user:pass@host:5432/dbname
export CYODA_IAM_MODE=jwt
export CYODA_REQUIRE_JWT=true
export CYODA_JWT_SIGNING_KEY_FILE=/run/secrets/signing.pem
cyoda
```
The binary accepts env vars from the process environment, from `.env` files loaded by `CYODA_PROFILES`, and from the user config written by `cyoda init`. The `CYODA_PROFILES` variable selects which `.env` profile files to load from the **current working directory**. For example, `CYODA_PROFILES=postgres,jwt` loads `.env.postgres` then `.env.jwt` from the working directory. The user config at `~/.config/cyoda/cyoda.env` (written by `cyoda init`) is always loaded automatically as a separate step — it is not a profile file.
### Docker
**Image:** `ghcr.io/cyoda/cyoda:latest`
The image uses `gcr.io/distroless/static` as its base. The binary is placed at `/cyoda`. The container runs as UID/GID 65532:65532 (non-root). `/var/lib/cyoda` is pre-staged with ownership 65532:65532 and is the intended mount point for persistent SQLite data.
Exposed ports: `8080` (HTTP), `9090` (gRPC), `9091` (admin).
The entrypoint is `/cyoda` with no default arguments. Subcommands (`init`, `health`, `migrate`) are passed as Docker CMD arguments.
**Minimal run (in-memory + mock auth):**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-p 127.0.0.1:9090:9090 \
-p 127.0.0.1:9091:9091 \
-e CYODA_ADMIN_BIND_ADDRESS=0.0.0.0 \
ghcr.io/cyoda/cyoda:latest
```
`CYODA_ADMIN_BIND_ADDRESS=0.0.0.0` is required when running in Docker so the health probes on port 9091 are reachable from outside the container. Without it, the admin server binds to loopback (127.0.0.1) inside the container and `/livez` and `/readyz` are unreachable.
**SQLite with persistent volume:**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-p 127.0.0.1:9090:9090 \
-p 127.0.0.1:9091:9091 \
-e CYODA_STORAGE_BACKEND=sqlite \
-e CYODA_SQLITE_PATH=/var/lib/cyoda/cyoda.db \
-e CYODA_ADMIN_BIND_ADDRESS=0.0.0.0 \
-v cyoda-data:/var/lib/cyoda \
ghcr.io/cyoda/cyoda:latest
```
**Postgres + JWT (production-shaped):**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-p 127.0.0.1:9090:9090 \
-p 127.0.0.1:9091:9091 \
-e CYODA_STORAGE_BACKEND=postgres \
-e CYODA_POSTGRES_URL=postgres://cyoda:secret@db:5432/cyoda \
-e CYODA_IAM_MODE=jwt \
-e CYODA_REQUIRE_JWT=true \
-e CYODA_JWT_SIGNING_KEY_FILE=/run/secrets/signing.pem \
-v /path/to/signing.pem:/run/secrets/signing.pem:ro \
-e CYODA_ADMIN_BIND_ADDRESS=0.0.0.0 \
ghcr.io/cyoda/cyoda:latest
```
### Docker Compose
The repository ships a bundled compose file at `deploy/docker/compose.yaml`.
**Default compose configuration:**
```yaml
services:
cyoda:
image: ghcr.io/cyoda/cyoda:latest
ports:
- "127.0.0.1:8080:8080"
- "127.0.0.1:9090:9090"
- "127.0.0.1:9091:9091"
environment:
CYODA_STORAGE_BACKEND: sqlite
CYODA_SQLITE_PATH: /var/lib/cyoda/cyoda.db
CYODA_ADMIN_BIND_ADDRESS: 0.0.0.0
volumes:
- cyoda-data:/var/lib/cyoda
healthcheck:
test: ["CMD", "/cyoda", "health"]
interval: 10s
timeout: 3s
start_period: 30s
retries: 3
```
The bundled compose file uses SQLite + mock auth by default. The compose healthcheck calls `cyoda health`, which GETs `/readyz` on the admin port with a 2-second client timeout (see `cmd/cyoda/health.go`).
**Run the bundled compose file:**
```
docker compose -f deploy/docker/compose.yaml up
```
**Enable JWT auth before starting compose (file-mount approach):**
**Do not** pass `CYODA_JWT_SIGNING_KEY` as an inline environment variable through docker compose — multi-line PEM content does not survive shell interpolation or YAML env-var parsing reliably. Always use `CYODA_JWT_SIGNING_KEY_FILE` with a volume mount.
```
# 1. Place the signing key on the host (outside the compose dir if gitignored):
# ./secrets/signing.pem
# 2. docker-compose.yaml snippet (add to the cyoda service):
# volumes:
# - ./secrets/signing.pem:/run/secrets/signing.pem:ro
# environment:
# CYODA_IAM_MODE: jwt
# CYODA_REQUIRE_JWT: "true"
# CYODA_JWT_SIGNING_KEY_FILE: /run/secrets/signing.pem
# CYODA_JWT_ISSUER: https://auth.example.com
# CYODA_JWT_AUDIENCE: cyoda-api
# 3. Launch:
docker compose up
```
**Use a custom image (e.g. a local dev build):**
```
CYODA_IMAGE=ghcr.io/cyoda/cyoda:dev \
docker compose -f deploy/docker/compose.yaml up
```
The compose file reads `${CYODA_IMAGE:-ghcr.io/cyoda/cyoda:latest}` for the image name.
**Adjust start_period for slow environments** (Postgres migrations, cluster mode) by editing the `healthcheck.start_period` field in `deploy/docker/compose.yaml`.
### Kubernetes (Helm)
cyoda-go ships a Helm chart at `deploy/helm/cyoda/`. The chart renders a StatefulSet (with Parallel pod management policy), ClusterIP Service, headless Service for gossip, ConfigMap for non-sensitive env vars, projected-volume Secrets for credentials, and optional Gateway API routes, Ingress, HorizontalPodAutoscaler, PodDisruptionBudget, NetworkPolicy, ServiceAccount, ServiceMonitor, and a pre-upgrade migration Job.
The chart is not yet published to a Helm repository. Install directly from the local path or from a cloned repository. See `helm` for the complete Helm reference.
**Minimal install:**
```
helm install cyoda ./deploy/helm/cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt
```
**Upgrade:**
```
helm upgrade --install cyoda ./deploy/helm/cyoda \
--set postgres.existingSecret=cyoda-pg \
--set jwt.existingSecret=cyoda-jwt
```
### Development Scripts
Developer convenience scripts live under `scripts/dev/`. These are not canonical provisioning artifacts. Canonical artifacts are in `deploy/`.
- `scripts/dev/run-local.sh` — runs `cyoda-go` via `go run ./cmd/cyoda` using the `local` profile (in-memory storage, mock auth). Override with `CYODA_PROFILES=postgres,otel ./scripts/dev/run-local.sh`.
- `scripts/dev/run-docker-dev.sh` — builds the binary from source for the host platform (`linux/amd64` or `linux/arm64`), builds a local Docker image tagged `ghcr.io/cyoda/cyoda:dev`, and runs it via `docker compose -f deploy/docker/compose.yaml up`. Generates a fresh JWT signing key and randomized bootstrap client secret per run. Intended for contributors testing local changes in a container before they land.
**Run with in-memory storage and mock auth (go run):**
```
./scripts/dev/run-local.sh
```
**Run with a custom profile set:**
```
CYODA_PROFILES=postgres,otel ./scripts/dev/run-local.sh
```
**Build and run a local Docker image:**
```
./scripts/dev/run-docker-dev.sh
```
## SIGNALS
- `SIGINT` (Ctrl+C) — triggers graceful shutdown. HTTP and admin servers drain in-flight requests within a 10-second deadline. The storage backend is closed. The process exits with code 0.
- `SIGTERM` — same behavior as `SIGINT`. Kubernetes sends `SIGTERM` when a pod is evicted or deleted.
- `SIGPIPE` — ignored. When the binary is piped through `tee` (e.g. `./bin/cyoda | tee log`) and Ctrl+C kills `tee` first, the broken pipe would cause the binary to exit immediately before the `SIGINT` handler runs. Ignoring `SIGPIPE` lets the write fail silently while the graceful shutdown proceeds. (Source: `cmd/cyoda/main.go`, `signal.Ignore(syscall.SIGPIPE)`.)
A **second** `SIGINT` or `SIGTERM` delivered while the drain is still running forces an immediate exit with code `2`. This is the operator's recourse when a graceful shutdown hangs on a stuck in-flight request or a slow-closing storage pool; nothing is drained or flushed on that path. Only the first signal starts the graceful shutdown, and only a genuine second one forces the hard exit.
Signal handling is established before the listeners start.
## HEALTH PROBES
Both probes are served on `CYODA_ADMIN_PORT` (default `9091`) at `CYODA_ADMIN_BIND_ADDRESS` (default `127.0.0.1`). Both endpoints are unauthenticated — authentication is not applied to `/livez` or `/readyz` regardless of `CYODA_METRICS_BEARER` or `CYODA_METRICS_REQUIRE_AUTH`. These are the deployment probes. `GET /health` on the API listener mirrors the same readiness flag as `/readyz` — `200 {"status":"UP"}` while healthy, `503 {"status":"DOWN"}` after a panic recovered in engine or store work, latched until the node is replaced — but it is for humans and simple scripts, not orchestrators. A panic in one of these probes or in a metrics scrape is contained with a ticket and a `500`, and does not latch: they do no engine work, so a broken probe is no evidence about the node's state.
- `GET /livez` — liveness probe. Returns `200 OK` with body `ok` when the admin server is accepting connections. No business logic check is performed, so a node that has recovered a panic still passes it. Nothing restarts such a node: it stops receiving new client connections through the Service, keeps handling established ones and any work peers forward to it, and waits for an operator to replace it.
- `GET /readyz` — readiness probe. Returns `200 OK` with body `ready`. Returns `503` permanently once the node has recovered a panic — its state is then unverified, so it stops receiving client traffic. The reason is in the server log; the response body stays generic. The admin listener only starts after storage is open and migrations have run, so during startup the probe is refused rather than answered `503`.
The `cyoda health` subcommand calls `/readyz` on the admin port with a 2-second HTTP client timeout and exits 0 on `200 OK`, 1 otherwise. This is the implementation behind Docker's `HEALTHCHECK: CMD /cyoda health` and is valid as a readiness check for any init system.
**Admin bind address in container environments:** set `CYODA_ADMIN_BIND_ADDRESS=0.0.0.0` to make health probes reachable from outside the container. The Kubernetes Helm chart sets this value in its ConfigMap. Without it, `/livez` and `/readyz` are inaccessible from the kubelet or Docker healthcheck daemon.
## SHUTDOWN TIMING
The graceful shutdown deadline is **10 seconds**, applied separately to the HTTP server and the admin server. This value is hardcoded in `cmd/cyoda/main.go`:
```go
shutdownCtx, cancel := context.WithTimeout(context.Background(), 10*time.Second)
```
After both HTTP servers shut down, `app.Close()` is called to release backend resources (database connection pools, cluster membership). There is no separate configurable timeout for `app.Close()` — it runs to completion after the HTTP deadline.
In Kubernetes, the pod `terminationGracePeriodSeconds` (default 30s) must be greater than 10s to allow the HTTP drain to complete before the kubelet sends `SIGKILL`.
## PORT LAYOUT
All ports are configurable via environment variables. The defaults:
- **HTTP REST API** — port `8080`, bind address `0.0.0.0` (all interfaces). Controlled by `CYODA_HTTP_PORT`. All entity, model, workflow, search, and auth endpoints, plus `GET /health` (a health summary for humans and simple scripts — not the deployment probe; see HEALTH PROBES above). Context path prefix: `CYODA_CONTEXT_PATH` (default `/api`).
- **gRPC** — port `9090`, bind address `0.0.0.0` (all interfaces). Controlled by `CYODA_GRPC_PORT`. Externalized-processor streaming (processor and criteria dispatch). The bind expression is `fmt.Sprintf(":%d", cfg.GRPC.Port)` — all interfaces, not loopback.
- **Admin** — port `9091`, bind address `127.0.0.1` (loopback) by default. Controlled by `CYODA_ADMIN_PORT` and `CYODA_ADMIN_BIND_ADDRESS`. Hosts `/livez`, `/readyz`, and `/metrics` — the deployment probes. Set `CYODA_ADMIN_BIND_ADDRESS=0.0.0.0` in Docker/Kubernetes to make probes reachable.
- **Gossip (cluster mode only)** — port `7946` TCP+UDP. Controlled by `CYODA_GOSSIP_ADDR` (default `:7946`). Used by the memberlist gossip protocol for cluster membership and SWIM health checking. Active only when `CYODA_CLUSTER_ENABLED=true`.
## EXAMPLES
**Binary — postgres + JWT, production-shaped:**
```
export CYODA_STORAGE_BACKEND=postgres
export CYODA_POSTGRES_URL_FILE=/run/secrets/postgres-url
export CYODA_IAM_MODE=jwt
export CYODA_REQUIRE_JWT=true
export CYODA_JWT_SIGNING_KEY_FILE=/run/secrets/signing.pem
export CYODA_JWT_ISSUER=https://auth.example.com
export CYODA_JWT_AUDIENCE=cyoda-api
./bin/cyoda
```
**Docker — in-memory + OTel tracing:**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-p 127.0.0.1:9090:9090 \
-p 127.0.0.1:9091:9091 \
-e CYODA_ADMIN_BIND_ADDRESS=0.0.0.0 \
-e CYODA_OTEL_ENABLED=true \
-e OTEL_EXPORTER_OTLP_ENDPOINT=http://host.docker.internal:4318 \
-e OTEL_SERVICE_NAME=cyoda \
ghcr.io/cyoda/cyoda:latest
```
**Docker — suppress banner (CI):**
```
docker run --rm \
-e CYODA_SUPPRESS_BANNER=true \
-e CYODA_ADMIN_BIND_ADDRESS=0.0.0.0 \
ghcr.io/cyoda/cyoda:latest
```
**Check health from outside the container:**
```
curl -s http://localhost:9091/readyz
```
**Binary — check readiness via subcommand:**
```
./bin/cyoda health
echo $? # 0 = ready, 1 = not ready or error
```
**Docker Compose — production JWT (file-mount):**
```
# Mount the PEM file and reference it via CYODA_JWT_SIGNING_KEY_FILE.
# Do not export CYODA_JWT_SIGNING_KEY inline — multi-line PEM does not
# survive shell → docker-compose env interpolation reliably.
# See the Docker Compose section above for the full snippet.
docker compose up
```
## SEE ALSO
- cli
- cli.serve
- cli.init
- cli.health
- quickstart
- helm
- config
- config.database
- config.auth
- telemetry
## See also
- [`cyoda help cli`](/help/cli/) — cyoda is a Go binary that embeds the full platform: API server, schema engine, workflow runner, and storage plugins. Invoked with no subcommand, it starts the server using environment-provided configuration. Subcommands provide operational affordances — `init` for first-run bootstrap, `health` for liveness probes, `migrate` for schema migrations.
- [`cyoda help cli serve`](/help/cli/serve/) — Starting with no subcommand loads configuration from environment variables, validates the IAM mode, and binds the REST, gRPC, and admin listeners. The server is single-process, multi-tenant, and stateful — storage is provided by one of the pluggable backends (`memory`, `sqlite`, or `postgres`); see `cyoda help config` for backend selection.
- [`cyoda help cli init`](/help/cli/init/) — `cyoda init` is the recommended first step for local desktop use. It writes a minimal user config file that sets `CYODA_STORAGE_BACKEND=sqlite`, enabling persistent local storage without requiring a database server.
- [`cyoda help cli health`](/help/cli/health/) — `cyoda health` sends an HTTP GET to `http://127.0.0.1:/readyz` and exits 0 if the server responds with HTTP 200. Any non-200 response or connection error causes exit 1.
- [`cyoda help quickstart`](/help/quickstart/) — cyoda-go is a single-process, multi-tenant REST and gRPC API server backed by a pluggable embedded database management system. Storage backends are `memory`, `sqlite`, and `postgres`; authentication modes are `mock` and `jwt`. All configuration is via environment variables with a `CYODA_` prefix.
- [`cyoda help helm`](/help/helm/) — The chart at `deploy/helm/cyoda` deploys cyoda-go on Kubernetes as a StatefulSet backed by an external PostgreSQL database. The chart requires Kubernetes `>=1.31.0`. Chart version: `0.1.0`. App version: `0.1.0` (synchronized to the binary by the `bump-chart-appversion.yml` CI workflow).
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help config database`](/help/config/database/) — config.database — storage backend selection and per-backend connection settings.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
- [`cyoda help telemetry`](/help/telemetry/) — cyoda-go integrates the OpenTelemetry Go SDK (`go.opentelemetry.io/otel`). The
**metric scrape pipeline is always on**: at startup the binary creates a meter
provider with an OpenTelemetry → Prometheus exporter and serves it at
`:9091/metrics`, regardless of `CYODA_OTEL_ENABLED`. No collector is required to
scrape metrics.
## Raw formats
- [`/help/run.json`](/help/run.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/run.md`](/help/run.md) — body only
---
## help/search.md
# search — entity search API
Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
cyoda-go version 0.8.4
# search
## NAME
search — entity search API: synchronous direct search and asynchronous snapshot search. Entity statistics endpoints (`/api/entity/stats/...`) are documented in the `crud` topic.
## SYNOPSIS
```
POST /api/search/direct/{entityName}/{modelVersion}
POST /api/search/async/{entityName}/{modelVersion}
GET /api/search/async/{jobId}
GET /api/search/async/{jobId}/status
PUT /api/search/async/{jobId}/cancel
```
Context path prefix is `CYODA_CONTEXT_PATH` (default `/api`). All endpoints require `Authorization: Bearer ` except when `CYODA_IAM_MODE=mock`.
## DESCRIPTION
Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
**Synchronous (direct) search**: `POST /search/direct/{entityName}/{modelVersion}`. Executes inline within the HTTP request. The response is an NDJSON stream (`application/x-ndjson`), one entity envelope per line. Search is bounded-or-fail: `limit` caps the matched set rather than paging it — a matched set larger than `limit` returns `400 SEARCH_RESULT_LIMIT`, never a truncated prefix. The default `limit` when omitted is 1000; the maximum is 10000; values below 1 are rejected with `400 BAD_REQUEST`.
**Asynchronous search**: `POST /search/async/{entityName}/{modelVersion}`. Submits a search job and returns a job UUID immediately. The search executes in a background goroutine (or in the plugin's own executor for `SelfExecutingSearchStore` plugins). Results are retrieved by polling status and then fetching pages.
Both modes accept the same `Condition` DSL as the request body. The condition is translated to a plugin-level predicate and pushed down to the backend — including inside an active transaction, where the pushdown is read-your-own-writes correct against the transaction's own uncommitted writes (see `trackingRead` below and `docs/CONSISTENCY.md` §3c). There is no in-memory fallback: a condition that cannot be translated is rejected with `400 INVALID_CONDITION` (or `INVALID_FIELD_PATH` for a path-shaped failure), and every backend implements the pushdown. The pushdown is a narrowing optimization only — the in-process kernel is authoritative for every match decision, so results never diverge by backend.
**Bounding.** The server bounds search *results*, never search *time*. Direct search is
bounded-or-fail on `limit`; async search caps neither duration nor result count. No
backend meters examined rows or applies a scan budget, so a non-indexable condition
forcing a residual scan runs to completion however long it takes.
Time is the caller's to bound, and it has the levers: `timeoutMillis` on direct search
(`408 SEARCH_TIMEOUT`, nothing partial returned), and job cancellation on async, which
takes effect mid-flight. Omitting them means unbounded, by choice. The one server-side
exception is an operator-configured backend ceiling on the async scan
(`CYODA_POSTGRES_SEARCH_STATEMENT_TIMEOUT`, see the `config.database` topic); a job that
hits it fails with a message naming both ways out.
Operator semantics (type-directed comparison, null handling, LIKE/regex grammar, validation) are documented in the `predicates` topic; workflow and transition criteria use the identical predicate semantics (see `workflows`).
## CONDITION DSL
All search requests accept a `Condition` JSON document as the POST body. Conditions are parsed recursively up to a maximum nesting depth of 50. Body size limit: 10 MiB.
**SimpleCondition** — match a single JSON path against a scalar value:
```json
{
"type": "simple",
"jsonPath": "$.category",
"operatorType": "EQUALS",
"value": "physics"
}
```
- `type`: `"simple"`
- `jsonPath`: JSON Path string, `$.` leader **required** (e.g., `"$.year"`, `"$.laureates[0].firstname"`) — see **JSONPath grammar** below
- `operatorType` (also accepted as `operator` or `operation`): operator string (see valid values below)
- `value`: any JSON scalar
**Valid `operatorType` values** (exhaustive): `EQUALS`, `NOT_EQUAL`, `GREATER_THAN`, `GREATER_OR_EQUAL`, `LESS_THAN`, `LESS_OR_EQUAL`, `CONTAINS`, `NOT_CONTAINS`, `STARTS_WITH`, `NOT_STARTS_WITH`, `ENDS_WITH`, `NOT_ENDS_WITH`, `LIKE`, `IS_NULL`, `NOT_NULL`, `BETWEEN`, `BETWEEN_INCLUSIVE`, `MATCHES_PATTERN`, `IEQUALS`, `INOT_EQUAL`, `ICONTAINS`, `INOT_CONTAINS`, `ISTARTS_WITH`, `INOT_STARTS_WITH`, `IENDS_WITH`, `INOT_ENDS_WITH`. `BETWEEN`/`BETWEEN_INCLUSIVE` require `value` to be a two-element array `[low, high]`. Comparison is type-directed and same-type only (a JSON number and a numeric-looking string are treated identically); a missing/null field never matches any binary operator, including the `NOT_*`/`INOT_*` negatives. Full per-operator semantics, LIKE grammar, and validation rules are in the `predicates` topic.
`IS_CHANGED`/`IS_UNCHANGED` are not supported.
**JSONPath grammar.** A condition's `jsonPath` is JSON Path nomenclature, checked at the API boundary before anything executes:
```
jsonPath = "$." segment ( "." segment )*
segment = name subscript*
name = 1*( ALPHA / DIGIT / "_" / "-" ) ; ASCII only
subscript = "[" ( "*" / 1*DIGIT ) "]" ; the digit run must fit a signed 32-bit integer
```
The `$.` leader is **required**. A bare `amount` is not a path and is rejected `400 errors.INVALID_FIELD_PATH` — it is not a tolerated alias for `$.amount`. So are an empty path, an empty or trailing segment (`$..a`, `$.a.`), bracket-quoted property access (`$['x']`, `$.['x']`, `$.a["b"]` — write `$.x`), and any character outside the segment set.
**Well-formed** array subscripts — the wildcard `[*]` or a non-negative index `[0]` — **are** valid and accepted (`$.tags[*].name`, `$.arr[0]`, `$.matrix[*][*]`, `$.orders[*].lines[*].sku`). A positional index pushes into the storage query on a backend that supports it. A wildcard cannot be pushed into a scalar comparison — it addresses a set, not one value — so it is always evaluated by re-checking the candidate rows; results are identical either way, only throughput differs.
`[*]` addresses **every** element, so a leaf on it holds when **some** element satisfies it: `$.tags[*] EQUALS "red"` selects the entities whose `tags` contains `"red"`. It is existential, so nothing matches an empty array — neither `IS_NULL` nor `NOT_NULL` holds on `{"tags": []}`. `[0]` addresses that one element. A trailing `[*]` on an array of **pure objects** is rejected `400 errors.INVALID_FIELD_PATH` under a scalar operator — the element has no scalar form, so navigate to the leaf (`$.items[*].sku`, not `$.items[*]`).
**Multi-branch fields and vacuity.** A field may be declared as more than one shape, and a path is accepted when it is a valid statement for **at least one** declared branch. Per entity the predicate then applies to whichever branch that entity's data actually is; where the path is not a valid statement for that branch the entity simply does not match — that is a non-match, not an error. So for a field declared as string *and* array-of-string, `$.a EQUALS "A"` selects the scalar-shaped entities and `$.a[*] EQUALS "A"` the array-shaped ones, and neither condition is rejected.
An empty array answers the three path forms differently, because each addresses something different. A bare `$.a` addresses the array itself, which exists when it is empty, so `NOT_NULL` is **true**. `$.a[*]` addresses the elements and never the array's own nullness, so over `[]` both `IS_NULL` and `NOT_NULL` are **false** — on a wildcard path the two are complements only where at least one element exists. `$.a[0]` addresses one position, which is absent and therefore null, so `IS_NULL` is **true**. Full addressing, branch and vacuity rules: `docs/cloud-parity/path-grammar.md`.
Every other bracket spelling is rejected `400 errors.INVALID_FIELD_PATH`: unclosed or unmatched (`$.a[`, `$.a[0`, `$.a]`), no field name before it (`$.[0]`), empty (`$.a[]`), negative or signed (`$.a[-1]`, `$.a[+1]`), a slice (`$.a[0:2]`), a union (`$.a[0,1]`), a filter expression (`$.a[?(@.x)]`), whitespace inside (`$.a[ 0]`), or a positional index too large to fit a signed 32-bit integer (`$.a[2147483648]`) — `2147483647` is the largest index accepted, and no entity array is long enough for a larger one to address a real position. The path is scanned to the end, so trailing junk after a valid subscript is caught too (`$.a[0]b`, `$.a[0];DROP`, `$.a[*]..b`). These used to go unvalidated and return `200` with an empty page.
Metadata is not addressed through `jsonPath` at all — a `lifecycle` condition names a meta field directly (see **LifecycleCondition**) and is not subject to this grammar. A *data* path that happens to spell `$._meta.state` is an ordinary dotted path.
The same grammar governs grouped statistics (`groupBy`, aggregation `field`), which additionally rejects array subscripts because a group key must be a single scalar — see the `crud` topic. It also governs workflow and transition `criterion` paths, rejected at workflow import with `400 errors.VALIDATION_FAILED` — see the `workflows` topic.
Operator strings outside this list are rejected with `errors.INVALID_CONDITION` at request time; the error detail includes the canonical list.
**LifecycleCondition** — match entity lifecycle metadata:
```json
{
"type": "lifecycle",
"field": "state",
"operatorType": "EQUALS",
"value": "APPROVED"
}
```
- `type`: `"lifecycle"`
- `field`: `state`, `creationDate`, `lastUpdateTime`, `transitionForLatestSave` (alias `previousTransition`), `transactionId`, `id`
- `operatorType` (also accepted as `operator` or `operation`): operator string — same valid values as for `SimpleCondition`
- `value`: any JSON scalar
`creationDate`/`lastUpdateTime` are temporal: compared chronologically at millisecond resolution. A comparison/range operand (`EQUALS`, `NOT_EQUAL`, `GREATER_THAN`, `LESS_THAN`, `GREATER_OR_EQUAL`, `LESS_OR_EQUAL`, `BETWEEN`, `BETWEEN_INCLUSIVE`) must parse as a temporal value — an offset-bearing RFC3339 instant, or a **coarser** value (`"2024"`, `"2024-09"`, an offset-less date-time) which **upscales** to an instant; only an operand that parses into no temporal form is rejected `400 CONDITION_TYPE_MISMATCH`. String and pattern operators (`CONTAINS`, `LIKE`, `MATCHES_PATTERN`, the case-insensitive family, …) do not apply to these fields and are rejected `400 INVALID_CONDITION` — not a type mismatch, since no operand could make the operator valid here. `IS_NULL`/`NOT_NULL` test presence and carry no type constraint. An unknown meta filter field is rejected `400 INVALID_FIELD_PATH`.
**GroupCondition** — combine conditions with a logical operator:
```json
{
"type": "group",
"operator": "AND",
"conditions": [
{ "type": "simple", "jsonPath": "$.year", "operatorType": "EQUALS", "value": "2024" },
{ "type": "lifecycle", "field": "state", "operatorType": "EQUALS", "value": "NEW" }
]
}
```
- `type`: `"group"`
- `operator`: `"AND"`, `"OR"`, or `"NOT"` — any other string is rejected `400 errors.INVALID_CONDITION` at validation time ("unknown group operator")
- `conditions`: array of `Condition` objects (recursive; maximum nesting depth 50) — for `"AND"`/`"OR"` any number of entries, including zero; for `"NOT"` **exactly one** entry
An `AND` group with an empty `conditions` array evaluates to `true` (vacuous conjunction). An `OR` group with an empty `conditions` array evaluates to `false` (vacuous disjunction).
**`NOT`** inverts its single child's two-valued answer: `NOT(c)` is true exactly when `c` is false. `conditions` with zero entries, or two or more, is rejected `400 errors.INVALID_CONDITION` — a bare list under `NOT` has two defensible readings ("not both" vs. "neither") that disagree on the same data, so the group is written by nesting: `NOT(A AND B)`, not `NOT[A, B]`. `NOT(NOT(x))` is legal and restores `x`'s own answer.
Over a wildcard path `NOT` is a **universal** quantifier, where the leaf underneath it is existential: `NOT($.tags[*] EQUALS "red")` matches when **no** element equals `"red"`, while `$.tags[*] NOT_EQUAL "red"` matches when **some** element differs from `"red"` — for `{"tags":["red","blue"]}` the first is false and the second is true. `NOT` is never rewritten by De Morgan into a leaf's negative twin (`NOT(EQUALS)` is not `NOT_EQUAL`; `NOT(IS_NULL)` is not `NOT_NULL` — see `predicates`), and a `NOT`ted group is never distributed over its children.
`NOT` over an empty list, an explicit `null`, or an absent field is **true**, because the inner leaf is false in all three states — `[*]` is existential and nothing matches an empty array (see above), and a missing/null value never matches any binary operator including the negatives (see `predicates`). On an absent field `NOT($.x EQUALS "A")` matches while both `$.x EQUALS "A"` and `$.x NOT_EQUAL "A"` do not — `NOT` sits outside the operator and inverts a result the operator itself never inverts.
There is no `ALL(P)` ("every element satisfies P") operator, and no sound way to build one from `NOT` over a list that may contain `null`: `NOT(some element satisfies ¬P)` reports "every element satisfies P" for `["red", null]`, which is wrong. Do not use that construction.
A `NOT` anywhere in a condition makes the whole query residual: no backend pushes a `NOT` into its own query language, so a condition containing one is not bounded by a pushed SQL `LIMIT` clause. It is evaluated in memory by the kernel, streaming through the model and stopping once enough matches accumulate to satisfy the request's own `limit`, rather than narrowing in SQL first.
**EMPTY CONDITION**: Submitting an empty body (`{}`) or a body with no `type` field as the top-level search condition is rejected with `errors.BAD_REQUEST` — the parser requires a valid `type` field. Submitting a valid `AND` group with an empty `conditions` array (`{"type":"group","operator":"AND","conditions":[]}`) is accepted and matches all entities — this is the correct way to retrieve all entities without filtering.
**ArrayCondition** — match positional values in a JSON array:
```json
{
"type": "array",
"jsonPath": "$.laureates[*]",
"values": ["John", null, "Hopfield"]
}
```
- `type`: `"array"`
- `jsonPath`: JSON Path to the array's elements, and **must carry a trailing `[*]`** (see **JSONPath grammar** below) — a bare path (`$.laureates`) addresses the array itself, not its elements, and is rejected `400 errors.INVALID_FIELD_PATH`
- `values`: positional values, one per array index in order; a `null` entry tests nothing at that index and is skipped
Each non-null entry is a positional test: `values[i]` compared against element `i`. The clause is read as an `AND` of those positional comparisons — `["John", null, "Hopfield"]` means element 0 equals `"John"` and element 2 equals `"Hopfield"`. `values` made entirely of `null` matches every entity.
**FunctionCondition** — server-side function predicate dispatched to a compute member. **Criteria only — search requests reject it.** Documented here because criteria and search share the one `Condition` DSL; a search, async-search, grouped-stats or conditional-delete body carrying a `function` clause at any depth is rejected `400 INVALID_CONDITION`. Use it in a workflow or transition `criterion` (see `workflows`).
```json
{
"type": "function",
"function": {
"name": "my-criteria-fn",
"config": {
"calculationNodesTags": "approval-service",
"attachEntity": true,
"responseTimeoutMs": 30000
}
}
}
```
- `type`: `"function"`
- `function.name`: string — identifies the function; becomes `criteriaId` / `criteriaName` in the dispatch request; required for routing
- `function.config.calculationNodesTags`: string — comma-separated tags used to select a registered compute member; follows the same tag-intersection rules as processor dispatch
- `function.config.attachEntity`: boolean (optional, default `true`) — when `true`, the full entity payload is included in the dispatch request
- `function.config.responseTimeoutMs`: int64 (optional, default `30000`) — timeout in milliseconds
When used as a criterion, the function is dispatched as `EntityCriteriaCalculationRequest` to the matching compute member — see the `grpc` topic for the request/response shape — and must be the whole criterion; one nested inside a `group` fails the evaluation. Search has no dispatcher: `FunctionCondition` cannot be translated to a storage-plugin pushdown filter and the in-process kernel has no evaluator for it, which is why it is rejected up front rather than attempted.
## ENDPOINTS
**POST /api/search/direct/{entityName}/{modelVersion}** — Synchronous search
- `entityName` (path): string
- `modelVersion` (path): int32
- `pointInTime` (query, optional): RFC 3339 date-time — search against entity state at this instant.
Point-in-time search uses the canonical inclusive (`<=`, no rounding) bound —
see `cyoda help crud` ("Point-in-time semantics").
- `limit` (query, optional): string-encoded integer, minimum 1, maximum 10000; default 1000
- `trackingRead` (query, optional): boolean, default `false`. Only meaningful inside an active transaction (see `crud` topic and `docs/CONSISTENCY.md` §3c for the transactional read-set): when `true`, the entities this search returns are recorded into the transaction's read-set, so a concurrent commit touching any of them aborts with `409 Conflict` at commit time. When `false` (default), the search is a plain snapshot read that records nothing — cheap, but it does not protect the returned rows from concurrent writes, and neither setting protects against phantoms (a new entity matching the predicate after the snapshot was taken). Ignored outside a transaction.
- `timeoutMillis` (query, optional): int64, no default — when absent, the search has no server-side deadline. When present, the search is aborted once it elapses and the request fails `408 errors.SEARCH_TIMEOUT` with no partial results returned. Rejected with `400 BAD_REQUEST` on a non-positive value or on a request that joins an open transaction (a routed compute-node callback cannot impose its own deadline on a transaction it does not own).
Request body: `Condition` JSON document.
Response: `200 OK`, `Content-Type: application/x-ndjson`.
Each line is a complete entity envelope JSON object:
```
{"type":"ENTITY","data":{"category":"physics","year":"2024"},"meta":{"id":"74807f00-ed0d-11ee-a357-ae468cd3ed16","modelKey":{"name":"nobel-prize","version":1},"state":"NEW","creationDate":"2025-08-01T10:00:00.000000000Z","lastUpdateTime":"2025-08-01T10:00:00.000000000Z"}}
{"type":"ENTITY","data":{"category":"chemistry","year":"2023"},"meta":{"id":"89abc100-ed0d-11ee-a357-ae468cd3ed16","modelKey":{"name":"nobel-prize","version":1},"state":"APPROVED","creationDate":"2025-07-15T09:00:00.000000000Z","lastUpdateTime":"2025-07-20T14:00:00.000000000Z"}}
```
The stream is truncated on encode failure after the header has been sent; the client detects truncation via a connection error or incomplete last line.
**POST /api/search/async/{entityName}/{modelVersion}** — Submit async search job
- `entityName` (path): string
- `modelVersion` (path): int32
- `pointInTime` (query, optional): RFC 3339 — if not provided, the current time is captured at submission
Request body: `Condition` JSON document.
Response: `200 OK`, `application/json` — bare UUID string (job ID):
```
"a1b2c3d4-e5f6-11ee-9e63-ae468cd3ed16"
```
The job is stored with status `RUNNING`. For non-`SelfExecutingSearchStore` backends, a goroutine begins the search immediately using a background context derived from the submitting user's tenant context.
Submission is bounded by a fixed-size worker pool (`CYODA_SEARCH_ASYNC_WORKERS`, `CYODA_SEARCH_ASYNC_QUEUE`); once both the running workers and the queue are exhausted, submission fails `503 SEARCH_QUEUE_FULL` (retryable) instead of blocking or spawning an unbounded goroutine per request.
Results stream incrementally as the scan runs rather than being materialized in memory and saved all at once. A running job stamps its own liveness on a fixed cadence (`CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL`, default 15s) starting from the moment it is submitted — including while it is still queued, not only while it is scanning — and the same poll also picks up a cancellation or an externally-recorded terminal status.
If a job's owning node dies without ever reaching a terminal status, a background reaper claims it once its heartbeat has gone silent for `CYODA_SEARCH_JOB_STALE_AFTER` (default 5m, enforced to be at least 4x the heartbeat interval), clears any partial results the dead executor left, and re-runs it on a live node as-at its originally stored `pointInTime` — the job still completes `SUCCESSFUL`. It is `FAILED` (with a generic message) only after `CYODA_SEARCH_JOB_MAX_ATTEMPTS` executor losses (default 3): the status is contractual, the message text is not. A graceful node shutdown or restart releases its in-flight jobs immediately for reclaim rather than waiting for them to go stale, so a planned handoff is prompt. The reaper runs on `CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL`'s ticker (default 15s) plus once at startup — not `CYODA_SEARCH_REAP_INTERVAL`, which drives only the unrelated snapshot-TTL cleanup — so actual detection latency for a crash is up to `CYODA_SEARCH_JOB_STALE_AFTER` + one heartbeat interval (~5m15s at the defaults).
**GET /api/search/async/{jobId}/status** — Get async job status
- `jobId` (path): UUID
Response: `200 OK`, `application/json`:
```json
{
"searchJobStatus": "SUCCESSFUL",
"createTime": "2025-08-01T10:00:00.000000000Z",
"entitiesCount": 42,
"calculationTimeMillis": 145,
"finishTime": "2025-08-01T10:00:00.145000000Z",
"expirationDate": "2025-08-02T10:00:00.000000000Z"
}
```
- `searchJobStatus`: `"RUNNING"`, `"SUCCESSFUL"`, `"FAILED"`, `"CANCELLED"`, or `"NOT_FOUND"` (snapshot expired or not found on commercial backends)
- `createTime`: RFC 3339 with nanoseconds
- `entitiesCount`: total matching entities (0 while running)
- `calculationTimeMillis`: elapsed search time in milliseconds
- `finishTime`: RFC 3339 with nanoseconds; absent when status is `RUNNING`
- `expirationDate`: `createTime + 24h` — job results expire after this time
A job ends `FAILED` when the search itself failed, when the reaper's reclaim of a dead node's job exhausts `CYODA_SEARCH_JOB_MAX_ATTEMPTS`, or when the model's schema becomes unloadable between submit and execution — the executor re-reads the schema, and a job that cannot validate its condition against it fails rather than finishing `SUCCESSFUL` with a short page.
**GET /api/search/async/{jobId}** — Retrieve async job results (paginated)
- `jobId` (path): UUID
- `pageSize` (query, optional): string-encoded integer, default `1000`
- `pageNumber` (query, optional): string-encoded integer, default `0`; offset = `pageNumber * pageSize`
The job must be in `SUCCESSFUL` status. Returns `400 BAD_REQUEST` if the job is not yet complete.
Response: `200 OK`, `application/json`:
```json
{
"content": [
{
"type": "ENTITY",
"data": { "category": "physics", "year": "2024" },
"meta": {
"id": "74807f00-ed0d-11ee-a357-ae468cd3ed16",
"modelKey": {"name": "nobel-prize", "version": 1},
"state": "NEW",
"creationDate": "2025-08-01T10:00:00.000000000Z",
"lastUpdateTime": "2025-08-01T10:00:00.000000000Z"
}
}
],
"page": {
"number": 0,
"size": 1000,
"totalElements": 42,
"totalPages": 1
}
}
```
Results are fetched from the stored entity snapshots at the job's `pointInTime`. Entities deleted or modified after submission are returned as they existed at submission time.
**PUT /api/search/async/{jobId}/cancel** — Cancel a running async job
- `jobId` (path): UUID
Cancellation succeeds only when the job status is `RUNNING`. If the job has already reached a terminal state (`SUCCESSFUL`, `FAILED`, or `CANCELLED`), the server returns `400 Bad Request`:
```json
{
"detail": "snapshot by id= is not running. current status=SUCCESSFUL",
"properties": {
"currentStatus": "SUCCESSFUL",
"snapshotId": ""
},
"status": 400,
"title": "Bad Request",
"type": "about:blank"
}
```
On successful cancellation, response: `200 OK`, `application/json`:
```json
{
"isCancelled": true,
"cancelled": true,
"currentSearchJobStatus": "CANCELLED"
}
```
## SORTING
Both sync and async search accept one or more `sort` query parameters. Repeat the parameter for multi-key sorting; precedence follows declaration order.
**Grammar:** `[@]path[:asc|desc]`
- Direction defaults to `asc` when omitted.
- A leading `$.` on a data path is tolerated and stripped: `$.year:desc` equals `year:desc`.
- Prefix `@` to sort by a meta field: `@creationDate:asc`.
**Meta field allowlist** (only these are accepted with `@`): `state`, `creationDate`, `lastUpdateTime`, `transitionForLatestSave`, `transactionId`, `id`.
**Order semantics:**
- Strings: byte (lexicographic) order.
- Numbers: numeric order.
- Meta dates (`creationDate`, `lastUpdateTime`, `transitionForLatestSave`): chronological; millisecond resolution is the minimum precision enforced cross-engine.
- Absent or null values sort last regardless of direction.
**Tiebreaker:** `entity_id` ascending is always appended as the final key.
**Key cap:** configurable via `CYODA_SEARCH_MAX_SORT_KEYS` (default 16); exceeding the cap returns `errors.INVALID_FIELD_PATH` (`400`), like any other malformed `sort` value.
**Invalid paths:** unsortable, unknown, array, or non-scalar paths return `errors.INVALID_FIELD_PATH` (`400`). A path segment is drawn from `A-Za-z0-9_-`, and an array subscript or projection (`items[*].name`, `items[0].name`) is rejected — an ordering needs a single scalar, and being a recorded field is not enough: a scalar leaf inside an array of objects is one. The gRPC `orderBy.path` is held to the same grammar in the same resolver, so both transports answer a given path identically.
## PAGINATION
Async search results use page-number pagination: `pageNumber=0` is the first page, `offset = pageNumber * pageSize`. `pageNumber` and `pageSize` are both string-encoded integers in query parameters.
Synchronous search neither paginates nor truncates: the matched set must fit within `limit` or the request fails `400 SEARCH_RESULT_LIMIT`. Any result set larger than that — including an ordered top-N over a large model (`sort` plus a small `limit`) — belongs on the async path, which snapshots the full result set and pages over it.
## ERRORS
- `errors.MODEL_NOT_FOUND` — `404` — model not registered for the calling tenant (search, async submit)
- `errors.SEARCH_JOB_NOT_FOUND` — `404` — async job UUID does not exist.
- `errors.SEARCH_JOB_ALREADY_TERMINAL` — `400` — cancel attempted on a job that is already `SUCCESSFUL`, `FAILED`, or `CANCELLED`; body carries `currentStatus` and `snapshotId`
- `errors.SEARCH_RESULT_LIMIT` — `400` — direct search's matched entity count exceeded the requested `limit`; enforced by the backend's bounded-or-fail `Search`. Async search never returns this code — an oversized `pageSize`/`pageNumber` on result retrieval is `errors.BAD_REQUEST` instead
- `errors.SEARCH_TIMEOUT` — `408` — direct search's client-supplied `timeoutMillis` elapsed before the result set was collected; retryable, and nothing partial is returned
- `errors.SEARCH_SHARD_TIMEOUT` — per-shard search timeout exceeded (relevant for distributed backends)
- `errors.SEARCH_QUEUE_FULL` — `503` — async submit refused for capacity: either the node's worker pool and submit queue are both exhausted, or the tenant is at its in-flight share of this node; retryable, tune via `CYODA_SEARCH_ASYNC_WORKERS`/`CYODA_SEARCH_ASYNC_QUEUE`/`CYODA_SEARCH_ASYNC_MAX_PER_TENANT`
- `errors.INVALID_FIELD_PATH` — `400` — a `jsonPath` is not valid JSON Path syntax (missing `$.` leader, bracket-quoted access, empty/trailing segment, disallowed character), or references field paths absent from the model's locked schema, or a `lifecycle` condition names an unknown meta filter field; the response detail names each offending path and why
- `errors.CONDITION_TYPE_MISMATCH` — `400` — condition value type is incompatible with the target field's locked DataType, e.g. an operand that parses into no temporal form on a temporal meta field (`creationDate`/`lastUpdateTime`); a string or pattern operator on one of those fields is `INVALID_CONDITION` instead, see **LifecycleCondition** above
- `errors.INVALID_CONDITION` — `400` — a condition fails a structural or shape check rather than a path or type check: an unknown or missing `operatorType`, a `null`/object/complex operand on a binary or range operator, a malformed `LIKE`/`MATCHES_PATTERN` operand, a string or pattern operator on a temporal meta field, an `array` clause on a bare path or with a badly-shaped `values` entry, or a `function` clause at any depth (criteria only — see `predicates`)
- `errors.BAD_REQUEST` — `400` — malformed condition JSON, invalid limit/pageSize/pageNumber, result retrieval on non-SUCCESSFUL job, unknown async job ID in result retrieval
- `errors.SERVER_ERROR` — `500` — the target model's schema could not be loaded or parsed, so the condition could not be checked against it. The request fails with a ticket id and no result set rather than skipping validation: without declared types, comparison and ordering leaves match nothing, so the answer would be a short page indistinguishable from a complete one. HTTP and gRPC fail alike — over gRPC it is an envelope error, never an empty stream. A condition built only of `lifecycle` clauses needs no schema and is unaffected
## EXAMPLES
**Synchronous search — match by field value:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"type":"simple","jsonPath":"$.category","operatorType":"EQUALS","value":"physics"}' \
"http://localhost:8080/api/search/direct/nobel-prize/1"
```
**Synchronous search — match by lifecycle state:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"type":"lifecycle","field":"state","operatorType":"EQUALS","value":"APPROVED"}' \
"http://localhost:8080/api/search/direct/nobel-prize/1"
```
**Synchronous search — AND group:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"type": "group",
"operator": "AND",
"conditions": [
{"type":"simple","jsonPath":"$.year","operatorType":"EQUALS","value":"2024"},
{"type":"lifecycle","field":"state","operatorType":"EQUALS","value":"NEW"}
]
}' \
"http://localhost:8080/api/search/direct/nobel-prize/1"
```
**Synchronous search at point in time with limit:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"type":"group","operator":"AND","conditions":[]}' \
"http://localhost:8080/api/search/direct/nobel-prize/1?pointInTime=2025-08-01T00:00:00Z&limit=100"
```
**Submit async search:**
```
JOB_ID=$(curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"type":"simple","jsonPath":"$.year","operatorType":"EQUALS","value":"2024"}' \
"http://localhost:8080/api/search/async/nobel-prize/1" | tr -d '"')
```
**Poll async job status:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/search/async/$JOB_ID/status"
```
**Retrieve async results (page 0):**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/search/async/$JOB_ID?pageNumber=0&pageSize=500"
```
**Cancel an async job:**
```
curl -s -X PUT \
-H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/search/async/$JOB_ID/cancel"
```
## SEE ALSO
- crud
- models
- analytics
- predicates
- workflows
- errors.MODEL_NOT_FOUND
- errors.SEARCH_JOB_NOT_FOUND
- errors.SEARCH_JOB_ALREADY_TERMINAL
- errors.SEARCH_RESULT_LIMIT
- errors.SEARCH_SHARD_TIMEOUT
- errors.SEARCH_QUEUE_FULL
- errors.INVALID_FIELD_PATH
- errors.CONDITION_TYPE_MISMATCH
- errors.INVALID_CONDITION
- openapi
## See also
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help analytics`](/help/analytics/) — Cyoda Cloud exposes entity data as Trino SQL tables through a Trino connector. The connector uses the Schema Management REST API to discover table definitions and the WebSocket (STOMP) messaging API to stream entity rows at query time.
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors SEARCH_JOB_NOT_FOUND`](/help/errors/search_job_not_found/) — Polling a search job by ID returns this error when the job ID is unknown or belongs to a different tenant. Jobs are tenant-scoped; a valid job ID from one tenant is not visible to another.
- [`cyoda help errors SEARCH_JOB_ALREADY_TERMINAL`](/help/errors/search_job_already_terminal/) — Search jobs are long-running asynchronous operations. Once a job reaches a terminal state it cannot be cancelled, resumed, or otherwise modified. This error is returned when such an operation is attempted on a finished job — `PUT /search/async/{jobId}/cancel` is the only endpoint that raises it.
- [`cyoda help errors SEARCH_RESULT_LIMIT`](/help/errors/search_result_limit/) — Direct (synchronous) search is bounded-or-fail: `limit` caps the matched result set rather than paging it. When more entities match than the limit allows, the request is rejected — it never returns a truncated prefix, because a partial result would be indistinguishable from a complete one.
- [`cyoda help errors SEARCH_SHARD_TIMEOUT`](/help/errors/search_shard_timeout/) — Distributed search fans out to multiple shards in parallel. If any shard does not return results before the search timeout expires, the job is marked failed and this error is returned. Occurs under high load, during partial cluster degradation, or with expensive queries.
- [`cyoda help errors SEARCH_QUEUE_FULL`](/help/errors/search_queue_full/) — `POST /api/search/async/{entityName}/{modelVersion}` runs on a bounded worker pool: a fixed number of workers drain a fixed-capacity queue. Submission fails fast with this error rather than blocking the request or spawning an unbounded goroutine per submission. The rejected submit leaves nothing behind — no job row, no id to poll.
- [`cyoda help errors INVALID_FIELD_PATH`](/help/errors/invalid_field_path/) — Three checks emit this code.
- [`cyoda help errors CONDITION_TYPE_MISMATCH`](/help/errors/condition_type_mismatch/) — Validation is parse-based: a comparison or range operand is rejected only when it parses into none of the field's declared DataTypes. For example `"abc"` against a DOUBLE field is rejected — it is not a number. A numeric-looking string against a polymorphic `[INTEGER, STRING]` field is accepted (it parses as STRING).
- [`cyoda help errors INVALID_CONDITION`](/help/errors/invalid_condition/) — Endpoints that accept a search-style condition in the request body — sync and async search, grouped statistics, and the conditional form of delete-by-model — reject a body whose condition cannot be parsed or is otherwise structurally invalid. The condition type is unrecognised, a nested clause is malformed, the JSON does not match the expected condition envelope, an `operatorType` is not one of the canonical operators, a `LIKE` or `MATCHES_PATTERN` operand is not a valid pattern, a `BETWEEN`/`BETWEEN_INCLUSIVE` operator's value is not a two-element array, a `group` clause's `operator` is not `AND`, `OR`, or `NOT`, or a `NOT` group's `conditions` does not hold exactly one entry (zero, or two or more).
- [`cyoda help predicates`](/help/predicates/) — predicates — operator catalog and evaluation semantics for the `Condition` DSL used by search (`cyoda help search`) and workflow/transition criteria (`cyoda help workflows`). Both consume the same kernel, so everything here applies identically to both.
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
## Raw formats
- [`/help/search.json`](/help/search.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/search.md`](/help/search.md) — body only
---
## help/telemetry.md
# telemetry — OpenTelemetry emission
cyoda-go integrates the OpenTelemetry Go SDK (`go.opentelemetry.io/otel`). The\n**metric scrape pipeline is always on**: at startup the binary creates a me…
cyoda-go version 0.8.4
# telemetry
## NAME
telemetry — OpenTelemetry trace, metric, and log emission configuration.
## SYNOPSIS
```
CYODA_OTEL_ENABLED=true \
OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 \
OTEL_SERVICE_NAME=cyoda \
cyoda
```
## DESCRIPTION
cyoda-go integrates the OpenTelemetry Go SDK (`go.opentelemetry.io/otel`). The
**metric scrape pipeline is always on**: at startup the binary creates a meter
provider with an OpenTelemetry → Prometheus exporter and serves it at
`:9091/metrics`, regardless of `CYODA_OTEL_ENABLED`. No collector is required to
scrape metrics.
`CYODA_OTEL_ENABLED` (default `false`) additionally enables **OTLP push** — the
OTLP metric and trace exporters and the tracer provider — for environments with
an OTel collector. When it is `false`, tracing is off and nothing is pushed, but
application metrics are still exposed at `/metrics`.
Which application metrics appear:
- **OIDC subsystem metrics** (`oidc_*`) — always exposed when IAM runs in `jwt`
mode (the OIDC subsystem is active).
- **Transaction and dispatch metrics** (`cyoda_tx_*`, `cyoda_dispatch_*`) —
exposed when `CYODA_OTEL_ENABLED=true` (their instrumentation decorators are
enabled with full observability).
- Go runtime and process metrics are always present.
The instrumentation name is `github.com/cyoda-platform/cyoda-go`.
## ENV VARS
**cyoda-specific:**
- `CYODA_OTEL_ENABLED` — `true` to enable OTLP push (the OTLP metric and trace exporters) and the otelhttp/gRPC tracing middleware; `false` (default) leaves tracing off and OTLP disabled, but the Prometheus scrape pipeline and `/metrics` remain active. All standard `OTEL_*` env vars are only read when this is `true`.
- `CYODA_METRICS_BEARER` — static Bearer token required on `GET :9091/metrics`. When empty (default), `/metrics` is unauthenticated. Supports `_FILE` suffix: `CYODA_METRICS_BEARER_FILE=` takes precedence over the plain var.
- `CYODA_METRICS_REQUIRE_AUTH` — `true` to refuse startup when `CYODA_METRICS_BEARER` is unset. Default `false`. The Helm chart sets this to `true` for shared-cluster deployments.
**Standard OTel env vars read by cyoda-go when `CYODA_OTEL_ENABLED=true`:**
- `OTEL_EXPORTER_OTLP_ENDPOINT` — base URL of the OTLP HTTP collector (e.g. `http://localhost:4318`). Applies to both trace and metric exporters unless overridden by signal-specific vars.
- `OTEL_EXPORTER_OTLP_TRACES_ENDPOINT` — OTLP HTTP endpoint for traces. Overrides `OTEL_EXPORTER_OTLP_ENDPOINT` for the trace exporter.
- `OTEL_EXPORTER_OTLP_METRICS_ENDPOINT` — OTLP HTTP endpoint for metrics. Overrides `OTEL_EXPORTER_OTLP_ENDPOINT` for the metric exporter.
- `OTEL_EXPORTER_OTLP_HEADERS` — comma-separated `key=value` headers sent with OTLP requests (e.g. for API key authentication).
- `OTEL_EXPORTER_OTLP_TRACES_HEADERS` — per-signal override of `OTEL_EXPORTER_OTLP_HEADERS` for traces.
- `OTEL_EXPORTER_OTLP_METRICS_HEADERS` — per-signal override of `OTEL_EXPORTER_OTLP_HEADERS` for metrics.
- `OTEL_SERVICE_NAME` — `service.name` resource attribute. Identifies the service in traces and metrics. Default value from the OTel SDK (`unknown_service`) when unset.
- `OTEL_TRACES_SAMPLER` — sampler selection. Supported values: (unset) → `ParentBased(AlwaysSample)` (default); `always_on` → `AlwaysSample` root; `always_off` → `NeverSample` root; `traceidratio` → `TraceIDRatioBased(OTEL_TRACES_SAMPLER_ARG)` root; `parentbased_always_on` → `ParentBased(AlwaysSample)`; `parentbased_always_off` → `ParentBased(NeverSample)`; `parentbased_traceidratio` → `ParentBased(TraceIDRatioBased(OTEL_TRACES_SAMPLER_ARG))`; unknown values → logged as WARN, fallback to `parentbased_always_on`.
- `OTEL_TRACES_SAMPLER_ARG` — ratio for `traceidratio` and `parentbased_traceidratio` samplers. Float in `(0, 1]`. Invalid or out-of-range values: logged as WARN, fallback to `1.0`.
## SIGNALS
**Traces**
Traces are exported via `otlptracehttp`. Spans are created by:
- `otelhttp.NewMiddleware("cyoda")` — wraps the HTTP API handler when `CYODA_OTEL_ENABLED=true`; creates one span per inbound HTTP request.
- `otelgrpc.NewServerHandler()` — installed as a gRPC stats handler when `CYODA_OTEL_ENABLED=true`; creates one span per inbound gRPC RPC.
- `observability.TracingTransactionManager` — decorator around the storage `TransactionManager`; creates spans for `tx.begin`, `tx.commit`, `tx.rollback`, `tx.savepoint`, `tx.rollback_to_savepoint`, `tx.release_savepoint`.
- `observability.TracingExternalProcessingService` — decorator around the processor dispatcher; creates spans for `dispatch.processor` and `dispatch.criteria`.
**Metrics**
Metrics are exported via `otlpmetrichttp` with a periodic reader. The following instruments are registered when `CYODA_OTEL_ENABLED=true` (their instrumentation decorators are active only when OTLP push is enabled):
- `cyoda.tx.duration` — `Float64Histogram`, unit `s` — transaction operation duration; labeled by `op` (`begin`, `commit`, `rollback`)
- `cyoda.tx.active` — `Int64UpDownCounter` — count of active (begun but not committed/rolled-back) transactions
- `cyoda.tx.conflicts` — `Int64Counter` — count of transaction serialization conflicts (commit returning `spi.ErrConflict`)
- `cyoda.dispatch.duration` — `Float64Histogram`, unit `s` — processor/criteria dispatch duration; labeled by `type` (`processor`, `criteria`)
- `cyoda.dispatch.count` — `Int64Counter` — total processor/criteria dispatch calls; labeled by `type` (`processor`, `criteria`)
OIDC subsystem metrics (`oidc_*`) are exposed at `/metrics` whenever IAM runs in `jwt` mode, regardless of `CYODA_OTEL_ENABLED`.
Postgres connection-pool metrics (`cyoda_storage_pool_*`) are Postgres-only — exposed
whenever the Postgres storage plugin is active — and always on, regardless of
`CYODA_OTEL_ENABLED`: pool saturation is the dominant outage mode this instrumentation
guards against, so it does not wait on OTLP push. Every data point carries a `backend`
attribute (`postgres`):
- `cyoda.storage.pool.connections` — `Int64ObservableGauge` — pool connections by state; labeled by `backend` and `state` (`acquired`, `idle`, `constructing`)
- `cyoda.storage.pool.max_connections` — `Int64ObservableGauge` — configured maximum pool size; labeled by `backend`
- `cyoda.storage.pool.acquires` — `Int64ObservableCounter` — successful connection acquires; labeled by `backend`
- `cyoda.storage.pool.empty_acquires` — `Int64ObservableCounter` — acquires that found the pool empty and had to wait; labeled by `backend`
- `cyoda.storage.pool.canceled_acquires` — `Int64ObservableCounter` — acquires cancelled by their context before a connection was available; labeled by `backend`
- `cyoda.storage.pool.acquire_duration` — `Float64ObservableCounter`, unit `s` — cumulative time spent in acquire, all acquires; labeled by `backend`
- `cyoda.storage.pool.empty_acquire_wait` — `Float64ObservableCounter`, unit `s` — cumulative time callers waited because the pool was empty; labeled by `backend`
`cyoda.storage.pool.empty_acquire_wait` is the saturation signal to alarm on — it isolates the time callers spent waiting because the pool was empty; `cyoda.storage.pool.acquire_duration` includes instant acquires alongside it and so dilutes the signal.
**Logs**
cyoda-go uses `log/slog` for structured logging. OTel log emission (OTLP log exporter) is not currently wired. Logs are written to stderr only.
## ATTRIBUTE VOCABULARY
Cyoda-specific span attribute keys defined in `internal/observability/attrs.go`:
- `entity.id` — UUID of the entity being processed
- `entity.model` — model name of the entity
- `entity.state` — current workflow state of the entity
- `tx.id` — transaction UUID
- `op` — operation name within a transaction (`begin`, `commit`, `rollback`, etc.)
- `workflow.name` — name of the workflow definition
- `transition.name` — name of the transition being executed
- `state.from` — workflow state before a transition
- `state.to` — workflow state after a transition
- `cascade.depth` — current depth in the automated-transition cascade loop
- `processor.name` — name of the processor being dispatched
- `processor.execution_mode` — execution mode of the processor (`SYNC`, `ASYNC_SAME_TX`, `ASYNC_NEW_TX`, or `COMMIT_BEFORE_DISPATCH`)
- `processor.tags` — comma-separated `calculationNodesTags` used for member routing
- `criterion.target` — criteria target type (`TRANSITION`, `WORKFLOW`)
- `criteria.matches` — boolean result of a criteria evaluation
- `type` — dispatch type label for `cyoda.dispatch.duration` and `cyoda.dispatch.count` (`processor` or `criteria`)
- `entity.count` — count of entities in a batch operation
- `cql.name` — CQL statement name (Cassandra plugin)
- `cql.op` — CQL operation type (Cassandra plugin)
- `batch.size` — size of a batch operation
- `batch.type` — type of batch
- `version_check.reason` — reason for a version check (cluster protocol)
- `tx.conflict` — boolean; set `true` on `tx.commit` spans when a serialization conflict is recorded
- `tx.savepoint_id` — savepoint identifier on savepoint-related spans
Standard OTel semantic convention attributes set on the resource:
- `service.name` — from `OTEL_SERVICE_NAME`
- `service.instance.id` — from `CYODA_NODE_ID` (set to the gossip node ID in cluster mode; empty string in single-node mode)
## TRACE CONTEXT PROPAGATION
cyoda-go uses **W3C Trace Context** (`traceparent`, `tracestate`) and **W3C Baggage** for context propagation, via `propagation.NewCompositeTextMapPropagator(propagation.TraceContext{}, propagation.Baggage{})` set as the global text map propagator.
**HTTP**: `otelhttp.NewMiddleware` extracts `traceparent` and `tracestate` from inbound HTTP request headers automatically. Outbound requests (inter-node cluster dispatch via `HTTPForwarder`) do not currently inject trace context.
**gRPC**: `otelgrpc.NewServerHandler()` extracts trace context from inbound gRPC metadata automatically.
**Messaging / internal**: `observability.InjectTraceContext(ctx, headers)` writes `traceparent` and `tracestate` into a `map[string]string` carrier. `observability.ExtractTraceContext(baseCtx, headers)` restores the remote span context. Both use the global text map propagator.
## METRICS ENDPOINT
**GET :9091/metrics**
Serves Prometheus-format metrics (text exposition format). The handler is `promhttp.Handler()` from `github.com/prometheus/client_golang`. Port is `CYODA_ADMIN_PORT` (default `9091`); bind address is `CYODA_ADMIN_BIND_ADDRESS` (default `127.0.0.1`).
The handler is backed by a dedicated `prometheus.Registry` that collects from the
OTel SDK meter provider (via the OpenTelemetry → Prometheus bridge), so
application metrics registered through the OTel API appear here automatically.
Go runtime metrics (GC, goroutine count, memory) and process metrics (CPU, open
FDs) are always present. OIDC subsystem metrics (`oidc_*`) appear whenever IAM
runs in `jwt` mode. Transaction and dispatch metrics (`cyoda_tx_*`,
`cyoda_dispatch_*`) appear when `CYODA_OTEL_ENABLED=true`.
## AUTHENTICATION
When `CYODA_METRICS_BEARER` is non-empty, `GET :9091/metrics` requires:
```
Authorization: Bearer
```
The comparison is constant-time to prevent timing attacks. `GET :9091/livez` and `GET :9091/readyz` remain unauthenticated regardless of `CYODA_METRICS_BEARER`.
When `CYODA_METRICS_BEARER` is empty (default), `/metrics` is unauthenticated. This is the expected posture when the admin listener is bound to loopback (`CYODA_ADMIN_BIND_ADDRESS=127.0.0.1`) and access is controlled at the network level.
### Bind-address modes
`CYODA_ADMIN_BIND_ADDRESS` is the outer boundary of the admin listener. Pair it with the bearer-token settings according to the deployment shape:
- **Desktop**: leave `CYODA_ADMIN_BIND_ADDRESS` at its default `127.0.0.1` (loopback only); no bearer needed.
- **Kubernetes**: bind to `0.0.0.0` so kubelet probes and Prometheus reach the pod-facing interface, and enable `CYODA_METRICS_BEARER` (+ `CYODA_METRICS_REQUIRE_AUTH=true`). The Helm chart does both, mounts the token via `_FILE`, and points the `ServiceMonitor` at it via `bearerTokenSecret`.
- **Docker Compose**: keep the default loopback bind inside the container and publish the port as `127.0.0.1:9091:9091` so it is only reachable from the host; no bearer needed.
The `/livez` and `/readyz` probe endpoints stay unauthenticated regardless of bind address, since kubelet probes carry no bearer.
## SAMPLER
The trace sampler is runtime-configurable via:
- `POST :8080/api/admin/trace-sampler` — replaces the sampler atomically; requires `Authorization: Bearer `
- `GET :8080/api/admin/trace-sampler` — returns the current sampler config
Request and response body:
```json
{
"sampler": "ratio",
"ratio": 0.1,
"parent_based": true
}
```
- `sampler` — `"always"`, `"never"`, or `"ratio"`
- `ratio` — float in `(0, 1]`; required and only valid when `sampler="ratio"`
- `parent_based` — boolean; when `true`, the sampler is wrapped with `ParentBased()`
The sampler is backed by `atomic.Pointer[samplerState]`. Reads on the sampling hot path pay no mutex cost. The runtime-replaced sampler takes effect immediately for all new spans.
On startup, `SamplerConfigFromEnv()` is called to seed the sampler from `OTEL_TRACES_SAMPLER` and `OTEL_TRACES_SAMPLER_ARG` before the `TracerProvider` is constructed.
## EXAMPLES
**Start with OTel enabled, exporting to a local OTLP collector:**
```
CYODA_OTEL_ENABLED=true \
OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 \
OTEL_SERVICE_NAME=cyoda-dev \
OTEL_TRACES_SAMPLER=parentbased_traceidratio \
OTEL_TRACES_SAMPLER_ARG=0.1 \
cyoda
```
**Start with OTel enabled via Docker, exporting to Jaeger:**
```
docker run --rm \
-p 127.0.0.1:8080:8080 \
-p 127.0.0.1:9090:9090 \
-p 127.0.0.1:9091:9091 \
-e CYODA_STORAGE_BACKEND=memory \
-e CYODA_OTEL_ENABLED=true \
-e OTEL_EXPORTER_OTLP_ENDPOINT=http://host.docker.internal:4318 \
-e OTEL_SERVICE_NAME=cyoda \
ghcr.io/cyoda/cyoda:latest
```
**Scrape Prometheus metrics from the admin port:**
```
curl -s http://localhost:9091/metrics | grep "^go_"
```
**Scrape metrics with bearer auth:**
```
curl -s \
-H "Authorization: Bearer $CYODA_METRICS_BEARER" \
http://localhost:9091/metrics
```
**Get current sampler configuration:**
```
curl -s \
-H "Authorization: Bearer $TOKEN" \
http://localhost:8080/api/admin/trace-sampler
```
**Set sampler to 10% ratio sampling:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"sampler":"ratio","ratio":0.1,"parent_based":true}' \
http://localhost:8080/api/admin/trace-sampler
```
## SEE ALSO
- config
- cli.serve
- cli.health
- config.auth
## See also
- [`cyoda help config`](/help/config/) — Environment variables beat default values. The `_FILE` suffix variant takes precedence over the plain variable when both are set — for example, `CYODA_POSTGRES_URL_FILE=/etc/secrets/db-url` wins over `CYODA_POSTGRES_URL`. There are no command-line flags for configuration values; env vars are the sole configuration surface.
- [`cyoda help cli serve`](/help/cli/serve/) — Starting with no subcommand loads configuration from environment variables, validates the IAM mode, and binds the REST, gRPC, and admin listeners. The server is single-process, multi-tenant, and stateful — storage is provided by one of the pluggable backends (`memory`, `sqlite`, or `postgres`); see `cyoda help config` for backend selection.
- [`cyoda help cli health`](/help/cli/health/) — `cyoda health` sends an HTTP GET to `http://127.0.0.1:/readyz` and exits 0 if the server responds with HTTP 200. Any non-200 response or connection error causes exit 1.
- [`cyoda help config auth`](/help/config/auth/) — config.auth — IAM mode, JWT issuer, HMAC secret, and admin bootstrap controls.
## Raw formats
- [`/help/telemetry.json`](/help/telemetry.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/telemetry.md`](/help/telemetry.md) — body only
---
## help/topic-tree.md
# cyoda help topic tree
Every flag, env var, endpoint, error, metric, and operation — browsable from the binary. This page is a navigator over the full topic tree, with links into the rendered mirror.
export const byTopLevel = (() => {
const groups = new Map();
for (const t of helpIndex.topics) {
const top = t.path[0];
if (!groups.has(top)) groups.set(top, []);
groups.get(top).push(t);
}
return Array.from(groups.entries()).map(([top, topics]) => {
topics.sort((a, b) => a.path.join('/').localeCompare(b.path.join('/')));
return { top, topics };
});
})();
The cyoda binary is self-documenting. Every flag, environment variable,
endpoint, error code, metric, header, and operation is described by a
**help topic** that ships with the binary. Topics are structured; many
subdivide into drilldowns. The tree is stable across patch releases and
evolves with minor releases.
For each topic listed below, the rendered mirror under
[`/help/`](/help/) carries the same content the binary's `cyoda help`
prints (pinned to v{helpIndex.pinnedVersion}). The binary you run is
the authority for the version you run.
## How to use it
```bash
cyoda help # browse the whole tree
cyoda help # read one topic (e.g. `cyoda help search`)
cyoda help # drill down (e.g. `cyoda help search async`)
cyoda help --format=json # machine-readable
cyoda help --format=markdown # default off-TTY — paste into docs, PRs, chat
```
## The tree
{byTopLevel.map(({ top, topics }) => {
const topUrl = `/help/${top.toLowerCase()}/`;
const topTopic = topics.find(t => t.path.length === 1);
return (
<>
);
})}
{`
.cyoda-help-tree dt {
margin-top: 1.2rem;
font-weight: 600;
}
.cyoda-help-tree dd {
margin-left: 1.5rem;
margin-top: 0.25rem;
}
.cyoda-help-tree dd p {
margin: 0 0 0.4rem 0;
}
.cyoda-help-tree dd ul {
margin: 0.25rem 0 0 0;
padding-left: 1.2rem;
}
.cyoda-help-tree dd li {
margin-block: 0.15rem;
}
.cyoda-help-tree dd code {
font-size: 0.9em;
}
`}
---
## help/workflows.md
# workflows — state machine definitions
A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. …
cyoda-go version 0.8.4
# workflows
## NAME
workflows — workflow state machine definitions: states, transitions, processors, and criteria.
## SYNOPSIS
```
POST /api/model/{entityName}/{modelVersion}/workflow/import
GET /api/model/{entityName}/{modelVersion}/workflow/export
```
Context path prefix is `CYODA_CONTEXT_PATH` (default `/api`). All endpoints require `Authorization: Bearer ` except when `CYODA_IAM_MODE=mock`.
## DESCRIPTION
A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
The engine executes automatically after every entity write. It sets the initial state, evaluates automated transitions (cascade), and invokes processors on each transition. Manual transitions are triggered by the client via `PUT /entity/{format}/{entityId}/{transition}`.
The engine enforces a per-state visit limit of 10 by default (configurable via `WithMaxStateVisits`) and an absolute cascade depth limit of 100 to prevent infinite loops. Static cycle detection runs at import time.
## WORKFLOW SCHEMA
**WorkflowDefinition** (element of the `workflows` array in import):
```json
{
"version": "1.4",
"name": "prize-lifecycle",
"desc": "State machine for Nobel Prize entities",
"initialState": "NEW",
"active": true,
"annotations": { "roles": ["reviewer"], "label": "Prize lifecycle" },
"criterion": null,
"states": {
"NEW": {
"transitions": [
{
"name": "APPROVE",
"next": "APPROVED",
"manual": true,
"annotations": { "ui": { "color": "green" } },
"disabled": false,
"criterion": null,
"processors": [
{
"type": "externalized",
"name": "notify-approval",
"executionMode": "SYNC",
"annotations": { "displayName": "Send approval email" },
"config": {
"attachEntity": true,
"calculationNodesTags": "approval-service",
"responseTimeoutMs": 30000,
"retryPolicy": "",
"context": ""
}
}
]
},
{
"name": "AUTO_VALIDATE",
"next": "VALIDATED",
"manual": false,
"disabled": false,
"criterion": {
"type": "simple",
"jsonPath": "$.year",
"operatorType": "EQUALS",
"value": "2024"
},
"criterionAnnotations": { "displayName": "Year is 2024" },
"processors": []
}
]
},
"APPROVED": {
"transitions": []
},
"VALIDATED": {
"transitions": []
}
}
}
```
**WorkflowDefinition fields:**
- `version` — semver `MAJOR.MINOR` string identifying the workflow-import contract this definition was authored against. Validated strictly on import; stamped to the current contract version on export. See `cyoda help workflows schema-version` for the bump rules and current/supported list.
- `name` — string — unique within the model; the primary key for MERGE mode
- `desc` — string — optional human-readable description. Surfaced in the import audit log line (`workflow import applied` at `INFO`, or `workflow import resulted in zero workflows` at `WARN`) as part of the per-workflow `{name, desc}` digest, and round-tripped via export when non-empty. Use it to record change intent that operators reading logs can correlate without consulting the workflow JSON
- `initialState` — string — state assigned when the entity is first created; must exist in `states`
- `active` — boolean — when `false`, the engine skips this workflow during selection
- `criterion` — `Condition` JSON or `null` — evaluated against the entity at creation to select this workflow; `null` matches all entities
- `states` — object — map of state name → `StateDefinition`
- `annotations` — object or absent — optional client-owned metadata, stored and round-tripped (compacted) but never interpreted by the engine. Must be a JSON object; capped at 64 KB per field. Use for client concerns such as permitted roles, display labels, or UI hints. Two well-known optional keys, `displayName` and `description` (strings), are documented for renderer use (workflow visualisers, condition builders); the engine ignores them and the types are advisory, not enforced. All five workflow element types — workflow, state, transition, processor, and criterion via `criterionAnnotations` — share this same bag shape
- `criterionAnnotations` — object or absent — optional client-owned metadata attached to this workflow's `criterion` as a whole (see `annotations` above); a sibling field rather than embedded in the criterion, so the criterion blob keeps round-tripping byte-verbatim
**StateDefinition:**
- `transitions` — array of `TransitionDefinition` — may be empty
- `annotations` — object or absent — optional client-owned metadata (see WorkflowDefinition `annotations`); object-only, 64 KB cap, engine-opaque
## TRANSITIONS
**TransitionDefinition fields:**
- `name` — string — transition name; used by the client in `PUT /entity/{format}/{entityId}/{name}` and in engine cascade
- `next` — string — target state; must exist in `states`
- `manual` — boolean — `true` means the transition requires an explicit client request; `false` means the engine evaluates it automatically in cascade
- `disabled` — boolean — when `true`, the engine skips this transition entirely
- `criterion` — `Condition` JSON or `null` — evaluated before executing the transition; `null` means always matches; the same Condition DSL as search (see `search` topic)
- `criterionAnnotations` — object or absent — optional client-owned metadata attached to this transition's `criterion` as a whole (see WorkflowDefinition `annotations`); sibling field, engine-opaque
- `processors` — array of `ProcessorDefinition` — invoked sequentially on this transition
- `annotations` — object or absent — optional client-owned metadata (see WorkflowDefinition `annotations`); object-only, 64 KB cap, engine-opaque
## PROCESSORS
A processor may return modified entity data. That data is governed by the model exactly as a client's write is: it must be storable, and it must satisfy the schema. Introducing a field the model does not declare requires the model's `changeLevel` to permit it; otherwise the transition fails with `WORKFLOW_FAILED` and rolls back, leaving neither the entity nor any schema change behind.
**ProcessorDefinition fields:**
- `type` — string — execution-location axis; see below for valid values
- `name` — string — logical processor name
- `executionMode` — string — execution mode; see valid values below
- `config` — `ProcessorConfig`
- `annotations` — object or absent — optional client-owned metadata (see WorkflowDefinition `annotations`); object-only, 64 KB cap, engine-opaque. Excluded from the gRPC `EntityProcessorCalculationRequest` sent to compute members — never delivered to external processor implementations
**Processor `type` (execution-location axis):**
- `"externalized"` (default when omitted) — dispatched via gRPC to a calculation node selected by `Config.calculationNodesTags`. This is the only execution location implemented today; all the `executionMode` semantics below apply to externalized processors.
The engine reserves the value `"internalized"` for an in-process execution location not yet implemented. Any transition that fires a processor with `type: "internalized"` is rejected at dispatch with `WORKFLOW_FAILED` (400) and the operator-visible error `processor X failed: execution type "internalized" is not yet implemented`. The reserved value is intentionally absent from the OpenAPI enum until the subtype lands; workflow authors who include it in import payloads will not be rejected at import, but their entities cannot transit past the affected step.
Any value other than `"internalized"` (including the empty string, the canonical `"externalized"`, and unknown values such as legacy `"scheduled"` or `"EXTERNAL"`) falls through to the `executionMode` dispatch path. This permissiveness will narrow in a future release; do not rely on it.
**Valid `executionMode` values (exhaustive):**
- `"SYNC"` — the engine dispatches the processor and blocks until a response is received; the entity write transaction remains open during the wait; processor failure (including timeout and `success=false` in the response) returns `errors.WORKFLOW_FAILED` (`400`) and the entity remains in the source state
- `"ASYNC_SAME_TX"` — same dispatch mechanics as `SYNC` (blocks inline, transaction stays open); failure semantics are identical to `SYNC`
- `"ASYNC_NEW_TX"` — dispatched within a savepoint; on failure the savepoint is rolled back and the error is logged as a warning; the pipeline continues to the next processor and the transition completes; returned entity modifications are discarded
- `"COMMIT_BEFORE_DISPATCH"` — the engine splits the cascade into two transactions around this processor. `TX_pre` flushes the pre-callout state of the transition and **commits before the processor is dispatched**, releasing the storage connection for the duration of the external compute. The processor runs outside any transaction (entity already durable in the pre-callout state). When the processor returns, the engine opens `TX_post` on the same node, reapplies the result via `CompareAndSave` (CAS expects the txID stamped at `TX_pre`'s commit), runs any subsequent SYNC processors and cascade transitions, then commits. CAS conflict at the boundary surfaces as `409 retryable`; entity remains durable in the pre-callout state, no engine-side retry, no automatic compensation. Failure of the dispatched processor (`success=false`, timeout, member crash) returns `errors.WORKFLOW_FAILED` (`400`) and the entity remains in the pre-callout state. Designed to relieve connection-pool pressure for slow processors and supersedes `ASYNC_NEW_TX` as the recommended mode for slow external work.
**`COMMIT_BEFORE_DISPATCH` configuration flag:**
- `startNewTxOnDispatch` — boolean — sibling field on the same processor object; default `false`; valid only when `executionMode == "COMMIT_BEFORE_DISPATCH"`. Validator rejects `true` for any other mode. When `true`, the engine opens a fresh transaction context (`TX_post`) for the dispatched processor's CRUD callbacks; the processor may use the supplied transaction token to read or write entities other than the cascade-anchor. When `false`, no transaction context is supplied to the dispatched call.
**`COMMIT_BEFORE_DISPATCH` workflow-author requirements:**
- **Idempotency.** A `COMMIT_BEFORE_DISPATCH` processor must be **idempotent or have an external mechanism for detecting prior completion** (e.g., a write-once external resource ID). Replays can fire from two distinct places: (a) CAS conflict during continuation — the caller's retry of the same API call restarts the cascade and re-dispatches the processor; (b) engine crash between segments — the entity is durable in the pre-callout state, the in-flight orchestration is gone, the caller retries, the cascade re-fires from the beginning, the processor is re-dispatched. The engine cannot deduplicate replays; idempotency is the workflow author's responsibility.
- **Visibility of segment-boundary states.** States on a segment boundary (the pre-callout state of a `COMMIT_BEFORE_DISPATCH` processor) are **publicly observable** to readers between segments. A concurrent transaction's `Get`/`GetPage`/`Iterate`/`Search`/`Count` will see the entity in the pre-callout state, and a second cascade may decide to fire criteria-driven transitions based on that observed state. Workflow authors using `COMMIT_BEFORE_DISPATCH` must treat segment-boundary states as committed states — design state-machine criteria, transition guards, and external monitoring accordingly. If invisibility of an intermediate state is required, model it as a workflow-level `DRAFT` parent state with sub-stages in payload, or do not expose the entity until a designated terminal state.
- **Attribution handover with `startNewTxOnDispatch=false`.** With no transaction context supplied, the dispatched processor's callback writes are ordinary independent requests — the platform tracks no causal chain for them. Each is attributed to whatever identity it presents (its own service credentials, or an OBO user token it forwards). The dispatch's AuthContext (`authtype`/`authid`/`authclaims`) carries the causal principal so the application can self-attribute if it wants user-level attribution; the platform supplies no separate carrier for this mode.
- **Best-practice: a processor must not save the entity it is processing for.**
Processors with TX-callback access (SYNC, ASYNC_SAME_TX, COMMIT_BEFORE_DISPATCH
with startNewTxOnDispatch=true) can write the cascade-anchor entity via the
supplied transaction token, but if they do AND also return mutations for the
same entity in their result, the engine's apply-result will overwrite the
processor's intra-TX writes (last-writer-wins inside the transaction buffer).
Pick one path: let the engine apply the result, OR have the processor write
the entity itself and return no mutations for it.
Import-time validation rejects any `executionMode` value not in the list above (and not empty) with `400 VALIDATION_FAILED`. The empty string continues to default to `SYNC` at engine fire.
**ProcessorConfig fields:**
- `attachEntity` — boolean, optional, default `true` — when `true`, the full entity payload is sent to the processor; set `false` to omit it
- `calculationNodesTags` — string — comma-separated tags for routing to registered calculation nodes; the engine selects a node that declares all required tags; returns `errors.NO_COMPUTE_MEMBER_FOR_TAG` if no node matches
- `responseTimeoutMs` — int64 — timeout in milliseconds for `SYNC` processor response; `0` means use node default
- `retryPolicy` — string — selects the server-resolved retry strategy.
Valid values: `NONE` (single attempt, no retry), `FIXED` (up to N
additional attempts with fixed delay between tries, where N and delay
are server-configured). When omitted, defaults to `FIXED` at engine
fire. Import-time validation rejects any other value with `400
VALIDATION_FAILED`. **cyoda-go status:** captured but not consumed —
the dispatcher is single-shot regardless of policy; the full retry
loop ships in a later release. Cloud honours both policies.
- `context` — string — pass-through string forwarded **verbatim** as the `parameters` JSON node of the outgoing `EntityProcessorCalculationRequest` (and `EntityCriteriaCalculationRequest` when used on a `function`-typed criterion's `config`). Marshalling shape is **pass-as-string**: the value is encoded as a JSON string, not parsed as JSON. The receiver gets a JSON-quoted string in `parameters`. Empty `context` causes `parameters` to be omitted entirely. Use to distinguish multiple workflow roles served by a single externalized processor or criterion implementation without registering a separate name per role.
- `asyncResult` — boolean (pointer; nil-default) — declared in the
OpenAPI for Cloud parity; the runtime does **not** implement
async-result semantics on this backend. Imports that set
`asyncResult: true` are rejected with `400 VALIDATION_FAILED`. The
explicit `asyncResult: false` and absent cases are accepted and
round-tripped.
- `crossoverToAsyncMs` — int64 (pointer; nil-default) — crossover
delay (ms) for the async-result semantic; declared in the OpenAPI
for Cloud parity; the runtime does **not** implement it. Imports
that set any non-nil value are rejected with `400 VALIDATION_FAILED`,
including the orphan case where `asyncResult` is absent or false.
## SCHEDULED TRANSITIONS
A transition may carry an optional `schedule` object, marking it as
**scheduled**: rather than being fired by an API call or by automated
cascade, it fires on its own at a computed **scheduled time**. How that
time is determined is chosen per transition, in one of two mutually
exclusive ways:
- **`delayMs`** — a static delay, the same for every entity.
- **`function`** — a per-entity Function callout that computes the
firing time (and optionally an expiry) from the entity itself.
Exactly one of `delayMs` / `function` is required whenever `schedule` is
present, and both are mutually exclusive with `manual: true`. The two
modes differ *only* in how the scheduled time (and expiry) are
determined; everything under **Engine behaviour** below applies to a
scheduled transition either way.
**Static timing — `delayMs`.** The transition fires at
`scheduledTime = stateEntryTime + delayMs`:
```json
{
"name": "AutoClose",
"next": "Closed",
"manual": false,
"schedule": {
"delayMs": 86400000,
"timeoutMs": 600000
}
}
```
- `delayMs` (integer) — delay between source-state entry and the
scheduled time, in milliseconds. Must be `> 0`.
- `timeoutMs` (integer, optional) — late-tolerance window past the
scheduled time (see **Lateness / expiry** below). Absent means no
timeout; explicit `0` is strictest (drop on any lateness). Independent
of `delayMs` — the two measure different quantities.
**Per-entity timing — `function`.** The transition computes its firing
time (and optional expiry) per entity via a Function callout — the same
dispatch mechanism as an externalized processor or a `function`-type
criterion, but returning a typed `Schedule` result instead of an entity
payload or a boolean:
```json
{
"name": "Escalate",
"next": "Escalated",
"manual": false,
"schedule": {
"function": {
"name": "compute-escalation-time",
"resultKind": "Schedule",
"calculationNodesTags": "escalation-service",
"attachEntity": true
}
}
}
```
- `name` (string, required) — registered function name.
- `resultKind` (string, required) — must be `"Schedule"`.
- `calculationNodesTags` (string, required) — comma-separated tags
selecting the dispatch target, same as a processor or criterion.
- `attachEntity` (boolean, optional, default `true`) — whether the
entity payload is attached to the request.
- `context` (string, optional) — pass-through string forwarded verbatim
as the request's `parameters`; omitted when empty.
- `responseTimeoutMs` (integer, optional) — response timeout for this
callout.
The function responds with `resultKind: "Schedule"` and a `result`
object giving the fire time and, optionally, an expiry:
```json
{ "fireAfterMs": 3600000, "expireAfterMs": 600000 }
```
- **Fire time** (required) — exactly one of `fireAt` (absolute,
epoch-ms) or `fireAfterMs` (relative to arm time). A past `fireAt` (or
non-positive `fireAfterMs`) is not an error — the transition is due
immediately.
- **Expiry** (optional) — at most one of `expireAt` (absolute) or
`expireAfterMs` (relative to the *resolved fire time*, not arm time).
Both absent means no expiry (equivalent to an absent `timeoutMs`). A
resolved expiry *after* the fire time becomes the `timeoutMs`
late-tolerance window — the gap between the two. A resolved expiry *at
or before* the fire time is **born expired**: the transition is not
armed, any existing scheduling for it is cancelled
(`SCHEDULED_TRANSITION_EXPIRE`), and the triggering write still
succeeds.
*Fail-closed.* The callout runs synchronously inside the entity-write
transaction (see **Arming** below), so a callout failure fails that
write. If the compute node is unreachable, disconnected, or times out,
the write fails as a retryable `503` with the same dispatch error codes
as a processor or criterion (`NO_COMPUTE_MEMBER_FOR_TAG`,
`DISPATCH_TIMEOUT`, `COMPUTE_MEMBER_DISCONNECTED`) — no state change
commits against an unschedulable transition. A structurally valid
response with the wrong `resultKind`, or a malformed `Schedule` value,
fails with `500 SCHEDULE_FUNCTION_INVALID_RESULT` (see that error topic).
**Import-time validation.**
- Exactly one of `schedule.delayMs` / `schedule.function` must be
present (`VALIDATION_FAILED`).
- `schedule` and `manual: true` are mutually exclusive
(`VALIDATION_FAILED`).
- Static mode: `delayMs <= 0` is rejected (`VALIDATION_FAILED`);
`timeoutMs` need only be `>= 0`.
- Function mode: `name` and `calculationNodesTags` must be non-empty,
and `resultKind` must be `"Schedule"` (`VALIDATION_FAILED`).
**Engine behaviour (applies to both timing modes).** A scheduled
transition is driven by a background scheduler, independently of cascade
evaluation and of any other API call touching the entity.
- **Arming.** On every write that leaves the entity in the transition's
source state — the initial entry AND every subsequent settled write
(an ordinary in-place data update or a self-loop) — the transition is
(re-)armed with a freshly computed scheduled time. Static mode sets it
to `now + delayMs`; function mode **invokes the callout**
synchronously, inside that write's transaction, and each call fully
replaces the previous scheduling decision.
- **Settled-interval reset.** Because arming happens on *every* settled
write, an entity written more often than its scheduled interval never
reaches the fire. Authors relying on "escalate N after entry"
semantics must account for this: routine touch-writes on a busy entity
postpone the fire indefinitely (and, in function mode, make a callout
on each such write).
- **Firing.** When the scheduled time is due, the engine re-evaluates
the transition's criterion exactly **once**. A `true` (or absent)
criterion fires the transition normally (processors run, state
advances, `TRANSITION_MAKE` is recorded). A `false` criterion
**declines** the transition — the entity stays in its current state
and the timer is **not** retried (`TRANSITION_NOT_MATCH_CRITERION`).
See "One-shot vs. polling" below for how to model a retry.
- **Lateness / expiry (`timeoutMs`).** `timeoutMs` — set directly on a
static schedule, or derived from a function schedule's expiry — bounds
how late the scheduler may pick up a due timer before giving up: if it
is picked up more than `timeoutMs` past the scheduled time, it is
**dropped** without evaluating the criterion (`Expired`) — the
transition never fires and the entity stays put. No `timeoutMs` (no
expiry) means no upper bound: the timer fires whenever it is
eventually picked up.
- **Explicitly firing a scheduled transition by name still returns**
HTTP 400 `TRANSITION_NOT_FOUND`, with the message `transition "X"
in state "Y" is scheduled and fires automatically; it is not
manually fireable`. Same code returned when a transition is
`disabled: true` — same semantic: "the transition exists but is not
currently dispatchable from the caller's POV." The entity remains
in the source state. To allow early firing, give the state an
ordinary manual transition alongside the scheduled one.
- **Audit trail.** Arming, firing, expiry, and cancellation each emit a
dedicated event: `SCHEDULED_TRANSITION_ARM`, `SCHEDULED_TRANSITION_FIRE`
(alongside the ordinary `TRANSITION_MAKE`), `SCHEDULED_TRANSITION_EXPIRE`,
`SCHEDULED_TRANSITION_CANCEL`. A loopback that re-arms the same state
emits only `ARM`, not `CANCEL`. `CANCEL` has two causes: the entity left
the source state before the timer fired, or the task came due and the
workflow now selected for the entity does not declare it as a scheduled
transition of that state (see *Workflow-level selection*). A task that is
both obsolete and past its `timeoutMs` grace band records `EXPIRE`, not
`CANCEL` — expiry is decided from the stored task and the clock alone,
before the workflow is consulted.
**One-shot vs. polling.** The criterion is evaluated once per fire —
there is no built-in retry-until-true. Three shapes cover the common
cases:
- **Unconditional scheduled cycle** (`S1 →scheduled→ S2 →scheduled→
S1`, no criteria) — an intentional recurring heartbeat: it fires
every `delayMs`, forever, for every entity in the cycle. Requires
`allowCycles: true` at import (below).
- **Conditional scheduled transition** (a criterion on the scheduled
transition) — a one-shot deadline gate: "at the deadline, fire iff
the condition holds, else abandon." A `false` criterion is a
deliberate Decline, not a retry.
- **Poll-until-condition** — model it as an *unconditional* scheduled
tick into a state whose **ordinary** (non-scheduled) transitions
carry the condition and exit when it holds. The retry loop lives in
normal workflow structure, not in the timer.
**Importing cyclic scheduled workflows.** A canonical scheduled-
transition use case is a polling pattern such as `S1 →scheduled→ S2
→scheduled→ S1`. The import-time cycle detector rejects unguarded
automated cycles by default — including this one, because a delayed
cycle is still a cycle. To import such a workflow, set the request-
level field `allowCycles: true` on the import body:
```json
{
"importMode": "REPLACE",
"allowCycles": true,
"workflows": [ /* ... */ ]
}
```
`allowCycles: true` bypasses only the cycle-detection check. Schedule
shape rules (the `delayMs`/`function` XOR, `manual`+`schedule`
exclusion) and all other validators remain unconditional. The runtime
cascade-depth and per-state visit caps still catch actual runaway at
fire time. Use only for workflows whose cyclicity is intentional.
## CRITERIA
Criteria on workflows and transitions use the same `Condition` DSL as search — five condition types are supported: `simple`, `lifecycle`, `group`, `array`, `function`. All but `function` are evaluated in-memory against the entity's JSON payload and lifecycle metadata; a `function` criterion is dispatched to a compute member and must be the whole criterion — one nested inside a `group` fails the evaluation. See `cyoda help search` for the per-type JSON shapes.
`simple` and `array` criteria address entity data fields by `jsonPath`, under the same grammar a search condition obeys — the `$.` leader is required, and a path outside it is rejected at **import** with `400 VALIDATION_FAILED` rather than at every later evaluation. Write `$.amount`, not `amount`. **Well-formed** array subscripts — the wildcard `[*]` or a non-negative index `[0]` — are valid (`$.tags[*].name`, `$.arr[0]`): criteria are evaluated in memory, which resolves them. A path ending in `[*]` addresses every element, so the criterion fires when **some** element satisfies it (`$.arr[*] GREATER_THAN 50`), and never on an empty array. Any other bracket spelling (`$.a[-1]`, `$.a[0:2]`, `$.a[?(@.x)]`, `$.a[`, `$.a[0]b`) is malformed and is rejected at import with the same `400 VALIDATION_FAILED` — previously it imported cleanly and the criterion then silently never fired, because no evaluator resolves those spellings. See `cyoda help search` for the grammar.
**Import checks the path's grammar, not whether the model declares it.** A model may legitimately be declared after the workflow that references it, so a criterion naming a field the model does not yet declare imports cleanly. The model check happens instead when the criterion is **evaluated**: a query never executes against a field the model does not declare, so if the field is still undeclared at evaluation time, the save that triggered the evaluation is **aborted and rolled back** with `400 WORKFLOW_FAILED` — no entity write, no state transition, no partial effect. This applies to all 26 operators, not only the ones that need a declared type. A field that no entity has ever written must be declared explicitly through `POST /model/import/...`; the model does not grow from a criterion alone. See `errors.WORKFLOW_FAILED` and `docs/cloud-parity/unevaluable-criterion-fails-save.md`.
`group` criteria combine conditions with `AND`, `OR`, or `NOT`. `NOT` takes **exactly one** child condition (`NOT(A AND B)` is written by nesting, not as a two-entry list); zero entries or two-or-more is rejected at import with `400 VALIDATION_FAILED`. Over a wildcard path `NOT` is a universal quantifier where the leaf beneath it is existential — `NOT($.tags[*] EQUALS "red")` fires when no element equals `"red"`, a different question from `$.tags[*] NOT_EQUAL "red"` (some element differs) — and `NOT` over an empty list, an explicit `null`, or an absent field fires, because the inner leaf is false. See `cyoda help search` for the full contract.
`lifecycle` criteria match entity metadata fields: `state`, `creationDate`, `lastUpdateTime`, `transitionForLatestSave` (alias `previousTransition`), `transactionId`, `id`. `creationDate` and `lastUpdateTime` are temporal — compared chronologically, exactly as in search.
A `null` criterion on a workflow means the workflow matches any entity. A `null` criterion on a transition means the transition always fires (automated) or is always available (manual). When multiple automated transitions are eligible, the engine selects the first one by declaration order whose criterion matches. A `null` criterion matches unconditionally, so a `null`-criterion automated transition must be the last automated transition in declaration order; any automated transitions declared after a `null`-criterion transition are unreachable.
### Workflow-level selection
When a model has more than one imported workflow definition, the engine picks the workflow per entity at execution time using these rules — applied in order on **every** door onto the engine, with no caching across calls: entity creation, a named transition, a loopback re-evaluation, a scheduled transition firing, and `GET /entity/{entityId}/transitions`:
1. Iterate workflows in their stored declaration order. (Storage preserves the order from the most recent import; MERGE inserts new workflows at the tail.)
2. Skip any workflow whose `active` flag is `false`. Inactive workflows are invisible to selection, regardless of their criterion.
3. For each active workflow, evaluate `criterion` against the entity payload and lifecycle metadata. A `null` (absent) criterion matches unconditionally — the workflow is selected immediately.
4. The first active workflow whose criterion matches is selected. Subsequent workflows in the array are not consulted.
5. If no active workflow matches — which includes the case where every active workflow has a criterion and none of them passes — the engine falls back to the embedded **default workflow**. The substitution surfaces on two channels: a body warning via `AddWarning` and an operator-visible `slog.Warn` line (`reason=no_criterion_matched`).
Place a `null`-criterion (or otherwise unconditional) workflow last in the import array if you want it to act as a catch-all. Any active workflows declared after it are unreachable for the same reason an unguarded automated transition shadows successors at the transition level.
Workflow-level selection is independent of transition-level selection: once a workflow is chosen, the engine then applies the transition-evaluation rules above against that workflow's `states` map.
Because selection is re-evaluated per call, editing an entity's payload can re-bind it to a different definition. If its current state is not declared in the newly selected workflow, the engine does **not** fall through to another definition that happens to declare it: a named transition is rejected with `400 WORKFLOW_FAILED`, and a loopback settles as a no-op.
A pending scheduled task the newly selected workflow no longer declares as a scheduled transition of that state is **not** cancelled by the write that caused the re-bind: cancellation on re-arm only removes tasks for a state the entity has left, and this one names the state the entity is still in. The task is discarded when it next comes due — the fire door re-resolves the workflow, finds no such scheduled transition, deletes the row and records `SCHEDULED_TRANSITION_CANCEL`. Nothing wrong fires in the meantime, but a timer retired this way is reported at its scheduled time, not at the write, and is attributed to the system principal.
Two consequences worth designing for:
- **Select on fields the caller cannot rewrite.** The criterion is evaluated against the payload of the request being served, so a criterion over a client-writable field lets one request choose which definition's guards apply to itself. Where definitions differ in what they permit, select on immutable fields or on lifecycle metadata.
- **Select on something that stays true for the entity's whole lifetime.** A criterion over a field that changes mid-flow can strand an entity in a state its new definition does not declare, and can silently retire a scheduled transition that was acting as a time-based control.
Selection is audited: each skipped workflow records a `WORKFLOW_SKIP` event (with the criterion's rejection reason) and the chosen one a `WORKFLOW_FOUND` event, under the transaction driving the call. `GET /entity/{entityId}/transitions` is a pure read and records nothing.
## IMPORT REQUEST
**POST /api/model/{entityName}/{modelVersion}/workflow/import**
- `entityName` (path): string
- `modelVersion` (path): int32
Request body (`application/json`):
```json
{
"importMode": "MERGE",
"workflows": [
{ ...WorkflowDefinition... }
]
}
```
- `importMode` — `"MERGE"` (default): incoming workflows overwrite existing ones by name; existing workflows not in the import are preserved. `"REPLACE"`: all existing workflows are discarded; only the incoming set is stored. `"ACTIVATE"`: incoming workflows replace same-named existing ones; existing workflows not in the import set are kept but flipped `active=false`. `REPLACE` / `ACTIVATE` reject an empty `workflows` array (or a missing `workflows` key) with `400 VALIDATION_FAILED` — once a model has imported workflows it always carries ≥1; the built-in default workflow is only used when no workflow has ever been imported. `MERGE` with an empty `workflows` array is allowed as a no-op. The field defaults to `MERGE` when omitted or empty. Parsing is **case-insensitive**: `"merge"`, `"Merge"`, and `"MERGE"` are equivalent. Any value outside the documented enum (after case-folding) is rejected with `400 BAD_REQUEST`.
- `workflows` — array of `WorkflowDefinition`. The `active` flag on each incoming workflow is preserved as supplied; the server never overrides it. If the field is absent (or explicitly `null`), it defaults to `true`. Controlling which workflows are active is entirely up to the importer.
Static validation runs on the incoming request before saving. Any of the following returns `400 VALIDATION_FAILED` with the offending workflow / state / transition named in `detail`:
- Definite infinite loops — cycles reachable only via unguarded automated transitions.
- Empty workflow `name`, or two workflows in the same request sharing a `name`.
- Empty `initialState`, or `initialState` not declared in `states`.
- Empty state-map key (i.e. `"states": { "": { … } }`).
- Empty or duplicate transition `name` within a single state.
- Empty processor `name`.
- Workflow / state / transition / processor names longer than 256 characters.
- Transition `next` not declared in `states`.
- Unknown `executionMode` value on any processor (allowed: `SYNC`, `ASYNC_SAME_TX`, `ASYNC_NEW_TX`, `COMMIT_BEFORE_DISPATCH`, or empty).
- Unknown `retryPolicy` value on any processor (allowed: `NONE`, `FIXED`, or empty).
- `startNewTxOnDispatch=true` on a processor whose `executionMode` is not `COMMIT_BEFORE_DISPATCH`.
- Empty `workflows` array (or a missing `workflows` key) when `importMode` is `REPLACE` or `ACTIVATE`. `MERGE` with an empty array is a legitimate no-op.
- A criterion `jsonPath` (on a `simple` or `array` clause, at any nesting depth) that is not JSON Path — see CRITERIA below.
- A criterion `LIKE` or `MATCHES_PATTERN` value that is not a valid pattern.
- A criterion `lifecycle` clause naming an unknown metadata field, or comparing a temporal field (`creationDate`, `lastUpdateTime`) against a non-timestamp operand.
- A criterion `group` clause whose `operator` is not `AND`, `OR`, or `NOT`, or whose `operator` is `NOT` with `conditions` other than exactly one entry.
The new structural rules (state graph, name uniqueness, `executionMode` enum, `retryPolicy` enum) run on the incoming request only — existing stored workflows are not retroactively re-checked against them. The cycle-detection and `startNewTxOnDispatch` coherence checks continue to run against the merged result, so a legacy stored cycle or incoherent flag still surfaces at any subsequent import.
Response: `200 OK`, `application/json`:
```json
{"success": true}
```
### Audit log on success
Every successful import emits a single structured `log/slog` line so operators can correlate workflow-config changes in their log pipeline.
- **Normal path** — `level=INFO`, `msg="workflow import applied"`. Fields: `pkg=workflow`, `tenant`, `entityName`, `modelVersion`, `importMode`, `workflowCount` (size of THIS call's incoming payload), `storedWorkflowCount` (model's post-merge total), `workflows` (array of `{name, desc}` reflecting the incoming payload — the audit subject is what was applied, not the resulting model state).
- **Zero-result canary** — `level=WARN`, `msg="workflow import resulted in zero workflows"`, same field shape. After `REPLACE` / `ACTIVATE` empty became a `400 VALIDATION_FAILED` (see above), the only reachable path is a `MERGE` with an empty `workflows` array against a model that has no prior workflows. The model will then silently fall back to the embedded default on the next entity execution; this canary surfaces that outcome before it shows up in entity-execution logs.
The `desc` field on each workflow is surfaced in the audit log digest, truncated to 200 characters with a `...` suffix when longer — set a meaningful description to record change intent that log readers can correlate without consulting the workflow JSON.
## EXPORT RESPONSE
**GET /api/model/{entityName}/{modelVersion}/workflow/export**
Response: `200 OK`, `application/json`:
```json
{
"entityName": "nobel-prize",
"modelVersion": 1,
"workflows": [
{ ...WorkflowDefinition... }
]
}
```
Returns `404 WORKFLOW_NOT_FOUND` when no workflows have been imported for the model.
**Export field omission:** The export response omits optional fields that were not explicitly set or are default values. Specifically, `TransitionDefinition` objects in the export may omit `disabled` (when `false`) and `processors` (when empty). States with no transitions are serialised as `{}` rather than `{"transitions":[]}`. The `desc` field on `WorkflowDefinition` is omitted when empty. `annotations` (on the workflow, any state, any transition, or any processor) and `criterionAnnotations` (on the workflow or any transition) are omitted when absent, and re-serialised in compacted form when present.
## ENGINE EXECUTION
The workflow engine runs synchronously within the entity write transaction. The execution sequence for a CREATE:
1. Load workflow definitions for the model.
2. Evaluate each workflow's `criterion` against the entity; select the first match. If none match (or if no workflows have been imported for the model), use the built-in default workflow. The substitution emits both a `slog.Warn` line (fields: `pkg=workflow`, `tenant`, `entityName`, `modelVersion`, `entityId`, `reason=no_workflows_imported`|`no_criterion_matched`) and an `AddWarning` entry surfaced in the response body, so operators can detect models silently running on the default.
3. Set `entity.Meta.State = workflow.initialState`.
4. If a named transition was requested (by the client), execute it: evaluate `criterion`, invoke processors, set `entity.Meta.State = transition.next`.
5. Cascade: repeatedly scan the current state's transitions; for each automated (`manual=false`) non-disabled transition, evaluate `criterion`; if it matches, invoke processors and advance the state. Stop when no automated transition matches or the state has no automated transitions.
6. The engine records `StateMachineEvent` entries to the audit log under the entity's `transactionId`.
Per-state visit limit (default 10) and total cascade depth limit (100) are enforced to prevent infinite loops.
## ERRORS
- `errors.TRANSITION_NOT_FOUND` — `400` — named transition does not exist in the current state's workflow
- `errors.WORKFLOW_NOT_FOUND` — `404` — no workflows found for the model (export endpoint)
- `errors.WORKFLOW_FAILED` — workflow engine encountered an unrecoverable error during execution
- `errors.NO_COMPUTE_MEMBER_FOR_TAG` — no registered calculation node matches the required `calculationNodesTags`
- `errors.COMPUTE_MEMBER_DISCONNECTED` — a calculation node disconnected during processor dispatch
- `errors.WORKFLOW_SCHEMA_VERSION_UNSUPPORTED` — `400` — workflow declares a schema version this server does not accept
- `errors.VALIDATION_FAILED` — `400` — workflow import validation failed; see IMPORT REQUEST above for the enumerated rules
## EXAMPLES
**Import a workflow:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"importMode": "MERGE",
"workflows": [
{
"version": "1.4",
"name": "prize-lifecycle",
"initialState": "NEW",
"active": true,
"states": {
"NEW": {
"transitions": [
{
"name": "APPROVE",
"next": "APPROVED",
"manual": true,
"processors": []
}
]
},
"APPROVED": {
"transitions": []
}
}
}
]
}' \
"http://localhost:8080/api/model/nobel-prize/1/workflow/import"
```
**Export workflows:**
```
curl -s -H "Authorization: Bearer $TOKEN" \
"http://localhost:8080/api/model/nobel-prize/1/workflow/export"
```
**Trigger a manual transition:**
```
curl -s -X PUT \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"category":"physics","year":"2024"}' \
"http://localhost:8080/api/entity/JSON/74807f00-ed0d-11ee-a357-ae468cd3ed16/APPROVE"
```
**Replace all workflows:**
```
curl -s -X POST \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"importMode": "REPLACE",
"workflows": [
{
"version": "1.4",
"name": "simple-wf",
"initialState": "OPEN",
"active": true,
"states": {
"OPEN": { "transitions": [] }
}
}
]
}' \
"http://localhost:8080/api/model/nobel-prize/1/workflow/import"
```
## SEE ALSO
- models
- crud
- grpc
- search
- errors.TRANSITION_NOT_FOUND
- errors.WORKFLOW_NOT_FOUND
- errors.WORKFLOW_FAILED
- errors.NO_COMPUTE_MEMBER_FOR_TAG
- errors.COMPUTE_MEMBER_DISCONNECTED
- errors.WORKFLOW_SCHEMA_VERSION_UNSUPPORTED
- errors.VALIDATION_FAILED
- errors.MODEL_NOT_FOUND
## Subtopics
- [`cyoda help workflows schema-version`](/help/workflows/schema-version/) — workflows schema-version — semver `MAJOR.MINOR` contract identifying the workflow-import DTO shape that a workflow definition was authored against.
## See also
- [`cyoda help models`](/help/models/) — A model is a named, versioned schema registered per tenant. Every entity in the system is an instance of exactly one model. Models are identified by `(entityName, modelVersion)`. The model ID is a deterministic UUID v5 derived from that key: `UUID.newSHA1(NameSpaceURL, "{entityName}.{modelVersion}")`.
- [`cyoda help crud`](/help/crud/) — Entities are instances of models. Each entity has a UUID, a model reference (`entityName`, `modelVersion`), and a lifecycle state managed by the workflow engine. Creating an entity requires the referenced model to be in `LOCKED` state. All write operations run within a Cyoda transaction and return a `transactionId` alongside the affected entity IDs.
- [`cyoda help grpc`](/help/grpc/) — cyoda-go exposes one gRPC service: `CloudEventsService` (package `org.cyoda.cloud.api.grpc`). All gRPC methods use the CloudEvents Protobuf envelope (`io.cloudevents.v1.CloudEvent`) as both request and response types. The event type string in the CloudEvent envelope selects the operation; the JSON payload in `text_data` (or `binary_data`) carries the operation-specific body.
- [`cyoda help search`](/help/search/) — Search operates against a specific entity model `(entityName, modelVersion)`. Two modes are supported:
- [`cyoda help workflows schema-version`](/help/workflows/schema-version/) — workflows schema-version — semver `MAJOR.MINOR` contract identifying the workflow-import DTO shape that a workflow definition was authored against.
- [`cyoda help errors TRANSITION_NOT_FOUND`](/help/errors/transition_not_found/) — Entity workflow state machines define explicit transitions between states. This error fires when a transition is triggered that does not exist in the model's workflow definition for the entity's current state. Also occurs when the transition name is misspelled, when the transition is disabled, when it is a scheduled transition (those fire on their timer and are never manually fireable), or when the entity is in a terminal state that allows no further transitions.
- [`cyoda help errors WORKFLOW_NOT_FOUND`](/help/errors/workflow_not_found/) — Entity models reference a workflow by name to govern state transitions. This error is returned when the named workflow cannot be found in the tenant's workflow registry, during entity type registration or when a model references a workflow that was deleted.
- [`cyoda help errors WORKFLOW_FAILED`](/help/errors/workflow_failed/) — During an entity create or transition operation the associated workflow processors (pre-processors, post-processors) or guard conditions ran but one of them signalled failure. The failure message from the processor is included in the error detail.
- [`cyoda help errors NO_COMPUTE_MEMBER_FOR_TAG`](/help/errors/no_compute_member_for_tag/) — Workflow processors are dispatched to nodes that advertise matching compute tags. When no node with the required tag is alive in the cluster within the configured wait timeout (`CYODA_DISPATCH_WAIT_TIMEOUT`), the operation is rejected with this error.
- [`cyoda help errors COMPUTE_MEMBER_DISCONNECTED`](/help/errors/compute_member_disconnected/) — The compute member responsible for executing a processor or workflow step disconnected before completing the operation. The task may or may not have been executed.
- [`cyoda help errors WORKFLOW_SCHEMA_VERSION_UNSUPPORTED`](/help/errors/workflow_schema_version_unsupported/) — Every workflow definition must declare a schema version in `MAJOR.MINOR` format (for example `"version": "1.1"`). This error is returned when the import request contains a version string that does not match any supported schema version.
- [`cyoda help errors VALIDATION_FAILED`](/help/errors/validation_failed/) — Unlike `BAD_REQUEST` (which covers parse failures, bad parameters, and unstorable bytes), this error is returned when the payload parsed and then failed against the registered model. On an entity write that means:
- [`cyoda help errors MODEL_NOT_FOUND`](/help/errors/model_not_found/) — The entity type or model name specified in the request does not exist in the tenant's model registry. Occurs on write paths (creating entities with an unknown type, importing data that references a missing model, performing model lifecycle transitions on a model ID that does not exist) and on read paths (list, stats, grouped-stats, and search operations that reference an unregistered model).
- [`cyoda help errors SCHEDULE_FUNCTION_INVALID_RESULT`](/help/errors/schedule_function_invalid_result/) — A `TransitionSchedule.function` callout must return `resultKind: "Schedule"` with a value shaped `{fireAt|fireAfterMs, expireAt?|expireAfterMs?}` — exactly one of `fireAt`/`fireAfterMs`, and at most one of `expireAt`/`expireAfterMs`. This error is raised when the compute node returns a different `resultKind`, or a `Schedule` value that is malformed: missing or duplicate fire/expiry fields, an unknown field, or a non-numeric value.
## Raw formats
- [`/help/workflows.json`](/help/workflows.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/workflows.md`](/help/workflows.md) — body only
---
## help/workflows/schema-version.md
# workflows schema-version — wire-format contract for workflow import
workflows schema-version — semver `MAJOR.MINOR` contract identifying the workflow-import DTO shape that a workflow definition was authored against.
cyoda-go version 0.8.4
# workflows schema-version
## NAME
workflows schema-version — semver `MAJOR.MINOR` contract identifying the workflow-import DTO shape that a workflow definition was authored against.
## SYNOPSIS
Every `WorkflowConfigurationDto` carries a `version` field. The server validates it strictly on import and stamps the current contract version on every workflow it exports.
```json
{
"version": "1.4",
"name": "my-workflow",
"initialState": "ready",
"states": { "ready": {} }
}
```
## SEMANTICS
- **MAJOR** bumps when a payload valid under the previous MAJOR is no longer valid (or vice-versa) — removing a field, renaming, changing semantics, making an optional field required.
- **MINOR** bumps for additive, backward-compatible changes — a new optional field, a new enum value in an existing string-enum, a new condition operator. **This is the common case.**
Multiple MAJORs may be accepted concurrently during a deprecation window. Within a MAJOR, the server accepts any MINOR in its declared `[minMinor, maxMinor]` range.
Current contract: **1.4**, which added the `NOT` group operator to a criterion's `group` clause (dual-shape: 1.1, 1.2 and 1.3 remain accepted). Not every behaviour change bumps this contract — the evaluation-time change that makes a criterion naming a field the model does not declare abort and roll back the save (see `errors.WORKFLOW_FAILED`) does not, because it alters no import validation, acceptance rule, or export shape. See `docs/workflow-schema-versioning.md` for the full rationale on both.
## DISCOVERY
Authoritative discovery is via the `versions` action:
```
cyoda help workflows schema-version versions
```
HTTP mirror:
```
GET /help/workflows/schema-version/versions
```
Both emit the same structured JSON:
```json
{
"current": "1.4",
"supported": [
{ "major": 1, "minMinor": 1, "maxMinor": 4 }
]
}
```
## VALIDATION ERRORS
On import, an unsupported or malformed `version` returns HTTP 400 with `errorCode: "WORKFLOW_SCHEMA_VERSION_UNSUPPORTED"`. The message body distinguishes:
- **Malformed** (`"x"`, `"1"`, `"1.0.0"`, leading zeros) — not in `MAJOR.MINOR` form.
- **Major unsupported** — the major version is not in any supported range.
- **Minor too new** — the major matches but the minor exceeds this server's `maxMinor`. Upgrade cyoda-go, or regenerate the file against an older schema.
- **Minor too old** — the major matches but the minor is below the server's `minMinor` (deprecation window). Re-author the file against a supported MINOR.
## EXAMPLE: PINNING
Pin your authoring tools and CI to the schema version they were tested against:
```bash
# in a CI step
current=$(curl -s $CYODA_HOST/api/help/workflows/schema-version/versions | jq -r .current)
test "$current" = "1.4" || { echo "schema drift"; exit 1; }
```
## See also
- [`cyoda help workflows`](/help/workflows/) — A workflow definition is a named finite state machine attached to an entity model. Workflows are stored per model reference `(entityName, modelVersion)`. A model may have multiple workflow definitions; the engine selects the matching one per entity using the workflow-level `criterion` field evaluated at entity creation time. When no `criterion` matches, the engine uses the default built-in workflow.
- [`cyoda help errors WORKFLOW_SCHEMA_VERSION_UNSUPPORTED`](/help/errors/workflow_schema_version_unsupported/) — Every workflow definition must declare a schema version in `MAJOR.MINOR` format (for example `"version": "1.1"`). This error is returned when the import request contains a version string that does not match any supported schema version.
- [`cyoda help openapi`](/help/openapi/) — cyoda-go generates its OpenAPI 3.1 specification from the embedded `api/openapi.yaml` file compiled into the binary at build time. The spec is served at `/openapi.json` with runtime-patched server URLs. The Scalar API Reference UI is served at `/docs` and loads the spec from `/openapi.json`.
## Raw formats
- [`/help/workflows/schema-version.json`](/help/workflows/schema-version.json) — full descriptor (matches `GET /help/{topic}` envelope)
- [`/help/workflows/schema-version.md`](/help/workflows/schema-version.md) — body only
---
## index.md
# Cyoda Documentation
Build and run Cyoda applications — from local cyoda-go to hosted Cyoda Cloud.

EDBMS — Entity Database Management System
# One transactional runtime for the entity lifecycle.
Cyoda is an EDBMS: state machine, processors, and full revision history
live inside the record, committed atomically — minimizing the need for
sagas. A simpler stack than Postgres + Temporal + Kafka + a CDC audit
pipeline. Build complete event-driven backends on one runtime. Open
source, single Go binary, Postgres-backed.
## Four storage engines. One application contract.
Three open-source engines ship with cyoda-go — in-memory, SQLite, and
PostgreSQL — each tuned to a different operational shape. A commercial
Cassandra plugin extends the same application code to fully scalable,
robust production workloads.
→ See [Storage engines](/run/storage-engines/) for per-engine
characteristics and deployment guidance.
## Where to go next
- **New here?** Start with the [install-and-first-entity onramp](/getting-started/install-and-first-entity/).
- **Understanding Cyoda?** Read [Concepts](/concepts/what-is-cyoda/).
- **Building an app?** [Build](/build/) covers tier-agnostic patterns.
- **Running one?** [Run](/run/) covers [desktop](/run/desktop/), [Docker](/run/docker/), and [Kubernetes](/run/kubernetes/).
- **Need it managed?** [Cyoda Cloud](/cyoda-cloud/) is the hosted offering — coming soon.
- **Need API specs?** [Reference](/reference/) embeds and ingests from [cyoda-go](https://github.com/Cyoda/cyoda-go).
---
## reference.md
# Reference
Technical references — mostly generated from cyoda-go at build time.
Reference content on this site is a narrative skin over the cyoda-go
binary. The binary is self-documenting — every flag, environment
variable, endpoint, error code, metric, header, and operation ships with
its own help topic. This section points you at the right topics, shows
you the REST/gRPC surfaces, and documents the CloudEvent JSON Schemas.
The material here was captured against **cyoda-go v{helpIndex.pinnedVersion}**.
For whatever version you are running, `cyoda help` on your own binary
is the authoritative source.
## Start here
- **[`cyoda help` topic tree](/help/topic-tree/)** — navigator over the full topic tree. Every
top-level topic and its drilldowns, with synopses. The best first stop.
## Surfaces
- **[API](./api/)** — REST OpenAPI 3.1 reference, interactive viewer.
- **[gRPC](./api/#grpc)** — gRPC CloudEventsService (cross-linked from the API page).
- **[CloudEvents Schemas](./schemas/)** — CloudEvent payload schemas, extracted from the
pinned binary at build time.
- **[Trino SQL](./trino/)** — SQL analytics surface (Cyoda Cloud; upcoming).
## Navigators over specific topics
- **[CLI](./cli/)** — command-line entry points and global flags.
- **[Configuration](./configuration/)** — configuration model, precedence,
profiles, `_FILE` secrets.
- **[Helm values](./helm/)** — chart layout, values model, secret provisioning.
- **[Entity model export](./entity-model-export/)** — SIMPLE_VIEW and JSON_SCHEMA export shapes.
Each navigator page carries a "Canonical reference" callout pointing at
the corresponding `cyoda help ` for the authoritative contract.
---
## reference/api.md
# API reference
REST and gRPC surfaces.
The REST API reference is rendered in a dedicated viewer so the documentation
chrome does not compete with it for horizontal space:
[Open the REST API reference](/api-reference/)
The viewer works from the OpenAPI spec shipped with this site
(`/openapi/openapi.json`), which was extracted from **cyoda-go v{helpIndex.pinnedVersion}**.
For the version you are running, `cyoda help openapi` on your own binary is
authoritative.
The viewer supports the standard operations: browsing endpoints, inspecting
request/response shapes, and try-it-out calls against an environment of your
choice.
## gRPC
gRPC proto documentation is tracked upstream and will appear here once the
generated reference is published from cyoda-go. Until then, the `.proto`
files in
[cyoda-go/api/grpc](https://github.com/Cyoda/cyoda-go/tree/main/api/grpc)
are the authoritative source.
---
## reference/cli.md
# CLI
cyoda-go command-line interface — narrative navigator over `cyoda help cli`.
export const cliTopics = (() => {
const found = helpIndex.topics.filter(t => t.path[0] === 'cli');
if (found.length === 0) {
throw new Error(`EmptyNavigator: reference/cli.mdx filtered helpIndex to zero topics under prefix "cli" (pinned v${helpIndex.pinnedVersion}). Likely a topic rename upstream.`);
}
return found;
})();
The `cyoda` binary is the server and its own control surface. It runs as a
single long-lived process by default, with a small number of subcommands
for bootstrapping, health, and migration. Every flag, subcommand, and env
var is documented in-binary via `cyoda help ` and is version-
accurate to whatever binary you are running.
## Output formats
Every help topic supports three output formats via `--format`:
- `text` (default on a TTY) — human reading.
- `markdown` (default off-TTY) — paste into docs, PRs, chat.
- `json` — machine-readable, stable schema; consumed by tools like
cyoda-docs' own build pipeline.
## Drilldowns
Topics that naturally subdivide take a multi-word path on the CLI: `cyoda
help search async`, `cyoda help grpc compute`, and so on. The same path
appears in the JSON surface as an array.
## Related topics
The subset of `cyoda help` topics directly relevant to the CLI surface
itself is below.
{cliTopics.map((t) => (
cyoda help {t.path.join(' ')} — {t.title.replace(/^[^—]*—\s*/, '')}
{t.synopsis}
))}
---
## reference/configuration.md
# Configuration
cyoda-go configuration model — narrative navigator over `cyoda help config`.
export const varsByTopic = (() => {
const groups = {};
for (const v of configData.vars) {
(groups[v.topic] ??= []).push(v);
}
return Object.entries(groups).sort((a, b) => (a[0] < b[0] ? -1 : a[0] > b[0] ? 1 : 0));
})();
export const configTopics = (() => {
const found = helpIndex.topics.filter(t => t.path[0] === 'config');
if (found.length === 0) {
throw new Error(`EmptyNavigator: reference/configuration.mdx filtered helpIndex to zero topics under prefix "config" (pinned v${helpIndex.pinnedVersion}). Likely a topic rename upstream.`);
}
return found;
})();
cyoda-go reads configuration from `CYODA_*` environment variables and
from `.env`-format files. The model — how sources compose, how profiles
work, and how secrets are mounted from files — is described below, and the
authoritative key list (every variable, its type, its default) is mirrored
in full under [All variables](#all-variables). The binary remains the
source of truth: run `cyoda help config` to read it directly.
## Sources and precedence
Values resolve in this order, highest to lowest:
1. Shell environment
2. `.env.{profile}` files (in `CYODA_PROFILES` declaration order; later profiles override earlier ones within their group)
3. `.env` in the project directory
4. User config file
5. System config file
6. Hardcoded defaults
Format is `.env` only (godotenv-parsed). No TOML, no YAML, no `--config`
flag. Subcommand flags (e.g. `cyoda init --force`) are operation-scoped
and do not override server-runtime configuration.
**User config path** varies by OS: `~/.config/cyoda/cyoda.env` (Linux,
macOS with XDG), `%AppData%\cyoda\cyoda.env` (Windows). **System config**
lives at `/etc/cyoda/cyoda.env` on POSIX.
## Profiles
`CYODA_PROFILES` is comma-separated and evaluated in declaration order.
Within a profile, regular `.env` precedence applies; across profiles,
later entries in the list override earlier ones.
## Secrets via `_FILE` suffix
Any variable that accepts a credential (Postgres URL, JWT signing key,
metrics bearer, gossip HMAC, bootstrap client secret) accepts a
companion `*_FILE` variable that reads from a mounted file. Trailing
whitespace is stripped. The `_FILE` variant takes precedence when both
are set — the pattern designed for Kubernetes Secrets and Docker
secrets mounts.
## All variables
Every `CYODA_*` variable the engine reads, grouped by topic. Empty **Default**
or **Type** cells mean the binary reports none. This table is generated from
the pinned cyoda-go configuration surface.
{varsByTopic.map(([topic, vars]) => (
{topic} ({vars.length})
Variable
Type
Default
Description
{vars.map((v) => (
{v.name}
{v.type || '—'}
{v.default ? {v.default} : '—'}
{v.description}
))}
))}
## Related topics
{configTopics.map((t) => (
cyoda help {t.path.join(' ')} — {t.title.replace(/^[^—]*—\s*/, '')}
{t.synopsis}
))}
---
## reference/entity-model-export.md
# Entity model export
Wire format of the SIMPLE_VIEW and JSON_SCHEMA entity-model exports — response envelope, node descriptors, type descriptors, and error shapes.
A model export returns the full structural model of an entity type in a
compact JSON form. It carries every node, every field and every declared type.
Two converters render the model. **`SIMPLE_VIEW`** is Cyoda's native
path-keyed form. **`JSON_SCHEMA`** is a JSON Schema document. This page is the
wire-format specification for both.
For the concepts behind a model, and for discovery, widening and locking, see
[Modeling entities](/build/modeling-entities/) and
[Entities and lifecycle](/concepts/entities-and-lifecycle/).
## Endpoint
```
GET /model/export/{converter}/{entityName}/{modelVersion}
```
| Parameter | Type | Description |
|----------------|---------|----------------------------------------------------|
| `converter` | String | `SIMPLE_VIEW` or `JSON_SCHEMA` |
| `entityName` | String | Name of the entity model |
| `modelVersion` | Integer | Version number of the entity model |
**Response Content-Type:** `application/json`
## Response envelope
Both converters return the same envelope. `currentState` and `model` are always
present; `uniqueKeys` appears only when the model declares composite unique
keys.
| Key | Type | Description |
|----------------|--------|----------------------------------------------------------------|
| `currentState` | String | Lifecycle state of the model: `"UNLOCKED"` or `"LOCKED"` |
| `model` | Object | The exported model, in the converter's own form |
| `uniqueKeys` | Array | Composite unique-key definitions; omitted when none are declared |
```json
{
"currentState": "LOCKED",
"model": { "…": "…" },
"uniqueKeys": [
{ "id": "by-email", "fields": ["$.email"] },
{ "id": "by-org-and-handle", "fields": ["$.org", "$.handle"] }
]
}
```
## SIMPLE_VIEW
The `model` value is a flat JSON object. Its **keys are node paths**, and its
**values are node descriptors**. This single-depth map holds the full nested
tree. Each descriptor is an object, and it describes one structural level.
### Node paths
A node path uses JSONPath syntax rooted at `$`. It is the same path that a
search condition uses to address the same place.
| Path | Meaning |
|-------------------------|---------------------------------------------------------------------|
| `$` | The root object |
| `$.address` | A nested object field |
| `$.laureates[*]` | The elements of the `laureates` array on the root object |
| `$.orders[*].lines[*]` | The elements of `lines`, nested inside `orders` array elements |
Write one `[*]` for each array level. The server sorts the node paths
lexicographically. Every export contains the root node `$`.
### Node descriptors
A node descriptor is a JSON object with two kinds of entry.
**Data fields — keys starting with `.`** carry the field's
[type descriptor](#type-descriptors):
```json
{
".category": "STRING",
".year": "YEAR",
".score": "DOUBLE"
}
```
An array field's key carries one `[*]` per array level, and the value is the
type of the element at that depth:
```json
{
".tags[*]": "STRING",
".matrix[*][*]": "INTEGER"
}
```
An array level whose elements were never observed declares the level, but not
the element type. Its value is `"NULL"`:
```json
{ ".e[*]": "NULL" }
```
**Structural fields — keys starting with `#`** mark this node's role. Only two
values are emitted:
| Key | Value | Meaning |
|----------------|-------------------|------------------------------------------------------------|
| `#` | `"ARRAY_ELEMENT"` | This node describes the elements of its parent array |
| `#.fieldName` | `"OBJECT"` | `fieldName` carries object structure and has its own node |
A nested object is **not** inlined into its parent with a dotted key. It gets a
`#.fieldName` marker in the parent and a node of its own:
```json
{
"$": { "#.address": "OBJECT", ".name": "STRING" },
"$.address": { ".city": "STRING", ".zip": "STRING" }
}
```
The server sorts the keys inside a node. Structural keys (`#`) come before
data keys (`.`), because `#` precedes `.` in ASCII.
### Kind unions
A field observed in more than one kind declares each kind, and the model
enforces each one. The export therefore names each branch.
A field seen as both a string and an object carries a data entry and a
structural marker. The object branch gets a node of its own:
```json
{
"$": { "#.o": "OBJECT", ".o": "STRING" },
"$.o": { ".a": "INTEGER" }
}
```
A field seen as both a scalar and an array names both forms in one node:
```json
{ ".poly": "STRING", ".poly[*]": "STRING" }
```
### Type descriptors
A type descriptor is a JSON string: either one `DataType` name, or a
bracketed set when the field declares several.
**Monomorphic:**
```
"STRING"
```
**Polymorphic:**
```
"[INTEGER, STRING]"
```
Types inside the brackets are sorted by the `DataType` enum ordering: the
integer families, then the decimal families, then text, temporal, identifier,
binary, boolean, and `NULL` last.
### DataType values
Twenty types, and no others:
| Group | DataType | Description |
|---|---|---|
| Integer | `INTEGER` | 32-bit signed integer |
| | `LONG` | 64-bit signed integer |
| | `BIG_INTEGER` | Arbitrary-precision integer fitting Int128 |
| | `UNBOUND_INTEGER` | Integer of arbitrary magnitude |
| Decimal | `DOUBLE` | Decimal within the precision-15, scale-292 envelope |
| | `BIG_DECIMAL` | Decimal fitting Trino's fixed-scale Int128 encoding |
| | `UNBOUND_DECIMAL` | Decimal of arbitrary precision and scale |
| Text | `STRING` | Variable-length character sequence |
| | `CHARACTER` | A single Unicode character |
| Temporal | `LOCAL_DATE` | Date without time zone |
| | `LOCAL_DATE_TIME` | Date-time without time zone |
| | `LOCAL_TIME` | Time without date |
| | `ZONED_DATE_TIME` | Date-time with time zone |
| | `YEAR` | Year value |
| | `YEAR_MONTH` | Year and month |
| Identifier | `UUID_TYPE` | UUID |
| | `TIME_UUID_TYPE` | Version 1 (time-based) UUID |
| Binary | `BYTE_ARRAY` | Binary data, base64-encoded |
| Boolean | `BOOLEAN` | Boolean value |
| Null | `NULL` | No type observed at this leaf |
### SIMPLE_VIEW examples
**Flat object with an array of objects.** In this example `"2020"` classifies
as `YEAR`, not `STRING`. A date-shaped sample value gives the field a temporal
type at registration.
```json
// posted: {"category":"chemistry","year":"2020",
// "laureates":[{"firstname":"Emmanuelle","surname":"Charpentier","id":"991"}]}
{
"currentState": "UNLOCKED",
"model": {
"$": {
"#.laureates": "OBJECT",
".category": "STRING",
".year": "YEAR"
},
"$.laureates[*]": {
"#": "ARRAY_ELEMENT",
".firstname": "STRING",
".id": "STRING",
".surname": "STRING"
}
}
}
```
**Nested object and a primitive array.** The array's element type is named
once; its length is not part of the model.
```json
// posted: {"name":"Alice","scores":[95,87,92],"address":{"city":"London","zip":"SW1A"}}
{
"currentState": "UNLOCKED",
"model": {
"$": {
"#.address": "OBJECT",
".name": "STRING",
".scores[*]": "INTEGER"
},
"$.address": {
".city": "STRING",
".zip": "STRING"
}
}
}
```
**Array of arrays.** One `[*]` per level, in the parent node. There is no
detached node for the inner array.
```json
// posted: {"matrix":[[1,2,3],[4,5,6]]}
{
"currentState": "UNLOCKED",
"model": { "$": { ".matrix[*][*]": "INTEGER" } }
}
```
**Polymorphic scalar**, after ingesting `{"data":"hello"}` and `{"data":42}`:
```json
{
"currentState": "UNLOCKED",
"model": { "$": { ".data": "[INTEGER, STRING]" } }
}
```
**Heterogeneous array.** Element types merge into one set, and a `null`
contributes no type:
```json
// posted: {"row":[1,null,"three"]}
{
"currentState": "UNLOCKED",
"model": { "$": { ".row[*]": "[INTEGER, STRING]" } }
}
```
**Kind union across a container and a scalar**, after ingesting
`{"data":[{"nested":"primitive"}]}` and `{"data":[[123,321],[456,654]]}`:
```json
{
"currentState": "UNLOCKED",
"model": {
"$": {
"#.data": "OBJECT",
".data[*][*]": "INTEGER"
},
"$.data[*]": {
"#": "ARRAY_ELEMENT",
".nested": "STRING"
}
}
}
```
**Two levels of object arrays:**
```json
// posted: {"orders":[{"lines":[{"sku":"AX-1","qty":2}]}]}
{
"currentState": "UNLOCKED",
"model": {
"$": { "#.orders": "OBJECT" },
"$.orders[*]": { "#": "ARRAY_ELEMENT", "#.lines": "OBJECT" },
"$.orders[*].lines[*]": {
"#": "ARRAY_ELEMENT",
".qty": "INTEGER",
".sku": "STRING"
}
}
}
```
### JSON Schema for the SIMPLE_VIEW response
```json
{
"$schema": "https://json-schema.org/draft/2020-12/schema",
"title": "SIMPLE_VIEW Model Export Response",
"description": "Response from GET /model/export/SIMPLE_VIEW/{entityName}/{modelVersion}",
"type": "object",
"required": ["currentState", "model"],
"additionalProperties": false,
"properties": {
"currentState": {
"type": "string",
"enum": ["LOCKED", "UNLOCKED"],
"description": "Lifecycle state of the entity model."
},
"model": {
"type": "object",
"description": "Map of node paths to node descriptors. Always contains at least the root node '$'.",
"propertyNames": {
"pattern": "^\\$(\\.[A-Za-z0-9_-]+(\\[\\*\\])*)*$"
},
"additionalProperties": { "$ref": "#/$defs/nodeDescriptor" }
},
"uniqueKeys": {
"type": "array",
"description": "Composite unique keys declared on the model. Omitted when none are declared.",
"items": {
"type": "object",
"required": ["id", "fields"],
"properties": {
"id": { "type": "string" },
"fields": {
"type": "array",
"items": { "type": "string" },
"minItems": 1
}
}
}
}
},
"$defs": {
"dataType": {
"type": "string",
"enum": [
"INTEGER", "LONG", "BIG_INTEGER", "UNBOUND_INTEGER",
"DOUBLE", "BIG_DECIMAL", "UNBOUND_DECIMAL",
"STRING", "CHARACTER",
"LOCAL_DATE", "LOCAL_DATE_TIME", "LOCAL_TIME",
"ZONED_DATE_TIME", "YEAR", "YEAR_MONTH",
"UUID_TYPE", "TIME_UUID_TYPE",
"BYTE_ARRAY", "BOOLEAN", "NULL"
]
},
"typeDescriptor": {
"description": "One DataType name, or a bracketed set when the field declares several.",
"type": "string",
"examples": ["STRING", "INTEGER", "NULL", "[INTEGER, STRING]"]
},
"structuralDataType": {
"type": "string",
"description": "Value of a '#'-prefixed structural key.",
"enum": ["OBJECT", "ARRAY_ELEMENT"]
},
"nodeDescriptor": {
"type": "object",
"description": "Keys prefixed with '.' are data fields; keys prefixed with '#' are structural markers.",
"propertyNames": {
"pattern": "^((\\.[A-Za-z0-9_-]+(\\[\\*\\])*)|(#(\\.[A-Za-z0-9_-]+)?))$"
},
"additionalProperties": {
"anyOf": [
{ "$ref": "#/$defs/typeDescriptor" },
{ "$ref": "#/$defs/structuralDataType" }
]
}
}
}
}
```
## JSON_SCHEMA
The `JSON_SCHEMA` converter renders the same model as a JSON Schema document
under the same envelope. Objects become `{"type": "object", "properties": …}`,
arrays become `{"type": "array", "items": …}`, and leaves map onto JSON Schema
primitives:
| DataType | Rendered as |
|---|---|
| `INTEGER`, `LONG`, `BIG_INTEGER`, `UNBOUND_INTEGER` | `{"type": "integer"}` |
| `DOUBLE`, `BIG_DECIMAL`, `UNBOUND_DECIMAL` | `{"type": "number"}` |
| `STRING`, `CHARACTER` | `{"type": "string"}` |
| `BOOLEAN` | `{"type": "boolean"}` |
| `NULL` | `{"type": "null"}` |
| `LOCAL_DATE` | `{"type": "string", "format": "date"}` |
| `LOCAL_DATE_TIME`, `ZONED_DATE_TIME` | `{"type": "string", "format": "date-time"}` |
| `LOCAL_TIME` | `{"type": "string", "format": "time"}` |
| `YEAR` | `{"type": "string", "format": "year"}` |
| `YEAR_MONTH` | `{"type": "string", "format": "year-month"}` |
| `UUID_TYPE`, `TIME_UUID_TYPE` | `{"type": "string", "format": "uuid"}` |
| `BYTE_ARRAY` | `{"type": "string", "format": "byte"}` |
**A field that declares more than one branch renders as `anyOf`**, never
`oneOf`. Two `DataType` values can render the same shape, because `INTEGER` and
`LONG` both give `{"type": "integer"}`, so a union may carry identical
branches.
```json
// posted: {"data":"hello"} then {"data":42}
{
"currentState": "UNLOCKED",
"model": {
"type": "object",
"properties": {
"data": { "anyOf": [{ "type": "integer" }, { "type": "string" }] }
}
}
}
```
The same rule covers a kind union. A field seen as both a scalar and an array
renders as an `anyOf` over the array branch and the scalar branch:
```json
// posted: {"poly":"a"} then {"poly":["b","c"]}
{
"currentState": "UNLOCKED",
"model": {
"type": "object",
"properties": {
"poly": {
"anyOf": [
{ "type": "array", "items": { "type": "string" } },
{ "type": "string" }
]
}
}
}
}
```
## Error responses
| Status | Condition | Error code |
|--------|-------------------------|---------------------|
| 404 | Model not found | `MODEL_NOT_FOUND` |
| 400 | Unknown converter value | `BAD_REQUEST` |
**404 example** (captured):
```json
{
"type": "about:blank",
"title": "Not Found",
"status": 404,
"detail": "MODEL_NOT_FOUND: cannot find model entityName=nobel-prize, version=2",
"instance": "/model/export/SIMPLE_VIEW/nobel-prize/2",
"properties": {
"entityName": "nobel-prize",
"entityVersion": 2,
"errorCode": "MODEL_NOT_FOUND"
}
}
```
## Key behaviours for consumers
1. **Output is deterministic.** Node paths are sorted lexicographically, and
keys within a node are sorted, so two exports of the same model are
byte-identical.
2. **Models evolve by merging.** When you ingest entities under a model whose
change level permits it, new fields appear, the declared types of a leaf
widen (`INTEGER` → `[INTEGER, STRING]`), and a field can declare a new kind.
The export does not report the length of an array.
3. **Every declared branch is exported.** A field that declares more than one
kind names each kind. The export describes what the model enforces.
4. **An export is not an import format.** `SAMPLE_DATA` is the only converter
that the import endpoint accepts. A `POST` of an export to
`/model/import/JSON/SIMPLE_VIEW/…` returns
`400 BAD_REQUEST: unsupported import converter`. To establish a model, post
representative sample documents.
## Where to go next
- [Modeling entities](/build/modeling-entities/) — what a field declares, the
change-level ladder, and the field-name grammar.
- [Searching entities](/build/searching-entities/#how-a-field-path-is-written) —
the path grammar these node paths mirror.
- [JSON schema reference](/reference/schemas/) — the REST-API message schemas
generated from cyoda-go.
---
## reference/helm.md
# Helm values
cyoda-go Helm chart — narrative navigator over `cyoda help helm`.
export const helmTopics = (() => {
const found = helpIndex.topics.filter(t => t.path[0] === 'helm');
if (found.length === 0) {
throw new Error(`EmptyNavigator: reference/helm.mdx filtered helpIndex to zero topics under prefix "helm" (pinned v${helpIndex.pinnedVersion}). Likely a topic rename upstream.`);
}
return found;
})();
The `deploy/helm/cyoda` chart packages cyoda-go for Kubernetes. The
chart's own `values.yaml` enumerates every configurable key; this page
covers the model that shapes how those values map to Kubernetes objects
and how secrets are provisioned.
## What the chart provisions
A standard deployment per release: a `Deployment`, a `Service` for HTTP
+ gRPC + admin ports, a `ConfigMap` materialising the `.env`-format
configuration, and a `Secret` for credential material. An optional
`ServiceMonitor` (Prometheus Operator) and `HorizontalPodAutoscaler`
are wired off per-value flags.
## Values model
Values split into two groups:
- **Configuration values** — map one-to-one to the `CYODA_*` env vars
documented in the binary. Changing them alters runtime behaviour but
not Kubernetes shape. See `cyoda help config` for the list.
- **Deployment values** — image tag, replica count, resource requests,
service type, ingress glue. These shape the Kubernetes objects the
chart renders; they never reach the binary.
## Secret provisioning
Credentials follow the same `_FILE` pattern as bare-metal deployments.
The chart mounts the `Secret` at a known path and sets `CYODA_*_FILE`
env vars accordingly, so the binary reads each secret at startup. You
never put raw credentials into the chart's `values.yaml` in a
production deployment — wire an existing `Secret` via `existingSecret`
or equivalent.
## Database migrations
Schema migrations can run under a **separate Postgres connection** from
the runtime. Set an optional migration DSN (`migrate.postgres`) when the
account that applies DDL should differ from the least-privilege account
the running pods use — a common production split. When it is unset,
migrations run over the runtime connection.
## Related topics
{helmTopics.map((t) => (
cyoda help {t.path.join(' ')} — {t.title.replace(/^[^—]*—\s*/, '')}
{t.synopsis}
))}
See [Run → Kubernetes](/run/kubernetes/) for the deployment pattern and
production-sizing guidance.
---
## reference/identity-and-iam.md
# Identity and IAM
Self-hosted cyoda-go IAM admin surface — OIDC provider trust, JWT signing keys, machine-to-machine clients, and the configuration that governs them.
cyoda-go is an OAuth 2.0 authorization server; this page is the operator's
reference for the **IAM admin surface** that configures it on a
self-hosted instance — which external identities to trust, which keys
sign and verify tokens, and which machine-to-machine clients exist. For
the conceptual model (token issuance, on-behalf-of exchange, federation),
see [Authentication and identity](/concepts/authentication-and-identity/);
for the managed equivalent, see
[Cyoda Cloud → identity and entitlements](/cyoda-cloud/identity-and-entitlements/).
All paths below are admin endpoints and require an administrative token.
The [REST API reference](/reference/api/) carries the authoritative
request/response schemas; this page covers what each group is for and how
the pieces fit together. Run `cyoda help auth` against your binary for the
version-specific detail.
## OIDC provider trust
Register the external OpenID Connect issuers a tenant should trust. Each
registration is validated against its discovery document, and incoming
tokens are checked against the local issuer first, then each registered
provider in turn.
| Method & path | Purpose |
| --- | --- |
| `GET /oauth/oidc/providers` | List registered providers. |
| `POST /oauth/oidc/providers` | Register a provider. |
| `PATCH /oauth/oidc/providers/{id}` | Update a registration. |
| `POST /oauth/oidc/providers/{id}/invalidate` | Stop trusting a provider (reversible). |
| `POST /oauth/oidc/providers/{id}/reactivate` | Resume trusting it. |
| `DELETE /oauth/oidc/providers/{id}` | Remove a registration. |
| `POST /oauth/oidc/providers/reload` | Re-fetch provider metadata (JWKS) cluster-wide. |
A registration describes how to trust the issuer:
```json
{
"wellKnownConfigUri": "https://your-idp/.well-known/openid-configuration",
"issuers": ["https://your-idp/"],
"expectedAudiences": ["cyoda-prod"],
"rolesClaim": "realm_access.roles"
}
```
- **`wellKnownConfigUri`** (required) — the provider's OIDC discovery
endpoint. cyoda-go fetches the JWKS and metadata from it.
- **`issuers`** — allowed `iss` values. When omitted, the `iss` claim must
match the discovery document's `issuer` exactly.
- **`expectedAudiences`** — accepted `aud` values. **When several tenants
share one IdP, set a distinct audience per registration** — this is what
disambiguates tokens; ambiguous tokens are rejected rather than guessed.
When omitted, the audience is not checked and issuer binding is the only
trust anchor.
- **`rolesClaim`** — the claim that carries roles, overriding the global
default (`CYODA_OIDC_ROLES_CLAIM`, typically `roles`). Per-provider
override accommodates IdP variation — Keycloak uses `realm_access.roles`,
Cognito uses `cognito:groups`. Object-nested claims are supported.
OIDC registration requires a **UUID-formatted tenant**. Deployments that
bootstrapped on the literal string `default-tenant` must migrate to a
tenant UUID before registering a provider.
## JWT signing keys
cyoda-go signs the tokens it issues with asymmetric keypairs and can also
trust externally injected public keys. Both are managed under
`/oauth/keys`.
### Signing keypairs
| Method & path | Purpose |
| --- | --- |
| `GET /oauth/keys/keypair/current` | The active signing keypair (public part). |
| `POST /oauth/keys/keypair` | Create / rotate a keypair. |
| `POST /oauth/keys/keypair/{keyId}/invalidate` | Invalidate a keypair (with grace). |
| `POST /oauth/keys/keypair/{keyId}/reactivate` | Reactivate it. |
| `DELETE /oauth/keys/keypair/{keyId}` | Delete it. |
### Trusted external keys
The `/oauth/keys/trusted/*` endpoints register public keys from an
external issuer so cyoda-go accepts tokens signed elsewhere. The same
`invalidate` / `reactivate` / `delete` lifecycle applies.
- **Signing keys expire** after a default **365 days** and must be
rotated. The startup banner warns for the final 30 days before
expiry — wire rotation into your operations.
- **Only `RS256`** is accepted for signing and verification. Other
algorithms are rejected at runtime.
- **Trusted-key registration is off by default.** Opt in explicitly with
`CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=true`.
## Machine-to-machine clients
Manage the technical-user clients that authenticate with the OAuth 2.0
client-credentials grant (see
[machine-to-machine credentials](/concepts/authentication-and-identity/#machine-to-machine-credentials)).
| Method & path | Purpose |
| --- | --- |
| `GET /clients` | List M2M clients. |
| `POST /clients` | Create a client. |
| `PUT /clients/{clientId}/secret` | Rotate the client secret. |
| `DELETE /clients/{clientId}` | Delete a client. |
Creation returns the credential once, in
[RFC 7591](https://www.rfc-editor.org/rfc/rfc7591) form — capture the
secret at creation time:
```json
{
"client_id": "abc523BCD",
"client_secret": "…",
"client_id_issued_at": 1709913600,
"client_secret_expires_at": 0
}
```
## Configuration
The IAM behaviours above are governed by `CYODA_*` configuration; the
authoritative key list lives in the binary (`cyoda help config`). The
settings most likely to affect an upgrade:
| Variable | Effect |
| --- | --- |
| `CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED` | Enables the trusted-key endpoints. Default `false`. |
| `CYODA_OIDC_ROLES_CLAIM` | Default JWT claim read for roles when a provider sets no `rolesClaim`. |
See [Configuration](/reference/configuration/) for the configuration
model and [Authentication and identity](/concepts/authentication-and-identity/)
for the concepts.
---
## reference/schemas.md
# CloudEvents Schemas
Complete reference for the CloudEvent and entity/model JSON schemas used in Cyoda
# CloudEvents Schemas
This section documents the JSON schemas used by the Cyoda platform — CloudEvent
payloads exchanged over the gRPC processing stream, plus the entity and model
structures that travel over REST and gRPC.
The schemas shown here were captured against **cyoda-go v0.8.4**.
For the version you are running, `cyoda help cloudevents` (narrative) and
`cyoda help cloudevents json` (machine-readable) on your own binary are
authoritative — the binary ships its own schema tree and always matches its
own code.
## Download Schemas
You can download all schemas as a ZIP file: [schemas.zip](/schemas.zip)
## Schema Categories
Browse [Common schemas](./common/)
Browse [Entity schemas](./entity/)
Browse [Model schemas](./model/)
Browse [Processing schemas](./processing/)
Browse [Search schemas](./search/)
## Using JSON Schemas
JSON schemas define the structure and validation rules for data in the Cyoda platform. Each schema includes:
- **Property definitions** with types and descriptions
- **Required fields** clearly marked
- **Validation rules** for data integrity
- **References** to related schemas
Navigate to any category above to explore the available schemas.
---
## reference/schemas/common.md
JSON schemas in the Common category
# Common Schemas
This section contains JSON schemas for common.
## Available Schemas
- [PatchFormat](./patch-format/)
- [ModelSpec](./model-spec/)
- [ModelInfo](./model-info/)
- [ModelConverterType](./model-converter-type/)
- [ErrorCode](./error-code/)
- [EntityMetadata](./entity-metadata/)
- [EntityChangeMeta](./entity-change-meta/)
- [DataPayload](./data-payload/)
- [DataFormat](./data-format/)
- [CloudEventType](./cloud-event-type/)
- [BaseEvent](./base-event/)
---
## reference/schemas/common/base-event.md
# BaseEvent
Schema definition for BaseEvent
# BaseEvent
Schema definition for BaseEvent
## Schema Viewer
## Description
This schema defines the structure and validation rules for BaseEvent.
## Properties
- **error** (object): Error details (if present).
- **id** (string, required): Event ID.
- **success** (boolean): Flag indicates whether this message relates to some failure.
- **warnings** (array): Warnings (if applicable).
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/cloud-event-type.md
# CloudEventType
Schema definition for CloudEventType
# CloudEventType
Schema definition for CloudEventType
## Schema Viewer
## Description
This schema defines the structure and validation rules for CloudEventType.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/data-format.md
# DataFormat
Specifies the format of the input data (e.g., JSON).
# DataFormat
Specifies the format of the input data (e.g., JSON).
## Schema Viewer
## Description
Specifies the format of the input data (e.g., JSON).
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/data-payload.md
# DataPayload
Schema definition for DataPayload
# DataPayload
Schema definition for DataPayload
## Schema Viewer
## Description
This schema defines the structure and validation rules for DataPayload.
## Properties
- **data** (any): Payload data.
- **meta** (any): Metadata for the payload.
- **type** (string, required): Payload type.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/entity-change-meta.md
# EntityChangeMeta
Metadata about entity changes including transaction information and change type.
# EntityChangeMeta
Metadata about entity changes including transaction information and change type.
## Schema Viewer
## Description
Metadata about entity changes including transaction information and change type.
## Properties
- **changeType** (string, required): Type of change that was made to the entity.
- **fieldsChangedCount** (integer): Number of fields changed in the entity for this change.
- **timeOfChange** (string, required): Timestamp when the change occurred.
- **transactionId** (string): UUID of the transaction that made this change.
- **user** (string, required): User who made the change.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/entity-metadata.md
# EntityMetadata
Metadata about an entity. id, modelKey and creationDate are invariant against the point-in-time. All other values are with respect to the as-at point-in-time for which the entity was retrieved. If the point-in-time was not explicitly set, the values correspond to the latest state of the entity.
## Schema Viewer
## Description
Metadata about an entity. id, modelKey and creationDate are invariant against the point-in-time. All other values are with respect to the as-at point-in-time for which the entity was retrieved. If the point-in-time was not explicitly set, the values correspond to the latest state of the entity.
## Properties
- **creationDate** (string, required): The creation date of the entity.
- **id** (string, required): ID of the entity.
- **lastUpdateTime** (string, required): The last time the entity was updated as-at the given point-in-time. Equals the creation date if the entity has not been updated.
- **modelKey** (object): Model of the entity.
- **pointInTime** (string): Optional value for the as-at point-in-time for which the entity was retrieved.
- **state** (string, required): The state of the entity at the given point-in-time.
- **transactionId** (string): The transaction id of the entity when last saved as-at the given point-in-time.
- **transitionForLatestSave** (string): The transition applied of the entity when last saved as-at the given point-in-time.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/error-code.md
# ErrorCode
Schema definition for ErrorCode
# ErrorCode
Schema definition for ErrorCode
## Schema Viewer
## Description
This schema defines the structure and validation rules for ErrorCode.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/model-converter-type.md
# ModelConverterType
Defines the type of converter to use when importing the model (e.g., SAMPLE_DATA to use sample object)
# ModelConverterType
Defines the type of converter to use when importing the model (e.g., SAMPLE_DATA to use sample object)
## Schema Viewer
## Description
Defines the type of converter to use when importing the model (e.g., SAMPLE_DATA to use sample object)
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/model-info.md
# ModelInfo
Schema definition for ModelInfo
# ModelInfo
Schema definition for ModelInfo
## Schema Viewer
## Description
This schema defines the structure and validation rules for ModelInfo.
## Properties
- **id** (string, required): Id of the model.
- **name** (string, required): Name of the model.
- **state** (string, required): Current state of the model.
- **version** (integer, required): Version of the model.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/model-spec.md
# ModelSpec
Schema definition for ModelSpec
# ModelSpec
Schema definition for ModelSpec
## Schema Viewer
## Description
This schema defines the structure and validation rules for ModelSpec.
## Properties
- **name** (string, required): Name of the model.
- **version** (integer, required): Version of the model.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/patch-format.md
# PatchFormat
Patch dialect: MERGE_PATCH (RFC 7386, implemented) or JSON_PATCH (RFC 6902, not implemented).
# PatchFormat
"Patch dialect: MERGE_PATCH (RFC 7386, implemented) or JSON_PATCH (RFC 6902, not implemented)."
## Schema Viewer
## Description
Patch dialect: MERGE_PATCH (RFC 7386, implemented) or JSON_PATCH (RFC 6902, not implemented).
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/statemachine.md
JSON schemas in the Statemachine category
# Statemachine Schemas
This section contains JSON schemas for statemachine.
## Available Schemas
- [WorkflowInfo](./workflow-info/)
- [TransitionInfo](./transition-info/)
- [ProcessorInfo](./processor-info/)
---
## reference/schemas/common/statemachine/processor-info.md
# ProcessorInfo
Schema definition for ProcessorInfo
# ProcessorInfo
Schema definition for ProcessorInfo
## Schema Viewer
## Description
This schema defines the structure and validation rules for ProcessorInfo.
## Properties
- **id** (string, required): Processor ID.
- **name** (string, required): Processor name.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/statemachine/transition-info.md
# TransitionInfo
Schema definition for TransitionInfo
# TransitionInfo
Schema definition for TransitionInfo
## Schema Viewer
## Description
This schema defines the structure and validation rules for TransitionInfo.
## Properties
- **id** (string, required): Transition ID.
- **name** (string, required): Transition name.
- **stateFrom** (string, required): Source state.
- **stateTo** (string, required): Target state.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/common/statemachine/workflow-info.md
# WorkflowInfo
Schema definition for WorkflowInfo
# WorkflowInfo
Schema definition for WorkflowInfo
## Schema Viewer
## Description
This schema defines the structure and validation rules for WorkflowInfo.
## Properties
- **id** (string, required): Workflow ID.
- **name** (string, required): Workflow name.
## Related Schemas
See other schemas in the [common](/reference/schemas/common/) category.
---
## reference/schemas/entity.md
JSON schemas in the Entity category
# Entity Schemas
This section contains JSON schemas for entity.
## Available Schemas
- [EntityUpdateRequest](./entity-update-request/)
- [EntityUpdatePayload](./entity-update-payload/)
- [EntityUpdateCollectionRequest](./entity-update-collection-request/)
- [EntityTransitionResponse](./entity-transition-response/)
- [EntityTransitionRequest](./entity-transition-request/)
- [EntityTransactionResponse](./entity-transaction-response/)
- [EntityTransactionInfo](./entity-transaction-info/)
- [EntityPatchRequest](./entity-patch-request/)
- [EntityPatchPayload](./entity-patch-payload/)
- [EntityDeleteResponse](./entity-delete-response/)
- [EntityDeleteRequest](./entity-delete-request/)
- [EntityDeleteAllResponse](./entity-delete-all-response/)
- [EntityDeleteAllRequest](./entity-delete-all-request/)
- [EntityCreateRequest](./entity-create-request/)
- [EntityCreatePayload](./entity-create-payload/)
- [EntityCreateCollectionRequest](./entity-create-collection-request/)
---
## reference/schemas/entity/entity-create-collection-request.md
# EntityCreateCollectionRequest
Schema definition for EntityCreateCollectionRequest
# EntityCreateCollectionRequest
Schema definition for EntityCreateCollectionRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityCreateCollectionRequest.
## Properties
- **dataFormat** (object, required):
- **payloads** (array, required): Data payloads containing entities to save.
- **transactionTimeoutMs** (integer): Indicates the timeout of transaction for transactional save.
- **transactionWindow** (integer): The collection will be saved in a single transaction up to a maximum number of entities given by the transactionWindow. Collections exceeding the transactionWindow size will be saved in separate chunked transactions of the transactionWindow size.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-create-payload.md
# EntityCreatePayload
Schema definition for EntityCreatePayload
# EntityCreatePayload
Schema definition for EntityCreatePayload
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityCreatePayload.
## Properties
- **data** (any, required): Payload data.
- **model** (object, required): Entity model to use for this payload.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-create-request.md
# EntityCreateRequest
Schema definition for EntityCreateRequest
# EntityCreateRequest
Schema definition for EntityCreateRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityCreateRequest.
## Properties
- **dataFormat** (object, required):
- **payload** (object, required): Data payload containing entity to save.
- **transactionTimeoutMs** (integer): Indicates the timeout of transaction for transactional save.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-delete-all-request.md
# EntityDeleteAllRequest
Schema definition for EntityDeleteAllRequest
# EntityDeleteAllRequest
Schema definition for EntityDeleteAllRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityDeleteAllRequest.
## Properties
- **model** (object, required): Information about the model.
- **pointInTime** (string): point in time, i.e. delete all that existed prior to this point in time
- **transactionSize** (integer): Transaction size.
- **verbose** (boolean): Include the list of entity ids deleted in the response
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-delete-all-response.md
# EntityDeleteAllResponse
Schema definition for EntityDeleteAllResponse
# EntityDeleteAllResponse
Schema definition for EntityDeleteAllResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityDeleteAllResponse.
## Properties
- **entityIds** (array, required): IDs the delete attempted, when verbose was requested; an id whose delete failed also appears in errorsById. Empty when verbose is false.
- **errorsById** (object): Collections of errors by ids if any.
- **modelId** (string, required): ID of the model.
- **numDeleted** (integer, required): Number of the deleted entities.
- **requestId** (string, required): ID of the original request to get data.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-delete-request.md
# EntityDeleteRequest
Schema definition for EntityDeleteRequest
# EntityDeleteRequest
Schema definition for EntityDeleteRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityDeleteRequest.
## Properties
- **entityId** (string, required): ID of the entity.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-delete-response.md
# EntityDeleteResponse
Schema definition for EntityDeleteResponse
# EntityDeleteResponse
Schema definition for EntityDeleteResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityDeleteResponse.
## Properties
- **entityId** (string, required): ID of the removed entity.
- **model** (object, required): Information about the model of the removed entity.
- **requestId** (string, required): ID of the original request to get data.
- **transactionId** (string, required): ID of the transaction.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-patch-payload.md
# EntityPatchPayload
Schema definition for EntityPatchPayload
# EntityPatchPayload
Schema definition for EntityPatchPayload
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityPatchPayload.
## Properties
- **entityId** (string, required): ID of the entity to patch.
- **ifMatch** (string): transactionId from the last read, or "*" for unconditional. Empty is rejected as precondition-required.
- **patch** (any, required): The patch document (RFC 7386 merge patch).
- **transition** (string): Transition to apply, or omit for loopback.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-patch-request.md
# EntityPatchRequest
Schema definition for EntityPatchRequest
# EntityPatchRequest
Schema definition for EntityPatchRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityPatchRequest.
## Properties
- **patchFormat** (object, required):
- **payload** (object, required): Data payload containing the entity id and patch.
- **transactionTimeoutMs** (integer): Indicates the timeout of transaction for transactional save.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-transaction-info.md
# EntityTransactionInfo
Schema definition for EntityTransactionInfo
# EntityTransactionInfo
Schema definition for EntityTransactionInfo
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityTransactionInfo.
## Properties
- **entityIds** (array, required): IDs of entities in this transaction.
- **transactionId** (string): ID of the transaction.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-transaction-response.md
# EntityTransactionResponse
Schema definition for EntityTransactionResponse
# EntityTransactionResponse
Schema definition for EntityTransactionResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityTransactionResponse.
## Properties
- **requestId** (string, required): ID of the original request to save data.
- **transactionInfo** (object, required): Entity transaction info.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-transition-request.md
# EntityTransitionRequest
Schema definition for EntityTransitionRequest
# EntityTransitionRequest
Schema definition for EntityTransitionRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityTransitionRequest.
## Properties
- **entityId** (string, required): ID of the entity.
- **transition** (string, required): Name of the transition to apply.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-transition-response.md
# EntityTransitionResponse
Schema definition for EntityTransitionResponse
# EntityTransitionResponse
Schema definition for EntityTransitionResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityTransitionResponse.
## Properties
- **availableTransitions** (array): Available transitions from the current state.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-update-collection-request.md
# EntityUpdateCollectionRequest
Schema definition for EntityUpdateCollectionRequest
# EntityUpdateCollectionRequest
Schema definition for EntityUpdateCollectionRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityUpdateCollectionRequest.
## Properties
- **dataFormat** (object, required):
- **payloads** (array, required): Data payloads containing entities to update.
- **transactionTimeoutMs** (integer): Indicates the timeout of transaction for transactional save.
- **transactionWindow** (integer): The collection will be saved in a single transaction up to a maximum number of entities given by the transactionWindow. Collections exceeding the transactionWindow size will be saved in separate chunked transactions of the transactionWindow size.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-update-payload.md
# EntityUpdatePayload
Schema definition for EntityUpdatePayload
# EntityUpdatePayload
Schema definition for EntityUpdatePayload
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityUpdatePayload.
## Properties
- **data** (any, required): Entity payload data.
- **entityId** (string, required): ID of the entity.
- **transition** (string): Transition to use for update.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/entity/entity-update-request.md
# EntityUpdateRequest
Schema definition for EntityUpdateRequest
# EntityUpdateRequest
Schema definition for EntityUpdateRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityUpdateRequest.
## Properties
- **dataFormat** (object, required):
- **payload** (object, required): Data payload containing entity to update.
- **transactionTimeoutMs** (integer): Indicates the timeout of transaction for transactional save.
## Related Schemas
See other schemas in the [entity](/reference/schemas/entity/) category.
---
## reference/schemas/model.md
JSON schemas in the Model category
# Model Schemas
This section contains JSON schemas for model.
## Available Schemas
- [EntityModelTransitionResponse](./entity-model-transition-response/)
- [EntityModelTransitionRequest](./entity-model-transition-request/)
- [EntityModelImportResponse](./entity-model-import-response/)
- [EntityModelImportRequest](./entity-model-import-request/)
- [EntityModelGetAllResponse](./entity-model-get-all-response/)
- [EntityModelGetAllRequest](./entity-model-get-all-request/)
- [EntityModelExportResponse](./entity-model-export-response/)
- [EntityModelExportRequest](./entity-model-export-request/)
- [EntityModelDeleteResponse](./entity-model-delete-response/)
- [EntityModelDeleteRequest](./entity-model-delete-request/)
---
## reference/schemas/model/entity-model-delete-request.md
# EntityModelDeleteRequest
Schema definition for EntityModelDeleteRequest
# EntityModelDeleteRequest
Schema definition for EntityModelDeleteRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelDeleteRequest.
## Properties
- **model** (object, required): Entity model specification.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-delete-response.md
# EntityModelDeleteResponse
Schema definition for EntityModelDeleteResponse
# EntityModelDeleteResponse
Schema definition for EntityModelDeleteResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelDeleteResponse.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-export-request.md
# EntityModelExportRequest
Schema definition for EntityModelExportRequest
# EntityModelExportRequest
Schema definition for EntityModelExportRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelExportRequest.
## Properties
- **converter** (object, required):
- **model** (object, required): Entity model specification.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-export-response.md
# EntityModelExportResponse
Schema definition for EntityModelExportResponse
# EntityModelExportResponse
Schema definition for EntityModelExportResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelExportResponse.
## Properties
- **model** (object, required): Entity model specification.
- **modelId** (string, required): ID of the entity model.
- **payload** (any, required): The content format of the exported entity model depends on the selected converter.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-get-all-request.md
# EntityModelGetAllRequest
Schema definition for EntityModelGetAllRequest
# EntityModelGetAllRequest
Schema definition for EntityModelGetAllRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelGetAllRequest.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-get-all-response.md
# EntityModelGetAllResponse
Schema definition for EntityModelGetAllResponse
# EntityModelGetAllResponse
Schema definition for EntityModelGetAllResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelGetAllResponse.
## Properties
- **models** (array, required): Information about registered models.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-import-request.md
# EntityModelImportRequest
Schema definition for EntityModelImportRequest
# EntityModelImportRequest
Schema definition for EntityModelImportRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelImportRequest.
## Properties
- **converter** (object, required):
- **dataFormat** (object, required):
- **model** (object, required): Entity model specification.
- **payload** (any, required): The data to be used for importing the model.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-import-response.md
# EntityModelImportResponse
Schema definition for EntityModelImportResponse
# EntityModelImportResponse
Schema definition for EntityModelImportResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelImportResponse.
## Properties
- **modelId** (string, required): ID of the created or updated entity model.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-transition-request.md
# EntityModelTransitionRequest
Schema definition for EntityModelTransitionRequest
# EntityModelTransitionRequest
Schema definition for EntityModelTransitionRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelTransitionRequest.
## Properties
- **model** (object, required): Entity model specification.
- **transition** (string, required): Specifies the transition to perform.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/model/entity-model-transition-response.md
# EntityModelTransitionResponse
Schema definition for EntityModelTransitionResponse
# EntityModelTransitionResponse
Schema definition for EntityModelTransitionResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityModelTransitionResponse.
## Properties
- **modelId** (string, required): ID of the entity model.
- **state** (string, required): State of the entity model.
## Related Schemas
See other schemas in the [model](/reference/schemas/model/) category.
---
## reference/schemas/processing.md
JSON schemas in the Processing category
# Processing Schemas
This section contains JSON schemas for processing.
## Available Schemas
- [EventAckResponse](./event-ack-response/)
- [EntityProcessorCalculationResponse](./entity-processor-calculation-response/)
- [EntityProcessorCalculationRequest](./entity-processor-calculation-request/)
- [EntityFunctionCalculationResponse](./entity-function-calculation-response/)
- [EntityFunctionCalculationRequest](./entity-function-calculation-request/)
- [EntityCriteriaCalculationResponse](./entity-criteria-calculation-response/)
- [EntityCriteriaCalculationRequest](./entity-criteria-calculation-request/)
- [CalculationMemberKeepAliveEvent](./calculation-member-keep-alive-event/)
- [CalculationMemberJoinEvent](./calculation-member-join-event/)
- [CalculationMemberGreetEvent](./calculation-member-greet-event/)
---
## reference/schemas/processing/calculation-member-greet-event.md
# CalculationMemberGreetEvent
Schema definition for CalculationMemberGreetEvent
# CalculationMemberGreetEvent
Schema definition for CalculationMemberGreetEvent
## Schema Viewer
## Description
This schema defines the structure and validation rules for CalculationMemberGreetEvent.
## Properties
- **joinedLegalEntityId** (string, required): ID of the legal entity under which this member has joined.
- **memberId** (string, required): Assigned member ID.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/calculation-member-join-event.md
# CalculationMemberJoinEvent
Schema definition for CalculationMemberJoinEvent
# CalculationMemberJoinEvent
Schema definition for CalculationMemberJoinEvent
## Schema Viewer
## Description
This schema defines the structure and validation rules for CalculationMemberJoinEvent.
## Properties
- **tags** (array): Member tags. Could be used to filter applicability.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/calculation-member-keep-alive-event.md
# CalculationMemberKeepAliveEvent
Schema definition for CalculationMemberKeepAliveEvent
# CalculationMemberKeepAliveEvent
Schema definition for CalculationMemberKeepAliveEvent
## Schema Viewer
## Description
This schema defines the structure and validation rules for CalculationMemberKeepAliveEvent.
## Properties
- **memberId** (string, required): Member ID.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/entity-criteria-calculation-request.md
# EntityCriteriaCalculationRequest
Schema definition for EntityCriteriaCalculationRequest
# EntityCriteriaCalculationRequest
Schema definition for EntityCriteriaCalculationRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityCriteriaCalculationRequest.
## Properties
- **criteriaId** (string, required): Criteria ID.
- **criteriaName** (string, required): Criteria name.
- **entityId** (string, required): Entity ID.
- **parameters** (any): Configured parameters, if any.
- **payload** (object):
- **processor** (object): Processor information, available for targets PROCESSOR.
- **requestId** (string, required): Request ID.
- **target** (string, required): Target to which this condition is attached. NA is reserved for future cases.
- **transactionId** (string): Transaction ID.
- **transition** (object): Transition information, available for targets TRANSITION and PROCESSOR.
- **workflow** (object): Workflow information, available for targets WORKFLOW, PROCESSOR, TRANSITION.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/entity-criteria-calculation-response.md
# EntityCriteriaCalculationResponse
Schema definition for EntityCriteriaCalculationResponse
# EntityCriteriaCalculationResponse
Schema definition for EntityCriteriaCalculationResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityCriteriaCalculationResponse.
## Properties
- **entityId** (string, required): Entity ID.
- **matches** (boolean): Criteria check result.
- **reason** (string): Reason for the criteria check result.
- **requestId** (string, required): ID of the original criteria calculation request.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/entity-function-calculation-request.md
# EntityFunctionCalculationRequest
Schema definition for EntityFunctionCalculationRequest
# EntityFunctionCalculationRequest
Schema definition for EntityFunctionCalculationRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityFunctionCalculationRequest.
## Properties
- **entityId** (string, required): Entity ID.
- **functionId** (string, required): Function ID.
- **functionName** (string, required): Function name.
- **parameters** (any): Configured parameters, if any.
- **payload** (object):
- **requestId** (string, required): Request ID.
- **transactionId** (string): Transaction ID.
- **transition** (object): Transition information.
- **workflow** (object, required): Workflow information.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/entity-function-calculation-response.md
# EntityFunctionCalculationResponse
Schema definition for EntityFunctionCalculationResponse
# EntityFunctionCalculationResponse
Schema definition for EntityFunctionCalculationResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityFunctionCalculationResponse.
## Properties
- **entityId** (string, required): Entity ID.
- **requestId** (string, required): ID of the original function calculation request.
- **result** (object): Function calculation result.
- **resultKind** (string): Discriminator identifying the shape of `result`.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/entity-processor-calculation-request.md
# EntityProcessorCalculationRequest
Schema definition for EntityProcessorCalculationRequest
# EntityProcessorCalculationRequest
Schema definition for EntityProcessorCalculationRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityProcessorCalculationRequest.
## Properties
- **entityId** (string, required): Entity ID.
- **parameters** (any): Configured parameters, if any.
- **payload** (object):
- **processorId** (string, required): Processor ID.
- **processorName** (string, required): Processor name.
- **requestId** (string, required): Request ID.
- **transactionId** (string): Transaction ID.
- **transition** (object): Transition information.
- **workflow** (object, required): Workflow information.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/entity-processor-calculation-response.md
# EntityProcessorCalculationResponse
Schema definition for EntityProcessorCalculationResponse
# EntityProcessorCalculationResponse
Schema definition for EntityProcessorCalculationResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityProcessorCalculationResponse.
## Properties
- **entityId** (string, required): Entity ID.
- **payload** (object):
- **requestId** (string, required): ID of the original calculation request.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/processing/event-ack-response.md
# EventAckResponse
Schema definition for EventAckResponse
# EventAckResponse
Schema definition for EventAckResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EventAckResponse.
## Properties
- **sourceEventId** (string, required): ID of the original event.
## Related Schemas
See other schemas in the [processing](/reference/schemas/processing/) category.
---
## reference/schemas/search.md
JSON schemas in the Search category
# Search Schemas
This section contains JSON schemas for search.
## Available Schemas
- [SnapshotGetStatusRequest](./snapshot-get-status-request/)
- [SnapshotGetRequest](./snapshot-get-request/)
- [SnapshotCancelRequest](./snapshot-cancel-request/)
- [SearchSnapshotStatus](./search-snapshot-status/)
- [EntityStatsResponse](./entity-stats-response/)
- [EntityStatsGetRequest](./entity-stats-get-request/)
- [EntityStatsByStateResponse](./entity-stats-by-state-response/)
- [EntityStatsByStateGetRequest](./entity-stats-by-state-get-request/)
- [EntitySnapshotSearchResponse](./entity-snapshot-search-response/)
- [EntitySnapshotSearchRequest](./entity-snapshot-search-request/)
- [EntitySearchRequest](./entity-search-request/)
- [EntityResponse](./entity-response/)
- [EntityGetRequest](./entity-get-request/)
- [EntityGetAllRequest](./entity-get-all-request/)
- [EntityChangesMetadataResponse](./entity-changes-metadata-response/)
- [EntityChangesMetadataGetRequest](./entity-changes-metadata-get-request/)
---
## reference/schemas/search/entity-changes-metadata-get-request.md
# EntityChangesMetadataGetRequest
Schema definition for EntityChangesMetadataGetRequest
# EntityChangesMetadataGetRequest
Schema definition for EntityChangesMetadataGetRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityChangesMetadataGetRequest.
## Properties
- **entityId** (string, required): ID of the entity to retrieve change history for.
- **pointInTime** (string): Point in time to retrieve the entity changes. If not provided, retrieves all changes up to the current consistency time.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-changes-metadata-response.md
# EntityChangesMetadataResponse
Schema definition for EntityChangesMetadataResponse
# EntityChangesMetadataResponse
Schema definition for EntityChangesMetadataResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityChangesMetadataResponse.
## Properties
- **changeMeta** (object, required): Metadata about a single entity change.
- **requestId** (string, required): ID of the original request to get entity changes metadata.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-get-all-request.md
# EntityGetAllRequest
Schema definition for EntityGetAllRequest
# EntityGetAllRequest
Schema definition for EntityGetAllRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityGetAllRequest.
## Properties
- **model** (object, required): Information about the model to search.
- **pageNumber** (integer): Page number (from 0).
- **pageSize** (integer): Page size.
- **pointInTime** (string): point in time
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-get-request.md
# EntityGetRequest
Schema definition for EntityGetRequest
# EntityGetRequest
Schema definition for EntityGetRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityGetRequest.
## Properties
- **entityId** (string, required): ID of the entity.
- **pointInTime** (string): Point in time to retrieve the entity. If not provided, retrieves the entity at the current consistency time.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-response.md
# EntityResponse
Schema definition for EntityResponse
# EntityResponse
Schema definition for EntityResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityResponse.
## Properties
- **payload** (object, required): Payload with entity data and meta information.
- **requestId** (string, required): ID of the original request to get data.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-search-request.md
# EntitySearchRequest
Schema definition for EntitySearchRequest
# EntitySearchRequest
Schema definition for EntitySearchRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntitySearchRequest.
## Properties
- **condition** (object, required): Query condition to use for building this snapshot.
- **limit** (integer): Caps the matched result set; not a page size. A matched set larger than `limit` is rejected rather than returned as a truncated prefix. Values below 1 are rejected.
- **model** (object, required): Entity model to use for building this snapshot.
- **orderBy** (array):
- **pointInTime** (string): point in time
- **timeoutMillis** (integer): The maximum time to wait in milliseconds for the query to complete.
- **trackingRead** (boolean): When true and this search runs inside an active transaction, the entities it returns are recorded into the transaction's read-set so commit-time first-committer-wins validates them. Defaults to false. Ignored outside a transaction.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-snapshot-search-request.md
# EntitySnapshotSearchRequest
Schema definition for EntitySnapshotSearchRequest
# EntitySnapshotSearchRequest
Schema definition for EntitySnapshotSearchRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntitySnapshotSearchRequest.
## Properties
- **condition** (object, required): Query condition to use for building this snapshot.
- **model** (object, required): Entity model to use for building this snapshot.
- **orderBy** (array):
- **pointInTime** (string): point in time
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-snapshot-search-response.md
# EntitySnapshotSearchResponse
Schema definition for EntitySnapshotSearchResponse
# EntitySnapshotSearchResponse
Schema definition for EntitySnapshotSearchResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntitySnapshotSearchResponse.
## Properties
- **status** (object, required): Status information for the requested snapshot.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-stats-by-state-get-request.md
# EntityStatsByStateGetRequest
Schema definition for EntityStatsByStateGetRequest
# EntityStatsByStateGetRequest
Schema definition for EntityStatsByStateGetRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityStatsByStateGetRequest.
## Properties
- **model** (object): Optional specifier of the Entity model to calculate statistics for.
- **pointInTime** (string): The point-in-time for statistics in ISO 8601 format. Defaults to current consistency time if not provided.
- **states** (array): Optional list of states for which to calculate statistics. If not provided, statistics will be calculated for all current workflow states.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-stats-by-state-response.md
# EntityStatsByStateResponse
Schema definition for EntityStatsByStateResponse
# EntityStatsByStateResponse
Schema definition for EntityStatsByStateResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityStatsByStateResponse.
## Properties
- **count** (integer, required): Entity count for this model and state.
- **modelName** (string, required): Entity model name.
- **modelVersion** (integer, required): Entity model version.
- **requestId** (string, required): ID of the original request.
- **state** (string, required): Entity state.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-stats-get-request.md
# EntityStatsGetRequest
Schema definition for EntityStatsGetRequest
# EntityStatsGetRequest
Schema definition for EntityStatsGetRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityStatsGetRequest.
## Properties
- **model** (object): Optional specifier of the Entity model to calculate statistics for.
- **pointInTime** (string): The point-in-time for statistics in ISO 8601 format. Defaults to current consistency time if not provided.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/entity-stats-response.md
# EntityStatsResponse
Schema definition for EntityStatsResponse
# EntityStatsResponse
Schema definition for EntityStatsResponse
## Schema Viewer
## Description
This schema defines the structure and validation rules for EntityStatsResponse.
## Properties
- **count** (integer, required): Entity count for this model.
- **modelName** (string, required): Entity model name.
- **modelVersion** (integer, required): Entity model version.
- **requestId** (string, required): ID of the original request.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/search-snapshot-status.md
# SearchSnapshotStatus
Schema definition for SearchSnapshotStatus
# SearchSnapshotStatus
Schema definition for SearchSnapshotStatus
## Schema Viewer
## Description
This schema defines the structure and validation rules for SearchSnapshotStatus.
## Properties
- **entitiesCount** (integer): Number of entities collected.
- **expirationDate** (string): Expiration date of the snapshot.
- **snapshotId** (string, required): ID of the snapshot.
- **status** (string, required): Status of the snapshot.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/snapshot-cancel-request.md
# SnapshotCancelRequest
Schema definition for SnapshotCancelRequest
# SnapshotCancelRequest
Schema definition for SnapshotCancelRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for SnapshotCancelRequest.
## Properties
- **snapshotId** (string, required): ID of the snapshot to cancel.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/snapshot-get-request.md
# SnapshotGetRequest
Schema definition for SnapshotGetRequest
# SnapshotGetRequest
Schema definition for SnapshotGetRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for SnapshotGetRequest.
## Properties
- **clientPointTime** (string): Page of time to retrieve the results.
- **pageNumber** (integer): Page number (from 0).
- **pageSize** (integer): Page size.
- **snapshotId** (string, required): ID of the snapshot to retrieve data.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/schemas/search/snapshot-get-status-request.md
# SnapshotGetStatusRequest
Schema definition for SnapshotGetStatusRequest
# SnapshotGetStatusRequest
Schema definition for SnapshotGetStatusRequest
## Schema Viewer
## Description
This schema defines the structure and validation rules for SnapshotGetStatusRequest.
## Properties
- **snapshotId** (string, required): ID of the snapshot.
## Related Schemas
See other schemas in the [search](/reference/schemas/search/) category.
---
## reference/trino.md
# Trino SQL surface
How entities are projected into virtual SQL tables — naming rules, type mapping, polymorphic fields, and JDBC.
Cyoda exposes an analytical SQL surface through a Trino connector. Every
entity model is projected into a set of **virtual SQL tables** so that
nested JSON/XML data can be queried with ordinary relational SQL — no
pre-flattening required.
This page documents the projection rules, the table naming convention, the
column categories, the JSON-to-SQL type mapping, and how polymorphic fields
are handled. For the conceptual framing of the three Cyoda surfaces (REST,
gRPC, Trino SQL), see [APIs and surfaces](/concepts/apis-and-surfaces/).
## Core concepts
Cyoda represents data (JSON/XML) as hierarchical tree structures.
Internally, these trees are decomposed into a collection of `Nodes`, each
capturing a specific branch or subset of the data. This decomposition
provides a uniform representation for querying and traversal — whether
through API-level path queries or via SQL through the Trino connector.
In the Trino view, each node is exposed as a **virtual SQL table**,
allowing nested structures to be queried using familiar relational syntax
without flattening the original hierarchy.
**Key principle**: each `Node` corresponds to exactly **one** SQL table.
### Node model
Each Node has:
- **path**: a string identifying the node's position in the hierarchy
(e.g. `$`, `$.organization.clients`, `$.agreement_data`)
- **fields**: a map of field names to values, where values can be:
- primitive types (string, number, boolean, date, etc.)
- 1-dimensional arrays of primitives
The collection of these nodes forms the internal data model that underpins
the Trino connector. The `TreeNodeEntity` is the object type that
encapsulates this node collection when interacting with the Cyoda API, but
it is a byproduct of this broader structural model rather than its
defining feature.
### Node creation rules
Nodes are derived directly from the structure of the data (such as
JSON/XML):
1. **Root node**: always created with path `$` containing top-level fields.
2. **Array of objects**: each array of objects creates a new node.
3. **Multidimensional arrays**: each dimension beyond one creates a further
node to preserve structural depth.
This consistent mapping enables Cyoda to represent, navigate, and query
arbitrarily nested data structures in a predictable and composable way.
#### Example: node structure
Given a JSON file with these paths:
```
$.organization.name
$.organization.address[]
$.organization.clients[].name
$.organization.clients[].address[]
$.quarterly_metrics[][]
```
The system creates the following nodes:
**Node 1** (Root):
- Path: `$`
- Fields: `.organization.name`, `.organization.address[]`
**Node 2** (Clients array):
- Path: `$.organization.clients[*]`
- Fields: `.name`, `.address[]`
**Node 3** (Agreement data — 2D array, detached):
- Path: `$.quarterly_metrics[*]`
- Fields: `[*]` (detached array containing the inner array elements)
- This is a detached array because `quarterly_metrics` is a 2-dimensional
array.
For example:
```json
{
"organization": {
"name": "Acme Corp",
"address": [
"123 Market Street",
"Suite 400",
"San Francisco, CA 94105"
],
"clients": [
{
"name": "Client A",
"address": ["10 First Ave", "Seattle, WA 98101"]
},
{
"name": "Client B",
"address": ["200 Second St", "Portland, OR 97204"]
}
]
},
"quarterly_metrics": [
[1000, 1200, 900, 1100],
[1300, 1400, 1250, 1500]
]
}
```
### Tree decomposition
Here is a visual representation of the node structure for the example
above, where the corresponding SQL tables are labelled ORGANIZATION,
CLIENTS, and METRICS:
- **`$` (root node → ORGANIZATION)**
- `organization`
- `organization.name`
- `organization.address[]`
- **`organization.clients[]` (clients node → CLIENTS)**
- `organization.clients[].name`
- `organization.clients[].address[]`
- **`quarterly_metrics[][]` (detached 2D array node → METRICS)**
- `quarterly_metrics[*]` (outer arrays)
- `quarterly_metrics[*][*]` (individual cell values)
### Embedded arrays and detached arrays
When JSON/XML contains one-dimensional arrays of primitives within objects,
the system does not create a separate node for such arrays. Instead they
are represented as a single column of an array type. In the table it can
be represented as a column of array type (i.e. `field_array` —
ARRAY[STRING]) or as multiple columns (i.e. `field_0` — STRING, `field_1`
— STRING, ...), depending on the `flatten_array` flag for this field in
the Trino schema settings. That setting also works for system fields,
such as `index`.
When JSON/XML contains multidimensional arrays (arrays of arrays), the
system creates separate nodes for each dimension after the first. This
process is called **array detachment**.
#### Understanding detached arrays
A **detached array** is created when an array contains other arrays as
elements. Each additional dimension becomes a separate node with its own
table.
The primary motivation behind this approach: if a JSON contains a
table-like structure — i.e. a 2-dimensional array of primitives — it
should be represented as a table in Trino. This logic was then extended
and generalized to work for arrays of any number of dimensions larger
than 1.
#### Example 1: simple 2D array
Consider this JSON with a 2-dimensional array:
```json
{
"matrix": [
[1, 2, 3],
[4, 5, 6]
]
}
```
**Nodes created:**
**Node 1** (Root — `$`):
- Path: `$`
- Fields: (none — the matrix field is an array of arrays, so it's not
stored here)
**Node 2** (First dimension — `$.matrix[*]`):
- Path: `$.matrix[*]`
- Fields: `[1]`, `[2]`, `[3]` (these are detached array fields containing
values from the inner arrays, which are represented as rows)
- This node is marked as having a detached array
**Generated tables:**
**Table 1: `mydata`** (from node `$`)
- Contains only special and root columns (no data fields in this case)
**Table 2: `mydata_matrix_array`** (from node `$.matrix[*]` — detached
array)
- Table name breakdown:
- `mydata` = entity name
- `_matrix` = field name from path
- `_array` = suffix indicating this is a detached array table
- Columns:
- `entity_id` (UUID)
- `point_time` (DATE)
- Root columns (creation_date, last_update_date, state)
- `index_0` (INTEGER) — Position in the outer array (0 or 1 in this
example)
- `element_0`, `element_1`, `element_2` (INTEGER) — The three elements
of each inner array
#### Example 2: 3D array
For a 3-dimensional array:
```json
{
"cube": [
[[1, 2], [3, 4]],
[[5, 6], [7, 8]]
]
}
```
**Nodes created:**
**Node 1** (Root — `$`):
- No data fields
**Node 2** (Second dimension — `$.cube[*][*]`, no separate layer for the
first dimension in this case):
- Fields: `[1]`, `[2]`, `[3]`
**Generated tables:**
**Table 1: `mydata`** (from node `$`)
**Table 2: `mydata_cube_2d_array`** (from node `$.cube[*][*]`. Note that
`2d` in this case represents the number of collapsed dimensions, while
the 3rd dimension is detached)
- Columns include `index_0` and `index_1` for positions in both
dimensions
- `element_0`, `element_1` for the two primitive values
#### Example 3: array of objects with nested arrays
```json
{
"data": [
{
"name": "item1",
"values": [10, 20, 30]
},
{
"name": "item2",
"values": [40, 50]
}
]
}
```
**Nodes created:**
**Node 1** (Root — `$`):
- Path: `$`
**Node 2** (Array of objects — `$.data[*]`):
- Path: `$.data[*]`
- Fields: `.name`, `.values[]`
**Generated tables:**
**Table 1: `mydata`** (from node `$`)
**Table 2: `mydata_data`** (from node `$.data[*]`)
- Columns:
- Special and root columns
- `index_0` (INTEGER) — Position in the data array
- `name` (STRING) — From `.name` field
- `values_array` (ARRAY[INTEGER]) or `values_0`, `values_1`, `values_2`
(INTEGER) depending on the `flatten_array` flag for this field in
the Trino schema settings
#### Variable-dimension arrays (mixed depths)
The system can handle arrays where elements have different nesting depths
— some elements are primitives while others are arrays.
**Example:**
```json
{
"data": [
1,
[2, 3],
[4, 5, [6, 7], [8, 9]]
]
}
```
This is a **polymorphic array** containing:
- A primitive value: `1`
- A 1-dimensional array: `[2, 3]`
- A 2-dimensional array: `[4, 5, [6, 7], [8, 9]]`
**Nodes created:**
**Node 1** (Root — `$`)
**Node 2** (Mixed node — `$.data[*]`)
**Node 3** (Mixed node — `$.data[*][*]`)
**Generated tables:**
**Table 1: `mydata`** (from node `$`)
- Columns:
- Special and root columns
- `data[*]` (ARRAY[INTEGER]) — Field for the top-level array elements
(one row with array value `[1]` for the current example)
**Table 2: `mydata_data_array`** (from node `$.data[*]`)
- Contains rows for second-level array elements (2 rows for the current
example)
- Columns:
- Special and root columns
- `index_0` (INTEGER) — Position in the data array
- `element_0`, `element_1` — columns for primitive values at the
second level (for values `2`, `3`, `4`, `5` presented in 2 rows)
**Table 3: `mydata_data_2d_array`** (from array part of `$.data[*][*]`)
- Contains the elements from nested arrays
- Columns:
- Special and root columns
- `index_0`, `index_1` (INTEGER) — Position in the outer array
- `element_0`, `element_1` — Elements from the third-level arrays
(for values `6`, `7`, `8`, `9` presented in 2 rows, with index
values `2,2` and `2,3`)
---
## SQL table generation
### Table naming convention
**Important**: each node in your `TreeNodeEntity` is mapped to exactly
**one** SQL table.
Table names are generated using the following rules:
1. **Base name**: Entity model name (e.g., `prizes`, `companies_details`)
2. **Version suffix** (if version > 1): `_` (e.g., `_2`, `_3`)
3. **Path suffix** (for non-root nodes): Derived from the node path with
`.` and `#` replaced by `_`
- Example: `$.prizes[*]` → `_prizes`
- Example: `$.prizes[*].laureates[*]` → `_prizes_laureates`
4. **Multidimensional suffix**: `_d` where N is the number of `][`
sequences in the *node path* + 1 (Note that this suffix is derived
from the node path, not the field path — it represents the number of
collapsed dimensions. So if we are dealing with a 3-dimensional array
of primitives, the suffix will be `_2d`, as the last dimension is
expanded into columns.)
- Example: `$.data[*][*]` has one `][` → `_2d`
- Example: `$.cube[*][*][*]` has two `][` → `_3d`
5. **Detached array suffix**: `_array` added when the node represents a
detached array
- This happens for multidimensional arrays where inner dimensions are
"detached".
#### Table naming examples
| Entity Name | Version | Node Path | Is Detached Array? | Table Name | Explanation |
|-------------|---------|-----------|-------------------|------------|-------------|
| `prizes` | 1 | `$` | No | `prizes` | Root node |
| `prizes` | 2 | `$` | No | `prizes_2` | Root node, version 2 |
| `prizes` | 1 | `$.prizes[*]` | No | `prizes_prizes` | Array of objects |
| `prizes` | 1 | `$.prizes[*].laureates[*]` | No | `prizes_prizes_laureates` | Nested array of objects |
| `companies` | 1 | `$.matrix[*]` | Yes | `companies_matrix_array` | 2D array — detached |
| `companies` | 1 | `$.cube[*][*]` | Yes | `companies_cube_2d_array` | 3D array — has `][` so gets `_2d`, plus `_array` |
This is the default schema-generation naming; any of these names can be
changed manually in the schema settings.
### Special JSON table
In addition to the structured tables, every entity model gets a special
**JSON table** that contains the complete reconstructed JSON for each
entity:
- **Table name**: `_json` (e.g., `prizes_json`)
- **Purpose**: allows you to retrieve the full original JSON document
:::caution[Performance]
When querying the JSON table, **always include `entity_id` in your WHERE
clause** for optimal performance. Without this predicate, the query may
be significantly slower, especially with large datasets.
:::
**Good practice:**
```sql
SELECT entity FROM prizes_json WHERE entity_id = '';
```
**Avoid:**
```sql
SELECT entity FROM prizes_json; -- This will be slow!
```
---
## Table columns
Every SQL table contains several categories of columns.
### 1. Special columns
These are system-generated columns available in all tables:
| Column Name | Data Type | Description |
|-------------|-----------|-------------|
| `entity_id` | UUID | Unique identifier for the entity (the loaded JSON/XML file) |
| `point_time` | DATE | Allows querying data as it existed at a specific point in time |
The JSON table also includes:
- `entity` (STRING): the complete reconstructed JSON document.
### 2. Root columns
These columns provide metadata about the entity:
| Column Name | Source Field | Data Type | Description |
|-------------|--------------|-----------|-------------|
| `creation_date` | `creationDate` | DATE | When the entity was created in the system |
| `last_update_date` | `lastUpdateTime` | DATE | When the entity was last modified |
| `state` | `state` | STRING | Current workflow state of the entity |
### 3. Index columns
For tables representing array (object or detached) elements (depth > 0),
an `index` column is provided:
- **Column name**: `index`
- **Purpose**: identifies the position of this row in the array hierarchy
- **Structure**: can be flattened into individual columns (`index_0`,
`index_1`, etc.) for multidimensional arrays. Flattened by default.
**Example**: For `$.prizes[*].laureates[*]`:
- `index_0`: Position in the `prizes` array
- `index_1`: Position in the `laureates` array within that prize
### 4. Data columns
These are the actual fields from your JSON/XML data.
#### Primitive fields
Simple fields are mapped directly to columns:
| JSON Path | Field Key | Column Name | Data Type |
|-----------|-----------|-------------|-----------|
| `$.organization.name` | `.organization.name` | `organization_name` | STRING |
| `$.prizes[*].year` | `.year` | `year` | STRING |
| `$.prizes[*].laureates[*].id` | `.id` | `id` | STRING |
**Naming rules:**
- Leading `.` is removed from the field key.
- Reserved field names (like `index`) are prefixed with `_` (e.g.,
`_index`).
#### Array fields
1-dimensional arrays of primitives are handled in two ways:
**Option 1: Array column** (default for homogeneous arrays)
- Column name: `_array`
- Data type: `ARRAY[]`
- Example: `.addresses[]` → `addresses_array` (ARRAY[STRING])
**Option 2: Flattened columns** (for multi-type or ZONED_DATE_TIME arrays)
- Multiple columns created: `_0`, `_1`, etc.
- Each column represents one position in the array.
- Example: `.scores[]` → `scores_0`, `scores_1`, `scores_2` (if array has
3 elements)
---
## Supported data types
The system supports the following data types, which are mapped to
appropriate SQL types for Trino queries. Understanding how these types
are detected from JSON is crucial for working with your data effectively.
**Important**: All data is stored internally in Cyoda with full
precision. Trino provides a SQL query interface to this data, and some
types (like `UNBOUND_DECIMAL` and `UNBOUND_INTEGER`) are represented as
strings in Trino due to Trino's numeric limitations, even though they
are stored as numbers in Cyoda.
### Data type reference table
| System Type | SQL Type | Description | JSON Detection |
|-------------|----------|-------------|----------------|
| STRING | VARCHAR | Text data (max 1024 characters) | Text values, or values that can't be parsed as other types |
| CHAR | CHAR | Single character | Single-character strings |
| BYTE | TINYINT | 8-bit integer (-128 to 127) | Integers in byte range |
| SHORT | SMALLINT | 16-bit integer (-32,768 to 32,767) | Integers in short range |
| INT | INTEGER | 32-bit integer | Integers in int range |
| LONG | BIGINT | 64-bit integer | Integers in long range |
| FLOAT | REAL | Single-precision floating point | Decimals with ≤6 digits precision and scale ≤31 |
| DOUBLE | DOUBLE | Double-precision floating point | Decimals with ≤15 digits precision and scale ≤292 |
| BIG_DECIMAL | DECIMAL(38,18) | High-precision decimal (Trino Int128) | Decimals that fit in Int128 with scale ≤18 |
| UNBOUND_DECIMAL | VARCHAR | Very large/precise decimals (Trino representation) | Decimals exceeding BIG_DECIMAL limits |
| BIG_INTEGER | DECIMAL(38,0) | Large integer (Trino Int128) | Integers that fit in Int128 range |
| UNBOUND_INTEGER | VARCHAR | Very large integers (Trino representation) | Integers exceeding BIG_INTEGER limits |
| BOOLEAN | BOOLEAN | True/false values | JSON boolean values |
| LOCAL_DATE | DATE | Date without time | ISO date strings (e.g., "2024-01-15") |
| LOCAL_TIME | TIME | Time without date | ISO time strings (e.g., "14:30:00") |
| LOCAL_DATE_TIME | TIMESTAMP | Date and time without timezone | ISO datetime strings |
| ZONED_DATE_TIME | TIMESTAMP WITH TIME ZONE | Date and time with timezone | ISO datetime with timezone |
| UUID | UUID | Universally unique identifier | Valid UUID strings |
| TIME_UUID | UUID | Time-based UUID (version 1) | UUID version 1 strings |
| BYTE_ARRAY | VARBINARY | Binary data | Base64-encoded strings |
### How number types are detected from JSON
When the system parses JSON numbers, it follows a specific detection
algorithm to determine the most appropriate type.
#### Integer detection
For whole numbers (no decimal point), the system checks in this order:
1. **BYTE** — if the value is between -128 and 127
2. **SHORT** — if the value is between -32,768 and 32,767
3. **INT** — if the value is between -2,147,483,648 and 2,147,483,647
4. **LONG** — if the value is between
-9,223,372,036,854,775,808 and 9,223,372,036,854,775,807
5. **BIG_INTEGER** — if the value fits in Int128 range (see below)
6. **UNBOUND_INTEGER** — for integers larger than Int128
**Example:**
```json
{
"small": 42, // → BYTE
"medium": 1000, // → SHORT
"large": 100000, // → INT
"veryLarge": 10000000000, // → LONG
"huge": 123456789012345678901234567890 // → BIG_INTEGER or UNBOUND_INTEGER
}
```
#### Decimal detection
For numbers with decimal points, the system checks in this order:
1. **FLOAT** — if precision ≤ 6 digits and scale is between -31 and 31
2. **DOUBLE** — if precision ≤ 15 digits and scale is between -292 and
292
3. **BIG_DECIMAL** — if the value fits in Int128 decimal constraints
(see below)
4. **UNBOUND_DECIMAL** — for decimals exceeding BIG_DECIMAL limits
**Example:**
```json
{
"price": 19.99, // → FLOAT (6 digits precision)
"precise": 123.456789012345, // → DOUBLE (15 digits precision)
"veryPrecise": 123456789012345.123456789012345, // → BIG_DECIMAL
"extremelyPrecise": 1.23456789012345678901234567890123456789 // → UNBOUND_DECIMAL
}
```
### Understanding BIG_DECIMAL and UNBOUND_DECIMAL
#### BIG_DECIMAL (Trino Int128 decimal)
**BIG_DECIMAL** is bounded by Trino's maximum numeric capacity, which
uses a 128-bit integer (Int128) with a **fixed scale of 18**.
**Constraints:**
- **Scale**: must be ≤ 18 decimal places
- **Precision**: must be ≤ 38 total digits (with some complexity — see
below)
- **Range**: approximately ±170,141,183,460,469,231,731.687303715884105727
**Detailed precision rules:**
The system uses two precision checks:
1. **Strict check**: `precision ≤ 38` AND `exponent ≤ 20` (where
exponent = precision - scale)
2. **Loose check**: `precision ≤ 39` AND `exponent ≤ 21` AND the value
fits when scaled to 18 decimal places
**Examples:**
```json
{
"fits": 12345678901234567890.123456789012345678, // ✓ BIG_DECIMAL (38 digits, scale 18)
"tooManyDecimals": 123.1234567890123456789, // ✗ UNBOUND_DECIMAL (scale > 18)
"tooLarge": 999999999999999999999.999999999999999999 // ✗ UNBOUND_DECIMAL (exceeds Int128)
}
```
#### UNBOUND_DECIMAL
**UNBOUND_DECIMAL** is used for decimal values that exceed Trino's
numeric representation limits.
**Storage vs representation:**
- **In Cyoda**: stored as full-precision BigDecimal numbers with all
numeric operations available in workflows.
- **In Trino SQL**: represented as VARCHAR (strings) due to Trino's
Int128 limitations.
**When a decimal becomes UNBOUND_DECIMAL:**
- Scale > 18 decimal places.
- Total value exceeds Int128 range.
- Precision and exponent exceed the limits.
**Important for SQL queries**: when querying UNBOUND_DECIMAL columns in
Trino, treat them as VARCHAR, not as numeric types. Numeric operations
are not available in SQL queries for these fields.
```sql
-- Correct: treat as string in Trino SQL
SELECT * FROM mytable WHERE unbound_decimal_field = '123.12345678901234567890123456789';
-- Incorrect: cannot use numeric operations in Trino SQL
SELECT * FROM mytable WHERE unbound_decimal_field > 100; -- This will fail!
-- Note: numeric operations ARE available in Cyoda workflows, just not in Trino SQL queries.
```
### Understanding BIG_INTEGER and UNBOUND_INTEGER
#### BIG_INTEGER (Trino Int128)
**BIG_INTEGER** is bounded by Trino's 128-bit integer capacity.
**Constraints:**
- **Range**: -170,141,183,460,469,231,731,687,303,715,884,105,728 to
170,141,183,460,469,231,731,687,303,715,884,105,727
- This is 2127 - 1 for the maximum and -2127 for
the minimum.
**Examples:**
```json
{
"fits": 123456789012345678901234567890, // ✓ BIG_INTEGER (within Int128)
"tooLarge": 999999999999999999999999999999999999999 // ✗ UNBOUND_INTEGER (exceeds Int128)
}
```
#### UNBOUND_INTEGER
**UNBOUND_INTEGER** is used for integer values that exceed the Int128
range.
**Storage vs representation:**
- **In Cyoda**: stored as full-precision BigInteger numbers with all
numeric operations available in workflows.
- **In Trino SQL**: represented as VARCHAR (strings) due to Trino's
Int128 limitations.
**Important for SQL queries**: when querying UNBOUND_INTEGER columns in
Trino, treat them as VARCHAR. Numeric operations are not available in
SQL queries for these fields.
```sql
-- Correct: treat as string in Trino SQL
SELECT * FROM mytable WHERE unbound_integer_field = '999999999999999999999999999999999999999';
-- Incorrect: cannot use numeric operations in Trino SQL
SELECT * FROM mytable WHERE unbound_integer_field > 1000; -- This will fail!
-- Note: numeric operations ARE available in Cyoda workflows, just not in Trino SQL queries.
```
### Type detection priority
When parsing JSON, the system always tries to use the **most specific
type** that fits the value:
1. **Smallest integer type** that can hold the value
(BYTE → SHORT → INT → LONG → BIG_INTEGER → UNBOUND_INTEGER).
2. **Smallest decimal type** that can hold the value
(FLOAT → DOUBLE → BIG_DECIMAL → UNBOUND_DECIMAL).
3. **STRING** as a fallback for any value that can't be parsed as a more
specific type.
### String parsing
When a JSON value is a string, the system attempts to parse it as other
types in this priority order:
1. **Temporal types** (dates, times, datetimes).
2. **UUID types**.
3. **Boolean** ("true" or "false").
4. **Numeric types** (if the string contains a valid number).
5. **STRING** (if none of the above match).
**Example:**
```json
{
"date": "2024-01-15", // → LOCAL_DATE
"uuid": "550e8400-e29b-41d4-a716-446655440000", // → UUID
"bool": "true", // → BOOLEAN
"text": "hello world" // → STRING
}
```
---
## Polymorphic fields
### What are polymorphic fields?
A **polymorphic field** occurs when the same field path has different
data types across different elements in your JSON/XML data. This commonly
happens in arrays of objects where the same field name contains different
types of values.
### Example of polymorphic data
```json
{
"items": [
{ "value": "text string" },
{ "value": 123 },
{ "value": 45.67 }
]
}
```
In this example, the field `$.items[*].value` is polymorphic because it
contains:
- A STRING in the first element
- An INTEGER in the second element
- A DOUBLE in the third element
### How polymorphic fields are handled
When the system detects polymorphic fields, it automatically determines a
**common data type** that can accommodate all the different types
encountered. The logic:
1. **Check for compatible types**: the system first checks if all types
are compatible and can be converted to a common type.
2. **Find the lowest common denominator**: it selects the most general
type that all values can be converted to.
3. **Fall back to STRING**: if no common numeric or date type exists,
the field is stored as STRING.
### Type compatibility rules
The system recognizes certain types as compatible and will convert them
to a common type using **widening conversions**. It always chooses the
type that can represent all values without loss of information.
#### Numeric type hierarchy
**Integer types** (from smallest to largest):
- BYTE → SHORT → INT → LONG → BIG_INTEGER → UNBOUND_INTEGER
**Decimal types** (from smallest to largest):
- FLOAT → DOUBLE → BIG_DECIMAL → UNBOUND_DECIMAL
**Cross-hierarchy conversions:**
- Any integer type can widen to any larger integer type or any decimal
type.
- Any decimal type can widen to a larger decimal type.
- UNBOUND_DECIMAL is the widest numeric type (can hold any number).
#### Common type conversion examples
| Types Found | Common Type Used | Explanation |
|-------------|------------------|-------------|
| BYTE, SHORT | SHORT | Wider integer type |
| INT, LONG | LONG | Wider integer type |
| BYTE, DOUBLE | DOUBLE | Integer widens to decimal |
| INT, BIG_DECIMAL | BIG_DECIMAL | Integer widens to decimal |
| LONG, UNBOUND_INTEGER | UNBOUND_INTEGER | Wider integer type |
| FLOAT, DOUBLE | DOUBLE | Wider decimal type |
| DOUBLE, BIG_DECIMAL | UNBOUND_DECIMAL | DOUBLE can't fit in BIG_DECIMAL's fixed scale |
| BIG_INTEGER, BIG_DECIMAL | BIG_DECIMAL | Integer widens to decimal |
| BIG_DECIMAL, UNBOUND_DECIMAL | UNBOUND_DECIMAL | Wider decimal type |
| BIG_INTEGER, UNBOUND_INTEGER | UNBOUND_INTEGER | Wider integer type |
| Any numeric, STRING | STRING | Incompatible — falls back to STRING |
| BOOLEAN, INT | STRING | Incompatible — falls back to STRING |
| UUID, STRING | STRING | Incompatible — falls back to STRING |
#### Temporal type conversions
Temporal types have a resolution hierarchy, where lower-resolution types
(like YEAR) can be converted to higher-resolution types (like
LOCAL_DATE) by adding default values for the missing components.
**Resolution hierarchy:**
- YEAR → YEAR_MONTH → LOCAL_DATE → LOCAL_DATE_TIME → ZONED_DATE_TIME
- LOCAL_TIME → LOCAL_DATE_TIME → ZONED_DATE_TIME
:::note
The LOCAL_DATE_TIME and ZONED_DATE_TIME types are considered incompatible
with each other because of type-detection ambiguity: since any value of
these types can be parsed as the other, such polymorphism cannot occur
automatically.
:::
When polymorphic temporal fields are detected, the system converts all
values to the highest-resolution type found.
##### Upscaling (low resolution → high resolution)
When converting from a lower-resolution type to a higher-resolution
type, the system adds default values for the missing components:
| From Type | To Type | Conversion Rule | Example |
|-----------|---------|-----------------|---------|
| YEAR | YEAR_MONTH | Add month = 1 (January) | `2024` → `2024-01` |
| YEAR_MONTH | LOCAL_DATE | Add day = 1 (first day of month) | `2024-01` → `2024-01-01` |
| LOCAL_DATE | LOCAL_DATE_TIME | Add time = 00:00:00 (midnight) | `2024-01-01` → `2024-01-01T00:00:00` |
| LOCAL_TIME | LOCAL_DATE_TIME | Add date = 1970-01-01 (epoch) | `14:30:00` → `1970-01-01T14:30:00` |
**Multi-step conversions:**
The system can perform multi-step conversions by chaining the rules
above:
- **YEAR → LOCAL_DATE**: `2024` → `2024-01` → `2024-01-01`
- **YEAR → LOCAL_DATE_TIME**: `2024` → `2024-01` → `2024-01-01` →
`2024-01-01T00:00:00`
- **YEAR_MONTH → LOCAL_DATE_TIME**: `2024-06` → `2024-06-01` →
`2024-06-01T00:00:00`
##### Downscaling (high resolution → low resolution)
When converting from a higher-resolution type to a lower-resolution
type, the system truncates the extra precision:
| From Type | To Type | Conversion Rule | Example |
|-----------|---------|-----------------|---------|
| YEAR_MONTH | YEAR | Extract year only | `2024-06` → `2024` |
| LOCAL_DATE | YEAR_MONTH | Extract year and month | `2024-06-15` → `2024-06` |
| LOCAL_DATE_TIME | LOCAL_DATE | Extract date part | `2024-06-15T14:30:00` → `2024-06-15` |
| LOCAL_DATE_TIME | LOCAL_TIME | Extract time part | `2024-06-15T14:30:00` → `14:30:00` |
Downscaling is primarily used internally for query optimization (e.g.
when processing a query condition against a [YEAR, DATE] polymorphic
field, the query condition is downscaled to YEAR for the YEAR part of
the target field). In polymorphic fields represented in Trino, the
system always upscales to the highest-resolution type.
##### Polymorphic temporal field examples
**Example 1: Mixed date resolutions**
```json
{
"events": [
{ "date": "2024" }, // YEAR
{ "date": "2024-06" }, // YEAR_MONTH
{ "date": "2024-06-15" } // LOCAL_DATE
]
}
```
The field `$.events[*].date` is polymorphic with types: YEAR,
YEAR_MONTH, LOCAL_DATE.
**Common type**: LOCAL_DATE (highest resolution).
**Trino SQL values after conversion:**
- `"2024"` → `2024-01-01` (January 1st, 2024)
- `"2024-06"` → `2024-06-01` (June 1st, 2024)
- `"2024-06-15"` → `2024-06-15` (unchanged)
**Example 2: Date and DateTime mix**
```json
{
"timestamps": [
{ "when": "2024-01-15" }, // LOCAL_DATE
{ "when": "2024-01-15T14:30:00" } // LOCAL_DATE_TIME
]
}
```
**Common type**: LOCAL_DATE_TIME.
**Trino SQL values after conversion:**
- `"2024-01-15"` → `2024-01-15T00:00:00` (midnight)
- `"2024-01-15T14:30:00"` → `2024-01-15T14:30:00` (unchanged)
**Example 3: Time and DateTime mix**
```json
{
"schedule": [
{ "time": "14:30:00" }, // LOCAL_TIME
{ "time": "2024-01-15T14:30:00" } // LOCAL_DATE_TIME
]
}
```
**Common type**: LOCAL_DATE_TIME.
**Trino SQL values after conversion:**
- `"14:30:00"` → `1970-01-01T14:30:00` (epoch date + time)
- `"2024-01-15T14:30:00"` → `2024-01-15T14:30:00` (unchanged)
##### Important considerations for temporal polymorphism
1. **Default values matter**: When YEAR is converted to LOCAL_DATE, it
becomes January 1st. This means:
```sql
-- If the field contains polymorphic YEAR and LOCAL_DATE values
SELECT * FROM events WHERE date = '2024-01-01'
-- This will match both "2024" (converted to 2024-01-01) and "2024-01-01"
```
2. **Loss of semantic meaning**: A YEAR value of `"2024"` represents the
entire year, but when converted to LOCAL_DATE it becomes `2024-01-01`,
which represents a specific day. The original semantic meaning (the
entire year) is lost.
3. **Query implications**: when querying polymorphic temporal fields, be
aware of the conversion rules:
```sql
-- Original data: ["2024", "2024-06-15"]
-- Stored as LOCAL_DATE: [2024-01-01, 2024-06-15]
-- This query will NOT match the original "2024" value
SELECT * FROM events WHERE date >= '2024-06-15'
-- Because "2024" was converted to 2024-01-01, which does not include every day of the year
```
4. **Best practice**: if you need to preserve the original resolution,
consider using separate fields:
```json
{
"yearOnly": "2024",
"exactDate": "2024-06-15"
}
```
##### Polymorphic temporal conversion summary
**Common polymorphic combinations:**
| Types Found | Common Type | Conversion Applied |
|-------------|-------------|-------------------|
| YEAR, YEAR_MONTH | YEAR_MONTH | YEAR → YEAR_MONTH (add month=1) |
| YEAR, LOCAL_DATE | LOCAL_DATE | YEAR → YEAR_MONTH → LOCAL_DATE |
| YEAR_MONTH, LOCAL_DATE | LOCAL_DATE | YEAR_MONTH → LOCAL_DATE (add day=1) |
| LOCAL_DATE, LOCAL_DATE_TIME | LOCAL_DATE_TIME | LOCAL_DATE → LOCAL_DATE_TIME (add time=00:00:00) |
| LOCAL_TIME, LOCAL_DATE_TIME | LOCAL_DATE_TIME | LOCAL_TIME → LOCAL_DATE_TIME (add date=1970-01-01) |
### Important notes
**Type conversion**: when a polymorphic field is stored as a common type
(e.g., STRING), all values are converted to that type. This means:
- Numeric values may be stored as strings: `"123"` instead of `123`.
- You may need to cast values in your SQL queries:
`CAST(value AS INTEGER)`.
### Best practices for polymorphic data
1. **Consistent typing**: when possible, maintain consistent data types
for the same field across all array elements.
2. **Explicit casting**: when querying polymorphic fields that were
converted to STRING, use explicit CAST operations with caution — some
values may not be castable.
3. **Understand your data**: use the schema-inspection API to see which
fields are polymorphic and what their common type is.
4. **Consider restructuring**: if you have control over the data
structure, consider using different field names for different types.
---
## Complete example
### Input JSON saved under model "prizes" version 1
```json
{
"extraction-date": "2024-01-15",
"prizes": [
{
"year": "2023",
"category": "Physics",
"laureates": [
{
"id": "1001",
"firstname": "Anne",
"surname": "L'Huillier",
"motivation": "for experimental methods...",
"share": 3
},
{
"id": "1002",
"firstname": "Pierre",
"surname": "Agostini",
"motivation": "for experimental methods...",
"share": 3
}
]
}
]
}
```
### Generated tables
#### Table 1: `prizes` (Root node: `$`)
| Column Name | Data Type | Category | Description |
|-------------|-----------|----------|-------------|
| `entity_id` | UUID | SPECIAL | Entity identifier |
| `point_time` | DATE | SPECIAL | Query time point |
| `creation_date` | DATE | ROOT | Entity creation date |
| `last_update_date` | DATE | ROOT | Entity last update |
| `state` | STRING | ROOT | Entity state |
| `extraction_date` | DATE | DATA | From `.extraction-date` |
#### Table 2: `prizes_prizes` (Node: `$.prizes[*]`)
| Column Name | Data Type | Category | Description |
|-------------|-----------|----------|-------------|
| `entity_id` | UUID | SPECIAL | Entity identifier |
| `point_time` | DATE | SPECIAL | Query time point |
| `creation_date` | DATE | ROOT | Entity creation date |
| `last_update_date` | DATE | ROOT | Entity last update |
| `state` | STRING | ROOT | Entity state |
| `index_0` | INTEGER | INDEX | Position in prizes array |
| `year` | STRING | DATA | From `.year` |
| `category` | STRING | DATA | From `.category` |
#### Table 3: `prizes_prizes_laureates` (Node: `$.prizes[*].laureates[*]`)
| Column Name | Data Type | Category | Description |
|-------------|-----------|----------|-------------|
| `entity_id` | UUID | SPECIAL | Entity identifier |
| `point_time` | DATE | SPECIAL | Query time point |
| `creation_date` | DATE | ROOT | Entity creation date |
| `last_update_date` | DATE | ROOT | Entity last update |
| `state` | STRING | ROOT | Entity state |
| `index_0` | INTEGER | INDEX | Position in prizes array |
| `index_1` | INTEGER | INDEX | Position in laureates array |
| `id` | STRING | DATA | From `.id` |
| `firstname` | STRING | DATA | From `.firstname` |
| `surname` | STRING | DATA | From `.surname` |
| `motivation` | STRING | DATA | From `.motivation` |
| `share` | TINYINT | DATA | From `.share` |
#### Table 4: `prizes_json` (Special JSON table)
| Column Name | Data Type | Category | Description |
|-------------|-----------|----------|-------------|
| `entity_id` | UUID | SPECIAL | Entity identifier |
| `point_time` | DATE | SPECIAL | Query time point |
| `creation_date` | DATE | ROOT | Entity creation date |
| `last_update_date` | DATE | ROOT | Entity last update |
| `state` | STRING | ROOT | Entity state |
| `entity` | STRING | SPECIAL | Complete JSON document |
---
## Querying your data
### Example queries
**1. Get all prizes from 2023:**
```sql
SELECT * FROM prizes_prizes WHERE year = '2023';
```
**2. Find all laureates with their prize information:**
```sql
SELECT
p.year,
p.category,
l.firstname,
l.surname,
l.motivation
FROM prizes_prizes p
JOIN prizes_prizes_laureates l
ON p.entity_id = l.entity_id
AND p.index_0 = l.index_0;
```
**3. Retrieve the full JSON for a specific entity:**
```sql
SELECT entity FROM prizes_json WHERE entity_id = '';
```
**4. Query data as it existed at a specific time:**
```sql
SELECT * FROM prizes_prizes
WHERE point_time = TIMESTAMP '2024-01-01 00:00:00';
```
---
## Best practices
1. **Use index columns for joins**: when joining tables from nested
arrays, always join on `entity_id` and matching index columns.
2. **Understand your schema**: use the schema-generation API to see
exactly what tables and columns are created for your data.
3. **Leverage the JSON table carefully**: for complex queries or when
you need the full document, query the `_json` table, but **always
include `entity_id` in the WHERE clause** for performance.
4. **Filter by `entity_id`**: for better performance, include
`entity_id` in your WHERE clause when possible, especially when
querying the JSON table.
5. **Use `point_time` wisely**: only specify `point_time` when you need
historical data; omit it for current data.
---
## Schema management
You can create any number of SQL schemas, each with a different set of
tables and columns.
### Via the HTTP API
You can manage and inspect your SQL schemas using the REST API:
- **Create default schema**: `PUT /sql/schema/putDefault/{schemaName}`
- **Get schema**: `GET /sql/schema/{schemaId}`
- **List all schemas**: `GET /sql/schema/listAll`
- **Generate tables from entity model**:
`GET /sql/schema/genTables/{entityModelId}`
- **Update tables**: `POST /sql/schema/updateTables/{entityModelId}`
For the full grammar, see the [REST API reference](/reference/api/).
## Connecting via JDBC
The JDBC connection string follows this pattern:
```
jdbc:trino://:443/cyoda/
```
where `` is the host serving the Trino connector — on
[Cyoda Cloud](/cyoda-cloud/), a managed endpoint per environment — and
`your_schema` is the schema name you configured.
For authentication credentials and technical-user setup, see
[Authentication and identity](/concepts/authentication-and-identity/).
## Gaps in this reference
The following are intentionally not yet specified here and are tracked as
upstream asks:
- **Supported SQL dialect scope** — which Trino features are guaranteed
supported versus best-effort.
- **Push-down matrix** — which predicates, projections, and aggregates
execute in the underlying store versus requiring a full scan.
- **Consistency / isolation** of long-running queries relative to
concurrent transition writes.
- **Performance envelope** — rows/sec scan rates, partitioning, and
per-tenant query limits.
See the
[cyoda-go issue tracker](https://github.com/Cyoda/cyoda-go/issues?q=is%3Aissue+label%3Acyoda-docs)
for progress.
---
## releases.md
# Releases
Release notes and changelog for Cyoda-Go — whats new in each version, newest first.
Release notes for **Cyoda-Go**, newest first. Each entry summarizes the
headline features and links to the full notes, including breaking changes
and upgrade guidance.
The authoritative, line-by-line changelog lives alongside the source in
the [`cyoda-go` repository](https://github.com/Cyoda/cyoda-go/blob/main/CHANGELOG.md).
The notes here add context, examples, and upgrade guidance on top of it.
---
## releases/v0-8-1.md
# Cyoda-Go v0.8.1
Federated identity, point-in-time statistics, OpenAPI-conformant IAM, and a new home on GitHub.
_Released 23 June 2026 · 52 issues delivered_
This is our largest release since the project went public. This cycle
focuses heavily on identity management and historical data analytics,
while resolving key API and SPI parity gaps with Cyoda Cloud. It is also
our first release under our new GitHub home.
## 🏠 We are now github.com/Cyoda
Our GitHub organization has been renamed from **Cyoda-platform** to
**Cyoda**, aligning the organization, the platform, and the company under
a single name.
While GitHub automatically redirects existing clones, links, and Go
module imports, we recommend updating your local remotes when convenient:
```bash
git remote set-url origin https://github.com/Cyoda/cyoda-go.git
```
The Go module path remains **unchanged** — no `go.mod` updates are
required.
## 📌 Why v0.8.1 and not v0.8.0
There is no v0.8.0 release. During release preparation, the
`cyoda-go-spi` v0.8.0 tag was published prematurely before it was
finalized. To keep versioning for both `cyoda-go` and `cyoda-go-spi` in
lock-step, we bumped both components directly to v0.8.1.
## ✨ Highlights
- **Federated Identity (OIDC):** Securely validate external OpenID
Connect tokens (e.g. Auth0, Zitadel, Keycloak) with multi-issuer
chaining and cross-tenant safety.
- **Point-in-Time Statistics:** Execute high-performance historical
queries to aggregate data and counts exactly as they existed at any
moment in the past.
- **OpenAPI-Conformant IAM:** Manage signing keys and machine-to-machine
technical clients via fully implemented, standard-compliant admin
endpoints.
- **Richer Workflow Configurations:** Attach custom metadata annotations
to workflows to drive UI/UX or custom RBAC policies.
- **Strict Import Validation:** Eliminate silent typos and structural
errors with immediate runtime rejection of invalid schemas.
## 🔍 Details
### 🔐 Federated identity arrives (OIDC)
Cyoda-Go can now validate tokens from **external OpenID Connect (OIDC)
providers** on a per-tenant basis. You can connect your preferred
identity provider (IdP) — such as Auth0, Zitadel, Keycloak, Entra, or any
spec-compliant OIDC issuer — and register it using our new REST
endpoints:
- **Per-tenant OIDC provider registry:** Includes seven new endpoints
under `/oauth/oidc/providers` to register, list, get, update,
invalidate, reactivate, delete, and reload providers.
- **Chained multi-issuer validation:** Validates against the local issuer
first, falling back to registered OIDC providers with support for
per-provider issuers, `expectedAudiences`, and `rolesClaim` overrides.
- **Support for object-shaped `rolesClaim`:** Correctly maps role
assertions nested inside a claim object (e.g. Zitadel project roles) to
Cyoda roles.
- **Safe-by-default cross-tenant routing:** Prevents token collisions
when multiple tenants share a physical IdP. Tokens are explicitly
disambiguated by audience; ambiguous tokens are rejected rather than
guessed. Operators sharing an IdP must configure distinct
`expectedAudiences` per registration.
- **SSRF-hardened discovery:** Enforces pinned-issuer validation at fetch
time, utilizes private-network guards, and respects configurable
timeouts.
- **Cluster-wide cache eviction:** Propagates provider updates across
nodes, invalidating the JWKS cache on all peers.
- **Built-in observability:** Out-of-the-box Prometheus metrics are now
emitted by the OIDC subsystem.
Run `cyoda help auth` to get started.
### 🔑 IAM endpoints now conform to the OpenAPI spec
The previously stubbed IAM surface is now fully implemented. Signing-key
and client management are live at their spec-conformant paths with
standardized DTOs:
- **`/oauth/keys/keypair/*` and `/oauth/keys/trusted/*`:** Provides 10
admin endpoints to manage signing keypairs and trusted external keys.
Storage-layer isolation is enforced per tenant, and a finite-validity
bootstrap key warns operators prior to expiration.
- **`/clients`:** Manages machine-to-machine (technical user) clients,
including creation, listing, deletion, and secret rotation.
### 📊 Point-in-time grouped statistics
A new grouped-statistics query answers: _"How many entities match X,
broken down by Y?"_ This query returns counts and numerical aggregates
(sum, avg, min, max, stdev) over any data field or workflow state,
filtered by the standard search Condition DSL. To optimize performance,
it returns only the calculated metrics, never the underlying entity
bodies.
```http
POST /entity/stats/{entityName}/{modelVersion}/query
```
Two design choices make this more powerful than a standard `GROUP BY`
database query:
1. **Snapshot/point-in-time capabilities:** Query the data exactly as it
existed at any instant in the past. This lets you easily compute
end-of-quarter counts, historical audit roll-ups, or audit questions
like _"how many claims were pending at midnight?"_
2. **Simplified domain modeling:** In an entity-per-item model, tracking
metrics (like "available units per variant") often requires building
and maintaining a derived counter entity that processors must update
on every state transition. Computing these aggregates on demand from
existing entities eliminates the need for these derived entities,
keeping your architecture cleaner.
### 🧩 Richer workflow configuration
- **Client-owned annotations:** Attach arbitrary JSON metadata (up to
64 KB per field) to workflows, states, and transitions. This lets
applications attach functionally meaningful information directly to the
workflow graph — to drive frontend UI/UX, trigger custom backend
processing, enforce application-level RBAC controls, and more. These
annotations are stored and round-tripped faithfully without engine
interpretation.
- **Scheduled state transitions:** Introduces the configuration schema
and SPI required to fire transitions based on time.
- **gRPC context pass-through:** Passes `ProcessorConfig.Context` directly
through to external gRPC processors to align with Cyoda Cloud.
- **`RetryPolicy` validation:** Validates retry policies and exposes an
`inbound-retryable` flag to callers.
- **Decoupled execution and timing:** Clearly separates a processor's
**execution location** from its **scheduled-transition timing** in both
the schema and the help documentation.
### 🛡️ Strict workflow imports
To prevent typos and structural errors from failing silently at import
time and causing unexpected runtime behavior, v0.8.1 introduces strict
validation. The engine now rejects structurally invalid graphs (such as
dangling states or duplicate names), unknown JSON fields (e.g. spelling
`transitions` with a typo), and silent empty-array deletions. It also
enforces workflow schema version 1.1 and respects `"active": false` flags
during roundtrips.
### 🧱 SPI & operational polish
- **Transaction-state sentinel errors:** The storage SPI now exposes
typed sentinel errors (rolled back, already closed, already committed)
to allow plugins and callers to handle transaction states precisely.
- **Helm chart updates:** Adds an optional, separate migration DSN
(`migrate.postgres`) so you can run schema migrations using a
connection with different privileges than the runtime environment.
- **Targeted CI runs:** CI now runs the full test suite on `release/`
branches, ensuring release candidates receive the same validation as
the main branch.
- **Dependency maintenance:** Upgraded dependencies across root and
plugin modules (including OpenTelemetry, pgx, x/crypto, kin-openapi,
and testcontainers) alongside Go toolchain updates to address standard
library CVEs.
This release intentionally tightens several API and schema contracts.
Please review the following breaking changes before upgrading:
- **Workflow payload schema version:** All workflow payloads must now
declare `version: "1.1"`. Payloads using `"1.0"` or bare `"1"` will be
rejected. You must regenerate your import payloads.
- **Strict workflow validation:** You must clean up any unknown or
misspelled fields in your workflow configurations. Empty-array no-ops
are no longer allowed in `REPLACE`/`ACTIVATE` modes.
- **Trusted-key registration:** This feature is now disabled by default.
You must opt in explicitly by setting
`CYODA_IAM_TRUSTED_KEY_REGISTRATION_ENABLED=true`.
- **Signing key expiration:** Signing keys now expire after a default of
365 days. Deployments must implement rotation. The startup banner will
display a warning starting 30 days before key expiration.
- **Cryptographic algorithms:** Only `RS256` is supported for signing and
verification in this release. Other algorithms defined in the
specification will be rejected at runtime.
- **OIDC tenant validation:** OIDC registration now requires a
UUID-formatted tenant. If you are bootstrapping deployments on the
literal string `default-tenant`, you must migrate to a tenant UUID.
For the complete and authoritative list of breaking changes, behavioral
updates, and known limitations (such as in-memory M2M client persistence
and rollback hazards), consult the
[CHANGELOG](https://github.com/Cyoda/cyoda-go/blob/main/CHANGELOG.md#081--2026-06-23).
## 🚀 Resources & getting started
For complete installation guides, building from source, detailed system
architectures, and guidance on running the engine locally or in
production, explore our core project resources:
- [**Cyoda Hub (cyoda.dev)**](https://cyoda.dev) — the primary portal for
the Cyoda ecosystem, community links, and major updates.
- [**Cyoda Documentation (docs.cyoda.net)**](https://docs.cyoda.net) —
quick-starts, configuration schemas, API references, deployment
architectures, and operations guides.
- [**GitHub Project (github.com/Cyoda/cyoda-go)**](https://github.com/Cyoda/cyoda-go)
— view the source code, check build requirements, or download specific
binary releases, packages, and cryptographic checksums directly from
the [v0.8.1 release tag](https://github.com/Cyoda/cyoda-go/releases/tag/v0.8.1).
## 💬 Feedback
If you find a bug, encounter a parity gap, or have a feature request,
please open an issue or start a thread in our
[GitHub Discussions](https://github.com/Cyoda/cyoda-go/discussions) — and
feel free to join the conversation on
[Discord](https://discord.com/invite/95rdAyBZr2). Thank you for building
with Cyoda-Go!
---
## releases/v0-8-2.md
# Cyoda-Go v0.8.2
Contract-true OpenAPI, richer entity queries, and transaction-joined compute callbacks.
_Released 8 July 2026 · 10 issues delivered_
This release sharpens the API contract and deepens the entity data layer.
The OpenAPI spec was reconciled end-to-end so that what the document
promises is exactly what the server does. Alongside that, entity reads and
writes gain sorting, partial updates, composite uniqueness, and a unified
point-in-time rule — while compute-node callbacks can now join the workflow
transaction that dispatched them.
## ✨ Highlights
- **Search result sorting:** Order search results by any scalar data field
or meta field, ascending or descending, with canonical cross-backend
ordering.
- **Partial entity updates (PATCH):** Update only the fields that changed
with RFC 7386 merge-patch semantics — no more accidentally destroying
fields you did not send.
- **Composite unique keys:** Declare multi-field uniqueness constraints on
an entity model, enforced on create and update.
- **Faster PostgreSQL search:** Predicates now push down into SQL instead of
loading and filtering every entity of a model in memory.
- **Transaction-joined compute callbacks:** Processor and criteria callbacks
from a compute node now join the originating workflow transaction.
- **Renderer annotations on processors & criteria:** Attach display
metadata to every workflow element for visualisers and condition builders.
- **Contract-true OpenAPI:** The spec was reconciled with the server —
error codes, response envelopes, and body shapes now match reality.
## 🔍 Details
### 🔎 Search: sorting and pushdown
Both search endpoints
(`POST /api/search/direct/{entityName}/{modelVersion}` and the async
`/api/search/async/{entityName}/{modelVersion}` variant)
now accept `sort` query parameters (HTTP) or a structured `orderBy` array
(gRPC). The HTTP grammar is `[@]path[:asc|desc]` — a bare dotted path for a
scalar data field, an `@`-prefixed name for a meta field (`state`,
`creationDate`, `lastUpdateTime`, `transitionForLatestSave`, `transactionId`,
`id`).
Ordering is **canonical across every backend**: Text by byte order, Numeric
by IEEE-754 double, Bool as `false < true`, and Temporal chronologically.
Absent or null values sort last, and `entity_id` is always the final
tiebreaker. Unsortable, array, or unknown paths are rejected with
`400 INVALID_FIELD_PATH`. The sort-key count is capped by
`CYODA_SEARCH_MAX_SORT_KEYS` (default `16`).
Separately, **PostgreSQL search now pushes supported predicates into SQL** —
JSONB extraction plus numeric, range, and string comparisons run in the
database, and `LIMIT`/`OFFSET` are pushed down when no residual filtering
remains. Non-pushable operators (regex, case-insensitive) are post-filtered
as rows stream. This eliminates full-model scans and per-document decode; it
is a constant-factor win, not a JSON-path-index feature (indexing queried
paths remains a separate operational step). SQLite already did this; the
memory backend filters in memory by design.
### ✏️ Partial entity updates (PATCH)
A first-class partial-update capability closes a common data-loss footgun:
the existing `PUT` update has **wholesale-replace** semantics, so any field
omitted from the request was silently destroyed.
```http
PATCH /api/entity/{format}/{entityId}
PATCH /api/entity/{format}/{entityId}/{transition}
```
The request body is a sparse JSON object applied to the **stored** entity
with RFC 7386 (`application/merge-patch+json`) semantics: a non-null key
overwrites, an explicit `null` deletes the key, and an omitted key is left
untouched. JSON-only (`XML` ⇒ `415`); RFC 6902 JSON Patch is recognised but
returns `501` for now.
Unlike `PUT`, **`If-Match` is required** — the merge is applied relative to
the base you read, so patching a stale base risks a lost update. The token is
the `meta.transactionId` from your last `GET`. A missing `If-Match` returns
`428 PRECONDITION_REQUIRED`; a stale one returns `412`. The merged result is
validated strictly against the model schema — a PATCH never extends the
model, even in an extend-permitting mode.
### 🔑 Composite unique keys
Entity models can now declare one or more composite unique keys via
`PUT /model/{entityName}/{modelVersion}/unique-keys` (UNLOCKED models only).
Each key is an ordered set of scalar field paths; uniqueness is scoped to
`(tenant, model, version)` over live entities. The null rule is
all-or-nothing: all fields null or absent ⇒ exempt; partial ⇒
`422 INVALID_UNIQUE_KEY`; all present ⇒ enforced on create and update. String
comparison is byte-exact, and soft-delete frees the value-set. Supported by
the memory, sqlite, and postgres backends; the commercial backend returns
`422 COMPOSITE_KEY_UNSUPPORTED` until its own support lands.
New error codes: `UNIQUE_VIOLATION` (409), `INVALID_UNIQUE_KEY` (422),
`COMPOSITE_KEY_UNSUPPORTED` (422), `INVALID_UNIQUE_KEY_DEFINITION` (422).
### 🗑️ Conditional delete and point-in-time list reads
`DELETE /api/entity/{entityName}/{modelVersion}` now honours an
`AbstractConditionDto` request body and deletes only matching entities (an
empty body still means all). This **closes a data-loss defect** where the
condition was ignored and the entire model was wiped. `verbose=true` returns
the deleted ids, and matched-vs-removed counts are reported separately. New
error code `INVALID_CONDITION` (400).
The model-scoped list read (`getAllEntities`) now honours `pointInTime`,
returning entities as-at the supplied instant and stamping `meta.pointInTime`.
### ⏱️ One point-in-time rule everywhere
Point-in-time ("as at T") reads now apply a **single canonical rule** across
every storage engine and read path: inclusive of the requested instant
(`<=`), compared at native precision, with no millisecond round-up.
Previously the memory engine and the SQL `GetAsAt`/`GetAllAsAt` paths rounded
up to the next millisecond while sqlite used a strict `<` bound — so
different backends, and even different read paths within one backend, could
disagree at sub-millisecond boundaries. That inconsistency is gone.
### 🔗 Transaction-joined compute-node callbacks
Processor and criteria-evaluation callbacks from a compute node now **join
the originating workflow transaction (`T`)** rather than running standalone.
Before each dispatch the engine mints a signed HMAC tx-token and attaches it
to the outbound CloudEvent as the `cyodatxtoken` extension attribute. Compute
nodes echo it on callbacks (`X-Tx-Token` HTTP header / `tx-token` gRPC
metadata); the receiving node verifies the HMAC and routes the callback to
the transaction owner — a local join when the owner is self, or an HTTP
reverse-proxy / gRPC forward otherwise.
Callbacks see the cascade's uncommitted writes, and their acks stay
provisional until `T` commits. `ASYNC_NEW_TX` callbacks join `T` via a
savepoint, so a processor failure discards its writes without aborting the
cascade. An absent token falls back to standalone execution — the normal
behaviour for `COMMIT_BEFORE_DISPATCH` with `startNewTxOnDispatch=false`.
New env vars: `CYODA_TX_TOKEN_TTL` (token validity, default `90s`),
`CYODA_GRPC_NODE_ADDR` (gRPC address advertised in tokens for B→A
forwarding), and `CYODA_COMPUTE_HTTP_BASE` (base URL for compute-test-client
HTTP callbacks).
### 🧩 Renderer annotations on processors and criteria
The engine-ignored `annotations` bag — previously available on workflows,
states, and transitions — now extends to the two elements that lacked it:
- **Processors** carry an embedded `annotations` object.
- **Criteria** carry a sibling `criterionAnnotations` object on the workflow
and on each transition (the criterion tree itself round-trips verbatim and
is never parsed to attach metadata).
Two well-known optional keys — `displayName` and `description` — are now
documented uniformly across all five element types for renderer and
condition-builder use. As before, annotations are object-only, capped at
64 KB per field, stored and re-emitted compacted, and **never interpreted by
the engine**; processor annotations are stripped before dispatch and never
reach compute members. This is an additive schema change: the workflow schema
moves to **1.2**, and every existing 1.1 payload remains valid.
### 📐 OpenAPI contract reconciliation
A substantial slice of this release makes the OpenAPI document tell the truth
about the running server, so generated clients and conformance tools can
trust it:
- **Typed-but-open entity `meta`** mirroring the canonical `EntityMetadata`;
the obsolete `previousTransition` field is removed.
- **Error-code conformance** — the E2E validator now enforces documented
`errorCode` strings for entity endpoints, not just response shapes.
- **`ProblemDetail` envelopes** (`application/problem+json`) declared for the
OIDC provider ops, audit search, async search, and the state-machine
finished-event endpoint; the duplicate `ProblemDetailDto` schema was
consolidated. `getTechnicalUserToken` keeps its RFC-6749 flat OAuth shape.
- **Config-conditional `501`** now documented for the 21 IAM-gated
operations when `CYODA_IAM_MODE ≠ jwt`, plus `404 FEATURE_DISABLED` on the
trusted-key ops when that feature is off.
- **Uniform `404 MODEL_NOT_FOUND`** across every model-scoped read when the
model is not registered for the tenant (these paths previously returned
empty results silently).
- **Dead-surface disposition** — SQL-schema drift fixes, CQL cleanup, and a
marker-backing invariant; fictional contract surface (a phantom `403`,
`408`, `timeoutMillis`, a no-op `pointInTime` param, a bogus UUID
constraint) removed.
- **Edge-message API** — the request envelope's optional metadata map is now
`metaData` (camelCase), symmetric with the response, and a new
`cyoda help messages` topic documents the full edge-message surface.
This release tightens several contracts. Review these before upgrading:
- **Edge-message `meta-data` → `metaData`.** The
`POST /api/message/new/{subject}` request envelope now carries its optional
metadata under `metaData`; the old kebab-case `meta-data` key is ignored.
Shipped in a patch because edge messages have no known consumers.
- **`changeType` spelling.** Entity change records now use canonical
`CREATE`/`UPDATE`/`DELETE` over HTTP (previously `CREATED`/`UPDATED`/
`DELETED`); gRPC and OpenAPI already agreed.
- **`DELETE /model/{entityName}/{modelVersion}` enforces UNLOCKED.** Deleting
a `LOCKED` model now returns `409 MODEL_ALREADY_LOCKED` instead of ignoring
the lock. Unlock the model first.
- **`searchEntities` limit is enforced, not clamped.** `limit > 10000` now
returns `400 BAD_REQUEST` across sync search (HTTP), gRPC direct search,
and async submission; the spec previously described a silent clamp.
- **`searchEntities` responds `application/x-ndjson` only.** The
previously-listed `application/json` variant is removed from the contract.
- **`listOidcProviders.activeOnly` is now a strict boolean.** Truthy values
(`1`, `true`, `t`) filter correctly; unparseable values such as
`?activeOnly=yes` return `400` instead of silently meaning false.
- **`registerOidcProvider` duplicate returns `409`** (`OIDC_PROVIDER_DUPLICATE`),
not `400`. The `400` path remains for validation failures.
- **Removed fictional parameters.** The no-op `pointInTime` on
`getAsyncSearchResults`, the `timeoutMillis` param and `408` on
`searchEntities`, and the fictional time-based-UUID `400` on
`getStateMachineFinishedEvent` are all gone from the contract.
For the complete and authoritative list, consult the
[CHANGELOG](https://github.com/Cyoda/cyoda-go/blob/main/CHANGELOG.md#082--2026-07-08).
## 🛡️ Security
- **Go toolchain 1.26.4 → 1.26.5** to clear govulncheck advisory
GO-2026-5856.
- **`goldmark` v1.7.13 → v1.7.17** (indirect) to clear GO-2026-5320 (XSS in
goldmark HTML rendering, reached via `glamour` in the `cyoda help`
renderer). The renderer only formats first-party help content embedded in
the binary, so the advisory was never reachable with attacker-controlled
input; the bump keeps the scan clean.
## 🚀 Resources & getting started
For installation guides, building from source, architecture, and running the
engine locally or in production:
- [**Cyoda Hub (cyoda.dev)**](https://cyoda.dev) — the primary portal for the
Cyoda ecosystem, community links, and major updates.
- [**Cyoda Documentation (docs.cyoda.net)**](https://docs.cyoda.net) —
quick-starts, configuration schemas, API references, and operations guides.
- [**GitHub Project (github.com/Cyoda/cyoda-go)**](https://github.com/Cyoda/cyoda-go)
— source code, build requirements, and binary releases with cryptographic
checksums under the
[v0.8.2 release tag](https://github.com/Cyoda/cyoda-go/releases/tag/v0.8.2).
## 💬 Feedback
Found a bug, hit a parity gap, or have a feature request? Open an issue or
start a thread in our
[GitHub Discussions](https://github.com/Cyoda/cyoda-go/discussions) — and
feel free to join us on
[Discord](https://discord.com/invite/95rdAyBZr2). Thank you for building with
Cyoda-Go!
## 📌 Footnote: why v0.8.2 is a patch, not a minor
This release adds several genuinely new capabilities, yet it ships as a
patch. That is deliberate. Pre-1.0, we follow the widely-adopted convention
(Cargo, npm `^0.x`) where the **leftmost non-zero component is the de-facto
major** and the minor component is reserved as a **breaking-change signal**.
Features ship in patches; a minor bump means "read the migration notes".
We also **decoupled the `cyoda-go-spi` version from the binary version**. The
two move independently now — the SPI is pinned per release, but its number no
longer has to march in lock-step with the engine. See
[docs/workflow-schema-versioning.md](https://github.com/Cyoda/cyoda-go/blob/main/docs/workflow-schema-versioning.md)
and the [README versioning section](https://github.com/Cyoda/cyoda-go#versioning)
for the full convention.
This release does still carry breaking contract changes — see the breaking
changes noted above — but they are contract-tightening corrections, not a new
feature epoch.
---
## releases/v0-8-3.md
# Cyoda-Go v0.8.3
Scheduled state transitions, Cloud-aligned search semantics, and honest attribution for follow-on actions.
_Released 27 July 2026 · 19 issues delivered_
This release adds time to the workflow engine: a transition can now declare a
delay and fire on its own, with the firing time computed per entity by a compute
node if a static delay is not enough. Search gains a single type-directed
evaluation kernel shared by every in-process code path, replacing two
implementations that had drifted, and direct search becomes bounded-or-fail on
every backend rather than silently truncating. Alongside that, a cascaded or
scheduled action is now recorded against the user who caused it instead of the
service account that happened to run it.
## ✨ Highlights
- **Scheduled state transitions:** A transition can carry `schedule: {delayMs, timeoutMs}` and fire automatically, durably armed and cancelled with the
entity write, coordinated across the cluster.
- **Per-entity firing times:** `schedule.function` calls out to a compute node
to compute a transition's fire and expiry times per entity.
- **Cloud-aligned search:** Predicate evaluation is type-directed and same-type
only, on one shared kernel, matching Cyoda Cloud's model.
- **Bounded-or-fail direct search:** A matched set larger than `limit` now fails
with `400 SEARCH_RESULT_LIMIT` instead of returning a truncated page that
looks complete.
- **Attribution for follow-on actions:** Cascaded writes and scheduled fires are
attributed to the originating principal while still executing with system
authority.
- **Criterion stoppage reason:** A criteria compute node can explain why it
blocked a passage, surfaced on the rejection response and the audit trail.
- **Tx-aware search pushdown:** In-transaction search no longer falls back to a
full-model scan.
## 🔍 Details
### ⏰ Scheduled state transitions
A transition carrying `schedule: {delayMs, timeoutMs}` fires `delayMs` after the
entity enters its source state. Timers are durable, stored per backend
(memory/sqlite/postgres) and armed or cancelled atomically with the entity
write. A cluster coordinator (lowest-live-node-ID, pluggable) scans due tasks and
distributes them round-robin to a fire-and-forget peer RPC; the firing node
re-reads the task and entity as a guard, so a stale or superseded task is a
silent no-op.
The transition's criterion is evaluated **once** at fire time — `false` declines
the transition and the entity stays put, with no retry. A lateness grace band
separates expiry (`timeoutMs` exceeded, dropped unfired) from firing, so clock
skew between nodes cannot produce a contradictory expire-and-fire. Any entity
write leaving the entity in the same state — including a routine data update or
a self-loop — resets the timer. Firing a scheduled transition explicitly by name
still returns `400 TRANSITION_NOT_FOUND`.
New audit events: `SCHEDULED_TRANSITION_ARM` / `FIRE` / `EXPIRE` / `CANCEL`. New
env vars: `CYODA_SCHEDULER_ENABLED`, `CYODA_SCHEDULER_SCAN_INTERVAL`,
`CYODA_SCHEDULER_BATCH_SIZE`, `CYODA_SCHEDULER_DISTRIBUTION`,
`CYODA_SCHEDULER_COORDINATOR`, `CYODA_SCHEDULER_REDISPATCH_BACKOFF`,
`CYODA_SCHEDULER_EXPIRY_GRACE` — documented under the new
`cyoda help config scheduler` topic.
### 🧮 Per-entity firing time via a Function callout
A static `delayMs` fires every entity at the same offset. For a per-entity
deadline — an `expiresAt` on the entity, a per-customer SLA, a user-chosen
reminder — a `schedule` may instead carry `function`, mutually exclusive with
`delayMs`, naming a compute node routed by `calculationNodesTags` exactly like an
externalized processor or criterion.
This introduces a generic **Function** callout: a third shape alongside Processor
(mutates the entity) and Criterion (returns a bool), returning a declared typed
value without mutating anything. For scheduling it returns a composite `Schedule`
result — `{fireAt | fireAfterMs, expireAt? | expireAfterMs?}`, absolute epoch-ms
or relative — resolved at arm time into the same `scheduledTime`/`timeoutMs` a
static schedule would populate. It is invoked on **every** re-arm, not once on
entry.
The path fails closed. The callout runs synchronously inside the entity-write
transaction, so a callout failure fails that write. A compute node that is
unreachable, disconnected, or timing out fails the write with a retryable `503`
— no state change commits against an unschedulable transition. A malformed or
wrong-kind result fails it with the new `500 SCHEDULE_FUNCTION_INVALID_RESULT`.
The one case where the write still succeeds is **born expired**: a resolved
expiry at or before the resolved fire time leaves the transition unarmed,
cancels any prior scheduling for it, and records a
`SCHEDULED_TRANSITION_EXPIRE` audit event. There is no silent skip.
Relatedly, the compute-infrastructure codes `NO_COMPUTE_MEMBER_FOR_TAG`,
`DISPATCH_TIMEOUT`, `DISPATCH_FORWARD_FAILED`, and
`COMPUTE_MEMBER_DISCONNECTED` now surface as retryable `503` uniformly across all
three callout kinds. Previously some of these — a missing compute member, most
visibly — fell through to a misleading `400 WORKFLOW_FAILED`.
The workflow schema moves to **1.3**; every existing 1.1 and 1.2 payload remains
valid.
### 🔎 Type-directed search and criteria evaluation
cyoda-go had two independent Go implementations of predicate leaf-comparison —
one behind workflow criteria and the search fallback, one behind the plugin
pushdown paths — and they had drifted, so the same query could return different
results depending on which evaluator ran. Both now delegate every leaf operator
to a single shared kernel in the SPI; the SQL planners mirror it and stay guarded
by the cross-backend parity suite. The kernel implements Cyoda Cloud's evaluation
model, documented in the new `cyoda help predicates` topic.
Observable changes:
- **Same-type comparison.** An operand is parsed against the field's declared
type(s), so a numeric-looking string and a JSON number behave identically and
there is no cross-type coincidental matching.
- **Precise numbers.** Arbitrary-precision comparison replaces `float64`
coercion — correct beyond 2^53.
- **`LIKE` is a real anchored glob** (`%`, `_`, `\`-escape, whole-string,
case-sensitive) on every backend, no longer wildcard-neutered on SQL.
- **Temporal data fields compare chronologically**, across six subtypes with
resolution upscale/downscale. Meta-field temporal filters
(`creationDate`/`lastUpdateTime`) now also accept a coarser operand such as a
bare year.
- **Negatives are null-guarded.** `NOT_EQUAL`, `NOT_CONTAINS`, `INOT_*` and the
rest evaluate to non-match on an absent or `null` field, rather than matching
via `!positive`.
- **`BETWEEN_INCLUSIVE` is fixed** — it previously fell through to a regex
evaluation on `Searcher`-backed stores instead of an inclusive range check.
- **Validation is parse-based:** a `400` is returned only when the operand parses
into none of the field's declared types, so some requests that used to fail now
succeed and vice versa.
- A field seen as both an object and a bare scalar is searchable via its scalar
type; a scalar operator against a pure-container path now returns
`400 INVALID_FIELD_PATH` instead of silently matching nothing.
Alongside this, the schema classifier now detects `LOCAL_DATE`,
`LOCAL_DATE_TIME`, `LOCAL_TIME`, `ZONED_DATE_TIME`, `YEAR`, and `YEAR_MONTH`
rather than classifying every temporal string as `STRING` — which is also the
prerequisite for temporal range indexes in a backend that builds them.
### 🚧 Direct search is bounded-or-fail
Direct (synchronous) search now caps the matched set rather than paging it: a
query matching more entities than `limit` allows returns
`400 SEARCH_RESULT_LIMIT` instead of a truncated prefix. A partial result was
indistinguishable from a complete one, which is the defect being closed. An exact
match at `limit` succeeds.
The default when `limit` is omitted is unchanged at 1000 — but it is now actually
applied. Previously the default was honoured only on the `GetAll`+match fallback
branch, while the `Searcher` pushdown branch used by all three OSS backends
treated an omitted limit as unbounded and returned the entire matched set.
`limit=0`, which used to mean an unbounded synchronous search, is now rejected
with `400 BAD_REQUEST`.
Ordered top-N over a large model — `sort` plus a small `limit` — is no longer
available on the synchronous path. Async search covers it: it snapshots the full
matched set and pages over it.
Two failure modes that previously surfaced as an opaque `500` ticket are now
classified `400`s: `SEARCH_RESULT_LIMIT` when a backend detects an over-cap
matched set, and the new `SCAN_BUDGET_EXHAUSTED` when a non-indexable residual
scan exceeds the backend's row budget. Conditional delete also forwards a
classified 4xx from its delete-selection search instead of a `500`.
### 🔁 Tx-aware search pushdown and `trackingRead`
An in-transaction search no longer falls back to a full `GetAll` scan plus
in-memory filtering. The plugin-level `Searcher` honours the active transaction
directly and stays read-your-own-writes correct against its uncommitted writes,
with no full-model materialisation — memory and sqlite overlay the transaction
buffer on the committed stream, postgres runs the query natively on its own
`pgx.Tx`.
A new optional `trackingRead` boolean (default `false`) on the synchronous search
endpoints opts a search into recording its **returned** entities into the
transaction's read-set, so a concurrent write to one of them aborts the
transaction at commit. This is entity-level, the same as `GetAll`, and still
offers no phantom-write-skew protection. The default is a plain snapshot read
recording nothing — a lighter read-set footprint than before. Async search does
not expose the flag, as it runs detached. See `docs/CONSISTENCY.md` §3c for the
updated fence guidance.
Separately, compute-node callback transaction-join now covers the gRPC search
RPCs. A callback presenting a valid `tx-token` on `EntitySearch` /
`EntitySearchCollection` previously had it silently ignored — the interceptor was
wired only for the write RPCs — so a processor's writes joined the originating
transaction while its searches ran unjoined against last-committed state. That
asymmetry produced stale results with no error.
### 👤 Attribution for deferred and cascaded actions
When a user's action set off a later or indirect workflow action, cyoda-go
recorded the follow-on against a service or system account, losing the human who
caused it. A cascade — a processor writing other entities in reaction to a user's
transition — was recorded as the compute service account; a scheduled fire was
recorded as a fake `"scheduler"` user.
Attribution and authorization are now separate concerns. A follow-on action is
**executed** with system or service authority — nobody is impersonated and no
user permissions are borrowed — but **attributed** to the principal captured
server-side when the follow-on was created: the transaction's origin for a
cascade, propagated unchanged through every joined write including a cross-node
proxied join, and the durable `ArmedBy` on the scheduled task for a timer fire.
Origin is platform-set only; no request field or worker input can set it.
Principals now carry an explicit kind — `user`, `service`, or `system` — instead
of being guessed from the presence of `ROLE_M2M`, a guess that was wrong in both
directions. `GET /entity/{entityId}/changes` gains `attributedKind` and
`executedBy: {id, kind}` per change, so a service-executed write is never
indistinguishable from a direct user action. The existing `user` field is
unchanged, and rows written before this release omit the two new fields entirely
rather than emitting `null`.
For compute-node authors, the new `api/grpc/authctx` helper exposes `Type`, `ID`,
and `Roles` readers plus `Require(ce, role)` — a fail-closed role gate returning
`false` for a nil event, absent or empty claims, or `authtype == system`.
### 🛑 Criterion stoppage reason
`EntityCriteriaCalculationResponse.reason` was declared on the wire but dead
end-to-end: a criteria compute node could not tell the engine *why* it returned
`false`. It is now live. A manual explicit transition rejected by its criterion
appends the reason to the `400 WORKFLOW_FAILED` detail — the guaranteed,
backend-independent surface.
For automated-cascade and workflow-selection paths the reason is additionally
recorded durably on the state-machine audit trail:
`TRANSITION_NOT_MATCH_CRITERION` carries
`{workflowName, transition, criterion, reason}` in its `data`, and
`WORKFLOW_SKIP` carries `{workflowName, reason}`. Reasons are capped at 2 KiB;
an omitted reason defaults to `"criterion did not match"`.
### 🐛 Correctness fixes
- **Depth-2 nested joins no longer deadlock the transaction.** When a joined
callback ran a transition whose own SYNC processor drove a further joined write
on the same transaction, the third-level write blocked on the per-transaction
gate the second-level callback still held while parked in its dispatch. The
transaction hung for the full 30 s dispatch timeout and then failed. The gate
is now released across every external dispatch and re-acquired before the
buffer is touched again, generalising the invariant the owner path already
upheld to every joined callback.
- **gRPC keep-alive storm.** The streaming server replied with a keep-alive to
every inbound member keep-alive while also sending its own on a 10 s ticker.
Against a client that likewise echoed, this produced a delay-free feedback loop
pinning both processes at ~100% CPU indefinitely, with nothing above Debug in
the logs. An inbound keep-alive is now liveness-only.
- **Boolean search conditions on postgres no longer `500`.** The query planner
bound a raw Go `bool` against a text-typed `doc->>'path'` extraction, which pgx
cannot encode. The operand is now rendered as its text form, matching what
memory and sqlite already did.
- **Malformed criterion regexes are rejected at import.** A non-compiling
`MATCHES_PATTERN` pattern imported successfully and then errored on every
evaluation of that transition; it now fails at registration with
`400 VALIDATION_FAILED`.
### 📚 Help and documentation
- **Plugins can contribute help topics.** `help.RegisterOverlay(fs.FS)` lets a
storage plugin hand its embedded `content/` tree to the help loader from
`init()`, mirroring the SPI storage-factory registration pattern, so a backend
can document its own behaviour through `cyoda help`.
- **`cyoda help config all`** lists every `CYODA_*` variable as a table, with
`--format=json` for the machine-consumable form and `GET /help/config/all` over
HTTP. It is assembled at request time from a root-side registry plus each
registered plugin's `ConfigVars()`, so an out-of-tree backend's variables
appear with no root import. New `config.cluster` and `config.scheduler`
subtopics give those variables first-class discoverability.
- **gRPC entity PATCH is documented,** along with
`EntityModelSetUniqueKeysRequest`; both were registered and tested but missing
from the event-type catalogue that downstream docs consume. A parity test now
pins the catalogue against the registered constants.
This release tightens several contracts. Review these before upgrading:
- **Direct search fails instead of truncating.** A synchronous search matching
more than the effective `limit` returns `400 SEARCH_RESULT_LIMIT`. Since the
omitted-`limit` default of 1000 is now genuinely applied, a query that
previously returned a truncated page — or, on a `Searcher` backend, an
unbounded result set — now fails. Narrow the condition, raise `limit` (maximum
10000), or move to async search.
- **`limit=0` is rejected.** It previously meant an unbounded synchronous search;
it now returns `400 BAD_REQUEST`. gRPC rejects `limit < 1` for the same reason.
- **Ordered top-N is gone from synchronous search.** Use async search.
- **Predicate evaluation is same-type.** Cross-type coincidental matches no
longer occur, negatives no longer match null or absent fields, `LIKE` is a real
anchored glob, and validation is parse-based — so a query's result set, or
whether it validates at all, may change. See `cyoda help predicates`.
- **CloudEvent `authtype` values changed.** The Auth Context attribute now emits
`user`, `service`, or `system`, driven by the principal's explicit kind.
`service_account` is retired. Compute nodes switching on the old string must be
updated. The attribute is always present and faithful: an unset or
unrecognized kind fails the callout dispatch rather than emitting a normalized
value.
- **Processor `config.attachEntity` defaults to `true`.** A processor omitting
the field is imported with `attachEntity: true`, matching `schedule.function`
and the criterion `function` callout. Existing workflows that omit it will
start attaching the entity payload on re-import. Set `attachEntity: false`
explicitly to opt out; compute nodes that ignore the payload are unaffected.
- **`TransitionScheduleDto.delayMs` is no longer `required`.** A `function`
schedule carries no `delayMs`, so consumers of the workflow-export response
must treat it as optional on a 1.3+ schedule. A pre-1.3 exported workflow
always has it.
- **Malformed criterion regexes are rejected at import** rather than at
evaluation. No previously-working configuration is affected — a non-compiling
pattern always errored at evaluation time.
- **SPI (plugin authors):** `Searcher.Search` must fail rather than truncate when
`SearchOptions.Limit` is exceeded, and must treat `Limit <= 0` as unbounded
without substituting its own default. `MergePage` is renamed `MergeBounded` and
drops its `offset` parameter; `SearchOptions.Offset` is removed outright.
Out-of-tree plugins must be rebuilt against `cyoda-go-spi v0.8.3`.
For the complete and authoritative list, consult the
[CHANGELOG](https://github.com/Cyoda/cyoda-go/blob/main/CHANGELOG.md#083--2026-07-27).
## 🛡️ Security
Both advisories cleared this cycle required a version beyond what Dependabot
proposed:
- **`google.golang.org/grpc` v1.81.1 → v1.82.1** (HIGH). The grouped Dependabot
PR stopped at v1.82.0 and would have left the advisory open.
- **`getkin/kin-openapi` v0.142.0 → v0.144.0** for GHSA-r277-6w6q-xmqw and
GHSA-jpcw-4wr7-c3vq (CRITICAL, fail-open auth bypass). The advisories are in
`openapi3filter`, which cyoda-go uses only in its E2E conformance validator;
the shipped binary uses kin-openapi for spec parsing and never for request
authentication. Dependabot proposed v0.142.0, short of the fix.
- **`oapi-codegen/v2` v2.7.0 → v2.7.1** (LOW), with `api/generated.go`
regenerated.
Every open CodeQL finding was also cleared. Two were genuine bugs: a path
traversal via a caller-supplied message id reaching `os.Remove` in the memory
plugin's message store, and a typed-nil-in-interface guard that could never fire,
marshalling a dangling `$ref` to `"null"` in the help renderer. The
`go/log-injection` rule (49 sites) is excluded with a test pinning the rationale:
`slog`'s `TextHandler` quotes injected newlines, so the protection is a property
of the handler rather than of each call site.
## 🚀 Resources & getting started
For installation guides, building from source, architecture, and running the
engine locally or in production:
- [**Cyoda Hub (cyoda.dev)**](https://cyoda.dev) — the primary portal for the
Cyoda ecosystem, community links, and major updates.
- [**Cyoda Documentation (docs.cyoda.net)**](https://docs.cyoda.net) —
quick-starts, configuration schemas, API references, and operations guides.
- [**GitHub Project (github.com/Cyoda/cyoda-go)**](https://github.com/Cyoda/cyoda-go)
— source code, build requirements, and binary releases with cryptographic
checksums under the
[v0.8.3 release tag](https://github.com/Cyoda/cyoda-go/releases/tag/v0.8.3).
## 💬 Feedback
Found a bug, hit a parity gap, or have a feature request? Open an issue or
start a thread in our
[GitHub Discussions](https://github.com/Cyoda/cyoda-go/discussions) — and
feel free to join us on
[Discord](https://discord.com/invite/95rdAyBZr2). Thank you for building with
Cyoda-Go!
## 📌 Footnote: why v0.8.3 is a patch that still breaks things
v0.8.3 is a patch release that carries breaking changes — listed in the
caution above. Pre-1.0 the minor component is the breaking-change signal and
features ship in patches; this release departs from that on the search and
`authtype` contracts. Read the breaking-changes list before upgrading rather
than inferring compatibility from the version number.
`cyoda-go-spi` ships its own breaking changes as **v0.8.3**. It is versioned on
an independent axis from the binary — see
[`COMPATIBILITY.md`](https://github.com/Cyoda/cyoda-go/blob/main/COMPATIBILITY.md)
for the supported combinations.
---
## releases/v0-8-4.md
# Cyoda-Go v0.8.4
One path grammar, one resolver, one search execution path — and a server boundary that stays up while it answers.
_Released 9 September 2026 · 40 issues delivered_
This is a consolidation release. Where cyoda-go had two implementations of the
same idea, it now has one. A field path is written one way and resolved by one
resolver on every surface — search, workflow criteria, grouping, sorting. A
value is judged admissible by one test, whether it arrives on a write or is
matched by a query. A search runs on one path, with the whole-model fallback
that quietly made a rejected condition succeed deleted outright. Duplication is
not a tidiness complaint here: every pair of implementations in this release
had already drifted, and each drift showed up to a caller as a plausible,
wrong `200`.
Alongside that, the server boundary was hardened. Panics are contained rather
than fatal, transactions are released on every exit path, PostgreSQL carries
real ceilings, and every read path that used to load a whole model into memory
now streams. Async search survives losing the node that was running the job.
This release changes more caller-visible behaviour than any before it. Read the
breaking-changes callout below before upgrading.
## ✨ Highlights
- **One path grammar.** A field path is JSON Path — `$.amount`, not `amount` —
on search conditions, workflow criteria, `groupBy`, aggregation fields and
sort keys alike, validated by one scanner at the boundary.
- **One resolver.** A path's meaning is decided by its syntax, not by the shape
of the stored value it happens to meet. `$.tags[*]` addresses the elements of
`tags`; it used to resolve to the array's length.
- **Search has one path.** The in-memory whole-model fallback is deleted. A
condition that cannot be translated is a `400`, not a full scan.
- **`NOT` is a real operator**, declared in the API since the first import and
answered `400` until now. Workflow schema moves to 1.4.
- **One type-admission test.** A field holds a value when its declared type
admits that value — asked directly, per value, on both the write side and the
query side, so what can be stored is exactly what can be found.
- **Transaction lifecycle safety.** Deferred rollback on every exit path, five
PostgreSQL ceilings, pool-acquire timeouts, and a new retryable
`503 STORAGE_UNAVAILABLE` on all 52 storage-backed operations.
- **Panic containment.** gRPC and every HTTP route recover; a panic in engine
or store work withdraws the node from service instead of killing the process
or silently continuing.
- **Nothing materialises a model.** Paged list reads, streamed async-search
results, streamed delete selection, purpose-built history reads.
- **Async search survives node loss.** Bounded worker pool, per-tenant
admission, heartbeats, fenced claim epochs, and orphaned jobs re-executed
rather than failed.
- **The write-visibility contract is stated.** A `2xx` write is visible to
every subsequent read on every node; `waitForConsistencyAfter` is retired
because it could toggle nothing.
## 🔍 Details
### 🧭 One path grammar, one resolver
cyoda-go accepted several spellings of a field path and resolved them in
several places. The spellings disagreed, and the disagreement was invisible:
each surface answered `200` with whatever its own resolver produced.
A path is now written as JSON Path and validated once, at the boundary, by a
scanner shared with the pushdown translator:
```
jsonPath = "$." segment ( "." segment )*
segment = name subscript*
name = 1*( ALPHA / DIGIT / "_" / "-" ) ; ASCII only
subscript = "[" ( "*" / 1*DIGIT ) "]" ; the digit run must fit an int32
```
What that closes, in the order it bit hardest:
- **A trailing wildcard addresses elements, not a count.** `$.tags[*] EQUALS
"red"` compared `"red"` against the number of tags and never matched. Multiple
array hops were broken by the same arithmetic, with or without a trailing
wildcard: `$.matrix[*][*]`, `$.a[*].b[*]` and `$.orders[*].lines[*].sku` all
compared against a nested array.
- **A bare path is rejected.** `amount` used to be read as `$.amount` by the
in-memory evaluator, so the pushdown translator refused it, the request fell
back to a full model scan, and the caller got correct-looking results off a
path the query planner had declined.
- **Malformed subscripts are rejected.** The path used to be scanned only as far
as the first `[`. `$.a[-1]`, `$.a[0:2]`, `$.a[?(@.x)]`, `$.a[0];DROP` and an
unclosed bracket all classified as "not pushdownable" and fell through to an
evaluator that resolves none of them — an empty page for a field that exists.
- **A positional path resolves.** `$.arr[0]` missed on three independent
lookups and answered an empty page while its wildcard twin worked. Two
spellings of one path disagreed.
- **Workflow criteria obey the same grammar**, enforced at import. A criterion
on `amount` used to import cleanly and then guard a transition that silently
never fired.
Grouped stats, aggregation fields and sort keys share the same scanner minus
the subscript production, so those three surfaces cannot drift from it again.
`$.`-prefix handling is now uniform across HTTP and gRPC: a gRPC `orderBy` on
`$.city` used to be looked up as `$.$.city`. The grammar and its addressing
rules are on the
[searching entities](/build/searching-entities/#how-a-field-path-is-written)
page; `docs/cloud-parity/path-grammar.md` carries the parity contract.
### 🔎 Search has one execution path
A condition that could not be translated into a backend query used to fall back
to loading the model and filtering in Go. Every call site treated a translation
failure as "scan instead", so a path the translator rejected was still
answered — with results, at `200`, off a plan the caller never asked for.
The fallback is deleted. A condition that does not translate is `400`
(`INVALID_CONDITION`, or `INVALID_FIELD_PATH` for a path-shaped failure). No
client-reachable request changes status, because the boundary grammar and the
translator now share one path parser and one operator set: validated input
always translates.
Conditional `DELETE /entity/{entityName}/{modelVersion}` and grouped statistics
each carried a fallback of the same shape, and both are gone too. One malformed
condition used to be answered three ways — a `400` from search, a served result
from each of the other two. All three refuse it now, for the same reason.
`EntityStore` gains `Search` and `Iterate` as required methods and loses
`GetAll`/`GetAllAsAt`. There is no whole-model read anywhere in the engine.
Grouped statistics therefore always has an execution path, and its
`501 NOT_IMPLEMENTED_BY_BACKEND` is retired.
Two other search-shaped defects go with it. Async search now translates the
condition **before** it persists the job, so a condition no backend can execute
is refused at submission instead of failing in the background. And a search
whose model schema cannot be loaded now fails with a `500` and a ticket rather
than skipping validation and answering: with no fields map, eight of the
twenty-six operators collapse to a non-match while the other eighteen keep
matching, so the short page was not merely unvalidated, it was wrong.
### 🚫 `NOT`, and the answers it exposed
`NOT` has been declared in `GroupConditionDto.operator`'s OpenAPI enum since the
initial import while the server answered `400` for it. It is now implemented end
to end — search, grouped stats, conditional delete, and workflow and transition
criteria.
It takes exactly one child condition; zero or two-or-more is `400
INVALID_CONDITION` (`400 VALIDATION_FAILED` at import). Over a wildcard-addressed
list it is a universal quantifier where the leaf it wraps is existential:
`NOT($.tags[*] EQUALS "red")` matches when no element equals `"red"`, a different
question from `$.tags[*] NOT_EQUAL "red"`. `NOT` over an empty list, an explicit
`null` or an absent field matches, because the wrapped leaf is false. It is
residual-only — no backend pushes it into its own query language.
Two adjacent answers were wrong and are now correct:
- **An unsatisfiable comparison follows operator polarity.** `$.n NOT_EQUAL 12.5`
on a field declared `INTEGER` used to return nothing. It now returns every
entity holding a number at `n`, because no integer equals `12.5` — the answer
PostgreSQL gives for `5::int <> 12.5`. This widens conditional delete as well
as search.
- **A criterion naming a field the model does not declare aborts the save it
evaluates**, `400 WORKFLOW_FAILED`, rolled back. It used to evaluate to "not
satisfied", so a misspelled field name meant a transition that silently never
fired.
Workflow schema version bumps 1.3 → 1.4. Schemas 1.1 through 1.4 are all
accepted; nothing is retired. An integrator whose CI pins
`GET /help/workflows/schema-version/versions` to `"1.3"` must update the pin.
See `docs/cloud-parity/negation.md`.
### 🧬 The model is one thing, and every part of the system reads it the same way
The model layer, the write validator and the search kernel each had their own
idea of what a field declares and what it can hold. Each disagreement produced a
value that could be stored but not found, or found but not stored.
- **A field holds a value when its declared type admits it** — a direct,
per-value test, on both sides. Ingestion used to compute a value's *label*
(`INTEGER`, `LONG`, a temporal subtype) and ask whether that label was
assignable to the declaration; search classified the stored value the same
way, and the two classifications did not always land on the same side of the
line. A `DOUBLE` field now accepts `2147483648` without widening the model,
and a `STRING` field holds `"2026-03-01"` with no schema change at any
`changeLevel`. See `docs/cloud-parity/numeric-type-admission.md`.
- **A schema node holds the set of kinds it was observed as.** The persisted
form gains `"kinds"`; a monomorphic node still writes `"kind"` and serialises
byte-identically, so no model needs migrating. A stored node under the old
single-label form now restores every branch its payload carries rather than
the one the label happened to name.
- **A value whose kind the field does not declare is rejected.** A field
declared `STRING` used to accept an array or an object and store it, while
correctly refusing a number. The reverse direction was always enforced, so the
hole was one-directional.
- **An array's length is not part of the model.** The discovery-time "widest
array seen" statistic is gone, along with the write-path width comparison and
the `(T x N)` decoration `SIMPLE_VIEW` rendered from an in-memory tree but
never from a persisted one. An export now describes the model rather than the
route the model took into memory. `ARRAY_LENGTH` keeps its place as the floor
of the ladder: the level that permits no schema change at all.
- **Model field names must be addressable.** A field name is accepted only if it
is a valid path segment. The model layer used to record any JSON key while the
query layer could address only this charset, so a document could establish a
field nothing could ever search.
- **The model export describes every branch a field declares.** An array of
arrays rendered as `.m[*]: NULL` instead of naming the elements at `.m[*][*]`;
a field observed as both scalar and container showed only the container. Two
models that enforce differently rendered identically. `JSON_SCHEMA` now renders
a kind union as `anyOf` — `oneOf` rejected values the model admits whenever two
branches rendered the same shape.
- **A JSON array posted to the sample-data import is a collection of sample
documents.** It used to register a model describing an array at the root:
`SIMPLE_VIEW` rendered `{}`, and the model then refused the very documents it
was derived from.
The rewritten [entity model export reference](/reference/entity-model-export/)
carries the new wire format for both converters.
### 🛟 Transaction and connection lifecycle
An entity write now releases its transaction on every exit path, including a
panic. Previously a panic between begin and commit left the transaction neither
committed nor rolled back with its pooled connection never returned; repeated,
that exhausts the pool and the node stops serving. The workflow engine likewise
releases the segments it opens itself — an ordinary compute-node failure
mid-cascade was enough to leak one, permanently on memory and sqlite.
PostgreSQL gains five configurable ceilings, all defaulting on:
| Variable | Default | Bounds |
|---|---|---|
| `CYODA_POSTGRES_STATEMENT_TIMEOUT` | `5m` | any single statement |
| `CYODA_POSTGRES_IDLE_IN_TX_TIMEOUT` | `5m` | idle gap inside an open transaction |
| `CYODA_POSTGRES_ACQUIRE_TIMEOUT` | `10s` | waiting for a pooled connection |
| `CYODA_POSTGRES_MIGRATE_LOCK_TIMEOUT` | `5m` | migration advisory lock |
| `CYODA_POSTGRES_SEARCH_STATEMENT_TIMEOUT` | `30m` | async-search statements |
Each takes a Go duration, `0` disables that limit, and a malformed value fails
startup rather than falling back to the default. `SQLSTATE 57014` and `25P03`
are classified rather than surfacing as unexplained errors.
The transaction reaper and `CYODA_TX_TTL`, `CYODA_TX_REAP_INTERVAL` and
`CYODA_TX_OUTCOME_TTL` are removed: nothing ever registered a transaction with
the reaper, so the TTL they advertised was never enforced.
A new retryable **`503 STORAGE_UNAVAILABLE`** covers pool exhaustion, a
transaction aborted by the idle ceiling, and a connection going away. It is
declared on all 52 storage-backed operations in `api/openapi.yaml`. Relatedly, a
storage outage no longer answers `404 Not Found` — async-search status and
results, trusted-key operations, the audit transaction lookup and several entity
reads used to collapse any store error into a not-found result, telling a client
"it does not exist" and stopping the retry.
Commits are now shielded from a client disconnect or an expired deadline
arriving mid-commit, so a deadline can no longer produce an in-doubt "client
sees failure but the write is durable" outcome.
### 🛡️ Server-boundary resilience
Panic recovery now covers the gRPC server (unary and stream) and every HTTP
route, where it previously covered only the `/` catch-all — so a gRPC panic
killed the process and an HTTP panic on a specific route dropped the connection
with no ProblemDetail and no ticket. Recovery is the outermost HTTP layer,
covering CORS and cluster-routing middleware and the admin server.
A recovered panic at any of the four sites that run engine or store work — the
two request doors, the async-search goroutine, the scheduler's dispatch
goroutine — permanently marks the node unhealthy: `GET /health` reports
`503 DOWN` and `/readyz` reports `503`, so Kubernetes drops the pod from its
Service within ~10-15s. The node's state is unverified, so withdrawing it is
deliberate. Know the bound: peer-forwarded work keeps arriving, established
connections stay open, and nothing restarts the node, since `/livez` is
unchanged. Read the ticket from the log and replace the pod.
Each compute member's stream now has exactly one writer goroutine draining an
outbox. A frozen compute node is evicted within `CYODA_KEEPALIVE_TIMEOUT` of
inbound silence **or** when one write has stalled that long, so a node that
keeps pinging while its application is stuck is caught too.
`CYODA_KEEPALIVE_INTERVAL` and `CYODA_KEEPALIVE_TIMEOUT` were parsed and
ignored; they now reach the gRPC server.
New HTTP receive-side timeouts, on both the API and admin servers:
`CYODA_HTTP_READ_HEADER_TIMEOUT` (`10s`), `CYODA_HTTP_READ_TIMEOUT` (`5m`),
`CYODA_HTTP_IDLE_TIMEOUT` (`2m`). `CYODA_HTTP_WRITE_TIMEOUT` exists and ships
disabled: the server imposes no time budget on work.
PostgreSQL pool saturation is now observable — seven
`cyoda_storage_pool_*` metrics, always on at `/metrics`.
A `4xx` error body no longer scales with the size of a malicious request. An
entity write with hundreds of thousands of undeclared fields renders the first
32 failures plus a summary; a rejected condition operand is truncated before it
is echoed back.
### 🌊 Nothing materialises a model
Every read path that used to load a whole model into memory now streams:
- **Paged entity-list reads.** `GET /entity/{entityName}/{modelVersion}` pages
at the store instead of loading the model and slicing in Go.
- **Streamed async-search results**, saved incrementally as the scan runs.
- **Streamed delete selection**, on both the conditional and unconditional
forms.
- **Purposed history reads.** `GET /entity/{entityId}/changes` and the audit
transaction lookup use metadata-only reads bounded by one entity's own version
history.
- **In-transaction reads on sqlite and memory** serve `Iterate`, `GetPage`,
`Count`, `CountByState` and `DeleteAll` from one overlay cursor rather than a
merged copy of the model.
The SQLite backend opens a dedicated read connection pool so a long undrained
scan cannot starve concurrent writes. Note the memory cost: `CYODA_SQLITE_CACHE_SIZE`
(default `64000` KiB) is **per connection**, so the resident ceiling is now
`(readers + 1) × CYODA_SQLITE_CACHE_SIZE` — on an 8-CPU host with defaults,
≈ 562 MiB where it was ≈ 62.5 MiB. `CYODA_SQLITE_READER_POOL_SIZE` sizes the
pool (default `GOMAXPROCS` clamped to 4..8). `GOMAXPROCS` follows the CPU quota
and is blind to the memory limit, so a container generous on cores and tight on
memory must lower this.
The server no longer imposes a scan budget on search: sqlite's residual-scan
budget, `CYODA_SQLITE_SEARCH_SCAN_LIMIT` and the `SCAN_BUDGET_EXHAUSTED` code
are removed, closing the divergence with memory and postgres. Bounding search
*time* is the caller's job, using `timeoutMillis` or cancellation. Bounding
search *memory* is the server's, and every search path now streams.
Two throughput fixes ride along: a model's parsed schema is cached alongside its
descriptor (on a 1000-field model, criterion evaluation drops from 1.84 ms and
12,400 allocations to 12 µs and 91), and the search leaf evaluator prepares once
per query instead of once per candidate row.
### ⏳ Async search operational hardening
Async search moves from one goroutine per submission to a bounded worker pool,
with a retryable **`503 SEARCH_QUEUE_FULL`** once workers and queue are both
exhausted. Five new env vars, all validated at startup rather than silently
clamped: `CYODA_SEARCH_ASYNC_WORKERS` (`8`), `CYODA_SEARCH_ASYNC_QUEUE` (`256`),
`CYODA_SEARCH_ASYNC_MAX_PER_TENANT` (`8`), `CYODA_SEARCH_JOB_HEARTBEAT_INTERVAL`
(`15s`), `CYODA_SEARCH_JOB_STALE_AFTER` (`5m`).
**Plan for the per-tenant cap.** It is on by default and counts queued and
running jobs together, so a single-tenant deployment's accepted-in-flight
ceiling drops from `workers + queue` (264) to **8**: a 50-submission burst that
was accepted in full now gets 8 accepted and 42 answered `503`. That is the
point — the cap is what stops one tenant locking every other tenant out — but a
single-tenant deployment sees only the cost. Raise it, or set `0` to restore
first-come-first-served.
A job whose owning node is lost is now **re-executed, not failed**. Every job
carries a claim epoch, and heartbeats, streamed result saves and the terminal
status write are all fenced against it, so an executor that was reaped and later
recovers has its next write rejected instead of corrupting a result set another
node has taken over. The reaper clears a claimed job's partial results and
re-runs it on a live node as at its originally stored point in time, so a client
observes only a longer `RUNNING` span. A graceful shutdown releases in-flight
jobs immediately for reclaim, and a released claim never counts against the
attempt cap, so a rolling restart of any length is free.
`CYODA_SEARCH_JOB_MAX_ATTEMPTS` (default `3`) bounds executor losses before the
job is failed. See `docs/cloud-parity/async-job-node-failure-resilience.md`.
Cancelling a job no longer leaves it permanently un-reapable: `CancelAsync`
called a generic status update that never stamped a finish time, and the reaper
only removes terminal jobs that have one, so every cancelled job accumulated for
the life of the process.
### 🎛️ Transaction-control parameters are honored
Three parameters that were accepted and silently ignored now do what they say:
- **`transactionTimeoutMillis`** on all seven entity write operations and
`newMessage`. It bounds time-to-first-commit; exceeding it rolls back and
fails **`408 TRANSACTION_TIMEOUT`** with nothing committed.
- **`transactionSize`** on `deleteEntities` and `deleteMessages`. Matching items
are deleted in independent batches; `deleteEntities` reports per-id errors in
`deleteResult.idToError` rather than retrying, and batches already committed
before a later failure stay committed.
- **`timeoutMillis`** on `searchEntities`, with **`408 SEARCH_TIMEOUT`** and no
partial results, enforced uniformly across memory, sqlite and postgres.
All three are rejected with `400` on a request that joins an open transaction,
where honoring them is unsafe. gRPC mirrors the same semantics.
A batched delete that can never finish now fails with a new retryable
**`409 DELETE_NOT_CONVERGED`** instead of running forever: with `transactionSize`
set and no `pointInTime`, the request re-selects before every batch, and if
entities are created at least as fast as they are removed, that pass never comes
up empty.
### 📣 The write-visibility contract
A successful write response already means the write is visible to every
subsequent read on every node, so `waitForConsistencyAfter` could toggle nothing.
It is retired from the seven entity write operations; a request that still
carries it is accepted and the parameter ignored. The contract, and what every
backend must do to meet it, is recorded in
`docs/cloud-parity/write-visibility-contract.md`.
The whole-model delete now honors `pointInTime` and `verbose` on both doors. Its
fast path ignored the instant — deleting entities created after it — and
returned an empty id list beside a non-zero count. The gRPC response's
`entityIds` is populated for the first time, and the inert `pageSize` field is
removed from `EntityDeleteAllRequest`.
### 🔀 Workflow correctness
**On a model with several imported workflows, every operation after creation ran
the wrong workflow's definition.** A named transition, a loopback re-evaluation
and a scheduled transition firing all resolved the workflow by "the first active
definition that declares the entity's current state", ignoring the entity's
selection criterion. Definitions on one model usually share state names, which
is the normal shape for a per-kind machine. In that case the resolver always
picked the first declared workflow, for every entity, applying the wrong guards,
processors and target states. It did so silently, and it failed open. Selection
at creation was correct, which is why the binding looked right in the creation
audit. All four doors now resolve through the documented criterion
rules on every call.
**Integrators:** because selection is re-evaluated per call, an entity whose
payload changes can re-bind to a different definition. Prefer selection criteria
that stay true for an entity's whole lifetime, and that read fields a caller
cannot rewrite in the same request — the criterion is evaluated against the
payload of the request being served, so where definitions differ in what they
permit, the selection field is a security control.
`GET /entity/{entityId}/transitions` no longer answers from the default workflow
when a selection criterion cannot be evaluated. That was a wrong-but-available
answer; it now fails the request. The same read was also writing
`WORKFLOW_SKIP`/`WORKFLOW_FOUND` audit events against an empty transaction id
despite intending not to.
A workflow processor's returned data is now governed by the model exactly as a
client's write is. A processor could previously write content no backend could
store, or fields the model does not declare — producing an entity the API would
return but then refuse to accept back on a `PUT`. A processor that writes a
field outside its model now needs that model's `changeLevel` set, or the field
declared.
A criterion carrying an operator nobody can evaluate now fails the save rather
than short-circuiting past it, and a model-store outage during criterion
evaluation is no longer masked by a structural error on a sibling conjunct.
### 🧱 Payload integrity
A family of payloads that were "valid JSON, unstorable" reached the store and
came back as `500` with a support ticket on PostgreSQL while memory and sqlite
accepted them — so the set of storable values depended on the backend. All are
now rejected at the boundary with `400`, on every backend and on both HTTP and
gRPC:
- A NUL (U+0000) anywhere in the payload.
- Unpaired UTF-16 surrogates and invalid UTF-8. The guard reads the raw request
bytes, which is load-bearing: Go's decoder rewrites both forms to U+FFFD, so
validating the decoded value cannot see them and re-serialising would store a
character the client never sent.
- A name repeated within one object. It was read as the *last* occurrence by
schema validation, the `GET` response and unique-key computation, and as the
*first* by criteria, search and grouped statistics — on the same bytes in the
same request.
- Trailing content after a valid JSON value (`{"x":1}}}`).
- A number outside PostgreSQL's `numeric` range.
The gRPC entity API now carries the client's payload bytes verbatim to the same
guard; it previously decoded and re-marshalled before validation. All five gRPC
entity write events enforce the full guard set.
Separately, an empty entity payload no longer bricks the entity **and its whole
model's listing** on PostgreSQL: `{}` was accepted with `200` and then failed
every subsequent read with `500`, including the model-wide listing, because one
unreadable row failed the whole page.
A processor returning `{"data":null}` no longer panics and leaks a database
connection.
### 🔐 Auth and cluster caches
- **`POST /api/oauth/oidc/providers/reload` no longer destroys the JWKS cache it
is documented to refresh.** The reload rebuilt the provider list but installed
empty key sources and never re-warmed them, so every federated token failed
`401 unknown kid` until a process restart — including providers that were
healthy before the call. Surviving key sources are now carried across the
rebuild and every loaded provider is force-warmed, on the receiving node and
on every broadcast peer.
- **A provider whose IdP was unreachable at startup no longer stays keyless for
the life of the process.** Failed warm-ups are retried every 30 seconds.
- **Trusted-key revocation propagates across the cluster**, and OIDC providers
converge after a dropped gossip broadcast.
- **Cross-node dispatch fails over to a peer** rather than failing the write.
### 🐘 Storage-backend conformance
A backend diverging from the others on the same contract is a defect, not an
accepted difference. This release closes a long list of them:
- **`CompareAndSave` compares the expected transaction ID literally on every
backend**, and rejects an empty one. The empty string named three states at
once — never written, deleted, and written outside any transaction — so "create
only" could silently overwrite an entity that exists. Compare-and-save can no
longer create or resurrect an entity: `Save` is how you create, and `Save` is
what unstages a delete.
- **Concurrent non-transactional compare-and-saves yield exactly one winner** on
all three backends; the check and the write are one atomic step.
- **A write inside a transaction carries that transaction's ID on every
backend.** memory and sqlite stamped only at commit; postgres honoured a
caller-supplied value. A row cannot claim it was committed by a transaction
that did not commit it.
- **A `pointInTime` read inside a joined transaction is committed-only on
PostgreSQL.** It ran on the caller's own transaction connection, so a snapshot
read answered with that transaction's uncommitted writes. Memory and sqlite
already behaved this way.
- **PostgreSQL's in-Go residual filter no longer sees the internal `_meta`
block**, so a condition naming a data path under `_meta` no longer matches
there and on no other backend.
- **PostgreSQL text comparisons use `COLLATE "C"`**, matching the ordering the
search kernel and `ORDER BY` already use. On a database whose default
collation is not byte order, a text range query can now return a different —
correct — set of rows.
- **sqlite numbers a new entity's first version 1**, matching memory and
postgres. Existing entities keep their stored numbers.
- **A client disconnect aborts in-flight per-item work on memory and sqlite**,
matching postgres.
- **sqlite's message batch-delete chunks its `IN` list** instead of breaking on
the driver's 32766 bound-variable limit.
### 📚 Help and documentation
Fourteen new error help topics — including `STORAGE_UNAVAILABLE`,
`TRANSACTION_TIMEOUT`, `SEARCH_TIMEOUT`, `SEARCH_QUEUE_FULL` and
`DELETE_NOT_CONVERGED` — plus ten grouped-statistics codes that were inline
string literals with no constant and no topic, so `cyoda help errors `
answered 404 for every one of them. `POLYMORPHIC_SLOT` and
`SCAN_BUDGET_EXHAUSTED` are retired.
Twenty new contract documents under `docs/cloud-parity/` (32 in total) state the behaviours
Cyoda Cloud mirrors, including `path-grammar.md`, `operator-semantics.md`,
`negation.md`, `numeric-type-admission.md`, `model-kind-enforcement.md`,
`write-visibility-contract.md` and `search-has-one-path.md`.
This list is long. The short version: if you send conditions, criteria or
`groupBy` paths, re-read them against the new grammar before upgrading.
**Paths and conditions**
- **A field path must be JSON Path.** `amount` is rejected; write `$.amount`.
Bracket-quoted access (`$['x']`), empty or trailing segments, and any
character outside `ALPHA / DIGIT / _ / -` are rejected. Applies to search
conditions, workflow criteria, `groupBy`, aggregation fields and sort keys.
- **A trailing `[*]` addresses elements, not the array's length.** A search that
returned an empty page now returns matches; a criterion that never fired now
fires, so entities sitting before a guarded transition will advance on their
next save. In the other direction, a comparison that held against the length
no longer matches. There is no path spelling for an array's length.
- **Malformed array subscripts are rejected** — slices, unions, negative
indices, filter expressions, unclosed brackets, trailing junk.
- **A trailing wildcard on an array of pure objects with a scalar operand is
`400 INVALID_FIELD_PATH`.** Navigate to the leaf sub-path.
- **An `array` clause's `jsonPath` must carry a trailing `[*]`**, and its
`values` are now type- and shape-checked.
- **A subscripted path is rejected on `groupBy`, aggregation fields and sort
keys** on every backend.
- **An unknown `operatorType` is `400 INVALID_CONDITION`** on every surface, and
fails workflow import.
- **A group condition's operator must be exactly `AND`, `OR` or `NOT`**,
case-sensitive.
- **String and pattern operators on `creationDate`/`lastUpdateTime` are
`400 INVALID_CONDITION`.** They previously answered `200` with results that
depended on which evaluator served the request.
- **A bare path no longer matches an array's elements, and a `[*]` path no
longer matches a scalar.** What a path addresses is decided by its syntax.
**Search behaviour**
- **`LIKE` is matched as a glob, not rewritten into a regex.** `%` and `_` now
match a newline; a backslash escape is now literal, so `LIKE "\d"` matches the
character `d` rather than any digit. Any operand carrying a backslash before an
ordinary character changes meaning. An unpaired trailing `\` is now rejected.
- **An invalid `LIKE` or `MATCHES_PATTERN` operand is rejected at the boundary**
with `400`, where it previously returned `200` and then failed or matched
nothing.
- **`NOT_EQUAL` against an unsatisfiable operand now matches.** `$.n NOT_EQUAL
12.5` on an `INTEGER` field returns every entity holding a number at `n`.
**Audit any conditional-delete automation using a negative operator** — it now
removes strictly more rows.
- **A `function` condition is rejected in a search body**, `400
INVALID_CONDITION`, at any depth. It is a criteria-only clause; search never
had a dispatcher for it.
- **A search whose model schema cannot be loaded is `500`**, not a `200` with a
silently wrong result set.
- **A condition naming a data path on a model that declares no fields is
`400 INVALID_FIELD_PATH`.**
- **Grouped stats validates its paths against the model** and no longer returns
plausible-looking empty buckets for undeclared fields.
- **`501 NOT_IMPLEMENTED_BY_BACKEND` and `SCAN_BUDGET_EXHAUSTED` are retired.**
- **`waitForConsistencyAfter` is retired** from the seven entity write
operations; still-sent values are ignored rather than rejected.
**Model and validation**
- **A value whose kind the field does not declare is rejected** — an array or an
object into a `STRING` field now answers `400 VALIDATION_FAILED`.
- **Model field names must be valid path segments.** Ingestion that previously
succeeded with an unspellable key now fails. No migration is provided: rename
the key and re-establish the model.
- **`POLYMORPHIC_SLOT` is retired.** Giving a path a kind it does not declare is
a `STRUCTURAL` change, so raising the level resolves it.
- **A payload failing against the model answers `400 VALIDATION_FAILED`, not
`400 BAD_REQUEST`.** The status is unchanged; only a client branching on the
code is affected.
- **`SIMPLE_VIEW` and `JSON_SCHEMA` emit different keys** for arrays of arrays,
multi-kind fields and never-observed array elements. `JSON_SCHEMA` unions are
`anyOf`, not `oneOf`.
- **A sample-data import body that is neither a document nor a collection of
documents is `400 VALIDATION_FAILED`.**
- **Numeric- and temporal-leaf model folding is order-dependent under concurrent
extension**, and that is accepted. Every reachable fold is monotone and admits
every value written; what varies is only how widely a future value is admitted
without a schema-change permission. Structural extension still converges
byte-identically.
- **A workflow processor's returned data is governed by the model.** A processor
writing a field outside its model now needs that model's `changeLevel`.
**Workflow**
- **Workflow schema moves to 1.4.** 1.1–1.4 are all accepted. Update any CI pin
reading `"current"` from `/help/workflows/schema-version/versions`.
- **A criterion's `jsonPath`, operator names and pattern operands are validated
at import**, `400 VALIDATION_FAILED`. Stored workflows keep evaluating and fail
on their next re-import.
- **A criterion naming an undeclared field aborts and rolls back the save.**
- **Workflow selection is re-evaluated on every door.** An entity may re-bind to
a different definition; if its current state is not declared there, the
transition is `400 WORKFLOW_FAILED` and a loopback settles as a no-op.
**Operational**
- **`CYODA_TX_TTL`, `CYODA_TX_REAP_INTERVAL` and `CYODA_TX_OUTCOME_TTL` are
removed.** They configured a reaper that never ran.
- **`CYODA_SQLITE_SEARCH_SCAN_LIMIT` is removed.** Remove it from your
configuration; it is no longer read.
- **PostgreSQL connections carry `statement_timeout` and
`idle_in_transaction_session_timeout`, both `5m` by default.** A processor
whose `responseTimeoutMs` exceeds the idle ceiling has its transaction
aborted; the 30s default sits well under it.
- **Pool acquisition fails with `503 STORAGE_UNAVAILABLE` after
`CYODA_POSTGRES_ACQUIRE_TIMEOUT`** rather than queueing indefinitely.
- **`CYODA_SEARCH_ASYNC_MAX_PER_TENANT` lowers the accepted-in-flight ceiling**
for single-tenant deployments from 264 to 8. Raise it or set `0`.
- **The SQLite reader pool raises the memory ceiling** to
`(readers + 1) × CYODA_SQLITE_CACHE_SIZE`.
- **Upgrading a populated PostgreSQL deployment briefly blocks writers to
`entities`.** Migration `000008` adds an index with a plain `CREATE INDEX`
rather than `CREATE INDEX CONCURRENTLY`, which provably deadlocks this
project's concurrent multi-node boot path. **Size a maintenance window to the
`entities` table's row count before upgrading.** See `docs/plugins/POSTGRES.md`.
- **A `pointInTime` read inside a joined transaction is committed-only on
PostgreSQL.** A compute-node callback that read its own uncommitted write this
way now gets `404 ENTITY_NOT_FOUND`. Omit `pointInTime` — a current-state read
inside a transaction is read-your-own-writes correct.
- **A recovered panic withdraws the node from service** (`/health` and `/readyz`
report `503`) without restarting it.
- **The gRPC `EntityDeleteAllRequest.pageSize` field is removed** from the
generated Go type. A client still sending it is tolerated.
**SPI (plugin authors)**
Out-of-tree plugins must be rebuilt against `cyoda-go-spi v0.8.4`:
- **`EntityStore` requires `Search` and `Iterate`;** `GetAll` and `GetAllAsAt`
are removed, and the optional `Searcher` and `Iterable` interfaces are folded
in. There is no deprecation window.
- **`CompareAndSave` must reject an empty `expectedTxID`** with a plain error,
not `ErrConflict`.
- **`AsyncSearchStore` gains `Release`; `SearchJob` gains `StaleClaims`.** A
`SelfExecutingSearchStore` may no-op `Release` and leave `StaleClaims` at 0.
- **`Filter.Prepare` / `PreparedFilter.Match` replace `MatchFilter`,
`EvalLeafString`, `evalLeafFast` and `Expansion.Void`,** with no deprecation
shim. A plugin doing its own per-row leaf evaluation must call `Prepare` once
**above** its row-scan loop and `Match` inside it — substituting the pair in
place inside the loop reintroduces the per-row cost the change removes.
- **`ConditionToFilter` and the model-schema read core now live in the SPI.**
cyoda-go deletes its copies; a backend that self-executes searches can now
reach the shared kernel instead of shipping a second evaluator.
- **`FieldDescriptor.MaxWidth`, `ArrayBranch.MaxWidth` and
`ModelNode.ObserveArrayWidth` are removed.**
- **`ModelNode` holds a set of branches**, and its API changed accordingly. A
plugin that decodes a schema itself needs the new pin.
- **`spitest` conformance gains cases** for the `TrackingRead` read-set contract
on both filter-taking read entry points, `CompareAndSave/EmptyExpectedIDRejected`,
and the `Release`/`StaleClaims` claim surface. A plugin that records per
scanned row rather than per yielded row fails on its next dependency update.
For the complete and authoritative list, consult the
[CHANGELOG](https://github.com/Cyoda/cyoda-go/blob/main/CHANGELOG.md#084--2026-09-09).
## 🛡️ Security
- **Cross-tenant timestamp leak closed.** `GetSubmitTime` was the only
transaction-lifecycle method without a tenant check: a caller supplying another
tenant's transaction ID — reachable via
`GET /entity/{id}/transitions?transactionId=` — could learn that transaction's
submit time or its in-flight state. All three storage backends now reject
cross-tenant lookups before any state-dependent response, and the endpoint
answers the same `400` for a foreign transaction ID as for a nonexistent one.
The SQLite `submit_times` table gains a `tenant_id` column (migration 000005,
drop-and-recreate; rows carry a 1-hour TTL).
- **A `4xx` body no longer amplifies with a malicious request.** Three
response-body amplification paths are bounded, and a decoding-contract
violation now answers `5xx` with a ticket instead of echoing an internal
decoding instruction or a Go type name into a `400`.
- **A raw driver error is no longer interpolated into an async-search `400`
body**, where it could carry connection detail.
- **A bare context cancellation escaping workflow evaluation is a sanitized
`500`**, not a `400` carrying the error's own text as domain detail.
- **Three permissive defaults on an unreachable parse error are now
fail-closed** in each of the memory, sqlite and postgres plugins.
- **Workflow selection criteria are a security control.** Because selection is
re-evaluated per call against the payload of the request being served, prefer
criteria reading fields a caller cannot rewrite in the same request.
## 🚀 Resources & getting started
For installation guides, building from source, architecture, and running the
engine locally or in production:
- [**Cyoda Hub (cyoda.dev)**](https://cyoda.dev) — the primary portal for the
Cyoda ecosystem, community links, and major updates.
- [**Cyoda Documentation (docs.cyoda.net)**](https://docs.cyoda.net) —
quick-starts, configuration schemas, API references, and operations guides.
- [**GitHub Project (github.com/Cyoda/cyoda-go)**](https://github.com/Cyoda/cyoda-go)
— source code, build requirements, and binary releases with cryptographic
checksums under the
[v0.8.4 release tag](https://github.com/Cyoda/cyoda-go/releases/tag/v0.8.4).
## 💬 Feedback
Found a bug, hit a parity gap, or have a feature request? Open an issue or
start a thread in our
[GitHub Discussions](https://github.com/Cyoda/cyoda-go/discussions) — and
feel free to join us on
[Discord](https://discord.com/invite/95rdAyBZr2). Thank you for building with
Cyoda-Go!
## 📌 Footnote: why v0.8.4 is a patch that still breaks things
v0.8.4 is a patch release that carries breaking changes — listed in the caution
above. Pre-1.0 the minor component is the breaking-change signal and features
ship in patches; this release departs from that on the path grammar, the search
execution contract, the model's type-admission rules, and the SPI. Read the
breaking-changes list before upgrading rather than inferring compatibility from
the version number.
`cyoda-go-spi` ships its own breaking changes as **v0.8.4**. It is versioned on
an independent axis from the binary — see
[`COMPATIBILITY.md`](https://github.com/Cyoda/cyoda-go/blob/main/COMPATIBILITY.md)
for the supported combinations.
---
## run.md
# Run
The cyoda-go packaging ladder — desktop, docker, kubernetes, and hosted Cyoda Cloud.
Cyoda runs on the tier that fits the job. Every packaging runs the same
application and the same workflow semantics; what changes is durability,
fault tolerance, and operational cost. Pick your packaging by what
you need to operate, not by what your app needs to do.
## Pick your packaging
| | In-Memory | SQLite | PostgreSQL | Cassandra |
|------------------|-----------|---------------|------------------|------------------|
| **Desktop** | ✓ | ✓ *(default)* | | |
| **Docker** | ✓ | ✓ | ✓ | |
| **Kubernetes** | | | ✓ *(production)* | ✓ *(Enterprise)* |
| **Cyoda Cloud** | | | | ✓ *(managed)* |
→ For per-engine durability, fault tolerance, and deployment scope, see [Storage engines](./storage-engines/).
## When to pick what
- **[Desktop](./desktop/)** — a single binary on a laptop or a small server.
In-memory for tests; SQLite as the default durable store. Right for
development, edge, IoT, and small-team self-hosting.
- **[Docker](./docker/)** — the same binary containerised. Use it for
bespoke integrations, composition with other services, local PostgreSQL
runs, and CI pipelines.
- **[Kubernetes](./kubernetes/)** — the production packaging for
self-hosted clusters. Active-active stateless cyoda-go pods behind a
load balancer with PostgreSQL as the only stateful dependency. Helm
chart ships from cyoda-go. The same Helm-deployed cluster, licensed
under **Enterprise**, runs against the Cassandra plugin for horizontal
write scale-out — same packaging, different storage tier.
- **[Cyoda Cloud](/cyoda-cloud/)** — cyoda-go delivered as a managed
service (coming soon). Isolated Postgres environments on the shared
tier, with dedicated and Cassandra-backed enterprise tiers above.
Right when you do not want to operate the infrastructure yourself.
## Moving between tiers
The application does not change when you move. That is the whole point of
the growth path: start on Desktop, containerise when integration demands
it, cluster on Kubernetes when scale demands it, and switch to the
Cassandra-backed tier — self-hosted under Enterprise or managed via
Cyoda Cloud — when single-PG write capacity becomes the constraint.
See [Digital twins and the growth path](/concepts/digital-twins-and-growth-path/)
for the decision framework.
## License and editions
Cyoda ships in three editions. Pick by how you want to consume it; the
application contract is the same across all three.
| Edition | License | Storage tiers | Status |
|---|---|---|---|
| **cyoda-go** | Apache 2.0 (OSS) | In-memory, SQLite, PostgreSQL | Generally available |
| **Enterprise** | Commercial (self-hosted) | Cassandra-backed | Available — contact sales |
| **Cyoda Cloud** | Commercial (hosted service) | Cassandra-backed | Beta — test/demo only; commercial SLAs planned |
The **cyoda-go** binary — everything in [Build](/build/) and
[Reference](/reference/) works against it — is Apache 2.0 and free to
use for development and production on the Desktop, Docker, and
Kubernetes packagings with the in-memory, SQLite, or PostgreSQL
storage engines. The **Cassandra-backed** tier (horizontal scale for
write volume and distributed `async` search) ships two ways: as a
self-hosted **Enterprise** distribution — the same Kubernetes Helm
chart, licensed for the Cassandra plugin — and as the hosted **Cyoda
Cloud** managed service. Cyoda Cloud is currently a Beta for test and
demonstration; production workloads on the Cassandra tier run under
the Enterprise license today.
---
## run/desktop.md
# Desktop (single binary)
Run cyoda-go from a single binary — dev, low-volume production, in-memory and SQLite modes.
The desktop packaging is cyoda-go as it ships out of the box: a single
binary, no orchestrator, no external database. It is the right choice for
local development, edge deployments, small-team self-hosting, and any
low-volume production workload where a single machine is enough.
## In-memory vs SQLite
The desktop binary supports two storage modes:
- **In-memory** — everything lives in process memory. Sub-millisecond
latencies. Data is lost on restart. Use it for tests, demos, and
digital-twin scenario runs.
- **SQLite (default after `cyoda init`)** — durable, single-file, zero-ops. Data survives
restarts; backup is a file copy. Use it for everyday persistent work.
SQLite is single-writer; all writes serialize through the database file,
which limits concurrent write throughput.
The SQLite database file is created at `~/.local/share/cyoda/cyoda.db` by
`cyoda init`. Back it up by copying the file; migrate it by moving the file.
## Install
Pick the installer that suits your platform; the authoritative list lives in
the [cyoda-go README](https://github.com/Cyoda/cyoda-go#install).
```bash
# macOS / Linux via Homebrew
brew install cyoda/cyoda-go/cyoda
```
Debian, RHEL, and `curl | sh` installers are available in the same
document.
## Run
The Homebrew and packaged installers run `cyoda init` for you, which sets
up the SQLite store. To start the server:
```bash
cyoda
```
The binary exposes REST on port **8080** and gRPC on **9090** by default.
The full CLI reference lives at [Reference → CLI](/reference/cli/).
## Configure
cyoda-go reads configuration from environment variables, a config file, or
CLI flags. The full list of options lives at
[Reference → Configuration](/reference/configuration/); for everyday use
the defaults are fine, and you only set a handful of variables
(`CYODA_STORAGE_BACKEND`, listen ports, JWT keys) to adapt to your environment.
For secrets, cyoda-go supports `*_FILE` suffixes on any credential
environment variable so you can mount them from a secrets store rather than
pass them on the command line.
## Upgrading
Upgrading is a version bump: install the new binary, restart the process.
cyoda-go follows semantic versioning; configuration migration policy is
documented in the
[cyoda-go release notes](https://github.com/Cyoda/cyoda-go/releases).
---
## run/docker.md
# Docker
Run cyoda-go in Docker for bespoke integrations and local compositions.
Docker is the right packaging when you need cyoda-go to sit inside a larger
composition — with your app, with a PostgreSQL backend, with an observability
stack — or when your CI pipeline wants a clean container image per run.
## When Docker fits
- **Bespoke integrations.** Deploy cyoda-go alongside your own services on a
single host, wire them over a Docker network.
- **Composed environments.** Run cyoda-go with PostgreSQL, Prometheus,
Grafana, and OpenTelemetry collectors as a complete local stack.
- **PostgreSQL for dev and test.** Point cyoda-go at a containerised
PostgreSQL to exercise production-mode behaviour locally before
deploying.
- **CI pipelines.** Ephemeral, reproducible, no host state.
## Image
cyoda-go publishes container images per release. The authoritative reference
and pull instructions live in the
[cyoda-go Docker reference](https://github.com/Cyoda/cyoda-go/tree/main/deploy/docker).
## Compose example
The repository ships a minimal `compose.yaml` for getting a single node and
PostgreSQL up, plus a richer
[compose-with-observability](https://github.com/Cyoda/cyoda-go/tree/main/examples/compose-with-observability)
example that wires tracing and metrics.
Use these as templates rather than retyping them here — they track the
cyoda-go release and we link whichever is current.
## PostgreSQL backend
Point cyoda-go at a PostgreSQL instance by setting `CYODA_STORAGE_BACKEND=postgres`
and the usual connection variables (or `*_FILE` forms for secrets). The DSN
goes in `CYODA_POSTGRES_URL` (or `CYODA_POSTGRES_URL_FILE` for a file-mounted
secret per Docker conventions). The Docker compose example wires this up
end-to-end; for production you will run PostgreSQL separately and pass only
the DSN.
## Observability
The container emits structured logs to stdout, exposes a Prometheus scrape
endpoint for metrics, and accepts OpenTelemetry configuration for traces.
The observability example demonstrates a full loop:
- **Logs** — stream from the cyoda-go container.
- **Metrics** — Prometheus scrapes the admin port.
- **Traces** — OTLP exporter configured via environment.
Tune sampling and log level at runtime via the admin endpoints;
see the
[cyoda-go observability reference](https://github.com/Cyoda/cyoda-go#observability).
Health probes live on the admin port (default 9091): `/livez` (liveness) and
`/readyz` (readiness). Both are unauthenticated. A node that recovers a panic in
engine or store work marks itself permanently unhealthy. `/readyz` and
`/health` then report `503`, and `/livez` continues to pass. An orchestrator
therefore stops routing to the node, and it does not restart it.
Three receive-side HTTP timeouts apply to the API server and to the admin
server: `CYODA_HTTP_READ_HEADER_TIMEOUT` (`10s`), `CYODA_HTTP_READ_TIMEOUT`
(`5m`) and `CYODA_HTTP_IDLE_TIMEOUT` (`2m`). `CYODA_HTTP_WRITE_TIMEOUT` ships
disabled, so the server sets no limit on how long a request may take to produce
its response.
## Data directory
The container pre-stages `/var/lib/cyoda` as the data directory (with the
correct ownership for the non-root `65532:65532` user). Mount it as a named
volume if you want SQLite data or any plugin state to persist across
container restarts.
---
## run/kubernetes.md
# Kubernetes
Deploy cyoda-go with the Helm chart for clustered PostgreSQL-backed production.
Kubernetes is the recommended production packaging for self-hosted cyoda-go.
The application is designed for active-active stateless deployment: three to
ten cyoda-go pods behind a load balancer, with PostgreSQL as the only
stateful dependency.
## When Kubernetes fits
- **Production workloads** that need high availability.
- **Multi-node clustering** with rolling upgrades and blue/green.
- **Horizontal scale** up to the PostgreSQL backend's limits (10+ stateless
pods serving one PostgreSQL cluster is a comfortable envelope).
- **Enterprise operations** — GitOps, secrets management, service meshes.
## Deployment shape
```
┌─────────────┐
│ Load │
│ Balancer │
└──────┬──────┘
│
┌────────┼────────┐
│ │ │
┌────▼─┐ ┌────▼─┐ ┌────▼─┐
│cyoda │ │cyoda │ │cyoda │ (stateless, 3–10 pods)
│-go │ │-go │ │-go │
└────┬─┘ └────┬─┘ └────┬─┘
│ │ │
└────────┼────────┘
│
┌──────▼──────┐
│ PostgreSQL │ (the only stateful dependency)
└─────────────┘
```
Every pod is identical; any pod can serve any request. There is no leader
election, no ZooKeeper, no etcd. Coordination happens through PostgreSQL's
SERIALIZABLE isolation for writes and a gossip protocol (HMAC-authenticated)
for membership, so concurrent writers never silently corrupt data.
The stateful backend is pluggable: PostgreSQL (OSS default) or the
commercial Cassandra storage engine. The pod topology and the application
contract are identical either way — only the storage plugin configuration
differs.
## Helm chart
cyoda-go ships a Helm chart under
[`deploy/helm`](https://github.com/Cyoda/cyoda-go/tree/main/deploy/helm).
The chart provisions the cyoda-go Deployment, a Service, a ConfigMap for
non-sensitive configuration, and Secret references for credentials.
The authoritative values reference lives under
[Reference → Helm values](/reference/helm/); the chart's own `values.yaml`
remains the runtime source of truth.
The Helm chart auto-generates the HMAC secret unless
`cluster.hmacSecret.existingSecret` is provided. GitOps deployments should
always set `existingSecret` to avoid Helm rendering a fresh secret on every
reconcile, which would cause inter-node auth to drift.
## High availability
- **Load balancer.** Any Kubernetes-native L4 or L7 will do; match the pod
readiness probe to the one the chart exposes.
- **Readiness and liveness probes.** Both are wired by default; tune if
your control plane has stricter latency budgets.
- **A node that panics withdraws itself and stays down.** See
[a panicked node withdraws itself](#a-panicked-node-withdraws-itself).
- **Pod Disruption Budgets.** Set a minimum available count that matches
your replica count minus one so rolling upgrades and node drains do not
take the service below quorum.
### A panicked node withdraws itself
A recovered panic in engine or store work marks the node permanently unhealthy.
`/health` reports `503 DOWN` and `/readyz` reports `503`, so Kubernetes removes
the pod from its Service in approximately 10 to 15 seconds. `/livez` still
passes, so Kubernetes does not restart the pod.
Two things keep running in the meantime. Peer-forwarded work still arrives, and
established connections stay open. Read the ticket id from the log, then
replace the pod.
## Backup and restore
Backup is standard PostgreSQL tooling: `pg_dump`, continuous WAL archiving,
snapshot-based backups from your cloud provider. cyoda-go does not maintain
any state outside PostgreSQL, so a PostgreSQL restore brings the platform
back to that point in time in full.
## Upgrades and rollback
cyoda-go releases follow semantic versioning. For production:
- **Blue/green or canary.** Run the new version alongside the old, cut
traffic over, retire the old.
- **Rolling upgrade.** Fine for minor releases; set `maxUnavailable: 0` so
capacity never drops.
- **Schema migration ordering.** Check the release notes for whether a
release requires a PostgreSQL schema migration step before the new binary
starts serving. The Helm chart runs schema migrations as a
pre-install/pre-upgrade hook; pod startup is blocked until migrations
complete.
## Sizing
Sizing is driven by write volume more than read volume, because reads scale
horizontally across pods while writes are serialised through PostgreSQL.
Qualitative guide:
- **Small.** 3 pods, `db.small` (or equivalent), up to a few hundred
transitions per second.
- **Medium.** 5–7 pods, dedicated PostgreSQL, low thousands of
transitions per second.
- **Large.** 10 pods with PostgreSQL scaled up; at this point consider
swapping to the commercial Cassandra storage engine (still on
Kubernetes), or handing operations to Cyoda Cloud as a SaaS.
## Observability
The chart exposes a Prometheus scrape annotation on the pods and surfaces
the admin endpoints for log-level and tracing control. Standard
OpenTelemetry configuration applies; wire OTLP exporters via environment
variables in the Helm values.
## Scaling past PostgreSQL
At the upper end of the sizing guide, PostgreSQL's write throughput
becomes the bottleneck. Two paths past it — the application contract
is identical in both:
- **Swap to the commercial Cassandra storage engine, still on
Kubernetes.** The licensable plugin replaces the PostgreSQL backend
with a horizontally-scaling Cassandra-backed tier. The Helm chart,
the pod topology, and the application code are unchanged — only the
storage plugin configuration changes.
- **Hand operations to Cyoda Cloud** (coming soon) — the managed
service that runs the stack for you, from shared Postgres up to the
Cassandra-backed enterprise tier. Same application contract,
different operational model.
See [Cyoda Cloud](/cyoda-cloud/) for the managed option; contact sales
for the commercial Cassandra plugin.
---
## run/storage-engines.md
# Storage engines
Five ways to run Cyoda — one application contract.
Cyoda runs on five storage configurations: four pluggable engines that
ship with `cyoda-go` (in-memory, SQLite, PostgreSQL, and a commercial
Cassandra plugin) plus the classic Kotlin runtime that has powered Cyoda
Cloud in production since 2017. They differ in durability, fault
tolerance, and operational footprint — but the **application contract
is identical across all five.** Code written against one runs unchanged
against any other.
## One application contract
Every Cyoda runtime offers the same isolation contract: **Snapshot
Isolation with First-Committer-Wins on entity-level conflicts** (SI+FCW).
What that gets you:
- **Snapshot reads** — a transaction sees a consistent point-in-time
view of the data, regardless of concurrent writes.
- **Entity-level conflict detection at commit** — if another transaction
modified an entity you read or wrote, your transaction aborts at
commit and you retry.
- **First-committer-wins on write/write conflicts** — concurrent updates
to the same entity resolve deterministically; the second commit
aborts.
What it does **not** give you:
- **No phantom or predicate protection.** A transaction that counts
rows matching a predicate cannot rely on the count being stable
across the transaction's lifetime. Workflow logic that needs
predicate-stable counts has to be expressed as an explicit
serialization point — see the operational rule for workflow authors
in [Concepts → Entities and lifecycle](/concepts/entities-and-lifecycle/).
The contract is delivered identically by every engine. cyoda-go's
in-memory and SQLite plugins implement SI+FCW in process. The
PostgreSQL plugin layers it on PostgreSQL `REPEATABLE READ`. The
Cassandra plugin and the classic CPL runtime implement it against
Cassandra primitives. The application has no way to tell which engine
it is running against — and that is the point.
**A successful write is visible everywhere.** A `2xx` write response means that
the data is visible to every later read on every node. A caller can write and
then read its own data back.
Every engine also agrees on these details:
- Compare-and-save compares the expected transaction id literally, and refuses
an empty one.
- A write inside a transaction carries that transaction's id.
- A point-in-time read inside a transaction is committed-only.
- Text comparisons order by byte value.
- A client disconnect stops the in-flight per-item work.
## At a glance
| Engine | Durability | Fault tolerance | Scale envelope | Footprint | Distribution | Best-fit scope |
|---|---|---|---|---|---|---|
| **In-memory** | Ephemeral | None — restart loses data | Bounded by host RAM | Single binary, no deps | OSS — ships with cyoda-go | Tests, digital-twin sims |
| **SQLite** | Durable (single file) | Single-process; survives restart, not disk loss | Single node, disk-bound | Single binary, no deps | OSS — ships with cyoda-go | Desktop, edge, single-node prod |
| **PostgreSQL** | Durable, replicated via PostgreSQL | HA via PostgreSQL replication & failover; mid-transaction node loss returns `TRANSACTION_NODE_UNAVAILABLE` (client retries) | Multi-node stateless cluster; writes bounded by single PG primary | cyoda-go nodes + PostgreSQL 14+ (managed or self-hosted) | OSS — ships with cyoda-go | Multi-node production; audit / compliance |
| **Cassandra** | Durable, replicated via Cassandra | Cluster-tolerant; transactions survive mid-flight node loss | Horizontal write scale-out, multi-cluster | cyoda-go nodes + Cassandra + Redpanda | Commercial — Enterprise edition or via Cyoda Cloud | Write-heavy scale-out; HA without retry-on-node-loss |
| **CPL / Classic** | Durable, replicated via Cassandra | Production-hardened since 2017; Cassandra-backed HA | Horizontal scale-out (Cassandra-backed); managed by Cyoda | None on your side | Managed service — Cyoda Cloud | Consume Cyoda as a service |
All five share the same SI+FCW application contract. *Distribution*
describes how you obtain the engine — open source in the cyoda-go repo,
commercial license, or managed service — not uptime or fault tolerance.
## In-memory
The in-memory plugin keeps all entity state in process memory.
Transactions complete in microseconds; there are no I/O paths and no
external dependencies. State is lost when the process exits.
It is the right choice for tests and for digital-twin simulations where
durability is delegated to a snapshot mechanism elsewhere. It is **not**
appropriate for any deployment where data must survive a restart.
A single process owns the store; there is no way to share in-memory
state across processes. Memory consumption is bounded by host RAM.
## SQLite
The SQLite plugin gives you durable single-node storage with the same
zero-dependency footprint as in-memory: a single `cyoda-go` binary, a
single database file, no other moving parts. The driver is a pure-Go
WASM build of SQLite — no CGO, clean cross-compilation.
SQLite provides only database-level write locking; entity-level
conflict detection (SI+FCW) is layered on top by `cyoda-go`. The
running process holds an exclusive `flock` on the database file for its
entire lifetime, so a second `cyoda-go` against the same file fails
fast at startup with a clear error. Two processes sharing a file would
have independent SI+FCW state and silently corrupt each other.
Best-fit deployments: desktop applications, edge devices, containerised
single-node production. The combination of "must survive restart" and
"single process is enough" lands here.
**Not** suitable for NFS-mounted database files (SQLite itself is
unreliable on NFS), nor for any deployment that needs more than one
`cyoda-go` process against the same data. If either of those applies,
move to PostgreSQL.
### Size the reader pool against your memory limit
The SQLite plugin opens a dedicated pool of read connections, so a long scan
does not block concurrent writes. `CYODA_SQLITE_READER_POOL_SIZE` sets the pool
size. It defaults to `GOMAXPROCS`, limited to the range 4 to 8.
Plan for the memory cost. `CYODA_SQLITE_CACHE_SIZE` (default `64000` KiB) is
**per connection**. The resident ceiling is therefore
`(readers + 1) × CYODA_SQLITE_CACHE_SIZE`. On an 8-CPU host with the default
values, that is approximately 562 MiB.
`GOMAXPROCS` follows the CPU quota, and it does not read the memory limit. In a
container with many cores and little memory, lower the pool size, the cache
size, or both.
## PostgreSQL
The PostgreSQL plugin is `cyoda-go`'s production multi-node tier. A
small cluster of stateless `cyoda-go` nodes — typical deployments run a
handful — sits behind a load balancer with PostgreSQL as the only
stateful dependency. Cluster discovery is gossip-based (HashiCorp
memberlist, embedded, pure Go); there is no ZooKeeper, etcd, or Kafka
to operate.
PostgreSQL 14 or later is required. The plugin works with any managed
PostgreSQL platform — RDS, Cloud SQL, Azure Database, Supabase, Neon,
Aiven — or with self-hosted PostgreSQL. SI+FCW is implemented as
PostgreSQL `REPEATABLE READ` plus an application-layer first-committer
validation at commit time. Tenant isolation is enforced via PostgreSQL
Row-Level Security as defense-in-depth: even an application-layer bug
in tenant scoping cannot leak data across tenants.
Write throughput is bounded by the single PostgreSQL primary's write
capacity. The cluster scales out for connection capacity and read
fan-out, not for writes against a single PG primary.
### Ceilings, saturation, and the upgrade window
The plugin sets five configurable ceilings on the database side. All five are
on by default. Each one takes a Go duration. Set a value to `0` to disable that
limit. A malformed value stops the server at startup.
| Variable | Default | Bounds |
|---|---|---|
| `CYODA_POSTGRES_STATEMENT_TIMEOUT` | `5m` | Any single statement |
| `CYODA_POSTGRES_IDLE_IN_TX_TIMEOUT` | `5m` | Idle gap inside an open transaction |
| `CYODA_POSTGRES_ACQUIRE_TIMEOUT` | `10s` | Waiting for a pooled connection |
| `CYODA_POSTGRES_MIGRATE_LOCK_TIMEOUT` | `5m` | Migration advisory lock |
| `CYODA_POSTGRES_SEARCH_STATEMENT_TIMEOUT` | `30m` | Async-search statements |
The database aborts the transaction of a workflow processor whose
`responseTimeoutMs` is longer than the idle-in-transaction ceiling. The processor default of 30
seconds is well below the 5-minute ceiling, so this affects long callouts only.
Three conditions return a retryable **`503 STORAGE_UNAVAILABLE`**: the pool
could not supply a connection, the idle ceiling aborted the transaction, and
the connection went away. Seven `cyoda_storage_pool_*` metrics report pool
saturation at `/metrics`. They are always on.
Migration `000008` adds an index to the `entities` table with a plain
`CREATE INDEX`. Writers to `entities` are blocked while the index builds.
On a populated deployment, plan a maintenance window sized to the row count of
the `entities` table.
The plugin makes one explicit, accepted trade-off: each transaction is
pinned to the `cyoda-go` node that opened it. If that node dies
mid-transaction, PostgreSQL rolls back the connection and the client
receives `TRANSACTION_NODE_UNAVAILABLE` and must retry from scratch.
This trade-off is what lets the plugin run without Paxos, Raft, or
ZooKeeper. For deployments that cannot tolerate this failure mode, the
Cassandra plugin removes it.
## Cassandra (commercial)
The Cassandra plugin is the answer for write volumes that exceed what a
single PostgreSQL primary can absorb, and for high-availability
deployments that cannot tolerate `TRANSACTION_NODE_UNAVAILABLE`.
Transactions are coordinated within the plugin itself rather than
pinned to an owning `cyoda-go` node, so a transaction survives the
mid-flight loss of any one node. The store scales horizontally without
a single-primary bottleneck and supports multi-DC topologies.
The operational footprint is larger than the PostgreSQL plugin: a
Cassandra cluster, a Redpanda message broker, and the `cyoda-go` nodes.
This is the same storage lineage that has run Cyoda Cloud in production
since 2017 — operational provenance, not a sales pitch.
There is one shape to watch for. The plugin is designed for entities
updated at moderate frequency — tens to low hundreds of versions over
an entity's lifetime. A single entity updated thousands of times per
day will let its version chain, partition size, and checkpoint cost
grow unbounded. The fix is a modelling one: represent the high-churn
state as a linked list of entities, where each "version" is its own
entity (a node in the list) rather than a new revision of one
long-lived entity.
The Cassandra plugin is available commercially — as the **Enterprise**
edition for self-hosted deployments and, ahead, as the enterprise
storage tier of **Cyoda Cloud**. For sizing or licensing, contact
Cyoda.
## CPL / Classic
The classic Kotlin/Java runtime has powered Cyoda Cloud in production
with clients since 2017, on a Cassandra storage backend. `cyoda-go` is
an adaptation of the EDBMS design that emerged from CPL — same
contract, same data model, same workflow semantics, different host
language and operational shape.
CPL today is an enterprise engagement: the runtime is operated by
Cyoda for established clients. The next generation of **Cyoda Cloud**
— the self-service managed home for cyoda-go applications — is being
built now; see [Cyoda Cloud](/cyoda-cloud/) for the design and
roadmap.
## Choosing an engine
Match the engine to the operational shape you can sustain:
- **Local development and tests** — start on **in-memory**. Microsecond
transactions, no setup, no cleanup.
- **Desktop, edge, single-node production** — **SQLite**. Durable,
embedded, single binary.
- **Multi-node self-hosted production**, including audit and compliance
workloads — **PostgreSQL**. Managed PG keeps the operational footprint
small.
- **Write throughput exceeds single-PG-primary capacity, or HA without
`TRANSACTION_NODE_UNAVAILABLE`** — **Cassandra** (Enterprise edition).
- **Don't want to run any of it** — **Cyoda Cloud**.
### When to switch
The progression is not a forced upgrade path; some deployments stay on
SQLite indefinitely and that is the right answer for them. Switch when:
- **Write throughput approaches the single-PG-primary ceiling** in
PostgreSQL deployments, with no managed-PG headroom left or the
upgrade exceeding the cost of moving — consider Cassandra.
- **Mid-transaction node loss is unacceptable** in your availability
budget — consider Cassandra; the plugin coordinates transactions at
the cluster level rather than pinning them to a single node.
- **Operational footprint outweighs the benefit of self-hosting** —
consider Cyoda Cloud.
The application contract does not change when you move. The
[growth-path framing in Concepts](/concepts/digital-twins-and-growth-path/)
covers the decision in narrative form.
## Where to next
- **Concepts** — [What is Cyoda](/concepts/what-is-cyoda/),
[Entities and lifecycle](/concepts/entities-and-lifecycle/),
[Digital twins and the growth path](/concepts/digital-twins-and-growth-path/).
- **Reference** — [Configuration](/reference/configuration/) for per-engine
environment variables, [CLI](/reference/cli/) for `cyoda-go` commands.
- **Cyoda Cloud** — [hosted service overview](/cyoda-cloud/).
---
## tools.md
# Tools
Developer tools, libraries, and project templates for building and operating Cyoda applications.
Cyoda maintains a set of open-source tools around the platform. They are
developed in their own repositories under
[github.com/Cyoda](https://github.com/Cyoda) and released independently of
cyoda-go.
| Tool | What it is | Runs against |
|---|---|---|
| [Cyoda Skills](./cyoda-skills/) | Skill set for AI coding agents (Claude Code plugin) | cyoda-go, Cyoda Cloud |
| [Dev Console and model-editor MCP](./dev-console/) | Desktop app and MCP server for viewing and editing workflow and entity model files | Local files, no instance required |
| [Workflow editor libraries](./workflow-editor/) | TypeScript packages to parse, render, and edit Cyoda workflow JSON | Your own application |
| [Environment dashboard](./env-dashboard/) | Web UI for investigating and exploring a running environment | Cyoda Cloud; cyoda-go with a reduced feature set |
| [Java client template](./java-client-template/) | Spring Boot template for Java/Kotlin Cyoda applications and compute nodes | Any Cyoda instance |
| [Python client template and MCP](./python-client-template/) | Quart template for Python compute nodes, plus an MCP server for Cyoda instances | Any Cyoda instance |
## Which tool for which job
- **Designing and building an app with an AI agent** — start with
[Cyoda Skills](./cyoda-skills/). Add the
[model-editor MCP](./dev-console/#model-editor-mcp) to watch the agent's
workflow and entity edits render live.
- **Reviewing or correcting generated workflow JSON** — the
[Dev Console](./dev-console/).
- **Writing compute nodes** — cyoda-go is language-agnostic: a compute node
is any process that speaks the gRPC protocol described in
[Client compute nodes](/build/client-compute-nodes/). AI coding agents
build them effectively from `cyoda help`, the
[API reference](/reference/api/), and [Cyoda Skills](./cyoda-skills/).
If you want an opinionated Java/Kotlin or Python starting point instead,
fork the [Java](./java-client-template/) or
[Python](./python-client-template/) template.
- **Inspecting entities, workflows, and processing on a running
environment** — the [environment dashboard](./env-dashboard/).
- **Showing or editing workflows in your own UI** — the
[workflow editor libraries](./workflow-editor/).
---
## tools/cyoda-skills.md
# Cyoda Skills
Skill set that teaches AI coding agents to set up, design, build, and debug Cyoda applications.
Repository: [github.com/Cyoda/cyoda-skills](https://github.com/Cyoda/cyoda-skills)
· Apache-2.0
Cyoda Skills are reusable instructions that teach an AI coding agent how to
provision a Cyoda instance, model entities, define workflows, implement
compute processors, and test the result. Claude Code is the best-supported
agent; the skill files are plain Markdown and can be read by any agent.
## Install
### Claude Code
Install from the plugin marketplace:
```text
/plugin marketplace add Cyoda/cyoda-skills
/plugin install cyoda@cyoda
/reload-plugins
```
Then start the guided journey:
```text
/cyoda:app
```
### Other agents
Point the agent at the repository and ask it to read the skill files before
building, for example:
> Read the skills in https://github.com/Cyoda/cyoda-skills and use them to
> help me build a Cyoda application.
## Skills
| Skill | Purpose |
|---|---|
| `/cyoda:app` | Entry point — walks the full build journey |
| `/cyoda:setup` | Install cyoda-go locally or connect to Cyoda Cloud |
| `/cyoda:auth` | Authenticate to Cyoda Cloud (obtain a JWT) |
| `/cyoda:design` | Design entities and workflows for an application |
| `/cyoda:build` | Incrementally build and register entity models and workflows |
| `/cyoda:compute` | Implement compute node processors and criteria services over gRPC |
| `/cyoda:test` | Smoke-test a running instance |
| `/cyoda:debug` | Diagnose failures and browse entity history |
| `/cyoda:migrate` | Move an application from local cyoda-go to Cyoda Cloud |
| `/cyoda:docs` | Look up Cyoda documentation |
| `/cyoda:status` | Report the current connection status |
`/cyoda:docs` prefers `cyoda help` on the local binary, which is
version-accurate, and falls back to this site.
## Related
- [model-editor MCP](/tools/dev-console/#model-editor-mcp) — live view of
the model files an agent is editing.
- [Build](/build/) — the manual reference behind what the skills do.
---
## tools/dev-console.md
# Dev Console and model-editor MCP
Local, file-based tools for viewing and editing Cyoda workflow and entity models — a desktop app and an MCP server for AI CLIs.
Repository: [github.com/Cyoda/cyoda-dev-console](https://github.com/Cyoda/cyoda-dev-console)
· MIT
The repository ships two artifacts for working with workflow and entity model
files on disk. Neither needs a running Cyoda instance. Both are built on the
[workflow editor libraries](/tools/workflow-editor/).
- **Dev Console** — a desktop app for inspecting and correcting workflow JSON
during the build phase, with an optional in-app AI assistant.
- **model-editor MCP** (`@cyoda/model-editor-mcp`) — an MCP server that
serves the workflow and entity editor to a browser and is driven by an AI
CLI such as Claude Code. The agent edits the model files and the diagram
updates live.
## Dev Console
### Install
| Platform | Command |
|---|---|
| macOS | `brew install --cask cyoda/cyoda/cyoda-dev-console` |
| Linux | `curl --proto '=https' --tlsv1.2 -fsSL https://github.com/cyoda/cyoda-dev-console/releases/latest/download/install.sh \| sh` |
| Windows | Build from source — see `RELEASE.md` in the repository |
Updates ship through Homebrew on macOS, or by re-running the installer on
Linux. The app does not auto-update.
### AI assistant
The in-app assistant is off by default. When enabled, you choose a provider
(Anthropic, OpenAI, or Gemini) and supply your own API key. With a workflow
open, the assistant can propose a change and apply it as a diff.
Data handling:
- Everything other than the assistant runs locally.
- The assistant sends the selected workflow JSON and your chat messages to
the chosen provider, using your key. Nothing is sent to Cyoda.
- Keys are held in session storage and cleared when the window closes.
- Provider calls go through the app's backend to a fixed allowlist of
provider hosts.
- Applied edits are re-validated and re-serialized before being written to
disk.
## model-editor MCP
### Register with Claude Code
Add the server to `.mcp.json` at the project root:
```json
{
"mcpServers": {
"model-editor": {
"command": "npx",
"args": ["-y", "@cyoda/model-editor-mcp@0.3.0", "--project", "."]
}
}
}
```
or run:
```bash
claude mcp add model-editor -- npx -y @cyoda/model-editor-mcp@0.3.0 --project .
```
On start, the server logs `model-editor-mcp: http://127.0.0.1:/?token=`
to stderr. Open that URL to see the editor. The port is derived from the
project path and is stable across restarts; the token is regenerated on
every start. Ask the agent to call `connection_info` for the current URL.
### Model discovery
By default the server discovers:
- workflows under `models/workflow/**/*.json`
- entities under `models/schema/**/*.json`
Override with `--workflow-globs` / `--entity-globs` at startup, or with the
`configure_project` tool during a session. Quote the glob values: a shell
that expands `**` into file paths will crash the server at startup.
The project tree is rescanned on every tool call, so files added or renamed
on disk are picked up immediately. Workflow file changes made outside the
agent (an editor, a `git checkout`) are pushed to the browser live.
### Division of work
- **The agent owns content.** Workflows and entities are written only through
MCP tools, and every write is validated. A failed validation writes nothing.
- **You own layout.** Dragging nodes in the browser persists positions to a
`.layout.json` sidecar next to the workflow file.
The browser sidebar lists every discovered workflow and entity; you can
browse them without going through the agent.
### Tools
The server exposes 24 tools:
| Group | Tools |
|---|---|
| Workflows | `list_workflows`, `show_workflow`, `get_workflow`, `create_workflow`, `update_workflow`, `delete_workflow`, `validate_workflow`, `validate_workflows`, `optimize_layout` |
| Workflow elements | `add_state`, `remove_state`, `rename_state`, `add_transition`, `update_transition`, `remove_transition` |
| Entities | `list_entities`, `get_entity`, `show_entity`, `create_entity`, `update_entity`, `delete_entity` |
| Project | `configure_project`, `get_project` |
| Connection | `connection_info` |
Element tools make one atomic, validated change and are preferred over
whole-document `update_workflow`. `rename_state` updates every reference to
the state: transition targets, `initialState`, lifecycle criteria, and the
saved layout position.
`show_workflow`, `create_workflow`, and `update_workflow` canonicalize the
JSON: `operatorType` becomes `operation`, an empty `context` is dropped, and
`disabled: false` is added where absent. `get_workflow` returns the on-disk
bytes unchanged.
The full tool reference is in
[`apps/model-editor-mcp/README.md`](https://github.com/Cyoda/cyoda-dev-console/blob/staging/apps/model-editor-mcp/README.md).
---
## tools/env-dashboard.md
# Environment dashboard
Web UI for investigating and exploring a running Cyoda environment — workflows, entity instances, reporting, and processing.
Repository: [github.com/Cyoda/cyoda-env-dashboard](https://github.com/Cyoda/cyoda-env-dashboard)
The environment dashboard is a general-purpose frontend for investigating and
exploring a Cyoda environment. It covers:
- workflows, state machines, and entity instances
- tasks
- reporting and the catalogue of aliases
- processing nodes and transitions
- Trino SQL schemas
Most functionality targets Cyoda Cloud environments. cyoda-go is also
supported, with a reduced feature set that is growing.
## Run it
The dashboard is a React + TypeScript pnpm monorepo. The deployable
application is `apps/saas-app`. It requires Node.js 22 or later and the pnpm
version pinned in the repository.
```bash
git clone https://github.com/Cyoda/cyoda-env-dashboard.git
cd cyoda-env-dashboard
corepack enable
pnpm install
pnpm dev
```
The dev server starts on `http://localhost:5173`. A VS Code Dev Container is
also provided if you prefer not to install the toolchain locally.
## Configuration
The app will not start until `apps/saas-app/.env` exists and sets
`VITE_APP_BASE_URL` to the base URL of the Cyoda environment. The dev
server proxies API calls (`/api`, `/platform-api`, `/platform-processing`,
`/platform-common`, `/auth`) to that environment.
Sign-in uses Auth0, configured through the `VITE_APP_AUTH0_*` variables.
The full environment reference is in `ENV_FILES_GUIDE.md` and
`apps/saas-app/README.md` in the repository. A mock backend under
`tools/backend-mock-server` is available for offline work.
---
## tools/java-client-template.md
# Java client template
Spring Boot template for building Java and Kotlin Cyoda applications and compute nodes.
Repository: [github.com/Cyoda/java-client-template](https://github.com/Cyoda/java-client-template)
· Apache-2.0
An opinionated Gradle and Spring Boot starting point for Cyoda applications
in Java or Kotlin. Fork it to start a project. It includes the Cyoda
integration — authentication, the REST repository layer, and the gRPC
compute-node client — so application code contains only entities,
processors, criteria, and REST controllers.
The template is optional. Compute nodes can be written in any language that
speaks the [compute-node protocol](/build/client-compute-nodes/), and AI
coding agents build them directly from `cyoda help`, the
[API reference](/reference/api/), and [Cyoda Skills](/tools/cyoda-skills/).
## Requirements
- Java 21
- A Cyoda instance and an M2M client (`client_id` and secret). On cyoda-go,
see [`cyoda help auth clients`](/help/auth/clients/).
## Get started
```bash
git clone https://github.com/Cyoda/java-client-template.git
cd java-client-template
```
Configure the connection through Spring profiles or environment variables:
```bash
export APP_CONFIG_CYODA_HOST=:
export APP_CONFIG_CYODA_CLIENT_ID=
export APP_CONFIG_CYODA_CLIENT_SECRET=
```
Import the workflow definitions, then run the application:
```bash
./gradlew runApp -PmainClass=com.java_template.common.tool.WorkflowImportTool \
--args='--spring.profiles.active=local'
./gradlew runApp --args='--spring.profiles.active=local'
```
The application serves Swagger UI at
`http://localhost:8080/swagger-ui/index.html`.
## Project layout
| Path | Contents |
|---|---|
| `src/main/java/com/java_template/common/` | Framework code: auth, config, gRPC client, repository, `EntityService`, serializers, `WorkflowImportTool`. Not modified by applications. |
| `src/main/java/com/java_template/application/` | Application code: `entity/`, `processor/`, `criterion/`, `controller/` |
| `src/main/resources/workflow//version_/.json` | Workflow definitions, one per entity model version |
## Core interfaces
| Interface | Role |
|---|---|
| `CyodaEntity` | Domain entity. Implements `getModelKey()` and `isValid()`. |
| `CyodaProcessor` | Runs business logic during a transition. Implements `process()` and `supports()`. |
| `CyodaCriterion` | Evaluates a transition condition. Implements `check()` and `supports()`. Must be side-effect free. |
| `EntityWithMetadata` | Wraps an entity with its technical metadata (ID, state). |
| `EntityService` | Single interface for all Cyoda data operations. |
Components are discovered through Spring's `@Component` annotation. A
processor cannot update the entity it is processing through `EntityService`.
Examples of each component type are under `src/test/java/com/example/application/`.
## Related
- [Client compute nodes](/build/client-compute-nodes/) — the protocol the
template implements.
- [Workflows and processors](/build/workflows-and-processors/)
---
## tools/python-client-template.md
# Python client template and MCP
Quart template for Python-based Cyoda compute nodes, and an MCP server that gives AI assistants access to a Cyoda instance.
Repository: [github.com/Cyoda/mcp-cyoda-quart-app](https://github.com/Cyoda/mcp-cyoda-quart-app)
· Apache-2.0
The repository contains two things:
- an opinionated **Python application template** for Cyoda compute nodes,
built on the asynchronous Quart framework — fork it to start a project
- **`mcp-cyoda`**, an MCP server that lets AI assistants read and write
entities, search, send edge messages, and manage workflows on a Cyoda
instance
Both need a Cyoda instance and an M2M client (`client_id` and secret). On
cyoda-go, see [`cyoda help auth clients`](/help/auth/clients/).
## Application template
The template is optional. Compute nodes can be written in any language that
speaks the [compute-node protocol](/build/client-compute-nodes/), and AI
coding agents build them directly from `cyoda help`, the
[API reference](/reference/api/), and [Cyoda Skills](/tools/cyoda-skills/).
The template manages entities, runs their workflows, and connects to Cyoda
over gRPC to execute processors and criteria. It also exposes REST endpoints
for entity and workflow operations.
| Path | Contents |
|---|---|
| `application/` | Application code: `entity/`, `routes/`, `processor/` |
| `common/` | Shared infrastructure: auth, config, gRPC client, repository, service interfaces |
| `example_application/` | Reference implementation |
| `cyoda_mcp/` | The MCP server |
| `tests/` | Test suite |
### Run it
```bash
git clone https://github.com/Cyoda/mcp-cyoda-quart-app.git
cd mcp-cyoda-quart-app
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
export CYODA_CLIENT_ID=
export CYODA_CLIENT_SECRET=
export CYODA_HOST=
python -m application.app
```
`CYODA_HOST` is the host name only, without a scheme.
## MCP server
`mcp-cyoda` is published on PyPI. Run it without installing:
```bash
pipx run mcp-cyoda
```
or install it once:
```bash
pipx install mcp-cyoda
mcp-cyoda # stdio (default)
mcp-cyoda --transport http --port 9000 # HTTP
```
The transport is `stdio`, `http`, or `sse`, set with `--transport` or
`MCP_TRANSPORT`. The server reads the same `CYODA_*` variables as the
template.
Register it with an MCP client (Claude Code, Claude Desktop, Cursor, and
others):
```json
{
"mcpServers": {
"cyoda": {
"command": "mcp-cyoda",
"env": {
"CYODA_CLIENT_ID": "",
"CYODA_CLIENT_SECRET": "",
"CYODA_HOST": ""
}
}
}
}
```
### Capabilities
| Area | Operations |
|---|---|
| Entities | Create, read, update, delete, list by model |
| Search | Field-based and condition-based search |
| Edge messages | Send and retrieve |
| Workflows | Export, import, copy between entity models |
## Related
- [Client compute nodes](/build/client-compute-nodes/) — the protocol the
template implements.
- [Edge messages](/build/edge-messages/)
---
## tools/workflow-editor.md
# Workflow editor libraries
TypeScript packages for parsing, projecting, rendering, and editing Cyoda workflow JSON.
Repository: [github.com/Cyoda/cyoda-workflow-editor](https://github.com/Cyoda/cyoda-workflow-editor)
· Apache-2.0
A TypeScript monorepo of packages for working with Cyoda workflow JSON in a
browser. It supports three uses:
1. **Display-only embeds** — a lightweight SVG viewer for static sites and
documentation.
2. **Full editor** — a React Flow canvas with an inspector for editing
states, transitions, criteria, processors, and comments.
3. **JSON editing** — a Monaco editor kept in sync with the canvas.
The Cyoda workflow JSON is the canonical state. Graph, layout, and canvas
comments are editor metadata and never appear in exported workflow JSON.
Round-tripping a workflow through the editor is byte-identical.
The [Dev Console and model-editor MCP](/tools/dev-console/) are built on
these packages.
## Packages
All packages are published to npm under `@cyoda/` and ship ESM, CJS, and
type declarations.
| Package | Purpose |
|---|---|
| `@cyoda/workflow-core` | Domain model: parse, normalize, validate, patch, serialize |
| `@cyoda/workflow-graph` | Projection of a workflow into nodes and edges |
| `@cyoda/workflow-layout` | Automatic layout (ELK), with presets and pinned positions |
| `@cyoda/workflow-viewer` | Read-only SVG renderer; no React Flow or Monaco dependency |
| `@cyoda/workflow-react` | Full editor shell (canvas, inspector, toolbar); peers on `react` and `reactflow` |
| `@cyoda/workflow-monaco` | Monaco JSON editor bound to the domain model; peers on `monaco-editor` |
## Display a workflow
```bash
pnpm add @cyoda/workflow-core @cyoda/workflow-graph @cyoda/workflow-viewer react react-dom
```
```tsx
const { document } = parseImportPayload(workflowJson);
if (!document) throw new Error("Invalid workflow JSON");
export function Embedded() {
return (
console.log("selected", id)}
/>
);
}
```
The viewer supports pan, zoom, and selection. Pass a layout from
`@cyoda/workflow-layout` through the `layout` prop for automatic
positioning. Theme through CSS custom properties.
## Edit a workflow
```bash
pnpm add @cyoda/workflow-core @cyoda/workflow-graph @cyoda/workflow-layout \
@cyoda/workflow-viewer @cyoda/workflow-react react react-dom reactflow
```
```tsx
const { document } = parseImportPayload(workflowJson);
if (!document) throw new Error("Invalid workflow JSON");
export function EditorPage() {
return (
autosave(doc)}
onSave={(doc) => pushToBackend(doc)}
/>
);
}
```
`mode` is `"viewer"`, `"playground"`, or `"editor"`. `onSave` fires on
Ctrl/Cmd+S only when the document validates. Set `enableJsonEditor` and
supply a Monaco runtime through `jsonEditor` to add a synchronized JSON
pane.
To load and save against a backend, implement the `WorkflowApi` interface
from `@cyoda/workflow-core` (`exportWorkflows`, `importWorkflows`) and wire
it in with the `useSaveFlow` hook from `@cyoda/workflow-react`, which handles
confirmation and concurrency conflicts.
The full prop reference, editor capabilities, and metadata persistence
options are in the
[repository README](https://github.com/Cyoda/cyoda-workflow-editor#readme).
## Related
- [Workflows and processors](/build/workflows-and-processors/) — the
workflow model these packages operate on.
---